mirror of
https://github.com/strands-agents/harness-sdk.git
synced 2026-10-02 02:44:48 +08:00
chore: sync strands-agents/docs into monorepo
Merge latest docs/main (6 commits):
- Propose a mono-repository (#811)
- design: add long term memory design (#844)
- docs(blogs): added strands-evals multimodal evaluation blog (#869)
- docs: add EdgeConditionWithContext and invocation_state to graph docs (#847)
- feat: add interventions primitive (#861)
- docs: add deploy guide for Nx Plugin for AWS (#766)

No conflicts.
This commit is contained in:
 Mackenzie Zastrow
@@ -0,0 +1,302 @@
|
||||
# Consolidate Strands SDK Repos into a Mono Repository
|
||||
|
||||
**Status**: Proposed
|
||||
|
||||
**Date**: 2026-05-05
|
||||
|
||||
## Overview
|
||||
|
||||
This document proposes consolidating the core Strands Agents repositories — both SDK implementations, docs, samples, and closely related tooling — into a single mono repository. The primary motivation is development velocity: a single team shipping features across Python and TypeScript, with heavy agentic development, benefits from co-location more than it suffers from the tradeoffs. This is an unusual choice in the SDK ecosystem, and the document surveys industry practice to explain why the standard arguments against it don't apply to our team structure.
|
||||
|
||||
## Context
|
||||
|
||||
Strands Agents is spread across 12 repos under [strands-agents](https://github.com/strands-agents). The SDK has a Python and TypeScript implementation, a docs site, shared tools, samples, and various supporting infra — all in separate repos. As development has ramped up, the friction of bouncing between these repos has become a real bottleneck.
|
||||
|
||||
During active development, we're constantly switching between repos. A single feature might touch both SDKs and the docs site, which means coordinated branches, separate PRs, and careful merge ordering. This slows everyone down, humans and agents alike.
|
||||
|
||||
- **Context switching**: devs and agents lose context every time they jump between repos. Setting up a new worktree means cloning N repositories and making sure they're all on the right branches — that's friction that scales with the number of repos involved.
|
||||
- **Fragmented PRs**: one logical change becomes multiple PRs that have to be reviewed and merged in the right order.
|
||||
- **Docs lag behind code**: docs live in a separate repo, so they end up being a follow-up step rather than part of the feature branch. We also can't always finish doc work until the code merges (or do complex branch pointing).
|
||||
- **Duplicated CI/tooling**: shared workflows and configs get duplicated or need a separate `devtools` repo to coordinate.
|
||||
- **Agent productivity**: agentic tools work best with the full project context in one checkout. Splitting the SDK across repos means the agent doesn't have the full picture out of the gate.
|
||||
|
||||
All of these problems are individually fixable. We can set up multi-repo clones, maintain cross-repo scripts, configure agents with multi-repo context. But each of those is overhead we have to build and maintain per-developer. The question is: why solve these problems individually when we can fix them as a group?
|
||||
|
||||
## Decision
|
||||
|
||||
We have a single team working across both languages, where every member is expected to implement features in all SDKs. Docs are tightly coupled to those implementations, and both humans and agents benefit from co-location.
|
||||
|
||||
Given all of that, we should consolidate the core SDK repos into a single mono repository.
|
||||
|
||||
### Which Repos Move
|
||||
|
||||
The candidates for consolidation are the repos tightly coupled to the SDK, the ones where we're doing a lot of overlapping work:
|
||||
- `sdk-python`, `sdk-typescript`, `docs`: these are the core. Cross-repo work here is constant.
|
||||
- `samples`, `mcp-server`, parts of `devtools`: probably move these too. They're closely tied to SDK development.
|
||||
|
||||
The repos that stay independent are the ones where there isn't a lot of overlap with day-to-day SDK work:
|
||||
- `evals`, `agent-builder`, `agent-sop`, `tools`: these are more standalone projects.
|
||||
- `.github`, `extension-template-python`: org-level config and templates.
|
||||
|
||||
## Consequences
|
||||
|
||||
### What becomes easier
|
||||
|
||||
- **Agentic development**: agents don't need multi-repo setups or special configuration to have full context. Porting code from Python to TypeScript (or vice versa) is much easier when the agent has both implementations open. Generating docs is more useful when the agent has the source code right there.
|
||||
- **Unified PRs**: documentation lives in the feature branch alongside the code. Doc development can be done in tandem with implementation rather than being a separate step.
|
||||
- **Centralized information**: one place for skills, agents, patterns, etc.
|
||||
|
||||
### What becomes harder
|
||||
|
||||
**Overlap and confusion** is the main concern. No major SDK project puts multiple language implementations in a single cross-language monorepo (see [Appendix A](#appendix-a-how-do-other-sdk-projects-handle-this)), so there's inherent unfamiliarity here.
|
||||
|
||||
Additional friction:
|
||||
|
||||
- **File discovery noise**: searching for a single construct returns many results. Even navigating to a file will surface many of the same files across SDK implementations. This is probably the biggest day-to-day annoyance.
|
||||
- **CI complexity**: multiple different things being built and tested in one repo. Pipelines require more custom code/configs to handle per-project builds, and this usually requires different tooling which can be more complex to set up and maintain.
|
||||
- **Migration effort**: real work to get it all working. Changes the ground underneath existing PRs. Issues need to be bulk migrated. Versioning/history gets noisier since git log fills up with commits on unrelated trees.
|
||||
- **GitHub is built around repos, not projects**: a monorepo flattens several repo-level abstractions that don't have good sub-repo equivalents.
|
||||
- *Releases*: tags and GitHub Releases share one timeline, even when sub-projects release independently.
|
||||
- *Issues*: users filing a Python SDK bug land in the same tracker as TypeScript and docs issues — no implicit scoping.
|
||||
- *Community signal*: stars, watchers, and forks collapse into one number. We lose visibility into which SDK is driving adoption or interest.
|
||||
|
||||
### Recommendation
|
||||
|
||||
The cons are real but manageable — CI complexity is solvable with path-based triggers, GitHub UX limitations can be mitigated with labels and naming conventions, and the migration is a one-time cost. The speed gains from co-location are ongoing: every feature, every port, every doc update benefits from having everything in one checkout. For a single team shipping across multiple languages with heavy agentic development, that daily velocity improvement outweighs the friction.
|
||||
|
||||
Additionally, **WASM is already pushing us here**. The TypeScript SDK has started moving towards a monorepo structure on its own because the WASM work requires co-locating TypeScript and Python code. `sdk-typescript` already has folders for the projected Python API from TS (`strands-ts`). Continue this pattern and go all in on a mono repository.
|
||||
|
||||
## Considerations
|
||||
|
||||
### What do other SDK projects do?
|
||||
|
||||
No major SDK project puts multiple language implementations in a single cross-language monorepo. The industry standard is monorepo-per-language (Azure, Google Cloud, LangChain) or fully separate repos per language. See [Appendix A](#appendix-a-how-do-other-sdk-projects-handle-this) for the full survey.
|
||||
|
||||
But those projects have dedicated teams per language. Azure has a Python team and a separate JS team. Google Cloud has separate teams per language. Their reasons for staying separate — independent contributor pools, independent release cadences, independent backlogs — don't apply to us. We're a single team implementing the same features across multiple languages, shooting for feature parity. That's a fundamentally different workflow, and it's the reason co-location helps us where it wouldn't help them.
|
||||
|
||||
This whole argument falls apart if that stops being true. If we eventually have dedicated per-language teams, or want the SDKs to diverge, then co-location is just noise and we should revisit.
|
||||
|
||||
### Will the repo be too big?
|
||||
|
||||
The combined repos total ~227 MB with ~2,000 commits. Industry monorepo problems don't manifest until 10+ GB / 100K+ files / 500K+ commits — we're 50–250x below every known threshold. Even with aggressive growth over 2+ years, Strands would remain in the "trivially small" category for Git.
|
||||
|
||||
The `samples` and `docs` repos are the largest (~130 MB and ~85 MB) due to binary assets — these should use Git LFS as a best practice regardless of repo structure.
|
||||
|
||||
See [Appendix B: Monorepo Size Research](#appendix-b-monorepo-size-research) for detailed thresholds, case studies, and projections.
|
||||
|
||||
### What happens to git history?
|
||||
|
||||
Git histories from each repo can be merged into the monorepo using standard techniques (`git merge --allow-unrelated-histories` with subtree moves, or tools like `git filter-repo` to rewrite paths before merging). This preserves full commit history, blame, and bisect across all projects. It's a well-documented, routine operation — many organizations do this when consolidating repos.
|
||||
|
||||
## Appendix A: How Do Other SDK Projects Handle This?
|
||||
|
||||
<details>
|
||||
<summary>Click to expand</summary>
|
||||
|
||||
### The Short Answer
|
||||
|
||||
**Almost no one puts multiple language SDKs in a single cross-language monorepo.** The dominant pattern in the industry is a monorepo *per language* — one repo containing all packages for a given language, but separate repos for each language implementation. A few projects use fully separate repos per language with no monorepo at all. Cross-language monorepos are rare and tend to be application-level, not SDK-level.
|
||||
|
||||
That said, the projects that *do* consolidate across languages report significant velocity gains, especially in the context of agentic development. The question isn't whether the industry does this — it's whether the industry's reasons for *not* doing it apply to us.
|
||||
|
||||
### Survey of SDK Repository Strategies
|
||||
|
||||
Every multi-language SDK project we found uses separate repos per language. None put Python + TypeScript (or any two languages) in a single cross-language monorepo.
|
||||
|
||||
**Per-language repos (hand-written SDKs):**
|
||||
- **Azure SDKs** — monorepo per language (`azure-sdk-for-python`, `azure-sdk-for-js`, etc.) with a shared guidelines repo. ([source](https://devblogs.microsoft.com/azure-sdk/building-the-azure-sdk-repository-structure/))
|
||||
- **Google Cloud SDKs** — separate repo per language (`google-cloud-python`, `google-cloud-node`, etc.)
|
||||
- **Firebase SDKs** — separate repo per language, each a monorepo of product packages within that language.
|
||||
- **OpenTelemetry** — separate repo per language, with a shared spec repo defining the cross-language API contract.
|
||||
- **LangChain** — monorepo per language (`langchain` for Python, `langchainjs` for TS). ([source](https://python.langchain.com/v0.2/docs/contributing/repo_structure/))
|
||||
|
||||
**Per-language repos (auto-generated SDKs) — less comparable to us:**
|
||||
- **AWS SDKs** — separate repo per language, code-generated from [Smithy](https://smithy.io) models.
|
||||
- **Stripe SDKs** — separate repo per language, code-generated from an OpenAPI spec.
|
||||
- **OpenAI SDKs** — separate repo per language, code-generated via [Stainless](https://www.stainlessapi.com/).
|
||||
- **Pulumi** — per-language SDKs generated from provider schemas.
|
||||
|
||||
The auto-generated SDKs are worth calling out because their repo-per-language structure is a natural consequence of the code generation pipeline, not a deliberate architectural choice. Each language SDK is an output artifact. Cross-language consistency comes from the shared model/spec, not from repo co-location — and there's no human writing both implementations, so the "context switching" problem doesn't exist. This makes them a weak counterexample to our proposal.
|
||||
|
||||
**Single-language projects** (CrewAI, OpenAI Agents SDK, Vercel AI SDK) aren't comparable — they don't face the cross-language question at all.
|
||||
|
||||
### Key Takeaway
|
||||
|
||||
Nobody at scale puts multiple hand-written language SDKs in the same repo. The reasons are practical: different CI toolchains, different release cadences, different contributor pools, and package manager ecosystems that expect language-specific repos. Companies like Google and Microsoft use massive cross-language monorepos *internally*, but their open-source SDKs are still split by language — those internal monorepo benefits come from custom tooling (Bazel, Citc, Piper) that doesn't exist in the OSS ecosystem.
|
||||
|
||||
### How Others Solve Cross-Language Consistency Without Co-Location
|
||||
|
||||
If consistency is a primary reason for a monorepo, it's worth understanding how other projects achieve it across separate repos — and where their approach breaks down for us.
|
||||
|
||||
**Formal specification + review board (Azure, OpenTelemetry).** Azure has the most mature process. They maintain a shared [design guidelines repo](https://azure.github.io/azure-sdk/general_introduction.html) with both general and per-language rules. An Architecture Board reviews every SDK before beta and GA release across all Tier 1 languages (.NET, Java, JS/TS, Python). Their explicit priority order: consistency within the language > consistency with the service > consistency between languages. OpenTelemetry takes a similar approach — a [specification repo](https://github.com/open-telemetry/opentelemetry-specification) defines the cross-language API contract using RFC-style language (MUST, SHOULD, MAY), and each language SIG implements against it. ([source](https://azure.github.io/azure-sdk/policies_reviewprocess.html))
|
||||
|
||||
**Shared serialization format (LangChain).** LangChain Python and LangChainJS use the same serializable format for prompts, chains, and agents, so artifacts can be shared between languages. But in practice, the TypeScript implementation [consistently lags behind Python](https://octomind.dev/blog/on-type-safety-in-langchain-ts) in features and documentation. Multiple developers have noted that LangChainJS feels like a port rather than a co-designed SDK. The separate repos make it easy for the two implementations to drift.
|
||||
|
||||
**Code generation from a shared model (AWS, Stripe, OpenAI).** These projects sidestep the consistency problem entirely — a single source of truth (Smithy model, OpenAPI spec) generates all language SDKs mechanically. Consistency is guaranteed by the generator, not by human coordination.
|
||||
|
||||
**Why these approaches haven't pushed anyone to co-locate:**
|
||||
|
||||
The only project that has explicitly documented *why* they chose per-language repos is Azure. Their [blog post on repository structure](https://devblogs.microsoft.com/azure-sdk/azure-sdk-packaging-tools-and-repository-structure/) explains the decision was driven by **package management toolchains**: each language ecosystem (NuGet, Maven, npm, PyPI) has different packaging formats, discovery mechanisms, and cardinality constraints (e.g., Swift Package Manager enforces one package per repo). Azure's conclusion was to align repo structure with the idioms of each ecosystem rather than fight the tooling. The consistency problem is handled separately through the Architecture Board and shared guidelines repo.
|
||||
|
||||
For OpenTelemetry and LangChain, we couldn't find documented rationale for why they chose separate repos. It's likely a combination of the same toolchain concerns plus the fact that these are large open-source projects with many contributors — but that's inference, not evidence. We don't actually know whether they considered and rejected a cross-language monorepo, or whether it simply never came up.
|
||||
|
||||
**Where this breaks down for us:** Azure's toolchain argument is real — Python and TypeScript have fundamentally different build/test/publish pipelines. But it's a solvable problem with path-based CI, not a hard blocker. The more interesting question is whether the consistency mechanisms these projects use (spec repos, architecture boards, shared serialization formats) would work for us. They're designed for large organizations with dedicated per-language teams. We have a small team where the same people implement features in both Python and TypeScript. Our consistency problem isn't "how do two separate teams stay aligned" — it's "how does one person (or one agent) efficiently port a feature from one implementation to the other." A spec repo and review board don't help with that. Having both implementations visible in the same checkout does.
|
||||
|
||||
The LangChain example is the most cautionary for us. They have a similar profile (Python-first, TypeScript port, overlapping concerns) and chose separate repos. The result is that TypeScript [consistently lags behind Python](https://octomind.dev/blog/on-type-safety-in-langchain-ts) in features and documentation, and multiple developers have noted that LangChainJS feels like a port rather than a co-designed SDK. We can't prove separate repos *caused* that drift, but it's a pattern worth noting.
|
||||
|
||||
### The Agentic Development Argument
|
||||
|
||||
This is where the standard industry wisdom may not apply to us. The strongest argument for consolidation isn't about CI or versioning — it's about agent context.
|
||||
|
||||
**Evidence that monorepos help agents:**
|
||||
- AI Hero Studio [documented](https://aihero.studio/blog/platform/agent-factory-monorepo) shipping a complete feature (backend, frontend, voice integration, website) in a single 3-hour agent session from a monorepo — something that would have required multi-day coordination across separate repos.
|
||||
- A [2026 analysis](https://tianpan.co/blog/2026-04-17-coding-agents-monorepo-context-window) of coding agents in monorepos found that the core failure mode is agents calling interfaces that were renamed in other parts of the codebase they can't see. Cross-repo splits make this worse because the agent literally cannot access the other repo's current state.
|
||||
- Research on agent-assisted PRs ([arxiv](https://arxiv.org/abs/2509.14745)) shows 83.8% of agent-assisted PRs are accepted, with 54.9% merged without modification — but this works best when the agent has full context of the change surface.
|
||||
|
||||
**The counterargument:** Large monorepos can *hurt* agents too. Context windows have limits (100K–2M tokens), and a 50-service monorepo can exceed what an agent can effectively attend to. The "lost in the middle" problem means agents treat content near the middle of long contexts less reliably than content at the edges. For Strands specifically, the combined SDK + docs + samples is likely well within manageable context size, but it's worth monitoring.
|
||||
|
||||
### What This Means for the Proposal
|
||||
|
||||
**We'd be doing something unusual.** No major SDK project puts Python and TypeScript implementations in the same repo. The industry consensus is monorepo-per-language with a shared spec/contract repo.
|
||||
|
||||
**The industry's reasons may not be our reasons.** The standard arguments against cross-language monorepos assume:
|
||||
- Large, separate contributor communities per language (we have a small, overlapping team)
|
||||
- Independent release cadences (we release both SDKs in lockstep for feature parity)
|
||||
- No need for cross-language context during development (we're constantly porting features between Python and TypeScript)
|
||||
- Human-only development workflows (we're heavily invested in agentic development)
|
||||
|
||||
If the primary driver is **conventional best practice**, the monorepo-per-language model (Azure/LangChain style) is the safer choice with well-understood tradeoffs.
|
||||
|
||||
</details>
|
||||
|
||||
## Appendix B: Monorepo Size Research
|
||||
|
||||
<details>
|
||||
<summary>Click to expand</summary>
|
||||
|
||||
*Research conducted 2026-05-05*
|
||||
|
||||
### Current Strands Repo Sizes (via GitHub API)
|
||||
|
||||
| Repo | Size | Commits |
|
||||
|------|------|---------|
|
||||
| sdk-python | 3.9 MB | ~685 |
|
||||
| sdk-typescript | 2.8 MB | ~416 |
|
||||
| docs | 84.5 MB | ~527 |
|
||||
| samples | 130 MB | ~141 |
|
||||
| tools | 734 KB | ~164 |
|
||||
| mcp-server | 39 KB | — |
|
||||
| devtools | 190 KB | — |
|
||||
| agent-builder | 70 KB | — |
|
||||
| agent-sop | 477 KB | — |
|
||||
| **Combined** | **~227 MB** | **~2,000** |
|
||||
|
||||
### Platform Limits
|
||||
|
||||
**GitHub:**
|
||||
- Recommended on-disk size: < 10 GB
|
||||
- Hard limit: 100 GB (warning at 75 GB)
|
||||
- Single file: < 100 MB enforced, < 50 MB recommended
|
||||
- Directory width: < 3,000 entries
|
||||
- Branches: < 5,000
|
||||
|
||||
**Azure DevOps:** Recommends < 10 GB for optimal performance.
|
||||
|
||||
### Performance Thresholds by Dimension
|
||||
|
||||
**Working tree (git status, git add, checkout) — driven by file count:**
|
||||
|
||||
| File Count | Impact |
|
||||
|-----------|--------|
|
||||
| < 10,000 | No noticeable issues |
|
||||
| 10,000–50,000 | Slight slowdown without FSMonitor; imperceptible with it |
|
||||
| 50,000–100,000 | `git status` takes 2–5 seconds without optimization |
|
||||
| 100,000–500,000 | Requires FSMonitor + sparse-checkout |
|
||||
| 500,000+ | Requires Scalar or VFS for Git |
|
||||
|
||||
**History operations (git log, git blame) — driven by commit count:**
|
||||
|
||||
| Commit Count | Impact |
|
||||
|-------------|--------|
|
||||
| < 50,000 | No issues |
|
||||
| 50,000–500,000 | `git log --graph` slows without commit-graph cache |
|
||||
| 500,000–1M+ | Noticeable delays; commit-graph essential |
|
||||
| 10M+ | Requires history pruning |
|
||||
|
||||
**Clone time — driven by repo size:**
|
||||
|
||||
| Repo Size | Approximate Clone Time |
|
||||
|-----------|----------------------|
|
||||
| < 1 GB | Seconds to low minutes |
|
||||
| 1–5 GB | 2–10 minutes |
|
||||
| 5–20 GB | 10–30 minutes |
|
||||
| 20–50 GB | 30–60 minutes |
|
||||
| 50–100 GB | 1+ hours |
|
||||
|
||||
### Case Studies
|
||||
|
||||
**Dropbox (March 2026)** — [source](https://dropbox.tech/infrastructure/reducing-our-monorepo-size-to-improve-developer-velocity)
|
||||
- 87 GB monorepo, growing 20–60 MB/day
|
||||
- Clone took > 1 hour; CI jobs repeatedly paying that cost
|
||||
- Approaching GitHub's 100 GB hard limit
|
||||
- Root cause: Git's delta compression heuristics interacting poorly with i18n directory structure (16-char path suffix matching paired unrelated files)
|
||||
- Fix: Server-side repack with tuned window/depth parameters → reduced to 20 GB (77% reduction)
|
||||
- Lesson: Size problems can be structural (how Git compresses), not just volumetric
|
||||
|
||||
**Grab (September 2025)** — [source](https://engineering.grab.com/taming-monorepo-beast)
|
||||
- 214 GB, 13M commits, 12M references, 444K files
|
||||
- Clone: 8+ minutes; replication lag: up to 4 minutes
|
||||
- GitLab HA completely broken — all traffic forced to single primary node
|
||||
- Fix: Custom migration script preserving tags + 1 month of history → 87 GB, 15.8K commits
|
||||
- Result: 99.4% improvement in replication, 36% faster clones
|
||||
- Lesson: Commit count and reference count matter as much as raw size
|
||||
|
||||
**Canva (June 2022)** — [source](https://www.canva.dev/blog/engineering/we-put-half-a-million-files-in-one-git-repository-heres-what-we-learned/)
|
||||
- 500K files, 60M lines of code, hundreds of engineers
|
||||
- Thousands of PRs/week, tens of thousands of commits/week
|
||||
- `git status` became the primary bottleneck, especially on macOS
|
||||
- Fix: FSMonitor, sparse-checkout, custom tooling
|
||||
- Lesson: File count is the primary working-tree performance driver
|
||||
|
||||
**Microsoft Windows (2017)** — [source](https://devblogs.microsoft.com/bharry/the-largest-git-repo-on-the-planet/)
|
||||
- 300 GB, 3.5M files, push every 20 seconds from 4,000 developers
|
||||
- Standard Git completely unusable
|
||||
- Created GVFS (Git Virtual File System), later evolved into Scalar
|
||||
- Virtualizes the working tree so Git only downloads/stats files you access
|
||||
- Lesson: At extreme scale you need a virtual filesystem layer — but this is orders of magnitude beyond any SDK project
|
||||
|
||||
**Chromium** — [benchmarked by git-tower](https://www.git-tower.com/blog/git-performance)
|
||||
- ~500K files
|
||||
- `git status`: ~3.5 seconds without optimization
|
||||
- With FSMonitor: < 1 second
|
||||
- Lesson: Modern Git features handle even very large repos well
|
||||
|
||||
### What Actually Causes Problems
|
||||
|
||||
The research consistently shows that **size alone is not the issue**. The problematic dimensions are:
|
||||
|
||||
1. **File count in working tree** (> 100K files → `git status` slowdown)
|
||||
2. **Commit/reference count** (> 1M commits → history operations slow)
|
||||
3. **Large binary files without LFS** (bloat history, poor delta compression)
|
||||
4. **CI clone overhead** (fresh clones on every job multiply any size issue)
|
||||
5. **Concurrent developer load** (> 500 devs pushing frequently → server-side pressure)
|
||||
|
||||
Things that are NOT problematic:
|
||||
- Multiple language directories in one repo (no performance impact)
|
||||
- Moderate file counts (< 50K is fine without any optimization)
|
||||
- Moderate history (< 100K commits is fine)
|
||||
|
||||
### Available Mitigations (in order of when you'd need them)
|
||||
|
||||
1. **Git LFS** — for binary assets > 1 MB (best practice from day 1)
|
||||
2. **`.gitignore` hygiene** — exclude build artifacts, node_modules, __pycache__
|
||||
3. **FSMonitor** (`core.fsmonitor true`) — free speedup at > 50K files
|
||||
4. **Commit-graph** (`fetch.writeCommitGraph true`) — speeds history at > 50K commits
|
||||
5. **Sparse-checkout** — only check out needed directories (> 100K files)
|
||||
6. **Partial clone** (`--filter=blob:none`) — skip downloading blobs until needed
|
||||
7. **Shallow clone for CI** (`--depth=1`) — CI doesn't need full history
|
||||
8. **Scalar** — Microsoft's tool for repos approaching millions of files
|
||||
|
||||
For Strands, only #1 and #2 are relevant today.
|
||||
|
||||
</details>
|
||||
@@ -0,0 +1,460 @@
|
||||
# Long-Term Memory
|
||||
|
||||
**Status**: Proposed
|
||||
|
||||
**Date**: 2026-05-14
|
||||
|
||||
**Issue**: TBD
|
||||
|
||||
**Scope**: TypeScript SDK
|
||||
|
||||
## Context
|
||||
|
||||
Strands agents today are stateless across sessions. Every conversation starts from zero: the agent can't recall user preferences, past decisions, or accumulated knowledge. When information leaves the context window, it's gone unless the developer builds custom persistence. The SDK provides session management (persisting conversation state) and context management (handling context window size within a session), but neither addresses cross-session knowledge. An agent that assists a user daily should be able to remember what it learned yesterday without replaying the full history. Prototyping a memory-enabled agent today requires wiring up a vector store, writing extraction logic, managing tool registration, and handling multi-tenancy. This should be supported natively.
|
||||
|
||||
This design proposes a `MemoryManager` primitive that owns long-term knowledge: persisting facts to configurable backends, recalling them via tools or context injection, and optionally extracting them from conversations. The primitive solves three distinct problems:
|
||||
|
||||
1. **Knowledge Retrieval**: how the agent searches and surfaces stored knowledge at the right time
|
||||
2. **Knowledge Extraction**: how conversation messages become structured knowledge entries and are written to stores
|
||||
3. **Context Injection**: how stored knowledge is passively surfaced without agent intervention
|
||||
|
||||
## Decision
|
||||
|
||||
### Architecture
|
||||
|
||||
`MemoryManager` is the component that gives agents persistent knowledge across sessions. It handles storing facts, recalling them when relevant, and optionally extracting them from conversations.
|
||||
|
||||
It is exposed as a top-level `memoryManager` parameter on `AgentConfig`, following the pattern of `contextManager` and `sessionManager`. It accepts either a `MemoryManager` instance or a plain `MemoryManagerConfig` object (auto-wrapped):
|
||||
|
||||
```typescript
|
||||
interface AgentConfig {
|
||||
memoryManager?: MemoryManager | MemoryManagerConfig
|
||||
}
|
||||
```
|
||||
|
||||
Under the hood, MemoryManager integrates with the agent lifecycle via hooks: registering tools at initialization, injecting knowledge before model calls, and extracting new facts after each turn.
|
||||
|
||||
**Stores.** A `MemoryStore` is a backend that holds and retrieves knowledge (a vector database, a managed service like Amazon Bedrock Knowledge Bases, or any implementation of the store interface). MemoryManager orchestrates one or more stores:
|
||||
|
||||
```typescript
|
||||
const agent = new Agent({
|
||||
model,
|
||||
memoryManager: new MemoryManager({
|
||||
stores: [userStore, teamStore, orgStore],
|
||||
}),
|
||||
})
|
||||
```
|
||||
|
||||
Multi-store support avoids pushing multi-tenancy complexity onto the developer. A single agent can query personal, team, and organization knowledge simultaneously. Scoping (namespace, tenant isolation) is handled by each store's own constructor config.
|
||||
|
||||
One `MemoryStore` interface with `search()` required and `add()` optional. Stores carry their own configuration as instance properties (name, description, limit, extraction config). This follows the SDK pattern where instances in arrays are self-contained — no wrapper config objects.
|
||||
|
||||
```typescript
|
||||
interface MemoryStore {
|
||||
readonly name: string
|
||||
readonly description?: string
|
||||
readonly limit?: number
|
||||
readonly extraction?: ExtractionConfig
|
||||
|
||||
search(query: string, options?: SearchOptions): Promise<MemoryEntry[]>
|
||||
add?(content: string, metadata?: Record<string, JSONValue>): Promise<void>
|
||||
}
|
||||
```
|
||||
|
||||
**Shipped backends.**
|
||||
|
||||
| Backend | Package | Use case |
|
||||
|---------|---------|----------|
|
||||
| `BedrockKnowledgeBaseStore` | `@strands-agents/sdk` | Production (managed, zero-infra) |
|
||||
|
||||
---
|
||||
|
||||
### Knowledge Retrieval
|
||||
|
||||
The agent needs stored knowledge at the right moment, but retrieving it has a cost (latency, tokens, relevance noise). MemoryManager provides two retrieval mechanisms that offer different trade-offs between precision and reliability. Both can be used together.
|
||||
|
||||
#### Active Recall
|
||||
|
||||
Active recall lets the agent decide when memory is relevant. Instead of retrieving knowledge every turn, the agent searches on demand, only when it judges that stored knowledge would help.
|
||||
|
||||
This works by registering a `search_memory` tool that the agent can call like any other tool. The trade-off: active recall depends on the model recognizing when to search. If the model doesn't think to look, relevant memories stay hidden.
|
||||
|
||||
```typescript
|
||||
const agent = new Agent({
|
||||
model,
|
||||
memoryManager: new MemoryManager({
|
||||
stores: [myStore],
|
||||
searchToolConfig: true,
|
||||
}),
|
||||
})
|
||||
```
|
||||
|
||||
When multiple stores are configured, results are concatenated in store config order. Scores are not compared across stores because different backends produce incomparable scales. If a store fails, partial results from other stores are still returned. Store names and descriptions are included in the tool description so the model can target specific stores by name when it knows which domain is relevant.
|
||||
|
||||
#### Context Injection
|
||||
|
||||
Context injection guarantees that relevant knowledge is always present, at the cost of paying for retrieval every turn. This is useful when baseline context is more important than token efficiency, or when the model can't reliably judge when to search.
|
||||
|
||||
Enabled via `injection: true`. Each turn, MemoryManager searches stores using the last substantive user message as the query, formats results, and injects them as a message immediately before the user's last turn. The injection target is configurable: `'message'` (default, keeps system prompt clean and prompt caching enabled) or `'systemPrompt'` (for behavioral instructions).
|
||||
|
||||
```typescript
|
||||
const agent = new Agent({
|
||||
model,
|
||||
memoryManager: new MemoryManager({
|
||||
stores: [myStore],
|
||||
injection: true,
|
||||
}),
|
||||
})
|
||||
```
|
||||
|
||||
---
|
||||
|
||||
### Knowledge Extraction
|
||||
|
||||
Knowledge can enter the system in two ways: the agent explicitly writes it (via a `store_memory` tool), or MemoryManager automatically extracts it from conversation messages using an extractor.
|
||||
|
||||
#### Tool-driven writes
|
||||
|
||||
The `store_memory` tool is controlled by `storeToolConfig` on MemoryManagerConfig. It defaults to `false` (not registered). When enabled:
|
||||
|
||||
- With a single writable store: `storeToolConfig: true` auto-targets that store
|
||||
- With multiple writable stores: must explicitly specify `storeToolConfig: { stores: ['personal'] }`
|
||||
- Throws at construction if multiple writable stores exist without explicit targeting
|
||||
|
||||
#### Automatic extraction
|
||||
|
||||
MemoryManager uses triggers to control when automatic extraction happens. A trigger is a class instance that causes MemoryManager to process recent messages and write to the store. Three built-in triggers:
|
||||
|
||||
| Trigger | When | Cost |
|
||||
|---------|---------------|---------------|
|
||||
| `InvocationTrigger` | After every agent invocation | High (model call per turn if an extractor is configured) |
|
||||
| `EvictionTrigger` | Messages are evicted from the context window | Medium (only fires on eviction events) |
|
||||
| `IntervalTrigger({ turns: N })` | Every N turns | Controllable |
|
||||
|
||||
Triggers are configured per-store via `extraction` on the `MemoryStore` interface:
|
||||
|
||||
```typescript
|
||||
const userStore = new BedrockKnowledgeBaseStore({
|
||||
name: 'personal',
|
||||
extraction: {
|
||||
triggers: [new InvocationTrigger()],
|
||||
extractor: new ModelExtractor({ systemPrompt: 'Extract user preferences as discrete facts.' }),
|
||||
},
|
||||
})
|
||||
```
|
||||
|
||||
All writes are async and non-blocking. This means a fact stored in one turn may not be searchable immediately in the next (eventual consistency).
|
||||
|
||||
**Deduplication.** MemoryManager tracks a per-store high-water mark: a pointer to the last message that was already processed. Each trigger only processes messages beyond that mark, preventing duplicate writes.
|
||||
|
||||
**Custom triggers.** `ExtractionTrigger` is an abstract base class — extend it for custom trigger logic.
|
||||
|
||||
**Corrections.** Corrections are handled by storing updated facts. Newer entries take precedence via recency weighting in search results.
|
||||
|
||||
#### Extractors
|
||||
|
||||
When messages are extracted, they need to become searchable entries. Some managed backends handle this transformation server-side. For self-managed backends, MemoryManager can extract discrete facts via an `Extractor`.
|
||||
|
||||
`ModelExtractor` is the built-in implementation: it calls a language model with a configurable system prompt to extract facts, defaulting to the agent's own model but configurable with an explicit cheaper model to reduce cost.
|
||||
|
||||
When no extractor is configured, messages are serialized as plain text and passed directly to the store's `add()` method.
|
||||
|
||||
---
|
||||
|
||||
## Developer Experience
|
||||
|
||||
### Minimal: prototyping
|
||||
|
||||
```typescript
|
||||
import { Agent, MemoryManager, InMemoryMemoryStore } from '@strands-agents/sdk'
|
||||
|
||||
const agent = new Agent({
|
||||
model,
|
||||
memoryManager: new MemoryManager({
|
||||
stores: [new InMemoryMemoryStore({ name: 'notes' })],
|
||||
storeToolConfig: true,
|
||||
}),
|
||||
})
|
||||
// Agent now has search_memory and store_memory tools. Zero infrastructure.
|
||||
```
|
||||
|
||||
### Production: Bedrock Knowledge Bases
|
||||
|
||||
```typescript
|
||||
import { Agent, MemoryManager, BedrockKnowledgeBaseStore, ModelExtractor, InvocationTrigger } from '@strands-agents/sdk'
|
||||
|
||||
const userKB = new BedrockKnowledgeBaseStore({
|
||||
name: 'personal',
|
||||
knowledgeBaseId: 'KB123',
|
||||
dataSourceId: 'DS456',
|
||||
extraction: {
|
||||
triggers: [new InvocationTrigger()],
|
||||
extractor: new ModelExtractor({ model, systemPrompt: 'Extract user preferences and decisions as discrete facts.' }),
|
||||
},
|
||||
})
|
||||
|
||||
const agent = new Agent({
|
||||
model,
|
||||
memoryManager: new MemoryManager({
|
||||
stores: [userKB],
|
||||
storeToolConfig: true,
|
||||
}),
|
||||
})
|
||||
```
|
||||
|
||||
### Multi-tenant: personal + team + org
|
||||
|
||||
```typescript
|
||||
const userKB = new BedrockKnowledgeBaseStore({
|
||||
name: 'personal',
|
||||
description: 'User preferences and facts',
|
||||
knowledgeBaseId: 'KB-USER',
|
||||
dataSourceId: 'DS-USER',
|
||||
extraction: { triggers: [new InvocationTrigger()], extractor },
|
||||
})
|
||||
|
||||
const teamKB = new BedrockKnowledgeBaseStore({
|
||||
name: 'team',
|
||||
description: 'Team decisions and processes',
|
||||
knowledgeBaseId: 'KB-TEAM',
|
||||
dataSourceId: 'DS-TEAM',
|
||||
})
|
||||
|
||||
const orgKB = new BedrockKnowledgeBaseStore({
|
||||
name: 'org',
|
||||
description: 'Organization policies',
|
||||
knowledgeBaseId: 'KB-ORG',
|
||||
dataSourceId: 'DS-ORG',
|
||||
})
|
||||
|
||||
const agent = new Agent({
|
||||
model,
|
||||
memoryManager: new MemoryManager({
|
||||
stores: [userKB, teamKB, orgKB],
|
||||
storeToolConfig: { stores: ['personal'] },
|
||||
}),
|
||||
})
|
||||
// search_memory queries all three, merges by rank position
|
||||
// store_memory writes only to personal (explicitly scoped)
|
||||
```
|
||||
|
||||
### With context injection
|
||||
|
||||
```typescript
|
||||
const agent = new Agent({
|
||||
model,
|
||||
memoryManager: new MemoryManager({
|
||||
stores: [myStore],
|
||||
injection: true, // default: message target, XML format, 2000 token budget
|
||||
}),
|
||||
})
|
||||
```
|
||||
|
||||
## Alternatives Considered
|
||||
|
||||
### 1. Memory as a top-level Agent parameter (no MemoryManager class)
|
||||
|
||||
```typescript
|
||||
new Agent({ memory: { stores: [...], injection: {...} } })
|
||||
```
|
||||
|
||||
**Why rejected:** A config object doesn't provide methods (`search`, `store`) that power users need for programmatic access. The class also owns the extraction queue lifecycle.
|
||||
|
||||
### 2. Single store (no multi-store orchestration)
|
||||
|
||||
**Why rejected:** Forces multi-tenant patterns onto the developer. Multi-store is a customer ask for production agents.
|
||||
|
||||
### 3. Two-interface split (`MemoryStore` + `MutableMemoryStore`)
|
||||
|
||||
The split provides compile-time guarantees that are leaky in practice for custom extensions. Some backends don't support writes at all, but would be forced to implement `add()` that throws. The two-interface approach creates false confidence while real integrations still hit runtime failures. A single interface with optional methods is simpler and more honest.
|
||||
|
||||
### 4. Wrapper config objects for stores (`StoreConfig`)
|
||||
|
||||
An earlier design used `stores: [{ store, name, limit, ingestion }]`. This was replaced by putting config directly on the store instance, matching the SDK pattern where instances in arrays are self-contained (like plugins, tools, MCP clients). Simpler DX: `stores: [userKB, teamKB, orgKB]`.
|
||||
|
||||
### 5. `includeTools` boolean for tool registration
|
||||
|
||||
An earlier design used `includeTools?: boolean | ToolsConfig` to control tool registration. This conflated tool registration with write targeting. Replaced by explicit `searchToolConfig` / `storeToolConfig` which cleanly separate tool configuration and provide fail-fast validation.
|
||||
|
||||
|
||||
## Consequences
|
||||
|
||||
### What Becomes Easier
|
||||
|
||||
- Cross-session knowledge becomes a single parameter. No custom persistence, no manual tool registration, no vector store wiring.
|
||||
- Multi-tenancy is built in via multi-store (scoping handled per-store).
|
||||
- Progressive complexity: prototyping with `InMemoryMemoryStore` to production with `BedrockKnowledgeBaseStore` is changing one import.
|
||||
|
||||
### What Becomes Harder or Requires Attention
|
||||
|
||||
- **Eventual consistency**: writes are async; a fact may not be searchable in the next turn.
|
||||
- **Extraction cost**: `InvocationTrigger` fires a model call every turn. We need sensible defaults and good documentation for users to navigate this.
|
||||
- **Active recall depends on model judgment**: the model must know when to search. Context injection guarantees baseline context at the cost of always paying for retrieval. We need to evaluate and baseline tool descriptions.
|
||||
|
||||
### Migration
|
||||
|
||||
No breaking changes. `memoryManager` is a new optional parameter on `AgentConfig`.
|
||||
|
||||
## Willingness to Implement
|
||||
|
||||
Yes.
|
||||
|
||||
---
|
||||
|
||||
<details>
|
||||
<summary><b>Appendix A: Core Interfaces</b></summary>
|
||||
|
||||
### MemoryEntry
|
||||
|
||||
```typescript
|
||||
interface MemoryEntry {
|
||||
id?: string
|
||||
content: string
|
||||
metadata?: Record<string, JSONValue>
|
||||
}
|
||||
```
|
||||
|
||||
### MemoryStore
|
||||
|
||||
```typescript
|
||||
interface SearchOptions {
|
||||
limit?: number
|
||||
}
|
||||
|
||||
interface MemoryStore {
|
||||
readonly name: string
|
||||
readonly description?: string
|
||||
readonly limit?: number
|
||||
readonly extraction?: ExtractionConfig
|
||||
|
||||
search(query: string, options?: SearchOptions): Promise<MemoryEntry[]>
|
||||
add?(content: string, metadata?: Record<string, JSONValue>): Promise<void>
|
||||
}
|
||||
```
|
||||
|
||||
### ExtractionConfig
|
||||
|
||||
```typescript
|
||||
interface ExtractionConfig {
|
||||
triggers: ExtractionTrigger[]
|
||||
extractor?: Extractor
|
||||
filter?: MessageFilter // default: { exclude: ['toolUse', 'toolResult'] }
|
||||
}
|
||||
|
||||
abstract class ExtractionTrigger {
|
||||
abstract readonly name: string
|
||||
}
|
||||
|
||||
class InvocationTrigger extends ExtractionTrigger {
|
||||
readonly name = 'invocation'
|
||||
}
|
||||
|
||||
class EvictionTrigger extends ExtractionTrigger {
|
||||
readonly name = 'eviction'
|
||||
}
|
||||
|
||||
class IntervalTrigger extends ExtractionTrigger {
|
||||
readonly name = 'interval'
|
||||
constructor(options: { turns: number })
|
||||
}
|
||||
|
||||
interface Extractor {
|
||||
extract(messages: MessageData[]): Promise<{ content: string; metadata?: Record<string, JSONValue> }[]>
|
||||
}
|
||||
|
||||
class ModelExtractor implements Extractor {
|
||||
constructor(options: {
|
||||
model?: Model
|
||||
systemPrompt?: string
|
||||
})
|
||||
}
|
||||
```
|
||||
|
||||
### MemoryManagerConfig
|
||||
|
||||
```typescript
|
||||
interface MemoryManagerConfig {
|
||||
stores: MemoryStore[]
|
||||
searchToolConfig?: MemoryToolConfig | boolean // default: true
|
||||
storeToolConfig?: MemoryToolConfig | boolean // default: false
|
||||
injection?: boolean | InjectionConfig // default: false
|
||||
}
|
||||
|
||||
interface MemoryToolConfig {
|
||||
name?: string
|
||||
description?: string
|
||||
stores?: (string | MemoryStore)[]
|
||||
}
|
||||
|
||||
interface InjectionConfig {
|
||||
target?: 'message' | 'systemPrompt'
|
||||
format?: (entries: MemoryEntry[]) => string
|
||||
maxTokens?: number
|
||||
query?: (messages: MessageData[]) => string
|
||||
}
|
||||
|
||||
interface MemorySearchOptions {
|
||||
limit?: number
|
||||
stores?: string[]
|
||||
}
|
||||
|
||||
interface MemoryStoreOptions {
|
||||
metadata?: Record<string, JSONValue>
|
||||
stores?: string[]
|
||||
}
|
||||
```
|
||||
|
||||
### MemoryManager
|
||||
|
||||
```typescript
|
||||
class MemoryManager implements Plugin {
|
||||
search(query: string, options?: MemorySearchOptions): Promise<MemoryEntry[]>
|
||||
store(content: string, options?: MemoryStoreOptions): Promise<void>
|
||||
}
|
||||
```
|
||||
|
||||
</details>
|
||||
|
||||
---
|
||||
|
||||
<details>
|
||||
<summary><b>Appendix B: Implementation Details</b></summary>
|
||||
|
||||
### Context injection lifecycle
|
||||
|
||||
When injection is enabled, MemoryManager hooks into `BeforeInvocationEvent` (once per turn). The lifecycle:
|
||||
|
||||
1. **Strip**: Remove previous injection from messages
|
||||
2. **Retrieve**: Use last substantive user message (>10 chars) as search query
|
||||
3. **Format**: Render results, respecting `maxTokens` budget
|
||||
4. **Inject**: Insert as message before user's last turn (default) or append to system prompt
|
||||
|
||||
If no substantive message exists or retrieval returns zero results, injection is skipped for that turn.
|
||||
|
||||
### `search_memory` tool behavior
|
||||
|
||||
Accepts `{ query: string, limit?: number, stores?: string[] }`. When `stores` is provided, only those named stores are queried; otherwise all stores are searched. Results are concatenated in store config order. Stores that fail are logged and skipped — partial results from other stores are still returned.
|
||||
|
||||
### `store_memory` tool behavior
|
||||
|
||||
Accepts `{ entries: string[], stores?: string[] }` (batch). Writes fan out to targeted stores. Returns `{ stored: number, failed: number }`.
|
||||
|
||||
### Message filter details
|
||||
|
||||
`filter: { exclude: ContentBlockType[] }` strips content block types before they reach the extractor or serializer. Messages that become empty after filtering are dropped entirely. Default: `exclude: ['toolUse', 'toolResult']`.
|
||||
|
||||
Extractors receive only unprocessed messages (tracked via per-store high-water mark).
|
||||
|
||||
### Custom triggers
|
||||
|
||||
```typescript
|
||||
const myStore = new BedrockKnowledgeBaseStore({ ... })
|
||||
|
||||
agent.addHook(AfterToolCallEvent, async (event) => {
|
||||
if (event.tool.name === 'important_api') {
|
||||
await myStore.add(`API result: ${summarize(event.result)}`)
|
||||
}
|
||||
})
|
||||
```
|
||||
|
||||
</details>
|
||||
@@ -86,6 +86,7 @@ sidebar:
|
||||
- docs/user-guide/concepts/plugins/skills
|
||||
- docs/user-guide/concepts/plugins/steering
|
||||
- docs/user-guide/concepts/plugins/context-offloader
|
||||
- docs/user-guide/concepts/agents/interventions
|
||||
- label: Streaming
|
||||
items:
|
||||
- docs/user-guide/concepts/streaming/async-iterators
|
||||
@@ -152,6 +153,7 @@ sidebar:
|
||||
- docs/user-guide/deploy/deploy_to_docker/typescript
|
||||
- docs/user-guide/deploy/deploy_to_kubernetes
|
||||
- docs/user-guide/deploy/deploy_to_terraform
|
||||
- docs/user-guide/deploy/deploy_with_nx_plugin_for_aws
|
||||
- label: Safety & Security
|
||||
items:
|
||||
- docs/user-guide/safety-security/responsible-ai
|
||||
|
||||
@@ -137,3 +137,18 @@
|
||||
name: Xuan Qi
|
||||
role: "Applied Scientist, AWS"
|
||||
bio: Xuan Qi is an Applied Scientist at Amazon Web Services focusing on ML modeling and simulation, translating scientific concepts into practical AI applications.
|
||||
|
||||
- id: sangmin-woo
|
||||
name: Sangmin Woo
|
||||
role: "Applied Scientist, AWS"
|
||||
bio: Sangmin Woo is an Applied Scientist at AWS AI Labs working on machine learning for agentic AI, with a focus on evaluation frameworks and improving agent behavior and performance. His interests span agentic AI, generative models, and multimodal AI.
|
||||
|
||||
- id: sungyeon-kim
|
||||
name: Sungyeon Kim
|
||||
role: "Applied Scientist, Amazon"
|
||||
bio: Sungyeon Kim is an Applied Scientist at Amazon Agentic AI with a research background in computer vision, multimodal learning, and retrieval systems, currently focused on multimodal understanding and evaluation frameworks for AI agents.
|
||||
|
||||
- id: haibo-ding
|
||||
name: Haibo Ding
|
||||
role: "Principal Applied Scientist, Amazon"
|
||||
bio: Haibo Ding is a Principal Applied Scientist at Amazon Agentic AI working on agent evaluation, tool optimization, and foundation model evaluation and critic models. He holds a Ph.D. from the University of Utah and has served as an area chair for AAAI and ACL.
|
||||
|
||||
+242
@@ -0,0 +1,242 @@
|
||||
---
|
||||
title: "Multimodal evaluators: MLLM-as-a-judge for image-to-text tasks in Strands Evals"
|
||||
date: 2026-05-20
|
||||
description: "Announcing four new MLLM-as-a-Judge evaluators for image-to-text tasks in Strands Evals: Overall Quality, Correctness, Faithfulness, and Instruction Following — automated, image-grounded scoring with reasoning."
|
||||
authors:
|
||||
- sangmin-woo
|
||||
- haibo-ding
|
||||
- sungyeon-kim
|
||||
- vinayak-arannil
|
||||
tags:
|
||||
- Evaluation
|
||||
- Announcement
|
||||
canonicalUrl: "https://aws.amazon.com/blogs/machine-learning/multimodal-evaluators-mllm-as-a-judge-for-image-to-text-tasks-in-strands-evals/"
|
||||
draft: false
|
||||
---
|
||||
|
||||
If you're building visual shopping, image or document understanding, or chart analysis, you need a way to verify whether your model's response is actually grounded in the source image. A text-only evaluator cannot tell you whether a caption faithfully describes an image, whether an extracted invoice total matches the document, or whether a screen summary hallucinated a button that was never on the page. Gartner [predicts](https://www.gartner.com/en/newsroom/press-releases/2025-07-02-gartner-predicts-80-percent-of-enterprise-software-and-applications-will-be-multimodal-by-2030-up-from-less-than-10-in-2024) that by 2030, 80% of enterprise software will be multimodal, up from less than 10% in 2024. Without automated multimodal evaluation, you're stuck between expensive human review and unreliable text-only proxies.
|
||||
|
||||
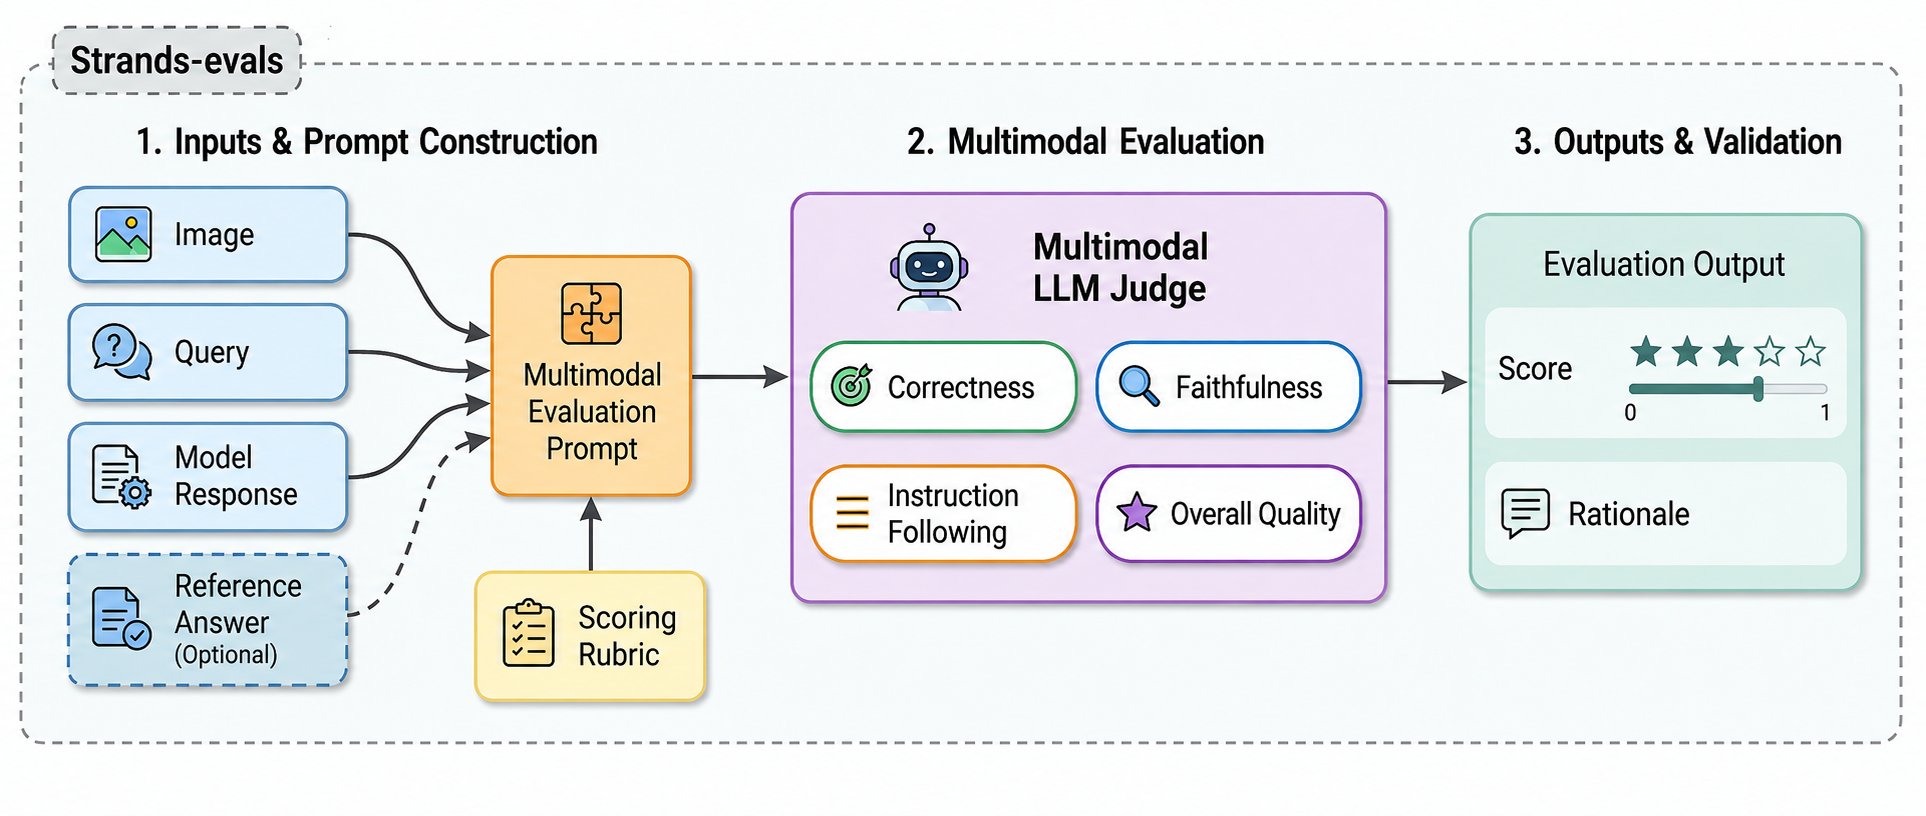
Today, we're announcing four new **multimodal large language model (MLLM)-as-a-Judge evaluators** for image-to-text tasks in [Strands Evals software development kit (SDK)](https://strandsagents.com/docs/user-guide/evals-sdk/quickstart/): **Overall Quality**, **Correctness**, **Faithfulness**, and **Instruction Following**. Each evaluator scores image-to-text outputs against the source image. The evaluator sends the image directly to a multimodal judge model, alongside the query, the response, and (optionally) a reference answer. The judge returns a score grounded in the image, together with a reasoning string you can use for debugging. You can use these evaluators as drop-in replacements for text-only judges in your existing Strands Evals `Case` → `Experiment` → `Report` workflow, and plug them into continuous integration (CI) to catch visual hallucinations, factual errors, and instruction violations automatically.
|
||||
|
||||
In this post, you will learn how to:
|
||||
|
||||
- Set up the four multimodal evaluators and run them on an image-to-text task.
|
||||
- Switch between reference-based and reference-free evaluation with the same evaluator.
|
||||
- Write a custom multimodal rubric for domain-specific criteria.
|
||||
- Choose a judge model on [Amazon Bedrock](https://aws.amazon.com/bedrock/) that balances accuracy, cost, and latency.
|
||||
- Apply prompt-design choices that improved judge-to-human alignment in our experiments.
|
||||
|
||||
|
||||
|
||||
_Figure 1: Overview of the multimodal judge framework. Given an image (or document image), a textual query, and a model-generated response, the framework constructs a multimodal evaluation prompt, applies an MLLM-based judge, and returns a score (Likert 1-5 or binary) along with reasoning. The framework supports both reference-based and reference-free evaluation, and integrates with Strands Evals for case management and reporting._
|
||||
|
||||
## Prerequisites
|
||||
|
||||
To follow the walkthrough in this post, you need:
|
||||
|
||||
- Python 3.10 or later installed in your environment.
|
||||
- pip install `strands-agents-evals` for the evaluators, and pip install `strands-agents` for the target agent used in the walkthrough.
|
||||
- An AWS account with access to Amazon Bedrock.
|
||||
- AWS credentials configured locally (for example, via `aws configure` or an AWS Identity and Access Management (AWS IAM) role) with Amazon Bedrock `InvokeModel` permission for the judge model.
|
||||
- Familiarity with the Strands Evals `Case` → `Experiment` → `Report` workflow. If you are new to Strands Evals, see the [Strands Evals launch blog post](/blog/evaluating-ai-agents-practical-guide-strands-evals) for a quick tour.
|
||||
|
||||
## Why text-only judges miss image-grounded failures
|
||||
|
||||
Suppose you've shipped a model that reads invoices, summarizes dashboards, or narrates screenshots. Running a text-only LLM-as-a-Judge over the response gets you _some_ signal (the writing is fluent, the structure is clean), but it misses exactly the failures that matter:
|
||||
|
||||
- The model confidently names a chart trend that the chart doesn't actually show.
|
||||
- It hallucinates a product, a label, or a person who isn't in the picture.
|
||||
- It answers the wrong question, or answers the right one in the wrong format.
|
||||
|
||||
A text-only judge reads the output and approves it without verifying the image. The ground truth lives in the image, and the judge never sees it.
|
||||
|
||||
Even when you _do_ get a low score from a holistic "rate overall quality" judge, the score alone doesn't tell you _what broke_. The failure could be a factual error, an invented detail, or an ignored instruction. These three failure modes require three different fixes, so collapsing them into one score makes debugging harder than it needs to be.
|
||||
|
||||
## Four evaluators for image-to-text tasks
|
||||
|
||||
The four evaluators target the most widely used multimodal category. The input is an image (or document image) together with text, and the output is text. This category covers image captioning, visual question answering, chart and infographic interpretation, document field extraction, OCR, and screenshot summarization. The table below summarizes what each of the four new evaluators catches.
|
||||
|
||||
| # | Evaluator | Score | Core question | What it catches |
|
||||
|---|-----------|-------|---------------|-----------------|
|
||||
| 1 | **Overall Quality** | Likert 1-5 | How good is the response overall? | Poor relevance, inaccuracy, shallow answers, lack of comprehensiveness |
|
||||
| 2 | **Correctness** | Binary | Is the response factually correct and complete given the image and query? | Factual errors, wrong attributes, counts, positions, omissions |
|
||||
| 3 | **Faithfulness** | Binary | Is the response grounded in the image without hallucinations? | Invented objects, unsupported inferences, external-knowledge leakage |
|
||||
| 4 | **Instruction Following** | Binary | Does the response adhere to the query's constraints? | Format violations, wrong counts, off-topic content, ignored scope |
|
||||
|
||||
Every evaluator supports two modes. **Reference-based** mode compares the response against a gold answer and is useful when you have labeled test sets. **Reference-free** mode judges from the image alone and is the only option when the system runs on live images with no ground truth available.
|
||||
|
||||
## End-to-end walkthrough: evaluating a chart-reading task
|
||||
|
||||
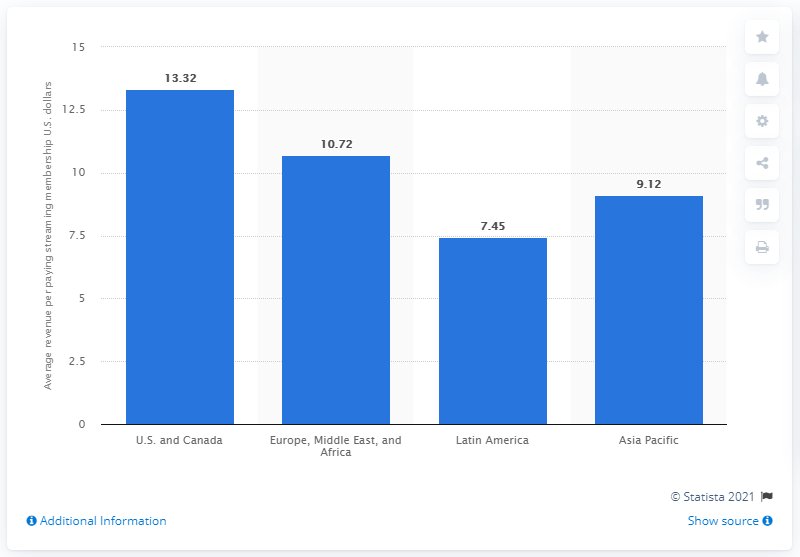
To make the API concrete, you'll walk through a single `Case`. The input is a bar chart of average revenue per paying streaming membership by region (U.S./Canada, EMEA, Asia Pacific, Latin America). The system under test is a simple vision agent that answers a narrow question about the chart. You run the four multimodal evaluators in the same `Experiment`. They share a common `MultimodalOutputEvaluator` base class and accept images through `ImageData`.
|
||||
|
||||
|
||||
|
||||
_Figure 2: Average revenue per paying streaming membership, by region (Statista). The system under test is asked to answer a grounded question about this chart._
|
||||
|
||||
**Step 1. Define the Case and evaluators.** The `Case` wraps the image and instruction in a `MultimodalInput`, and providing `expected_output` activates reference-based judging for the evaluators that support it.
|
||||
|
||||
```python
|
||||
from strands import Agent
|
||||
from strands_evals import Case, Experiment
|
||||
from strands_evals.evaluators import (
|
||||
MultimodalOverallQualityEvaluator,
|
||||
MultimodalCorrectnessEvaluator,
|
||||
MultimodalFaithfulnessEvaluator,
|
||||
MultimodalInstructionFollowingEvaluator,
|
||||
)
|
||||
from strands_evals.types import ImageData, MultimodalInput
|
||||
|
||||
cases = [
|
||||
Case[MultimodalInput, str](
|
||||
name="revenue-chart-1",
|
||||
input=MultimodalInput(
|
||||
media=ImageData(source="revenue_chart.jpeg"),
|
||||
instruction="Which region has the highest average revenue? "
|
||||
"State the region name and the dollar amount shown in the chart.",
|
||||
),
|
||||
expected_output="U.S. and Canada has the highest at $13.32.",
|
||||
metadata={"dataset": "ChartQA"},
|
||||
),
|
||||
]
|
||||
|
||||
evaluators = [
|
||||
MultimodalOverallQualityEvaluator(), # Likert 1-5
|
||||
MultimodalCorrectnessEvaluator(), # Binary
|
||||
MultimodalFaithfulnessEvaluator(), # Binary
|
||||
MultimodalInstructionFollowingEvaluator(), # Binary
|
||||
]
|
||||
```
|
||||
|
||||
**Step 2. Wire up the task and run the experiment.** The `task` function receives each `Case`, runs the vision model on the image plus instruction, and returns the response string to be evaluated.
|
||||
|
||||
```python
|
||||
agent = Agent(callback_handler=None)
|
||||
task_output = None
|
||||
|
||||
def run_task(case):
|
||||
global task_output
|
||||
image = case.input.media
|
||||
messages = [
|
||||
{"image": {"format": image.format or "png", "source": {"bytes": image.to_bytes()}}},
|
||||
{"text": case.input.instruction},
|
||||
]
|
||||
task_output = str(agent(messages))
|
||||
return task_output
|
||||
|
||||
reports = await Experiment(cases=cases, evaluators=evaluators).run_evaluations_async(
|
||||
task=run_task, max_workers=1,
|
||||
)
|
||||
```
|
||||
|
||||
Because each `Case` above carries a `MultimodalInput` with media, the four evaluators include the image in the judge prompt. To ablate whether the image modality is contributing meaningfully on your own data, swap the `MultimodalInput` for a plain-string input (for example, a text description of the image) and rerun. The same evaluator scores from text alone.
|
||||
|
||||
**Step 3. Inspect the Report.** Each `Report` contains per-case `scores`, `test_passes`, and `reasons`:
|
||||
|
||||
```python
|
||||
print(f"Task Output:\n{task_output}\n")
|
||||
print("=" * 50)
|
||||
for name, report in zip(
|
||||
["Quality", "Correctness", "Faithfulness", "Instruction"], reports,
|
||||
):
|
||||
reason = report.reasons[0] if report.reasons else ""
|
||||
status = "PASS" if report.test_passes[0] else "FAIL"
|
||||
print(f"{name}: {report.scores[0]:.2f} [{status}]")
|
||||
print(f" Reason: {reason}\n")
|
||||
```
|
||||
|
||||
Running on the chart above produces the following transcript:
|
||||
|
||||
```
|
||||
Task Output:
|
||||
According to the chart, the U.S. and Canada region has the highest average
|
||||
revenue per paying streaming membership at $13.32.
|
||||
|
||||
==================================================
|
||||
Quality: 1.00 [PASS]
|
||||
Reason: The response correctly identifies U.S. and Canada as the highest
|
||||
revenue region at $13.32, directly addressing both parts of the instruction.
|
||||
The answer is factually accurate based on the chart data and provides
|
||||
appropriate context.
|
||||
|
||||
Correctness: 1.00 [PASS]
|
||||
Reason: The factual claims are accurate. U.S. and Canada is correctly
|
||||
identified as the region with the highest bar in the chart, and $13.32 is
|
||||
the exact dollar amount visible on that bar. No factual errors found.
|
||||
|
||||
Faithfulness: 1.00 [PASS]
|
||||
Reason: The response is fully grounded in the image. Each claim can be
|
||||
directly verified against the chart. U.S. and Canada shows $13.32 and is
|
||||
visibly the highest bar. No hallucinations detected.
|
||||
|
||||
Instruction: 1.00 [PASS]
|
||||
Reason: Response perfectly follows instruction by stating both required
|
||||
elements: region name (U.S. and Canada) and dollar amount ($13.32). Matches
|
||||
expected output factually with no constraint violations.
|
||||
```
|
||||
|
||||
Two things to notice. First, every evaluator returns a `reason` string in addition to a score, which is critical for debugging. When a run fails in CI, you can see _why_ without re-running. Second, the same `Case` was scored by four independent judges (one Likert, three binary) in a single `Experiment`, so your workflow is identical to single-evaluator runs in text-only Strands Evals.
|
||||
|
||||
**Custom rubrics.** For domain-specific criteria, the base class accepts an arbitrary rubric string:
|
||||
|
||||
```python
|
||||
from strands_evals.evaluators import MultimodalOutputEvaluator
|
||||
|
||||
medical_eval = MultimodalOutputEvaluator(rubric="""Rate diagnostic accuracy:
|
||||
- 1.0: All findings correctly identified with proper terminology.
|
||||
- 0.5: Key findings identified but imprecise terminology.
|
||||
- 0.0: Critical findings missed or misidentified.""")
|
||||
```
|
||||
|
||||
## What we learned: three design questions
|
||||
|
||||
### Q1. Does the judge need to see the image?
|
||||
|
||||
A natural question: can a text-only LLM judge, given a detailed auto-generated image description in place of the image, substitute for a multimodal judge? We compared MLLM-as-a-Judge (image plus text) against LLM-as-a-Judge with long and short image descriptions feeding into the same prompt.
|
||||
|
||||
**Takeaway:** the multimodal judge aligned more closely with human scores than either text-only variant. Once you count the extra LLM call to generate the image description, the text-only route is not meaningfully cheaper or faster either. If you have a multimodal judge available, use it directly.
|
||||
|
||||
### Q2. Which model on Amazon Bedrock to use as the judge?
|
||||
|
||||
We evaluated several MLLMs available on Amazon Bedrock as judges and used alignment with human scores, per-query cost, and latency to pick a default. Anthropic Claude Sonnet 4.6 on Amazon Bedrock offered the best accuracy-to-cost trade-off across our runs, and we use it as the default judge model for the multimodal evaluators. Two broader observations also held up consistently across the models we tried. First, larger reasoning-capable models were more reliable as judges than smaller ones. Second, within the capable tier, premium-priced models did not gain measurable accuracy over mid-tier ones for this task.
|
||||
|
||||
**Recommended default:** Anthropic Claude Sonnet 4.6.
|
||||
|
||||
### Q3. Which prompt-design choices actually matter?
|
||||
|
||||
We ablated several prompt-design axes against our final recommended prompt. The takeaways that generalized across our runs:
|
||||
|
||||
1. **Ask the judge to reason before scoring.** This was the single most impactful choice we measured. Score-only output is cheaper and more self-consistent, but alignment with human scores drops noticeably. If you only remember one thing, it is this.
|
||||
2. **Include a few diverse calibration examples.** Alignment improved monotonically as we moved from zero-shot to a handful of examples.
|
||||
3. **Use a fine-grained, multi-dimensional rubric** (e.g., visual accuracy, instruction adherence, completeness, coherence) instead of a single holistic prompt. Separating dimensions prevents a single vague score from absorbing distinct failure modes.
|
||||
|
||||
### Bonus: reference-based vs. reference-free
|
||||
|
||||
Injecting a gold reference answer into the judge prompt helps content-grounded evaluators. Overall Quality, Correctness, and Faithfulness aligned more closely with human judgment when a reference was available. Instruction Following went the other way. Adding reference content distracted the judge from checking structural constraints (format, scope, order, count) that are determined by the query and response alone.
|
||||
|
||||
**As a general guideline:** use references for content-grounded metrics, and skip them for structural metrics like instruction following.
|
||||
|
||||
## Best practices
|
||||
|
||||
Based on our experiments and integration work, we recommend:
|
||||
|
||||
- **Default to `MultimodalOverallQualityEvaluator` for quick sanity checks**, then add targeted binary evaluators (Correctness, Faithfulness, Instruction Following) as you diagnose specific failure modes.
|
||||
- **Start with Claude Sonnet 4.6 as the judge**, and drop to smaller reasoning-capable MLLMs on Amazon Bedrock only if cost or latency dominates your constraints. Avoid small models for judgment.
|
||||
- **Keep the reason+score output format.** Score-only is tempting for cost, but alignment with human scores drops noticeably.
|
||||
- **Use references for correctness, faithfulness, and overall quality if available. Skip them for instruction following.**
|
||||
|
||||
## Conclusion
|
||||
|
||||
The four new MLLM-as-a-Judge evaluators in Strands Evals move image-to-text evaluation from expensive human review or unreliable text-only proxies to automated, image-grounded scoring. Overall Quality, Correctness, Faithfulness, and Instruction Following each target a distinct failure mode, support both reference-based and reference-free evaluation, and return diagnostic reasoning alongside every score. On our held-out validation split, the four evaluators aligned well with human judgment across diverse image domains. This is the first step toward broader multimodal evaluation in Strands Evals. Future work includes step-level evaluation for multimodal tool use and agent trajectories, and additional modality combinations such as text-to-image, video-to-text, and audio-to-text.
|
||||
|
||||
Start evaluating your image-to-text agents today. Install Strands Evals with the following command:
|
||||
|
||||
```
|
||||
pip install strands-agents-evals
|
||||
```
|
||||
|
||||
Then explore the resources below:
|
||||
|
||||
- Read the [Strands Evals documentation](https://strandsagents.com/) for an end-to-end overview of the `Case` → `Experiment` → `Report` workflow.
|
||||
- See the [multimodal evaluator reference](https://strandsagents.com/docs/user-guide/evals-sdk/evaluators/multimodal_output_evaluator/) for the full API, including `MultimodalInput`, `ImageData`, the built-in rubrics, and the four convenience subclasses.
|
||||
- Try the [multimodal evaluator example](https://github.com/strands-agents/docs/blob/main/docs/examples/evals-sdk/multimodal_output_evaluator.py) in the Strands Agents docs repository.
|
||||
- Share your feedback and feature requests in [GitHub Issues](https://github.com/strands-agents/evals/issues).
|
||||
@@ -0,0 +1,103 @@
|
||||
---
|
||||
title: Interventions
|
||||
description: "A composable control layer for authorization, guardrails, and steering with typed actions, ordered evaluation, and short-circuiting."
|
||||
tags: [hooks, event-loop, tool-execution]
|
||||
languages: [typescript]
|
||||
---
|
||||
|
||||
Interventions are a composable control layer for agents. They provide a typed action model for common control concerns — authorization, guardrails, steering, and content transformation — with ordered evaluation and short-circuiting. Unlike raw [hooks](./hooks.mdx) and [plugins](../plugins/index.mdx) which mutate event objects directly, intervention handlers return typed decisions (`proceed`, `deny`, `guide`, `confirm`, `transform`) that the framework applies with well-defined semantics — enabling automatic short-circuiting, feedback accumulation, and conflict resolution.
|
||||
|
||||
## Basic Usage
|
||||
|
||||
Create an intervention handler by extending `InterventionHandler` and overriding the lifecycle methods you need. Register handlers via the `interventions` option in agent configuration:
|
||||
|
||||
```typescript
|
||||
--8<-- "user-guide/concepts/agents/interventions.ts:basic_usage"
|
||||
```
|
||||
|
||||
Handlers only need to override the lifecycle methods relevant to their concern — all methods default to `proceed()`.
|
||||
|
||||
## Action Types
|
||||
|
||||
Each lifecycle method returns one of five typed actions:
|
||||
|
||||
| Action | Factory | Description |
|
||||
|--------|---------|-------------|
|
||||
| Proceed | `InterventionActions.proceed()` | Allow the operation to continue unchanged |
|
||||
| Deny | `InterventionActions.deny(reason)` | Block the operation. Short-circuits remaining handlers |
|
||||
| Guide | `InterventionActions.guide(feedback)` | Cancel and provide feedback for the model to retry with |
|
||||
| Confirm | `InterventionActions.confirm(prompt)` | Pause for human approval |
|
||||
| Transform | `InterventionActions.transform(apply)` | Modify event content in-place before execution continues |
|
||||
|
||||
The following examples show each action type in a realistic handler:
|
||||
|
||||
```typescript
|
||||
--8<-- "user-guide/concepts/agents/interventions.ts:action_types"
|
||||
```
|
||||
|
||||
## Lifecycle Methods
|
||||
|
||||
Intervention handlers can override five lifecycle methods. Each method supports a specific subset of actions:
|
||||
|
||||
| Method | Valid Actions | When it Runs |
|
||||
|--------|-------------|--------------|
|
||||
| `beforeInvocation` | Proceed, Deny, Guide, Transform | Before the agent loop starts |
|
||||
| `beforeToolCall` | Proceed, Deny, Guide, Confirm, Transform | Before each tool execution |
|
||||
| `afterToolCall` | Proceed, Transform | After each tool execution |
|
||||
| `beforeModelCall` | Proceed, Deny, Guide, Transform | Before each model API call |
|
||||
| `afterModelCall` | Proceed, Guide, Transform | After each model response |
|
||||
|
||||
How actions behave depends on the lifecycle method:
|
||||
|
||||
| Action | Before events | After events |
|
||||
|--------|--------------|--------------|
|
||||
| **Deny** | Sets `event.cancel`, short-circuits remaining handlers | No effect (warns at runtime) |
|
||||
| **Guide** | On `beforeToolCall`/`beforeInvocation`: cancels with accumulated feedback. On `beforeModelCall`: injects feedback as user message | Injects feedback and retries |
|
||||
| **Confirm** | Pauses agent via interrupt/resume for human approval; denied responses set `event.cancel` | Not supported |
|
||||
| **Transform** | Calls `action.apply(event)` — later handlers see modified content | Calls `action.apply(event)` |
|
||||
|
||||
## Evaluation Order and Short-Circuiting
|
||||
|
||||
Handlers evaluate in **registration order**. If any handler returns `deny()`, remaining handlers are skipped — the operation is blocked immediately. This enables efficient pipelines where fast checks (like authorization) run first and prevent expensive evaluations (like LLM-based steering) from running unnecessarily.
|
||||
|
||||
```typescript
|
||||
--8<-- "user-guide/concepts/agents/interventions.ts:short_circuiting"
|
||||
```
|
||||
|
||||
For `guide()` actions, all handlers continue to run and their feedback is accumulated — the model receives combined guidance from all guiding handlers.
|
||||
|
||||
## Error Handling
|
||||
|
||||
The `onError` property controls what happens when a handler throws an exception:
|
||||
|
||||
| Value | Behavior |
|
||||
|-------|----------|
|
||||
| `'throw'` | Rethrow the error (default). The invocation fails. |
|
||||
| `'proceed'` | Log the error and continue as if `proceed()` was returned. |
|
||||
| `'deny'` | Log the error and treat it as a `deny()` (fail-closed). |
|
||||
|
||||
```typescript
|
||||
--8<-- "user-guide/concepts/agents/interventions.ts:error_handling"
|
||||
```
|
||||
|
||||
Use `'deny'` for security-critical handlers where a failure should block execution. Use `'proceed'` for non-critical handlers like logging where availability is more important than enforcement.
|
||||
|
||||
## Relationship to Hooks and Plugins
|
||||
|
||||
Interventions are built on top of the [hooks](./hooks.mdx) system — under the hood, each lifecycle method registers a hook callback. The difference is in how they communicate with the framework.
|
||||
|
||||
[Hooks](./hooks.mdx) and [plugins](../plugins/index.mdx) mutate event properties directly (e.g., setting `event.cancel = "reason"`). The framework doesn't know _why_ something was cancelled — was it a hard authorization denial or soft guidance to retry differently? Multiple plugins modifying the same event can conflict silently with last-write-wins semantics.
|
||||
|
||||
Interventions return typed actions that the framework interprets. This enables:
|
||||
|
||||
- **Short-circuiting** — a `deny()` from an authorization handler skips all remaining handlers automatically. With hooks, each plugin must independently check `event.cancel` before doing work.
|
||||
- **Feedback accumulation** — multiple handlers can return `guide()` and their feedback is combined into a single message to the model, rather than overwriting each other.
|
||||
- **Human-in-the-loop** — `confirm()` integrates with the SDK's interrupt/resume system to pause for approval without the handler needing to manage interrupt lifecycle.
|
||||
- **Ordered evaluation** — handlers always run in registration order with well-defined precedence (deny > confirm > guide > transform > proceed).
|
||||
- **Error policies** — each handler declares its own failure mode via `onError`. A logging handler can use `'proceed'` (skip on failure), while an auth handler can use `'deny'` (fail closed). Hooks have no equivalent — a thrown error always propagates.
|
||||
|
||||
## Related topics
|
||||
|
||||
- [Hooks](./hooks.mdx) — Low-level event callbacks for observing and modifying agent behavior
|
||||
- [Plugins](../plugins/index.mdx) — Bundle related hooks and tools into reusable modules
|
||||
- [Interrupts](../interrupts.mdx) — The interrupt/resume system that `confirm()` builds on
|
||||
@@ -0,0 +1,237 @@
|
||||
import { Agent, FunctionTool, InterventionHandler, InterventionActions } from '@strands-agents/sdk'
|
||||
import type { OnError } from '@strands-agents/sdk'
|
||||
import {
|
||||
BeforeInvocationEvent,
|
||||
BeforeToolCallEvent,
|
||||
AfterToolCallEvent,
|
||||
BeforeModelCallEvent,
|
||||
AfterModelCallEvent,
|
||||
} from '@strands-agents/sdk'
|
||||
|
||||
// Mock tools for examples
|
||||
const searchTool = new FunctionTool({
|
||||
name: 'search',
|
||||
description: 'Search for information',
|
||||
inputSchema: { type: 'object', properties: { query: { type: 'string' } } },
|
||||
callback: async (input: unknown) => 'search results',
|
||||
})
|
||||
|
||||
const sendEmailTool = new FunctionTool({
|
||||
name: 'send_email',
|
||||
description: 'Send an email',
|
||||
inputSchema: {
|
||||
type: 'object',
|
||||
properties: {
|
||||
to: { type: 'string' },
|
||||
body: { type: 'string' },
|
||||
},
|
||||
},
|
||||
callback: async (input: unknown) => 'email sent',
|
||||
})
|
||||
|
||||
const deleteTool = new FunctionTool({
|
||||
name: 'delete_file',
|
||||
description: 'Delete a file',
|
||||
inputSchema: { type: 'object', properties: { path: { type: 'string' } } },
|
||||
callback: async (input: unknown) => 'deleted',
|
||||
})
|
||||
|
||||
// =====================
|
||||
// Basic Usage
|
||||
// =====================
|
||||
|
||||
async function basicUsageExample() {
|
||||
// --8<-- [start:basic_usage]
|
||||
class ToolGuard extends InterventionHandler {
|
||||
readonly name = 'tool-guard'
|
||||
private blockedTools: string[]
|
||||
|
||||
constructor(blockedTools: string[]) {
|
||||
super()
|
||||
this.blockedTools = blockedTools
|
||||
}
|
||||
|
||||
override beforeToolCall(event: BeforeToolCallEvent) {
|
||||
if (this.blockedTools.includes(event.toolUse.name)) {
|
||||
return InterventionActions.deny(
|
||||
`Tool '${event.toolUse.name}' is not allowed in this environment`
|
||||
)
|
||||
}
|
||||
return InterventionActions.proceed()
|
||||
}
|
||||
}
|
||||
|
||||
const agent = new Agent({
|
||||
tools: [searchTool, deleteTool],
|
||||
interventions: [new ToolGuard(['delete_file'])],
|
||||
})
|
||||
|
||||
// The agent can search freely, but any attempt to call delete_file
|
||||
// is blocked before execution — the model sees the denial reason
|
||||
// and adjusts its approach
|
||||
await agent.invoke('Clean up the temp directory')
|
||||
// --8<-- [end:basic_usage]
|
||||
}
|
||||
|
||||
// =====================
|
||||
// Action Types
|
||||
// =====================
|
||||
|
||||
async function actionTypesExample() {
|
||||
// --8<-- [start:action_types]
|
||||
// deny — block tool calls that access production resources
|
||||
class EnvironmentGuard extends InterventionHandler {
|
||||
readonly name = 'environment-guard'
|
||||
|
||||
override beforeToolCall(event: BeforeToolCallEvent) {
|
||||
const input = event.toolUse.input as Record<string, string>
|
||||
if (input.database?.includes('prod')) {
|
||||
return InterventionActions.deny('Production database access is not allowed')
|
||||
}
|
||||
return InterventionActions.proceed()
|
||||
}
|
||||
}
|
||||
|
||||
// guide — steer the model when it tries to send emails without a subject
|
||||
class EmailValidator extends InterventionHandler {
|
||||
readonly name = 'email-validator'
|
||||
|
||||
override beforeToolCall(event: BeforeToolCallEvent) {
|
||||
if (event.toolUse.name === 'send_email') {
|
||||
const input = event.toolUse.input as Record<string, string>
|
||||
if (!input.subject) {
|
||||
return InterventionActions.guide('All emails must include a subject line.')
|
||||
}
|
||||
}
|
||||
return InterventionActions.proceed()
|
||||
}
|
||||
}
|
||||
|
||||
// confirm — require human approval before deleting files
|
||||
class DeleteApproval extends InterventionHandler {
|
||||
readonly name = 'delete-approval'
|
||||
|
||||
override beforeToolCall(event: BeforeToolCallEvent) {
|
||||
if (event.toolUse.name === 'delete_file') {
|
||||
const input = event.toolUse.input as Record<string, string>
|
||||
return InterventionActions.confirm(
|
||||
`Approve deleting "${input.path}"?`
|
||||
)
|
||||
}
|
||||
return InterventionActions.proceed()
|
||||
}
|
||||
}
|
||||
|
||||
// transform — redact PII from outgoing email bodies
|
||||
class PiiRedactor extends InterventionHandler {
|
||||
readonly name = 'pii-redactor'
|
||||
|
||||
override beforeToolCall(event: BeforeToolCallEvent) {
|
||||
if (event.toolUse.name === 'send_email') {
|
||||
return InterventionActions.transform((e) => {
|
||||
const toolEvent = e as BeforeToolCallEvent
|
||||
const input = toolEvent.toolUse.input as Record<string, string>
|
||||
input.body = input.body.replace(/\b\d{3}-\d{2}-\d{4}\b/g, '[REDACTED]')
|
||||
})
|
||||
}
|
||||
return InterventionActions.proceed()
|
||||
}
|
||||
}
|
||||
// --8<-- [end:action_types]
|
||||
}
|
||||
|
||||
// =====================
|
||||
// Short-Circuiting
|
||||
// =====================
|
||||
|
||||
async function shortCircuitingExample() {
|
||||
// --8<-- [start:short_circuiting]
|
||||
class RateLimiter extends InterventionHandler {
|
||||
readonly name = 'rate-limiter'
|
||||
private callCount = 0
|
||||
|
||||
override beforeToolCall(event: BeforeToolCallEvent) {
|
||||
this.callCount++
|
||||
if (this.callCount > 10) {
|
||||
// deny() short-circuits: handlers registered after this one are skipped
|
||||
return InterventionActions.deny('Rate limit exceeded')
|
||||
}
|
||||
return InterventionActions.proceed()
|
||||
}
|
||||
}
|
||||
|
||||
class ToneSteeringHandler extends InterventionHandler {
|
||||
readonly name = 'tone-steering'
|
||||
|
||||
override afterModelCall(event: AfterModelCallEvent) {
|
||||
// This handler never runs for denied tool calls
|
||||
return InterventionActions.guide('Use a more professional tone.')
|
||||
}
|
||||
}
|
||||
|
||||
// Handlers evaluate in registration order
|
||||
const agent = new Agent({
|
||||
tools: [searchTool],
|
||||
interventions: [
|
||||
new RateLimiter(), // Evaluates first
|
||||
new ToneSteeringHandler(), // Skipped if RateLimiter denies
|
||||
],
|
||||
})
|
||||
// --8<-- [end:short_circuiting]
|
||||
}
|
||||
|
||||
// =====================
|
||||
// Error Handling
|
||||
// =====================
|
||||
|
||||
async function errorHandlingExample() {
|
||||
// --8<-- [start:error_handling]
|
||||
// 'proceed' — if this handler throws, continue as if proceed() was returned
|
||||
class BestEffortLogger extends InterventionHandler {
|
||||
readonly name = 'best-effort-logger'
|
||||
readonly onError: OnError = 'proceed'
|
||||
|
||||
override beforeToolCall(event: BeforeToolCallEvent) {
|
||||
// If the logging service is unreachable, the agent continues normally
|
||||
console.log(`Tool called: ${event.toolUse.name}`)
|
||||
return InterventionActions.proceed()
|
||||
}
|
||||
}
|
||||
|
||||
// 'deny' — if this handler throws, treat it as a deny (fail-closed)
|
||||
class StrictAuth extends InterventionHandler {
|
||||
readonly name = 'strict-auth'
|
||||
readonly onError: OnError = 'deny'
|
||||
|
||||
override beforeToolCall(event: BeforeToolCallEvent) {
|
||||
// If the auth service is down (throws), the operation is denied
|
||||
if (!this.checkPermission(event.toolUse.name)) {
|
||||
return InterventionActions.deny('Unauthorized')
|
||||
}
|
||||
return InterventionActions.proceed()
|
||||
}
|
||||
|
||||
private checkPermission(toolName: string): boolean {
|
||||
// ... call external auth service
|
||||
return true
|
||||
}
|
||||
}
|
||||
|
||||
// 'throw' (default) — errors propagate and fail the invocation
|
||||
class CriticalValidator extends InterventionHandler {
|
||||
readonly name = 'critical-validator'
|
||||
// onError defaults to 'throw'
|
||||
|
||||
override beforeToolCall(event: BeforeToolCallEvent) {
|
||||
// If this throws, the entire invocation fails
|
||||
return InterventionActions.proceed()
|
||||
}
|
||||
}
|
||||
// --8<-- [end:error_handling]
|
||||
}
|
||||
|
||||
// Suppress unused function warnings
|
||||
void basicUsageExample
|
||||
void actionTypesExample
|
||||
void shortCircuitingExample
|
||||
void errorHandlingExample
|
||||
@@ -215,6 +215,55 @@ builder.add_edge("research", "analysis", condition=only_if_research_successful)
|
||||
</Tab>
|
||||
</Tabs>
|
||||
|
||||
### Conditional Edges with Runtime Context
|
||||
|
||||
:::note[Python only]
|
||||
This feature is currently available in the Python SDK only.
|
||||
:::
|
||||
|
||||
Edge conditions can optionally receive an `invocation_state` dictionary, enabling routing decisions based on runtime context such as feature flags, user roles, or environment-specific configuration. This is passed during graph invocation and forwarded to conditions that accept it.
|
||||
|
||||
Both signatures are supported — existing conditions that only accept `state` continue to work without changes.
|
||||
|
||||
```python
|
||||
from strands import Agent
|
||||
from strands.multiagent import GraphBuilder
|
||||
from strands.multiagent.graph import GraphState
|
||||
|
||||
# New-style condition: receives invocation_state for runtime routing
|
||||
def requires_admin(state: GraphState, *, invocation_state: dict, **kwargs) -> bool:
|
||||
"""Only traverse if the invoking user has admin role."""
|
||||
return invocation_state.get("role") == "admin"
|
||||
|
||||
def requires_feature_flag(state: GraphState, *, invocation_state: dict, **kwargs) -> bool:
|
||||
"""Only traverse if the experimental feature is enabled."""
|
||||
return invocation_state.get("enable_experimental", False)
|
||||
|
||||
# Build the graph with conditional routing
|
||||
builder = GraphBuilder()
|
||||
builder.add_node(router, "router")
|
||||
builder.add_node(admin_panel, "admin_panel")
|
||||
builder.add_node(experimental_feature, "experimental")
|
||||
builder.add_node(standard_path, "standard")
|
||||
|
||||
builder.add_edge("router", "admin_panel", condition=requires_admin)
|
||||
builder.add_edge("router", "experimental", condition=requires_feature_flag)
|
||||
builder.add_edge("router", "standard")
|
||||
|
||||
graph = builder.build()
|
||||
|
||||
# Pass runtime context at invocation time
|
||||
result = graph("Process this request", invocation_state={"role": "admin", "enable_experimental": True})
|
||||
```
|
||||
|
||||
The `invocation_state` dictionary is:
|
||||
|
||||
- Passed to every `EdgeConditionWithContext` condition during edge evaluation
|
||||
- Persisted across interrupt/resume cycles (serialized with the graph checkpoint)
|
||||
- Available via the [`EdgeConditionWithContext`](@api/python/strands.multiagent.graph#EdgeConditionWithContext) protocol
|
||||
|
||||
Legacy conditions (`Callable[[GraphState], bool]`) are detected automatically and called with only `state` — no migration is required.
|
||||
|
||||
### Waiting for All Dependencies
|
||||
|
||||
:::note[Python only]
|
||||
|
||||
@@ -0,0 +1,151 @@
|
||||
---
|
||||
title: Deploy with Nx Plugin for AWS
|
||||
sidebar:
|
||||
label: "Nx Plugin for AWS"
|
||||
tags: [deployment]
|
||||
---
|
||||
|
||||
[Nx](https://nx.dev/) is a build system and monorepo tool for managing multi-project workspaces. The [Nx Plugin for AWS](https://awslabs.github.io/nx-plugin-for-aws/) extends Nx with generators that scaffold Strands agents, APIs, React websites, MCP servers, and more with infrastructure as code, packaging, and deployment configuration out of the box. It supports both Python and TypeScript, with a choice of [AWS CDK](https://docs.aws.amazon.com/cdk/) or [Terraform](https://developer.hashicorp.com/terraform) for infrastructure management.
|
||||
|
||||
Using the Nx Plugin for AWS means you don't need to manually configure Dockerfiles, infrastructure definitions, or deployment pipelines — the generators handle this for you, but give you flexibility to modify the generated code to suit your needs.
|
||||
|
||||
## Prerequisites
|
||||
|
||||
- [Node.js](https://nodejs.org/) (v22 or later)
|
||||
- A package manager: [pnpm](https://pnpm.io/), [yarn](https://yarnpkg.com/), [npm](https://www.npmjs.com/), or [bun](https://bun.sh/)
|
||||
- [UV](https://docs.astral.sh/uv/) (for Python agents)
|
||||
- [AWS CLI](https://docs.aws.amazon.com/cli/latest/userguide/getting-started-install.html) configured with credentials
|
||||
- [Terraform CLI](https://developer.hashicorp.com/terraform/install) (if using Terraform as your IaC provider)
|
||||
|
||||
:::note
|
||||
The examples below use [pnpm](https://pnpm.io/), but npm, yarn, and bun are also supported. See the [Quick Start Guide](https://awslabs.github.io/nx-plugin-for-aws/en/get_started/quick-start/) for commands using other package managers.
|
||||
:::
|
||||
|
||||
## Step 1: Create an Nx Workspace
|
||||
|
||||
Create a new Nx workspace using the `@aws/nx-plugin` preset:
|
||||
|
||||
```bash
|
||||
pnpm create @aws/nx-workspace my-agent-project
|
||||
```
|
||||
|
||||
You will be prompted to choose an infrastructure as code (IaC) provider — either **CDK** or **Terraform**. This choice is the default for all infrastructure generated within the workspace. See the [Quick Start Guide](https://awslabs.github.io/nx-plugin-for-aws/en/get_started/quick-start/) for more details.
|
||||
|
||||
## Step 2: Add a Strands Agent
|
||||
|
||||
<Tabs>
|
||||
<Tab label="Python">
|
||||
|
||||
First, generate a Python project to host your agent:
|
||||
|
||||
```bash
|
||||
pnpm nx g @aws/nx-plugin:py#project
|
||||
```
|
||||
|
||||
Then add a Strands agent to the project:
|
||||
|
||||
```bash
|
||||
pnpm nx g @aws/nx-plugin:py#agent
|
||||
```
|
||||
|
||||
Follow the prompts to select your project, agent name, authentication method, and compute type. For full details on the generator options and output, see the [Python Strands Agent guide](https://awslabs.github.io/nx-plugin-for-aws/en/guides/py-agent/).
|
||||
|
||||
</Tab>
|
||||
<Tab label="TypeScript">
|
||||
|
||||
First, generate a TypeScript project to host your agent:
|
||||
|
||||
```bash
|
||||
pnpm nx g @aws/nx-plugin:ts#project
|
||||
```
|
||||
|
||||
Then add a Strands agent to the project:
|
||||
|
||||
```bash
|
||||
pnpm nx g @aws/nx-plugin:ts#agent
|
||||
```
|
||||
|
||||
Follow the prompts to select your project, agent name, authentication method, and compute type. For full details on the generator options and output, see the [TypeScript Strands Agent guide](https://awslabs.github.io/nx-plugin-for-aws/en/guides/ts-agent/).
|
||||
|
||||
</Tab>
|
||||
</Tabs>
|
||||
|
||||
The generator scaffolds your agent code, infrastructure definitions, a Dockerfile, and deployment configuration targeting [Amazon Bedrock AgentCore Runtime](https://docs.aws.amazon.com/bedrock-agentcore/latest/devguide/).
|
||||
|
||||
## Step 3: Add Infrastructure
|
||||
|
||||
Generate an infrastructure project for your chosen IaC provider:
|
||||
|
||||
<Tabs>
|
||||
<Tab label="CDK">
|
||||
|
||||
```bash
|
||||
pnpm nx g @aws/nx-plugin:ts#infra --name infra
|
||||
```
|
||||
|
||||
Then open `packages/infra/src/stacks/application-stack.ts` and instantiate the generated construct for your agent:
|
||||
|
||||
```typescript {9}
|
||||
import { Stack, StackProps } from 'aws-cdk-lib';
|
||||
import { MyAgent } from ':my-agent-project/common-constructs';
|
||||
import { Construct } from 'constructs';
|
||||
|
||||
export class ApplicationStack extends Stack {
|
||||
constructor(scope: Construct, id: string, props?: StackProps) {
|
||||
super(scope, id, props);
|
||||
|
||||
new MyAgent(this, 'MyAgent');
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
Replace `MyAgent` with the construct name generated for your agent (based on the name you chose in Step 2).
|
||||
|
||||
</Tab>
|
||||
<Tab label="Terraform">
|
||||
|
||||
```bash
|
||||
pnpm nx g @aws/nx-plugin:terraform#project --name infra
|
||||
```
|
||||
|
||||
Then open `packages/infra/src/main.tf` and add the generated module for your agent:
|
||||
|
||||
```hcl
|
||||
module "my_agent" {
|
||||
source = "../../common/terraform/src/app/agents/my-agent"
|
||||
}
|
||||
```
|
||||
|
||||
Replace `my-agent` with the module name generated for your agent (based on the name you chose in Step 2).
|
||||
|
||||
</Tab>
|
||||
</Tabs>
|
||||
|
||||
## Step 4: Build and Deploy
|
||||
|
||||
Build all projects in the workspace:
|
||||
|
||||
```bash
|
||||
pnpm build
|
||||
```
|
||||
|
||||
Then deploy:
|
||||
|
||||
```bash
|
||||
pnpm nx deploy infra
|
||||
```
|
||||
|
||||
The Nx Plugin handles containerizing your agent, provisioning the required AWS resources, and deploying to [Amazon Bedrock AgentCore Runtime](https://docs.aws.amazon.com/bedrock-agentcore/latest/devguide/). Follow the [Quick Start Guide](https://awslabs.github.io/nx-plugin-for-aws/en/get_started/quick-start/) for a full walkthrough of the build and deploy workflow.
|
||||
|
||||
:::tip[Beyond Agents]
|
||||
The Nx Plugin for AWS can also generate APIs (tRPC, FastAPI, Smithy), React websites, and MCP servers. Use the [connection generator](https://awslabs.github.io/nx-plugin-for-aws/en/guides/connection/) to wire these components together — for example, connecting a React frontend to your Strands agent, or linking an agent to an MCP server. The plugin also supports local development with hot reload via a `nx serve-local` command that spins up all connected components (websites, APIs, agents, MCP servers) locally.
|
||||
|
||||
The Nx Plugin for AWS also ships with an [MCP server](https://awslabs.github.io/nx-plugin-for-aws/en/get_started/building-with-ai/) that you can use with your favourite AI assistant to accelerate scaffolding and development.
|
||||
:::
|
||||
|
||||
## Additional Resources
|
||||
|
||||
- [Nx Plugin for AWS Documentation](https://awslabs.github.io/nx-plugin-for-aws/)
|
||||
- [Python Strands Agent Guide](https://awslabs.github.io/nx-plugin-for-aws/en/guides/py-agent/)
|
||||
- [TypeScript Strands Agent Guide](https://awslabs.github.io/nx-plugin-for-aws/en/guides/ts-agent/)
|
||||
- [Nx Plugin for AWS Quick Start](https://awslabs.github.io/nx-plugin-for-aws/en/get_started/quick-start/)
|
||||
Reference in New Issue
Block a user