 Ray
5f7a39e175
* Tool-path rate limits: retry at the bridge, then fail the run fast

A PageIndex cloud 429 (or 5xx) on a tool call used to reach the model as
an INTERNAL_ERROR envelope saying "try again": the model re-called once
with no wait, then wrote the failure into its answer, and chat() returned
normally with no status anywhere. The same 429 before the loop (the
doc_id targeting lookup) already propagated raw.

- McpBridge mounts a urllib3 Retry: 429/502/503 and connection failures,
  three attempts, 0/2/4 s apart or as Retry-After says; read timeouts
  are never replayed (240 s each, and the server may have acted); a
  Retry-After past a minute is a quota, not a blip, so the backoff runs
  instead of sleeping it out. Exhausted, the last response falls through
  to the existing >= 400 branch, so the status_code survives.
- _bridge_invoker re-raises 429/5xx alongside 401/403. The frameworks
  turn a raised tool exception back into model-visible text, so each
  chat() door gets its own escape: the in-process MCPServer's
  failure_error_function lets a PageIndex-caused failure propagate and
  _translate_run_error unwraps it from the framework's wrapper (which
  also un-flattens the 401 case); the Messages lane runs each turn's
  tools through the runner's public generate_tool_call_response() and
  raises before the next model call.
- _model_backend_error keeps the provider's status_code.

Claude Agent SDK tools cannot fail fast: the SDK MCP server converts
handler exceptions into JSON-RPC errors for Claude Code by design.

Claude-Session: https://claude.ai/code/session_014S88dcSz7jykegAWyWZk8E

* Tool-path fail-fast: cover unreachable servers and all 5xx

The bridge retry is now a plain urllib3 Retry: 429 and every 5xx retried
three times at the fixed 0/2/4 s backoff, Retry-After ignored. That drops
the _Retry subclass, whose get_retry_after raised InvalidHeader on a
non-integer header (turning a 429 into "could not reach the server"),
honoured a 60 s Retry-After three times over, and let a 413 carrying
Retry-After replay. 500 and 504 join the forcelist so the invoker's "what
survived the bridge's retries" holds for every status it re-raises. Retry
is imported from requests.adapters, the declared dependency.

The invoker re-raises transport failures too: once the bridge's own
connection retries fail, the model cannot reach the server either, and
the envelope only sent it round the retry loop.

The handshake error blames the API key only on 401/403: a rate-limited
handshake is now a run-terminating error and was telling users to rotate
a working key.

Docstrings on agent_tools()/build_agent_tools and the Anthropic adapter
state the real raise set: 401/403, post-retry 429/5xx, unreachable server.

Claude-Session: https://claude.ai/code/session_013xk3xt9KgHNTjsYmFLKxbu

* fix: surface Messages tool failures before advancing runner

* fix: require urllib3 1.26 for MCP retries

* fix: keep the Messages fail-fast quiet and single-path

Raise ToolError from the tools chat(protocol="messages") runs instead of
the raw PageIndexAPIError: the Anthropic runner log.exception()s any
other exception, so every fail-fast printed a 20-line traceback from
anthropic's internals before the SDK raised its own error. The lane
still records the failure and raises it right after the runner's tool
batch, so the ToolError content never reaches the model.

Drop the two post-loop _messages_fail_fast calls: the runner executes
tools only through the public generate_tool_call_response (0.108.0
through 1.4.0), which checked_tool_response wraps, so they could never
fire. Annotate _pageindex_cause for the py.typed package.

Claude-Session: https://claude.ai/code/session_01CfYSeq8kM7HjfF79TGbsiT

* fix: fail fast on the cloud's account-limit tool errors; one 5xx list

RATE_LIMITED / USAGE_LIMIT_REACHED (pageindex-chat #472) arrive as a
normal tool error inside HTTP 200, already retried server-side; the
invoker re-raises them as 429 / 402, the way a post-retry status
escapes, so every lane fails fast without a per-lane change.

The bridge retries the whole 5xx range, the same range the invoker
re-raises; a non-JSON 200 body (a JSONDecodeError is a RequestException
too) stays a model-visible envelope, since the server was reached. The
MCP stub tests keep the machine's proxy out of 127.0.0.1.

Claude-Session: https://claude.ai/code/session_01F7vqmZdnWeKC9SUBytDrdf

* fix: raise the account-limit escape outside the invoker's own try

_raise_account_limit fired inside _invoke's try, so its escape depended
on 429 and 402 also appearing in the except's re-raise tuple: two lists
in one function that had to agree. The check now runs after the try,
where the except cannot swallow it, and 402 leaves the tuple (the MCP
route never answers HTTP 402; it was there only to let the raise through).

The mcp_stub fixture also sets the lowercase no_proxy: requests reads
that spelling first, so a machine with no_proxy set still routed the
stub requests through its proxy despite NO_PROXY.
PageIndex: Vectorless, Reasoning-based RAG
Reasoning-based RAG ◦ No Vector DB, No Chunking ◦ Context-Aware Retrieval ◦ Reads Like a Human
🌐 Website • ☁️ Cloud • 📖 Docs • 📝 Blog • ✉️ Contact
Updates
- [Aug '26] 🔥 PageIndex SDK:
pip install -U pageindexnow ships local mode: index, retrieve, and chat entirely on your machine with your own LLM key, or point the same client at PageIndex Cloud with an API key. - [Aug '26] ⚡ PageIndex Flash: fast tree index generation for text-based PDFs, now the default indexing method in PageIndex SDK local mode.
- Scale PageIndex to Millions of Documents: PageIndex File System is a file-level tree indexing layer that lets PageIndex reason over an entire corpus, not just a single document.
- PageIndex App: a human-like document analysis agent for long professional documents.
What is PageIndex?
Are you frustrated with vector database retrieval accuracy for long and complex documents? Vector-based RAG retrieves by semantic similarity. But similarity ≠ relevance — what retrieval actually needs is relevance, and relevance requires reasoning. On professional documents that demand contextual understanding, domain expertise, and multi-step reasoning, similarity search misses what is relevant but not similar, and returns what is similar but not relevant.
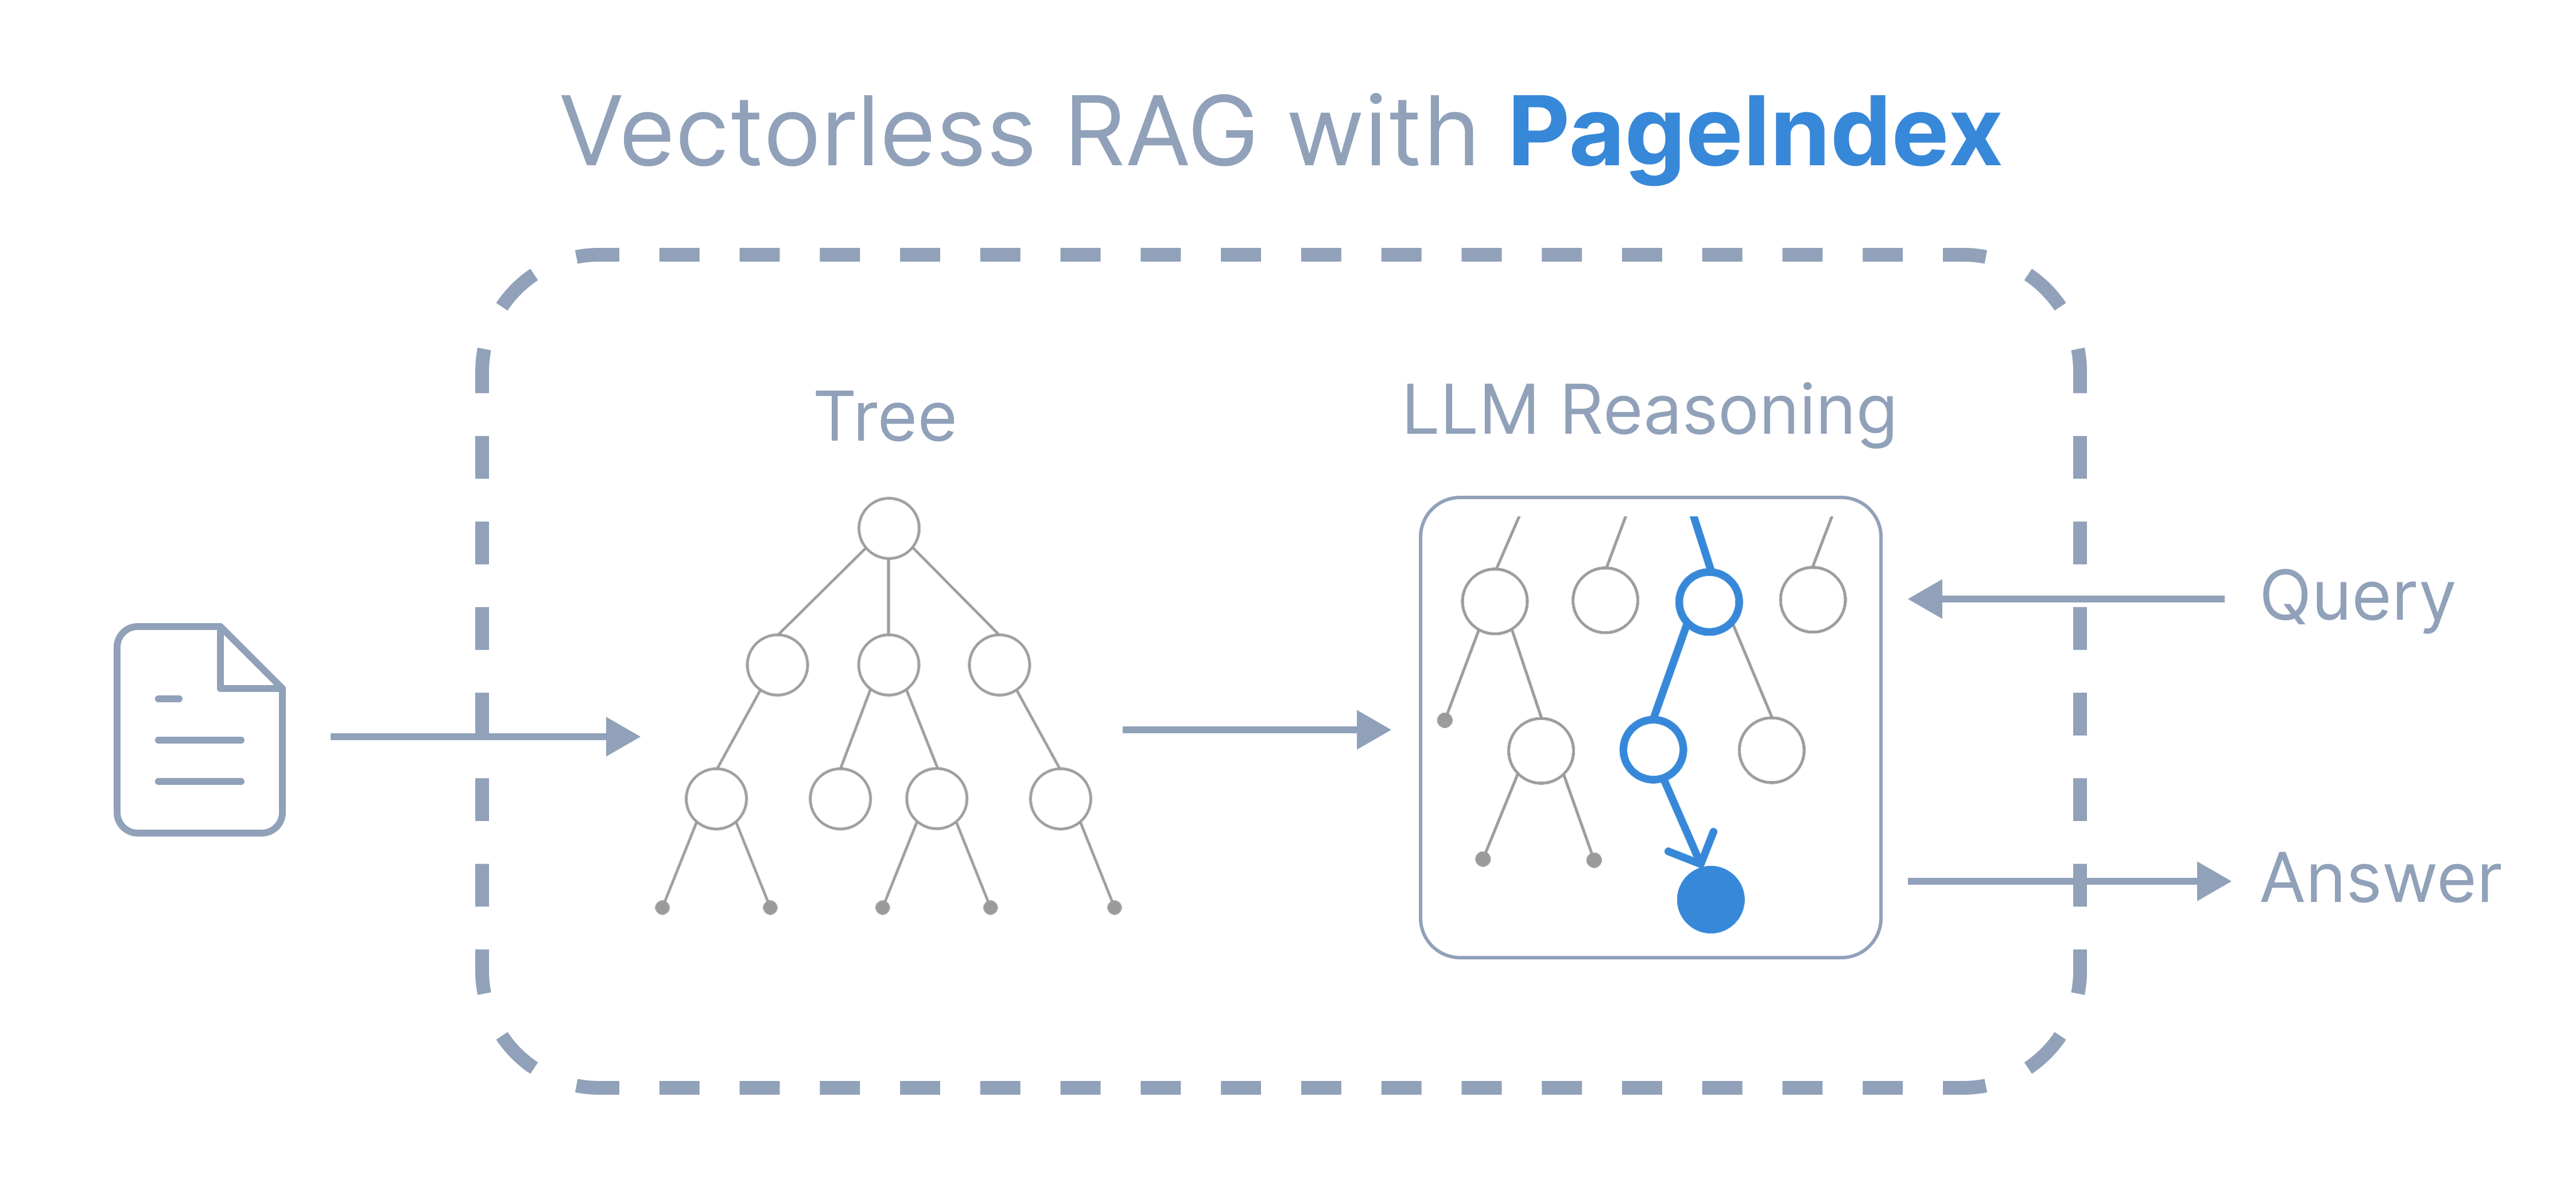
Inspired by AlphaGo, PageIndex replaces the vector index with a hierarchical tree index and lets an LLM reason its way through it, the way a human expert turns to and reads the right section of a long report. Retrieval happens in two steps:
- Index: generate a tree-structure index for each document
- Retrieve: agentically search that tree with LLM reasoning
TL;DR
PageIndex is a vectorless, reasoning-based RAG engine that mirrors how humans read, delivering traceable, explainable, and context-aware retrieval, with no vector DBs or chunking.
Compare with Vector RAG
| Vector RAG | PageIndex | |
|---|---|---|
| Index | vector index | tree index |
| Retrieval | semantic similarity search | LLM reasoning over the tree |
| Result | opaque, “vibe retrieval” | traceable to explicit references |
| Context | query embedding only | full context: conversation history, domain knowledge, etc. |
It is ideal for financial reports, legal documents, regulatory filings, technical manuals, medical literature, academic textbooks, and any other long, complex professional document.
Quickstart
pip install -U pageindex
import os
from pageindex import PageIndexClient

os.environ["OPENAI_API_KEY"] = "your-openai-key"

client = PageIndexClient(
    index="gpt-5.6-luna",               # model to build the tree index
    chat="gpt-5.6-sol",                 # model to search the tree
)
doc_id = client.submit_document("report.pdf")["doc_id"]

answer = client.chat("What was the 2023 operating margin?", doc_id=doc_id)
print(answer)
Model Recommendations
index=: a basic model is sufficient. The tree structure itself is extracted from the document layout without an LLM; the index model only summarizes and refines it, which a basic model does well.chat=: use the best model you can afford. The chat model searches the tree to retrieve information. See Query cost and accuracy.
Use PageIndex through the SDK client →
Configure other models, streaming, multi-document search, citations, and more.
Integrate PageIndex with your own agent →
Drop PageIndex tools into the OpenAI Agents SDK, the Claude Agent SDK, or any other framework.
Benchmarks
Local indexing cost and time
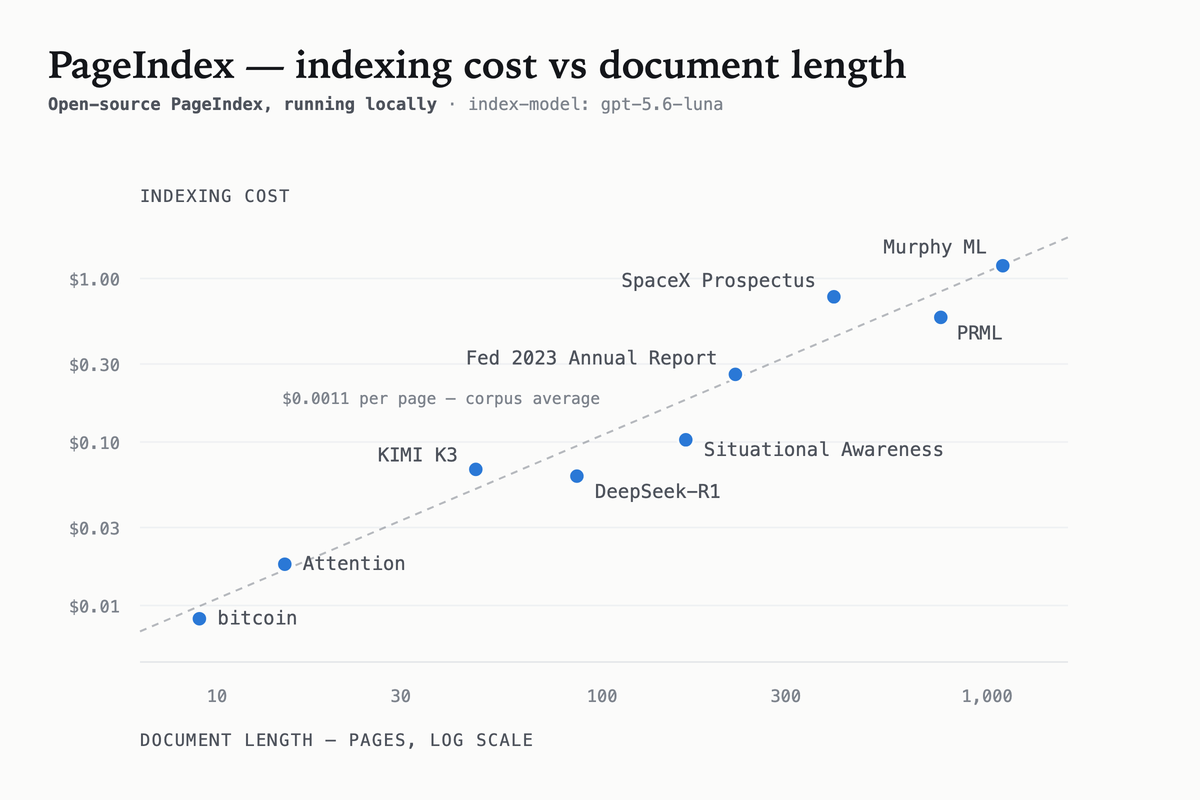
Building a tree locally runs about $0.001 per page with gpt-5.6-luna as the index model, so a 1,000-page textbook costs a little over a dollar and a few minutes, once, and every later question reuses it. PageIndex is designed not to rely heavily on the model used at index time, so in our experiments a basic model does not hurt quality.
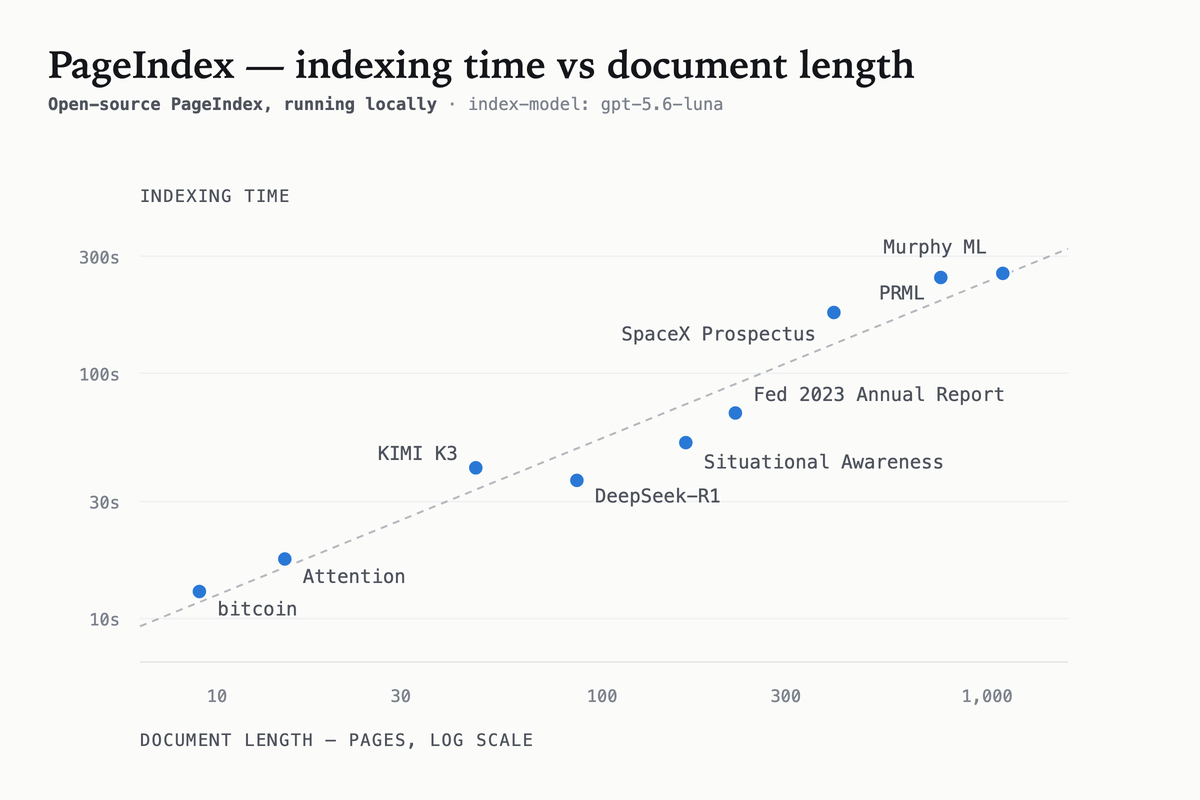
Indexing time also scales predictably with document length. In the same local setup, the benchmark documents (9 to 1,098 pages) finished in roughly 13 seconds to 4.5 minutes.
Query cost and accuracy
PageIndex-OSS-Benchmark measures exactly the setup in the quickstart above (PageIndexClient() in local mode, flash indexing, no OCR) on 62 lookup questions over 34 PDFs (1,945 pages) drawn from MMLongBench-Doc-V2. Every question's answer is a fact stated in running text, so a wrong answer is a retrieval or reading failure, not a reasoning one.
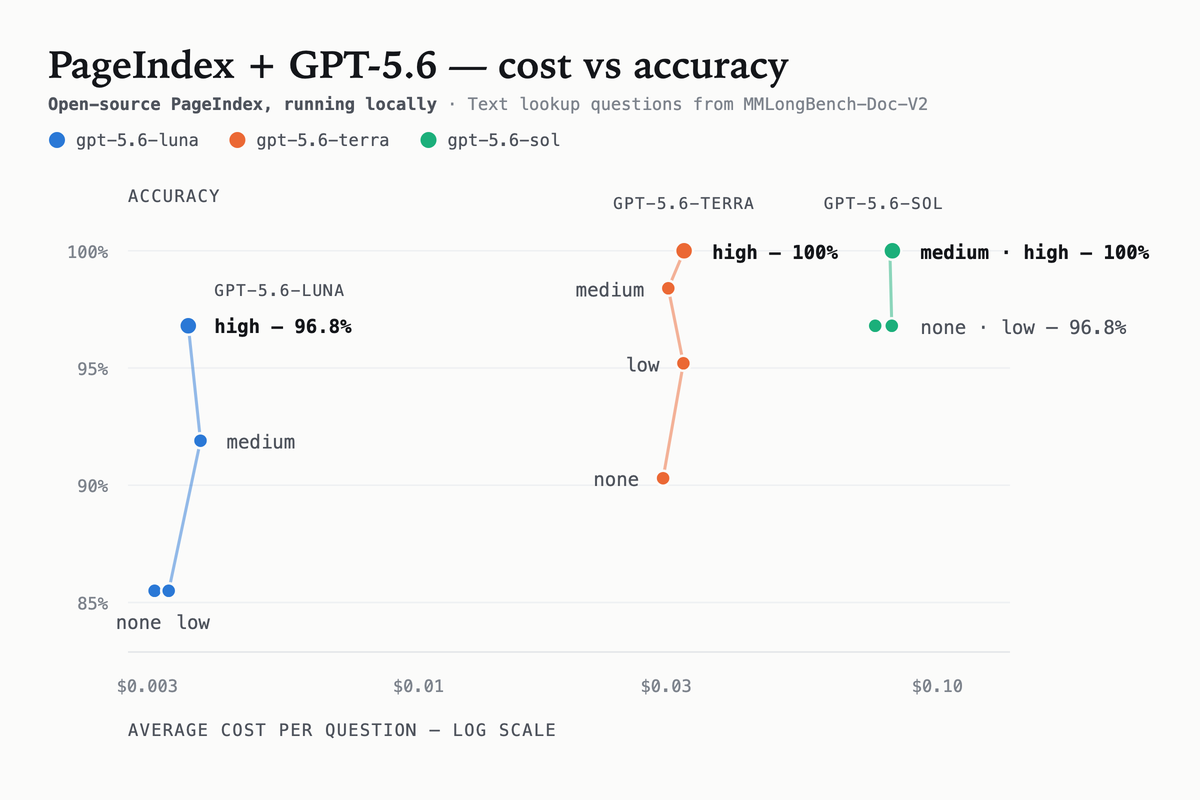
Full results, data, and the runner are in the benchmark repo.
Cost per query vs. native PDF input
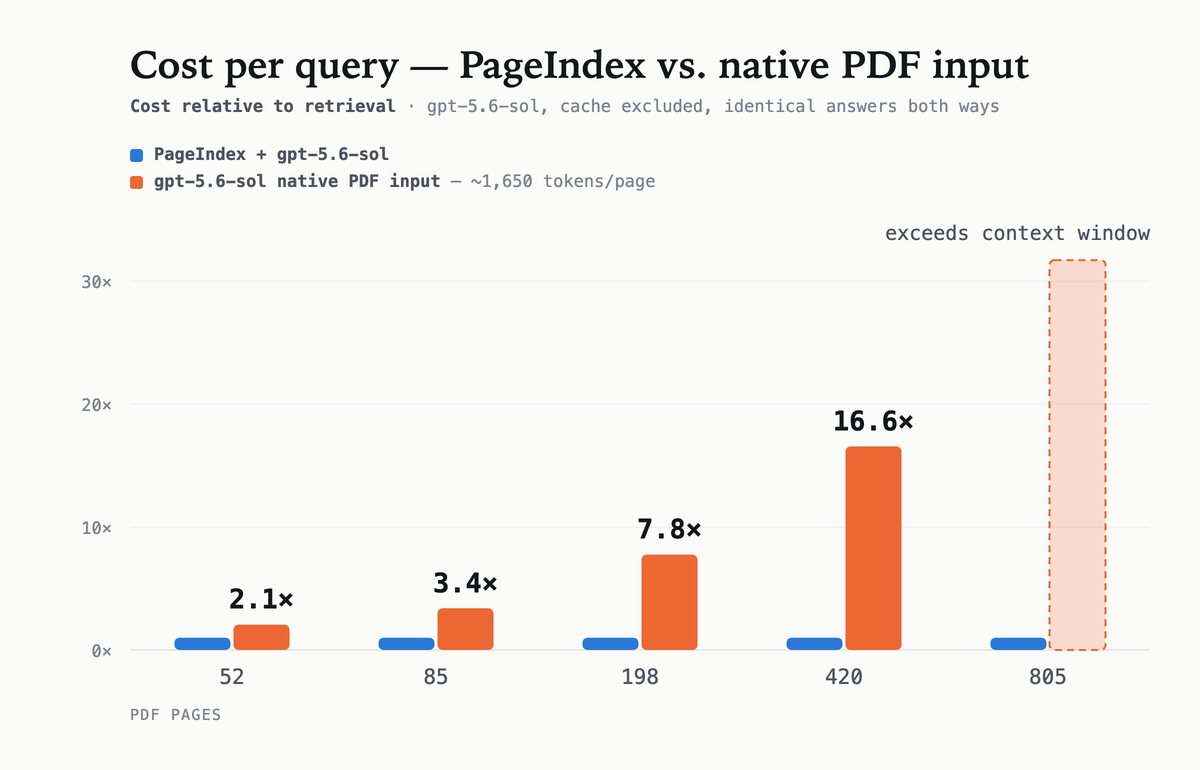
The alternative to retrieval is handing the model the whole PDF on every question. That cost grows with the document; PageIndex's does not, because it reads only the nodes its reasoning reaches. On documents where both routes return the same answer, native PDF input costs 2.1× more at 52 pages and 16.6× more at 420 (gpt-5.6-sol, prompt caching excluded) — and at 805 pages the document no longer fits in the context window at all.
Leading accuracy on FinanceBench
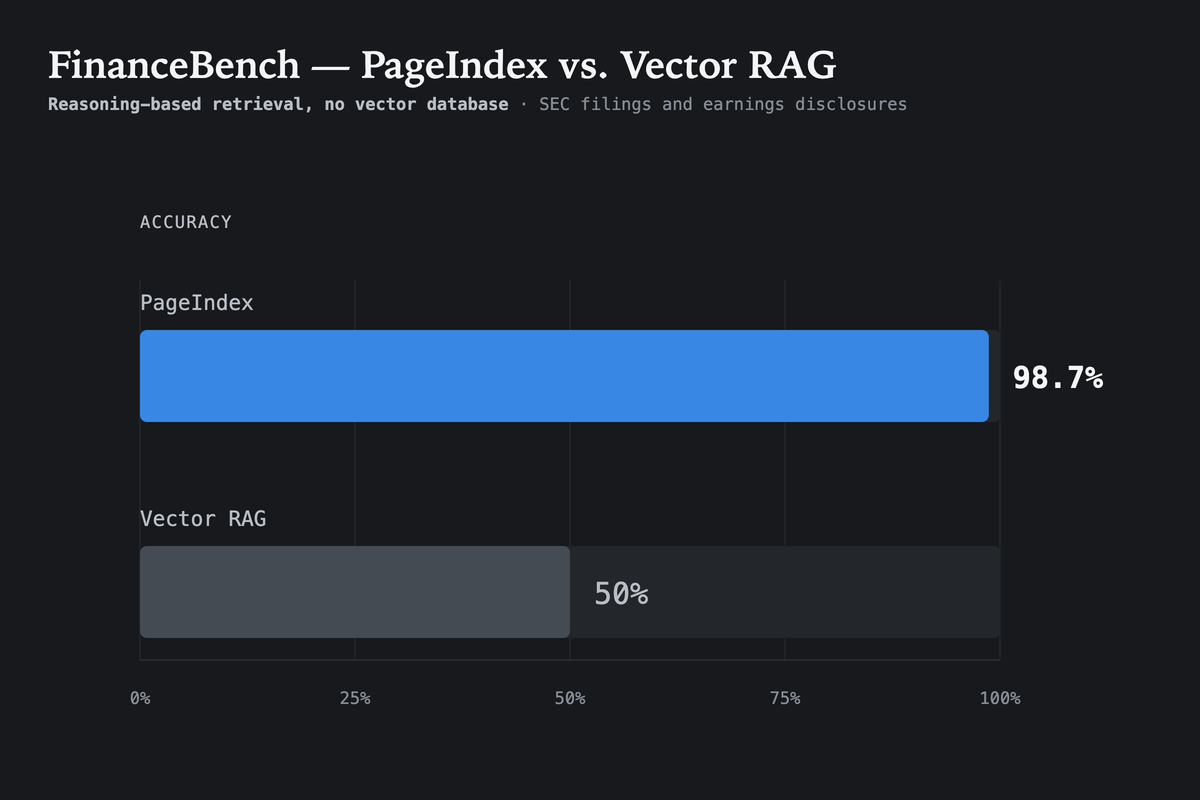
PageIndex reached a state-of-the-art 98.7% accuracy on FinanceBench (financial document QA benchmark), vastly outperforming vector-based RAG.
Explore the full FinanceBench evaluation results and the blog post.
PageIndex Cloud
The open-source version is ideal for text-heavy PDFs and local workflows. With PageIndex Cloud, document indexing and storage run in the cloud: PageIndex handles parsing, OCR, image understanding, tree-index construction, and managed storage for you. The chat and retrieval layer remains compatible with your model, so you can search the cloud-hosted index using the model provider your application already uses.
Moving indexing and storage from Local to Cloud only requires a PageIndex API key:
import os
from pageindex import PageIndexClient

os.environ["PAGEINDEX_API_KEY"] = "your-pageindex-key"
os.environ["OPENAI_API_KEY"] = "your-openai-key"

client = PageIndexClient(
    index="cloud",                       # build and store the index in PageIndex Cloud
    chat="gpt-5.6-sol",                  # use your preferred compatible model for chat
)
doc_id = client.submit_document("report.pdf", wait=True)["doc_id"]
print(client.chat("What was the 2023 operating margin?", doc_id=doc_id))
| Capability | Local (this repo) | Cloud (get an API key) |
|---|---|---|
| Best for | text-heavy PDFs and local workflows | scanned, image-heavy, and large document collections |
| Indexing | runs locally | runs in PageIndex Cloud, with production OCR and image understanding |
| Storage | local | managed in PageIndex Cloud |
| Chat model | your model | your model, or the managed chat included with your key |
| Citations | page-level | line-level |
| Image understanding | — | ✅ |
| Multi-document scale | manual | PageIndex File System |
| MCP server | — | ✅ |
More About PageIndex Cloud
- Scale PageIndex to Millions of Documents: PageIndex File System is a Cloud-only, file-level tree indexing layer that lets PageIndex reason over an entire corpus, not just a single document.
Ready to Try It?
- Get a PageIndex API key
- Read the PageIndex Cloud documentation
For dedicated deployment (VPC or on-premises), contact us or book a demo.
⭐ Support Us
Leave us a star 🌟 if you like our project. Thank you!
Please cite this work as:
Mingtian Zhang, Yu Tang and PageIndex Team,
"PageIndex: Next-Generation Vectorless, Reasoning-based RAG",
PageIndex Blog, Sep 2025.
Or use the BibTeX citation.
@article{zhang2025pageindex,
  author = {Mingtian Zhang and Yu Tang and PageIndex Team},
  title = {PageIndex: Next-Generation Vectorless, Reasoning-based RAG},
  journal = {PageIndex Blog},
  year = {2025},
  month = {September},
  note = {https://pageindex.ai/blog/pageindex-intro},
}
© 2026 PageIndex AI