mirror of
https://github.com/NVIDIA/Model-Optimizer.git
synced 2026-11-01 07:53:10 +08:00
 h-guo18
2b296b2f62
# Support fine-tuning released DFlash/DSpark drafters (causal SWA, attention sink, warm start) ### What does this PR do? Type of change: New feature + bug fix Adds what ModelOpt was missing to fine-tune an already-published DFlash/DSpark draft model. The concrete target is [`nvidia/NVIDIA-Nemotron-3.5-Lightning-30B-A3B-BF16-DSpark`](https://huggingface.co/nvidia/NVIDIA-Nemotron-3.5-Lightning-30B-A3B-BF16-DSpark) on its hybrid Mamba/attention/MoE base, but every change is generic. Before this PR that checkpoint could not be trained faithfully — or even loaded: its attention-sink tensors were dropped as unexpected keys, its block-causal attention had no implementation, and its capture layers were silently overwritten with ModelOpt's defaults. **New user-facing options** (all default to today's behavior, so existing runs are unchanged): | Option | Values | Purpose | | --- | --- | --- | | `dflash_draft_attention` | `bidirectional` (default) / `causal` | Block-internal attention pattern. `causal` restricts a query at block position `i` to draft positions `<= i`. | | `dflash_attention_sink` | `false` (default) / `true` | Learnable per-head `attention_sink_bias [num_heads]` on every draft layer — one extra logit appended before the softmax and dropped after, so a head can put probability mass nowhere instead of being forced to attend inside its window (the GPT-OSS formulation). | | `dflash_init_checkpoint` | path | Warm-start the draft from an exported checkpoint instead of a random init. Any missing/unexpected/wrong-shaped tensor raises rather than warns. | | `dflash_architecture_config.target_layer_ids` | list | Which base layers feed the draft's `fc`. Previously recomputed unconditionally with no override. | **Bugs fixed along the way** (each one silently corrupts training rather than failing): - The exporter hard-coded `dflash_config.causal: False` and only wrote it under SWA, so even a correctly-trained causal draft would be served non-causally. It now reflects the trained setting, and emits `attention_sink_bias` when enabled. - `_build_generate_swa_mask` returned `None` whenever `swa_window_size` was unset, which would have dropped the causal structure at generation time while training used it. - `target_layer_ids` was recomputed from the uniform default on every convert. The released drafter uses `[1,5,19,29,41,51]`; the default for a 52-layer base is `[1,11,20,30,39,49]` — *different layers*. Here it surfaced as a matmul shape error only because the plane counts disagreed; with a matching count it would have trained on the wrong features silently. - The streaming dataset assumed the draft's aux layers all sit below the base's final layer (`aux = planes[:-1]`, `target = planes[-1]`). A draft whose top aux id *is* the final layer cannot get an extra plane — vLLM captures each layer once — so `final_aux_is_base_hidden` now lets the last plane serve both roles. It is derived from the model, not configured by hand. - DSpark head weights load from either the flat layout ModelOpt exports (upstream DeepSpec convention) or the nested `markov_head.` layout the NVIDIA release uses. Without the remap the two `[131072, 512]` Markov tables — ~14% of the draft's parameters — stay randomly initialized while everything else warm-starts, with no error. - `nemotron_h` is enabled in `_FINAL_NORM_TYPE_BY_MODEL_TYPE`: despite the hybrid stack, `NemotronHModel.norm_f` is a plain RMSNorm, and without the entry the offline/streaming fake base raises instead of reconstructing the distillation target. ### Usage ```yaml dflash: dflash_init_checkpoint: /path/to/NVIDIA-Nemotron-3.5-Lightning-30B-A3B-BF16-DSpark dflash_draft_attention: causal dflash_attention_sink: true dflash_swa_window_size: 1024 dflash_block_size: 8 dflash_mask_token_id: 990 dflash_architecture_config: target_layer_ids: [1, 5, 19, 29, 41, 51] ``` A full worked example is at `modelopt_recipes/general/speculative_decoding/dspark_nemotron35_warmstart.yaml`. ### Testing **Unit tests** — 124 pass (`test_hf_dflash.py`, `test_hf_dspark.py`, `test_hf_domino.py`, `test_hf_dflash_offline.py`, `test_modeling_final_norm.py`), 32 of them new: causal mask structure (lower-triangular per block, no cross-block leakage, context visibility unchanged), the sink math (degenerates to plain attention at `-inf`, absorbs mass monotonically, receives gradient), warm-start load/reject paths, Markov key remapping, and explicit `target_layer_ids`. **Checkpoint compatibility** — the released drafter loads with zero missing/unexpected keys and zero shape mismatches; all 77 tensors (6 attention sinks and both Markov tables included) match bit-exactly, and a training step runs with gradients reaching the sink and Markov parameters. **End-to-end streaming training** — Nemotron-3.5 base served by vLLM (1 node, TP8) feeding 8 trainer GPUs over NIXL; the draft warm-starts from the released checkpoint and trains with `causal` + sink + SWA 1024. 128 Daring-Anteater conversations, 20 epochs (the plot shows the first 5, where the trend is clearest — the curves flatten after that): 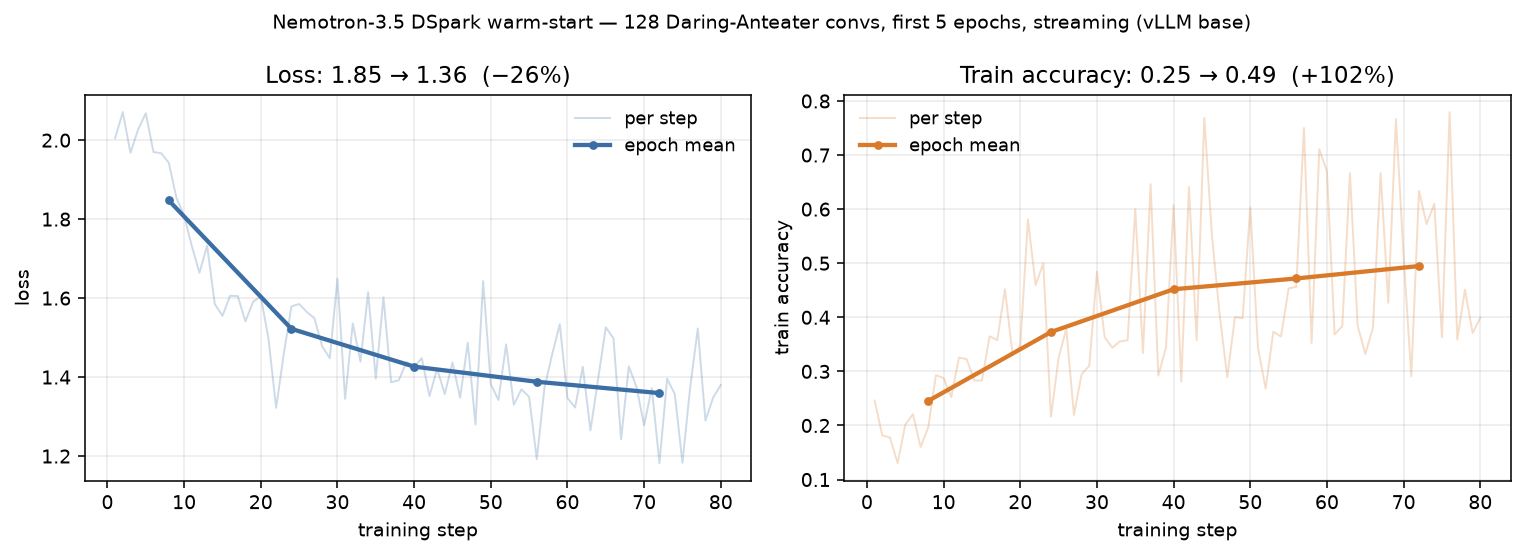 Over the first 5 epochs loss falls **1.85 → 1.36** and train accuracy rises **0.25 → 0.49**; across the full 20 epochs they reach **1.21** and **0.48** (peak 0.54) before flattening. This validates the pipeline end-to-end — capture layers, plane split, mask direction, sink loading and warm-start weights all have to be right for this curve to appear. It is *not* a model-quality result: 128 samples over 20 epochs overfits by construction, and the corpus is not generated by the base model, so the absolute numbers are not meaningful. ### TODO (follow-up) **A complete, robust checkpoint/config converter.** Both conversions are handled ad hoc here: - *Draft config → training config.* The recipe transcribes ~15 fields by hand from the drafter's `config.json`. Only the shape-bearing ones (`num_hidden_layers`, `num_attention_heads`, `intermediate_size`, `markov_rank`) fail loudly when mistyped; the rest — `mask_token_id`, `causal`, `swa_window_size`, `block_size` — train "successfully" on a wrong value and only surface later as a mysteriously low acceptance length. A converter should derive the whole block from the checkpoint, including its aliases (`pard_token`, `dspark_markov_rank`, `dflash_query_causal`, top-level `sliding_window` / `attention_sink_bias`) and duplicated fields. - *Weight layout.* The `markov_head.` remap is a load-time hook. A converter should normalize layouts explicitly, and decide whether export should also emit the release's aliases so a round-trip reproduces the original format (today it renames `architectures` to `DFlashDraftModel`). - *Base config.* Serving this base on vLLM needs its `config.json` layer-type vocabulary updated for the transformers-5 path (`mamba` → `linear_attention`, `attention` → `full_attention`, plus a matching `hybrid_override_pattern`). That is done by hand today and is not covered by this PR. ### Before your PR is "*Ready for review*" - **Make sure you read and follow [Contributor guidelines](https://github.com/NVIDIA/TensorRT-Model-Optimizer/blob/main/CONTRIBUTING.md)** and your commits are signed. - **Is this change backward compatible?**: Yes - **Did you write any new necessary tests?**: Yes - **Did you add or update any necessary documentation?**: Yes - **Did you update [Changelog](https://github.com/NVIDIA/TensorRT-Model-Optimizer/blob/main/CHANGELOG.rst)?**: No <!-- This is an auto-generated comment: release notes by coderabbit.ai --> ## Summary by CodeRabbit * **New Features** * Added configurable causal or bidirectional attention for DFlash models. * Added optional attention sinks, checkpoint warm starts, and explicit target-layer selection. * Improved streaming data handling for shared auxiliary and base hidden states. * Added Nemotron-3.5 Lightning DSpark warm-start training and serving recipes. * **Bug Fixes** * Preserved configured attention behavior during model export. * Prevented warm-start checkpoints from being reapplied during restoration. * Improved checkpoint compatibility, validation, and attention-mask handling. <!-- end of auto-generated comment: release notes by coderabbit.ai --> Signed-off-by: h-guo18 <67671475+h-guo18@users.noreply.github.com>

365 lines
16 KiB
Python
365 lines
16 KiB
Python
# Adapted from https://github.com/tatsu-lab/stanford_alpaca/blob/3783d18/train.py
|
|
|
|
# Copyright 2023 Rohan Taori, Ishaan Gulrajani, Tianyi Zhang, Yann Dubois, Xuechen Li
|
|
#
|
|
# Licensed under the Apache License, Version 2.0 (the "License");
|
|
# you may not use this file except in compliance with the License.
|
|
# You may obtain a copy of the License at
|
|
#
|
|
# http://www.apache.org/licenses/LICENSE-2.0
|
|
#
|
|
# Unless required by applicable law or agreed to in writing, software
|
|
# distributed under the License is distributed on an "AS IS" BASIS,
|
|
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
|
# See the License for the specific language governing permissions and
|
|
# limitations under the License.
|
|
|
|
# SPDX-FileCopyrightText: Copyright (c) 2024 NVIDIA CORPORATION & AFFILIATES. All rights reserved.
|
|
# SPDX-License-Identifier: Apache-2.0
|
|
#
|
|
# Licensed under the Apache License, Version 2.0 (the "License");
|
|
# you may not use this file except in compliance with the License.
|
|
# You may obtain a copy of the License at
|
|
#
|
|
# http://www.apache.org/licenses/LICENSE-2.0
|
|
#
|
|
# Unless required by applicable law or agreed to in writing, software
|
|
# distributed under the License is distributed on an "AS IS" BASIS,
|
|
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
|
# See the License for the specific language governing permissions and
|
|
# limitations under the License.
|
|
|
|
import argparse
|
|
import dataclasses
|
|
import os
|
|
|
|
import fsdp2_buffer_patch
|
|
import torch
|
|
import transformers
|
|
from eagle_utils import (
|
|
DFlashFSDP2ShardedSDExportCallback,
|
|
EagleTrainerWithAccLog,
|
|
EagleTrainingPlot,
|
|
LoRAWarmupCallback,
|
|
make_speculative_data_module,
|
|
patch_ring_attention_for_ttt,
|
|
)
|
|
from rich.pretty import pprint
|
|
from transformers.trainer_utils import get_last_checkpoint
|
|
|
|
import modelopt.torch.opt as mto
|
|
import modelopt.torch.speculative as mtsp
|
|
from modelopt.recipe import load_recipe
|
|
from modelopt.recipe.config import (
|
|
ModelOptDFlashRecipe,
|
|
ModelOptEagleRecipe,
|
|
ModelOptMedusaRecipe,
|
|
ModelOptSpeculativeRecipeBase,
|
|
)
|
|
from modelopt.torch.speculative.plugins.hf_domino import DominoLambdaCallback
|
|
from modelopt.torch.speculative.plugins.hf_training_args import (
|
|
TrainingArguments as SpecTrainingArgs,
|
|
)
|
|
from modelopt.torch.speculative.utils import load_vlm_or_llm, patch_transformers5_params_loading
|
|
from modelopt.torch.utils import print_rank_0
|
|
from modelopt.torch.utils.distributed import is_master, local_rank
|
|
|
|
torch.manual_seed(0)
|
|
mto.enable_huggingface_checkpointing()
|
|
|
|
if os.environ.get("PATCH_FSDP2_BUFFERS_TF457") == "1":
|
|
fsdp2_buffer_patch.apply()
|
|
|
|
|
|
# HF-compatible TrainingArguments with our speculative-decoding extensions, auto-derived
|
|
# from :class:`SpecTrainingArgs` so its field set can't drift from the Pydantic recipe schema.
|
|
# Used at runtime as ``HfTrainingArguments(**recipe.training.model_dump())`` to obtain a
|
|
# ``transformers.Trainer``-compatible dataclass.
|
|
HfTrainingArguments = dataclasses.make_dataclass(
|
|
"HfTrainingArguments",
|
|
[
|
|
(name, fi.annotation, dataclasses.field(default=fi.default))
|
|
for name, fi in SpecTrainingArgs.model_fields.items()
|
|
],
|
|
bases=(transformers.TrainingArguments,),
|
|
)
|
|
|
|
|
|
def _parse_cli() -> tuple[str, bool, list[str]]:
|
|
"""Parse --config (required) and --dry_run from argv; return remaining args as dotlist overrides.
|
|
|
|
Extra positional args use dotlist syntax, e.g.
|
|
``model.model_name_or_path=meta-llama/Llama-3.2-1B training.output_dir=ckpts/test``.
|
|
"""
|
|
p = argparse.ArgumentParser(add_help=False)
|
|
p.add_argument(
|
|
"--config",
|
|
required=True,
|
|
help=(
|
|
"Path to a modelopt speculative-decoding recipe YAML "
|
|
"(speculative_eagle / speculative_dflash / speculative_medusa)."
|
|
),
|
|
)
|
|
p.add_argument(
|
|
"--dry_run",
|
|
action="store_true",
|
|
help="Skip training: load base + mtsp.convert + save_pretrained, then exit. "
|
|
"Produces a ModelOpt HF checkpoint with untrained draft-head weights, suitable "
|
|
"for end-to-end plumbing tests (e.g. running scripts/export_hf_checkpoint.py).",
|
|
)
|
|
args, overrides = p.parse_known_args()
|
|
return args.config, args.dry_run, overrides
|
|
|
|
|
|
def init_distributed_env(training_args: transformers.TrainingArguments) -> None:
|
|
"""Resolve dp_shard_size from the live env and attach a ParallelismConfig in-place.
|
|
|
|
Reads ``WORLD_SIZE`` / ``torch.cuda.device_count()`` and (when actually distributed)
|
|
builds an ``accelerate.ParallelismConfig`` on ``training_args``. Kept out of the
|
|
Pydantic schema so the recipe stays a pure declarative spec.
|
|
"""
|
|
if training_args.cp_size < 1:
|
|
raise ValueError(f"cp_size must be >= 1, got {training_args.cp_size}.")
|
|
world_size = int(os.environ.get("WORLD_SIZE", torch.cuda.device_count() or 1))
|
|
if training_args.dp_shard_size is None:
|
|
training_args.dp_shard_size = world_size // training_args.cp_size
|
|
if training_args.dp_shard_size < 1:
|
|
raise ValueError(
|
|
f"dp_shard_size resolved to {training_args.dp_shard_size}; "
|
|
f"WORLD_SIZE ({world_size}) must be >= cp_size ({training_args.cp_size})."
|
|
)
|
|
|
|
if training_args.cp_size > 1 or training_args.dp_shard_size > 1:
|
|
parallel_size = training_args.dp_shard_size * training_args.cp_size
|
|
if world_size % parallel_size != 0:
|
|
raise ValueError(
|
|
f"world_size ({world_size}) must be divisible by "
|
|
f"dp_shard_size ({training_args.dp_shard_size}) * "
|
|
f"cp_size ({training_args.cp_size}) = {parallel_size}"
|
|
)
|
|
try:
|
|
from accelerate import ParallelismConfig
|
|
except ImportError as e:
|
|
raise ImportError(
|
|
"cp_size>1 or dp_shard_size>1 requires `accelerate` for ParallelismConfig. "
|
|
"Install it via `pip install accelerate`."
|
|
) from e
|
|
training_args.parallelism_config = ParallelismConfig(
|
|
cp_size=training_args.cp_size,
|
|
dp_shard_size=training_args.dp_shard_size,
|
|
dp_replicate_size=world_size // parallel_size,
|
|
)
|
|
|
|
|
|
def _is_hf_format_checkpoint(checkpoint: str | None) -> bool:
|
|
"""True if the checkpoint dir holds consolidated HF weights (from_pretrained-loadable).
|
|
|
|
FSDP2 SHARDED_STATE_DICT checkpoints contain only distributed shards
|
|
(``pytorch_model_fsdp_*/``), no ``model.safetensors`` — those return False, signalling
|
|
the caller to load the base model and resume via the Trainer instead. This inspects the
|
|
on-disk format of the *resume* checkpoint, which is a property of the existing bytes and
|
|
is independent of the current run's save mode (the two can differ across runs), so it's
|
|
intentionally separate from the save-time FSDP state-dict-type gate used for the export
|
|
callback.
|
|
"""
|
|
if not checkpoint:
|
|
return False
|
|
hf_files = ("model.safetensors", "pytorch_model.bin", "model.safetensors.index.json")
|
|
return any(os.path.isfile(os.path.join(checkpoint, f)) for f in hf_files)
|
|
|
|
|
|
def train():
|
|
config_path, dry_run, overrides = _parse_cli()
|
|
recipe = load_recipe(config_path, overrides=overrides)
|
|
if not isinstance(recipe, ModelOptSpeculativeRecipeBase):
|
|
raise ValueError(
|
|
f"main.py expects a speculative-decoding recipe (eagle / dflash / medusa); "
|
|
f"got {type(recipe).__name__} from {config_path!r}."
|
|
)
|
|
|
|
# Pydantic-typed sections flow straight through as *_args; only TrainingArguments is
|
|
# reconstructed as an HF dataclass so it can be handed to transformers.Trainer.
|
|
training_args = HfTrainingArguments(**recipe.training.model_dump())
|
|
init_distributed_env(training_args)
|
|
|
|
if not dry_run and recipe.data.mode in ("online", "streaming") and not recipe.data.data_path:
|
|
raise ValueError(f"data.mode={recipe.data.mode!r} requires data.data_path.")
|
|
if training_args.cp_size > 1:
|
|
patch_ring_attention_for_ttt()
|
|
# accelerate requires an fsdp_plugin when cp_size > 1; the --fsdp launcher flags that
|
|
# used to provide one were dropped from launch_train.sh.
|
|
if not training_args.fsdp_plugin_args:
|
|
training_args.fsdp = "full_shard"
|
|
training_args.fsdp_config = {"fsdp_version": 2}
|
|
training_args.fsdp_plugin_args = training_args._process_fsdp_args()
|
|
if is_master():
|
|
pprint(recipe)
|
|
|
|
# Detect checkpoint to resume from
|
|
last_checkpoint = (
|
|
get_last_checkpoint(training_args.output_dir)
|
|
if os.path.isdir(training_args.output_dir)
|
|
else None
|
|
)
|
|
if last_checkpoint:
|
|
print_rank_0(f"Last checkpoint detected: {last_checkpoint}")
|
|
|
|
checkpoint = training_args.resume_from_checkpoint or last_checkpoint
|
|
|
|
use_offline_training = recipe.data.mode != "online"
|
|
|
|
# Resume path depends on the existing checkpoint's on-disk format: consolidated HF
|
|
# weights load via from_pretrained; FSDP sharded checkpoints load the base model and
|
|
# resume through the Trainer.
|
|
checkpoint_is_hf = _is_hf_format_checkpoint(checkpoint)
|
|
|
|
if checkpoint_is_hf:
|
|
assert checkpoint is not None # guaranteed by checkpoint_is_hf
|
|
with patch_transformers5_params_loading():
|
|
model = load_vlm_or_llm(
|
|
checkpoint, dtype="auto", trust_remote_code=recipe.model.trust_remote_code
|
|
)
|
|
tokenizer = transformers.AutoTokenizer.from_pretrained(
|
|
checkpoint, trust_remote_code=recipe.model.trust_remote_code
|
|
)
|
|
else:
|
|
if checkpoint:
|
|
print_rank_0(
|
|
f"Checkpoint {checkpoint} is not in HF format (FSDP distributed checkpoint). "
|
|
f"Loading base model and resuming via Trainer."
|
|
)
|
|
model_name_or_path = recipe.model.model_name_or_path
|
|
if model_name_or_path is None:
|
|
raise ValueError(
|
|
"model.model_name_or_path must be set in the recipe YAML or via a dotlist override."
|
|
)
|
|
# To avoid OOM for large models, we load and convert model on CPU first.
|
|
# Model will be moved to GPU during HF trainer.init().
|
|
model = load_vlm_or_llm(
|
|
model_name_or_path,
|
|
use_fake_base=recipe.model.use_fake_base_for_offline,
|
|
use_offline_training=use_offline_training,
|
|
dtype="auto",
|
|
device_map="cpu",
|
|
trust_remote_code=recipe.model.trust_remote_code,
|
|
)
|
|
tokenizer = transformers.AutoTokenizer.from_pretrained(
|
|
model_name_or_path,
|
|
model_max_length=training_args.training_seq_len,
|
|
trust_remote_code=recipe.model.trust_remote_code,
|
|
)
|
|
if isinstance(recipe, ModelOptMedusaRecipe):
|
|
medusa_cfg: dict = recipe.medusa.model_dump()
|
|
mtsp.convert(model, [("medusa", medusa_cfg)])
|
|
elif isinstance(recipe, ModelOptEagleRecipe):
|
|
eagle_cfg: dict = recipe.eagle.model_dump()
|
|
mtsp.convert(model, [("eagle", eagle_cfg)])
|
|
# Load draft vocab cache
|
|
mtsp.plugins.HFEagleModel.load_draft_vocab_cache(model, recipe.data.draft_vocab_cache)
|
|
elif isinstance(recipe, ModelOptDFlashRecipe):
|
|
# Fall back to tokenizer.mask_token_id when not set in the recipe; require one of the two.
|
|
if recipe.dflash.dflash_mask_token_id is None:
|
|
recipe.dflash.dflash_mask_token_id = getattr(tokenizer, "mask_token_id", None)
|
|
if recipe.dflash.dflash_mask_token_id is None:
|
|
raise ValueError(
|
|
"dflash.dflash_mask_token_id is required: set it in the recipe YAML "
|
|
"or use a tokenizer that defines mask_token_id."
|
|
)
|
|
dflash_cfg: dict = recipe.dflash.model_dump()
|
|
mtsp.convert(model, [("dflash", dflash_cfg)])
|
|
else:
|
|
raise ValueError(f"Unsupported speculative recipe type: {type(recipe).__name__}")
|
|
|
|
if dry_run:
|
|
# is_master() is unreliable here: we return before the HF Trainer inits torch.distributed,
|
|
# so use local_rank() (env-based) to keep a single writer to output_dir.
|
|
if local_rank() == 0:
|
|
os.makedirs(training_args.output_dir, exist_ok=True)
|
|
model.save_pretrained(training_args.output_dir)
|
|
tokenizer.save_pretrained(training_args.output_dir)
|
|
print_rank_0(
|
|
f"[dry-run] saved ModelOpt HF checkpoint (untrained draft head) to "
|
|
f"{training_args.output_dir}"
|
|
)
|
|
return
|
|
|
|
print_rank_0("Loading dataset...")
|
|
is_dflash = isinstance(recipe, ModelOptDFlashRecipe)
|
|
data_module = make_speculative_data_module(
|
|
tokenizer,
|
|
recipe.data,
|
|
train_len=training_args.training_seq_len,
|
|
answer_only_loss=training_args.answer_only_loss,
|
|
shift_labels=not is_dflash,
|
|
final_aux_is_base_hidden=recipe.data.final_aux_is_base_hidden,
|
|
)
|
|
|
|
callbacks = [EagleTrainingPlot(training_args.ar_validate_steps, training_args.estimate_ar)]
|
|
if (
|
|
isinstance(recipe, ModelOptEagleRecipe)
|
|
and recipe.eagle.eagle_base_lora
|
|
and recipe.eagle.eagle_base_lora_warmup_steps > 0
|
|
):
|
|
callbacks.append(LoRAWarmupCallback(recipe.eagle.eagle_base_lora_warmup_steps))
|
|
# Domino (dflash recipe with projector_type=domino) needs the lambda_base
|
|
# curriculum schedule driven by the trainer's global step.
|
|
if (
|
|
isinstance(recipe, ModelOptDFlashRecipe)
|
|
and recipe.dflash.dflash_architecture_config.get("projector_type") == "domino"
|
|
):
|
|
callbacks.append(DominoLambdaCallback())
|
|
# Leave training_args.ignore_data_skip at its default (False). The dataset is
|
|
# map-style, so HF Trainer's resume skips consumed indices at the batch-sampler
|
|
# level (accelerate.skip_first_batches) without re-fetching them, landing at the
|
|
# exact data position. Setting it True would restart the data order from the top.
|
|
|
|
# Tell the draft model the CP degree so it skips the dense eagle mask under CP.
|
|
model.eagle_cp_size = training_args.cp_size
|
|
|
|
trainer = EagleTrainerWithAccLog(
|
|
model=model,
|
|
processing_class=tokenizer,
|
|
args=training_args,
|
|
callbacks=callbacks,
|
|
**data_module,
|
|
)
|
|
|
|
if os.environ.get("PATCH_FSDP2_BUFFERS_TF457") == "1":
|
|
fsdp2_buffer_patch.patch_accelerator(trainer.accelerator)
|
|
|
|
# DFlash: export the draft submodule after each checkpoint save — but only under FSDP2
|
|
# SHARDED_STATE_DICT, where checkpoints are distributed shards the post-training
|
|
# export_hf_checkpoint.py pass can't read. Gate by reading the live FSDP state dict
|
|
# type off the accelerator; full-state-dict runs (DDP, single-device, FSDP2
|
|
# FULL_STATE_DICT) use the launcher's post-run export instead.
|
|
if isinstance(recipe, ModelOptDFlashRecipe):
|
|
fsdp_plugin = getattr(trainer.accelerator.state, "fsdp_plugin", None)
|
|
sd_type = str(getattr(fsdp_plugin, "state_dict_type", "") or "")
|
|
if "SHARDED_STATE_DICT" in sd_type:
|
|
trainer.add_callback(DFlashFSDP2ShardedSDExportCallback())
|
|
print_rank_0("DFlash: FSDP2 SHARDED_STATE_DICT — enabling per-save draft export.")
|
|
else:
|
|
print_rank_0(
|
|
f"DFlash: checkpoints use {sd_type or 'a full state dict'}; relying on the "
|
|
"launcher's post-run export (no per-save export callback added)."
|
|
)
|
|
|
|
# Manually enable this to return loss in eval
|
|
trainer.can_return_loss = True
|
|
# Make sure label_smoother is None
|
|
assert trainer.label_smoother is None, (
|
|
"label_smoother is not supported in speculative decoding!"
|
|
)
|
|
|
|
# Diagnostic (no-op unless DFLASH_LOG_PARAM_DTYPES=1): verifies FSDP2 dtype sync.
|
|
fsdp2_buffer_patch.log_param_dtypes(trainer.model)
|
|
|
|
print_rank_0("Start training...")
|
|
trainer.train(resume_from_checkpoint=checkpoint)
|
|
trainer.save_state()
|
|
trainer.save_model(training_args.output_dir)
|
|
|
|
|
|
if __name__ == "__main__":
|
|
train()
|