mirror of
https://github.com/NVIDIA/Model-Optimizer.git
synced 2026-10-21 06:10:05 +08:00
pull-request/2240
484
Commits
| Author | SHA1 | Message | Date | |
|---|---|---|---|---|
 gcunhaseandmodelopt-fix-agent-bot |
1db503675d |
sensitivity: revert Gelu autotune extension and address round-3 review nits
Round-3 bot review flagged five items on top of ``c7d455e``. This commit
addresses all five.

op_types.py -- revert Gelu from get_activation_ops
==================================================

An earlier round added ``"Gelu"`` to ``get_activation_ops()``, which
consumers in ``autotuner_base.py:547`` treat as a cross-cutting behavior
change on Gelu-containing autotuned models (see the reviewer's note that
the addition was undocumented in both CHANGELOG and PR body). Reverting
restores the pre-round-2 behavior and keeps this PR scoped to the
sensitivity primitive only. If autotune needs the Gelu recognition as a
bug fix, it will land in a follow-up PR against ``autotuner_base.py``
with its own CHANGELOG entry.

examples/onnx_ptq/README.md -- collapse mode-description comment
================================================================

A previous edit left a hybrid fragment ("Coverage mode (default) leaves
the / walks targets in descending score order ..."). Collapsed the whole
paragraph to a single line -- the mode semantics are already documented
in the Sphinx guide (``_onnx_quantization.rst``) and in the
``suggest_exclusion`` docstring; the example README doesn't need to
re-explain them.

tests/gpu/onnx/quantization/sensitivity/test_score.py
=====================================================

- Import path: switched ``from tests._test_utils....`` to
  ``from _test_utils....`` to match the repo convention across every
  other ONNX test file (``tests/`` is on ``pythonpath`` per
  ``pyproject.toml``, so the shorter form is what actually collects
  under a plain ``pytest tests/gpu/...`` invocation).
- Hoisted ``import math`` and ``import shutil`` from inside test bodies
  to the module-level import block. Both are stdlib and unconditional.

modelopt/onnx/quantization/sensitivity/__main__.py
==================================================

``main()``'s docstring promised "non-zero if ``score`` raises" but
uncaught exceptions actually propagate to the caller (the CLI unit
tests assert ``pytest.raises`` on the ONNX-oversize and empty-calib-dir
paths). Reworded the ``Returns:`` block to describe the real behavior:
``0`` on success; exceptions propagate; Python's default non-zero exit
code applies at the process boundary.

Signed-off-by: gcunhase <4861122+gcunhase@users.noreply.github.com>
Co-Authored-By: modelopt-fix-agent-bot (Opus 4.7) <noreply@anthropic.com>
|
||
|
gcunhaseandmodelopt-fix-agent-bot
|
521f030cd4 |
sensitivity: address CodeRabbit findings (picker collision, docs, CLI tests, utils move)
picker.py -- singleton-name collision fix
=========================================

Regression: when ``blocks=`` was set and an unmatched node's name happened to
equal a configured group name, ``_assign_groups``'s
``groups.setdefault(key, []).append(node_name)`` silently merged the unmatched
node into that group instead of keeping it as an isolated singleton. On a
graph like ``scores={"g_n1": 0.01, "g": 10.0}, blocks={"g": [r"^g_"]}``, the
standalone node ``g`` (score 10.0) would land inside the ``g`` group's member
list alongside ``g_n1``, inflating the group's aggregated score and altering
which groups the coverage / threshold picker selected.

Fix: prefix unmatched-node singleton keys with a sentinel (``"\0singleton:"``)
that cannot collide with any user-supplied group name. Group ranking still
receives correct (name, members) pairs; the sentinel is internal to the
``groups`` dict and does not leak into the return value (the picker returns
member node names, not group keys).

Added ``test_unmatched_node_name_collision_with_group_name_stays_isolated``
in ``test_picker.py`` as a regression witness.

utils.py -- host ``validate_file_size``
=======================================

``modelopt.onnx.quantization.sensitivity.__main__`` imported ``validate_file_size``
from ``modelopt.onnx.quantization.__main__``, pulling the main quantize CLI's
full import graph (``autotune.utils``, ``quantize``, ...) into the sensitivity
CLI just to reuse a 15-line size check. If the main CLI later grows a heavier
import, the sensitivity CLI breaks silently.

Moved ``validate_file_size`` to ``modelopt/onnx/utils.py`` alongside the other
low-level ONNX helpers. Both CLIs now import from ``modelopt.onnx.utils``. No
behavior change.

docs -- coverage-mode wording + sample output
=============================================

The ``_onnx_quantization.rst`` guide and ``examples/onnx_ptq/README.md`` still
described coverage mode as "excludes the largest node set whose cumulative
sensitivity score stays at or below ``coverage * total_mass``" -- the same
phrasing the ``suggest_exclusion`` docstring was corrected away from in
an earlier round. Synced to the rank-prefix wording ("walks targets in
descending score order and accumulates them until the next one would push
cumulative sensitivity above ``coverage * total_mass``").

The rendered-ranking example in ``_onnx_quantization.rst`` also could not
be produced by ``_render_ranked_table()``: it mixed ``~0`` string values
(``_render_ranked_table`` uses ``{value:.3f}``, never ``~0``) with a
visible ``Gemm 0 <-- lowest impact`` row (zero-score rows are hidden by
default) and a ``1 target(s) hidden`` footer. Regenerated the sample to
match actual CLI output: drop the ``~0`` rows, move the lowest-impact
marker to the last visible non-zero row (MatMul 0.015), and update the
hidden-count footer to 4.

test_cli.py -- coverage for previously untested CLI helpers
===========================================================

New ``tests/unit/onnx/quantization/sensitivity/test_cli.py`` covers the CLI
functions that landed in earlier rounds but had no unit tests:

* ``_default_output_json``: absolute-path and relative-path derivation.
* ``_validate_calibration_dir``: empty dir raises, under-limit dir passes,
  per-file cap trips, aggregate cap trips.
* ``_render_ranked_table``: no scores + no failed, no scores + all failed,
  normal ranking with hidden zeros, ``show_zero_scores=True``, all-zero
  footer, failed footer.
* ``main()``: synthetic-calibration happy path, default output-JSON path,
  oversize ONNX rejected before ``score()`` is called, calibration-directory
  path validated before ``score()`` runs.

17 tests total, all pure Python (``score`` monkeypatched, no GPU / no real
ONNX quantization). Wall-clock < 1 s.

test_quantize_api.py -- hoist local imports
===========================================

Moved ``onnx_graphsurgeon as gs`` and ``modelopt.onnx.utils.save_onnx``
from inside ``test_quantize_honors_nodes_to_quantize_allowlist`` to
module scope. Neither is optional or circular.

Signed-off-by: gcunhase <4861122+gcunhase@users.noreply.github.com>
Co-Authored-By: modelopt-fix-agent-bot (Opus 4.7) <noreply@anthropic.com>
|
||
|
gcunhaseandmodelopt-fix-agent-bot
|
37359fdd0c |
docs(onnx_ptq): fix two typos in sensitivity-driven exclusion section
- ``we proppose`` -> ``we propose`` - ``individual nodes.See the`` -> ``individual nodes. See the`` (missing space after period) Signed-off-by: gcunhase <4861122+gcunhase@users.noreply.github.com> Co-Authored-By: modelopt-fix-agent-bot (Opus 4.7) <noreply@anthropic.com> |
||
|
gcunhaseandmodelopt-fix-agent-bot
|
c14569f5f5 |
docs(onnx_ptq): add sensitivity-driven node exclusion section to README
Adds a new subsection under Advanced Features documenting the `modelopt.onnx.quantization.sensitivity` primitive as a downstream tool for recovering accuracy after quantization. Shows the end-to-end Python flow -- `score()` -> `suggest_exclusion()` + `summarize_exclusion()` -> `quantize(nodes_to_exclude=...)` -- reusing the same `vit_base_patch16_224.onnx` and `calib.npy` produced earlier in the example via `download_example_onnx.py` and `image_prep.py`; no extra setup needed. Hyperlinks to the guide's Quantization Sensitivity Scan section and to the block-picker sub-anchor cover the full API reference, block-picker recipe, and validation results without duplicating them in the example README. Signed-off-by: gcunhase <4861122+gcunhase@users.noreply.github.com> Co-Authored-By: modelopt-fix-agent-bot (Opus 4.7) <noreply@anthropic.com> |
||
|
Keval MorabiaandClaude Opus 5
|
8810eb5e31 |
Add ModelOpt recipe for DeepSeek-V4-Pro-0813 NVFP4 and --recipe to its PTQ script (#2287)
### What does this PR do?

Type of change: new feature

The quantization config for `nvidia/DeepSeek-V4-Pro-0813-NVFP4` existed
only as Python inside `_build_nvfp4_experts_cfg()`, so the released
checkpoint had **no entry in `modelopt_recipes/`** and could not be
looked up by name the way every other published model can.
`modelopt_recipes/README.md` states the goal directly — a recipe is
*"the single, version-controlled source of truth for how a model is
optimized … expressed as data instead of code"* — and this model was the
exception.

This adds:

-
`modelopt_recipes/huggingface/models/deepseek-ai/DeepSeek-V4-Pro-0813/ptq/nvfp4_experts_only.yaml`,
composed from the existing `configs/ptq/units/base_disable_all` and
`configs/numerics/nvfp4` units.
- An optional `--recipe` flag on `examples/deepseek/deepseek_v4/ptq.py`.

It follows **`examples/kimi/kimi_k3`**, the closest precedent: a very
large MoE whose source already ships MXFP4 routed experts, converted via
`--cast_mxfp4_to_nvfp4` rather than through `examples/hf_ptq`, and
already wired to `--recipe` with a published YAML.

### Usage

```sh
torchrun --nproc-per-node 8 deepseek_v4/ptq.py \
    --model_path  <mp8_checkpoint> \
    --config      <DeepSeek-V4-Pro-0813>/inference/config.json \
    --calib_size  512 \
    --calib_seq   4096 \
    --output_path <amax_dump> \
    --recipe huggingface/models/deepseek-ai/DeepSeek-V4-Pro-0813/ptq/nvfp4_experts_only
```

Omitting `--recipe` keeps the previous behaviour exactly.

### Testing

- `load_recipe` resolves the YAML and yields `num_bits (2, 1)` with
`block_sizes {-1: 16, type: dynamic, scale_bits: (4, 3)}` — identical to
the hardcoded config.
- **Equivalence checked behaviourally**, not by eyeballing dicts: both
configs were resolved against representative quantizer names using
last-match-wins, and agree on all of them.

  | quantizer | hardcoded | recipe |
  | --- | --- | --- |
| `...ffn.experts.17.w1_weight_quantizer` | enabled, NVFP4 | enabled,
NVFP4 |
| `...ffn.experts.17.w2_input_quantizer` | enabled, NVFP4 | enabled,
NVFP4 |
  | `...ffn.shared_experts.w1_weight_quantizer` | disabled | disabled |
  | `...attn.wq_weight_quantizer` | disabled | disabled |
  | `mtp.0.ffn.experts.2.w1_weight_quantizer` | disabled | disabled |
  | `lm_head_weight_quantizer` | disabled | disabled |

- `mtq.quantize` documents `algorithm` as a string **or** a dict keyed
on `method`, so the recipe's `{'method': 'max'}` needs no translation.
- `pre-commit` clean, including `validate modelopt recipes`.

No GPU run: this changes config plumbing only, and the default path is
byte-identical to before.

### Before your PR is "*Ready for review*"

- Is this change backward compatible?: ✅ — `--recipe` is optional and
defaults to `None`; without it `_build_nvfp4_experts_cfg()` is used
exactly as before.
- If you copied code from any other sources or added a new PIP
dependency, did you follow guidance in `CONTRIBUTING.md`: ✅ — no new
dependencies; `modelopt.recipe` is already a first-party import.
- Did you write any new necessary tests?: N/A — no new logic;
equivalence to the existing config is the property that matters and is
documented above.
- Did you update
[Changelog](https://github.com/NVIDIA/Model-Optimizer/blob/main/CHANGELOG.rst)?:
N/A — recipe library addition; recent recipe/example PRs add no entry.
- Did you get Claude approval on this PR?: ❌ — not yet run.

### Additional Information

The recipe covers the **quant config only**. `--calib_seq` — the setting
that mattered most for this checkpoint, since the 512 default does not
cover long-context activation ranges — is a dataloader argument rather
than part of the `mtq` config, so it stays on the CLI. Worth knowing if
the recipe is ever treated as a complete reproduction of the released
checkpoint: it is not, on its own.

🤖 Generated with [Claude Code](https://claude.com/claude-code)

<!-- This is an auto-generated comment: release notes by coderabbit.ai
-->
## Summary by CodeRabbit

* **New Features**
* Added post-training quantization support for DeepSeek-V4-Pro-0813
routed experts using NVFP4.
* Added an optional recipe path for selecting equivalent quantization
settings.
* Preserved source formats for shared experts, attention, embeddings,
output layers, and MTP components.

* **Bug Fixes**
* Improved validation for missing or malformed quantization
configurations.
* Added safeguards against unsupported formats, scopes, algorithms, and
enabled MTP quantizers.

* **Documentation**
* Documented checkpoint conversion behavior, calibration requirements,
and supported quantization workflows.
<!-- end of auto-generated comment: release notes by coderabbit.ai -->

---------

Signed-off-by: Keval Morabia <28916987+kevalmorabia97@users.noreply.github.com>
Co-authored-by: Claude Opus 5 <noreply@anthropic.com>
|
||
|
Frida HouandClaude Opus 5
|
029c67f27e |
feat(export): export each decoder layer as layerwise calibration finishes it (#2136)
### What does this PR do?

Type of change: new feature

Layerwise calibration can already resume, but only through a
full-precision scratch checkpoint, and a completed run still pays for a
second whole-model export pass over it.

`layerwise.export_dir` writes each decoder layer to its own quantized
shard as soon as calibration finishes with it, so the directory is a
complete, loadable checkpoint when the last layer lands and
`export_hf_checkpoint()` is skipped. The shards *are* the resume
artifact: a restarted run reuses layers already on disk instead of
recalibrating and re-exporting them, so no full-precision copy of the
model accumulates. The resume directory beside it holds only the current
boundary's cached activations and the per-layer output shapes.

Setting the config field is the whole switch — no CLI flag. `hf_ptq.py`
rewrites its value to `--export_path`, and derives the resume directory
(`<export_path>.layerwise_resume`) when you haven't chosen one.

One shard per layer is what makes resume safe: shards are written whole
and named from the layer index, so a crash can lose the layer in flight
but never corrupt an earlier one, and a re-run overwrites in place.

Because a resumed run never recalibrates the layers it skipped, **the
in-memory model is not valid for inference afterwards**; the field
implies `--skip_generate`.

Includes a pre-existing `main` fix this depends on: `_is_layerwise` used
`getattr` on an algorithm that YAML parses as a **dict**, so it answered
`False` for every layerwise recipe in the repo and the batch-size probe
it gates was never skipped. **Behaviour change:** `--batch_size 0` now
yields `batch_size=1` for layerwise recipes, as its comment intends.
Detection also now scans every algorithm entry rather than the first, so
a list-form recipe whose `layerwise` block is not first is recognised as
layerwise — same batch-size consequence. Nothing else on the non-fused
paths changes: `FUSION_FREE_FORMATS` is the exact set the inline list
held, `save_non_weight_artifacts` is a lift of the streaming exporter's
own block, and the calibration-loop changes are gated on an exporter
being present.

**Refused before calibration starts**, since each would otherwise
produce a silently different checkpoint rather than fail:

| Refused | Why |
|---|---|
| AWQ / SVDQuant | need pre-quant-scale steps that are still whole-model
|
| Weight-tied quantized modules | `sync_tied_input_amax` merges amaxes
across a partner that may be uncalibrated or already written |
| Multi-process (FSDP2) | every rank would write the same shards |
| Multimodal (VLM) | calibration runs on the extracted language model |
| MTP models | exclusions applied after calibration has written
everything |
| AutoQuantize recipes | only the mono-quantize path retargets
`export_dir` |
| Spec-dec, `--vllm_fakequant_export`, non-dense sparsity,
`int8_smoothquant`, encoder-decoder `model_type` | each routes to a
second exporter that would overwrite `--export_path` |
| `export_dir` on more than one algorithm entry, or on any but the last
| export finalizes shards as calibration walks the layers, so a later
pass would change the model after its checkpoint was written |

Shards are also bound to the run that produced them
(`.layerwise_export.json`: model class, layer count, formats, KV-cache
format, and a digest of the resolved quant config), so one run's
manifest cannot finalize another's shards. Source weights are not
digested — that would mean reading the whole model — so
differently-trained weights at the same path compare equal.

### Why a separate exporter

Three reuse paths were considered before adding one:

- **Extend `_StreamingShardWriter`.** It buffers by `max_shard_size`
into `__shard_part_*` temp names and renames to canonical names only in
`finalize()`, once the shard count is known. The resume invariant needs
the opposite: a stable `model-layer-00007.safetensors` committed when
layer 7 finishes, so "shard exists" means "layer done" across a restart.
Forcing a per-layer flush still leaves temp names, finalize-time
renaming, and an in-memory `_key_to_part` — every method would change.
- **Keep the layerwise checkpoint and run the streaming exporter at the
end.** This works, and it is why the pitch above is *not* durability:
that already exists. What it leaves is a second whole-model pass owed
*after* calibration finishes — itself needing a GPU session — where
per-layer export makes the last calibrated layer also the last exported
one. Scratch size only separates them for weight-mutating calibrators:
`save_layer_state` is off under per-layer export, but with
`calib_mutates_weights: false` (the shipped recipe) the checkpoint holds
just amax buffers either way.
- **Factor a shared per-module writer around `ExportContext`.** The
right long-term shape, but it touches all three existing export paths;
doing it here makes this change larger, not smaller.

One deliberate divergence from `_StreamingShardWriter` worth knowing
about: it clones tensors that share storage, this path lets `save_file`
raise instead. No model was found where the clone fires, and copying
unattributed aliases can hide a real bug rather than surface it. If a
checkpoint ever trips it, that is information we want.

Happy to take a different call on this — flagging it for maintainer
sign-off rather than assuming it.

### Usage

```bash
python examples/hf_ptq/hf_ptq.py --pyt_ckpt_path <model> --export_path <out> \
    --recipe modelopt_recipes/general/ptq/nvfp4_experts_only-kv_fp8_layerwise_export.yaml
```

Interrupt and rerun the same command: calibration resumes from the last
committed layer, finished shards are reused, and a run that had already
finished every layer only re-runs `finalize()`.

```yaml
quantize:
  algorithm:
    method: max
    layerwise:
      enable: true
      calib_mutates_weights: false
      export_dir: /tmp/modelopt_layerwise_export   # presence is the switch; value replaced with --export_path
      # checkpoint_dir omitted -> derived as <export_path>.layerwise_resume
```

### Testing

Each row exports the same calibration two ways — per-layer, and
whole-model via `export_hf_checkpoint()` — and compares them **tensor
for tensor and config for config**.

The 35B row was re-run on the current head, against a baseline built
from a `main` worktree rather than from this branch, so it covers both
"per-layer differs from whole-model" and "this branch broke the shared
whole-model path". The other rows date from earlier heads; the code they
exercise is unchanged, but they are not fresh runs.

| Model | Config | Result |
|---|---|---|
| Qwen3.6-35B-A3B (40 layers, 256 fused experts) | NVFP4 W4A4
experts-only + FP8 KV | 123,513 tensors, 0 mismatched; `config.json`,
`hf_quant_config.json`, `generation_config.json` all identical |
| Qwen3-30B-A3B (48 layers, 128 per-expert linears) | NVFP4 experts
(`nvfp4_static` weights) + `mse`, offload | 74,163 tensors, 0 mismatched
|
| Qwen3-30B-A3B | same, `SIGKILL` after 25/48 layers, then resumed |
74,163 tensors, 0 mismatched **vs the uninterrupted run** |
| Llama-3.1-8B-Instruct | FP8 dense + FP8 KV, resident | 803 tensors, 0
mismatched |

**Refusals verified on real checkpoints**, each writing **zero shards**
and never reaching calibration — the "refused before calibration starts"
claim above, demonstrated rather than asserted: multimodal and MTP
(Qwen3.6-35B, the MTP case on a text-only view since the multimodal gate
fires first), tied embeddings (Qwen3-0.6B), and multi-process (2-rank
`torchrun --use_fsdp2`, Llama-3.1-8B).

**Served, not just compared.** Under vLLM 0.27.1 (Marlin NVFP4 kernels,
SM 8.9): the 30B checkpoint exported three ways — whole-model,
per-layer, per-layer-resumed-after-a-kill — and the 8B exported both
ways all load and produce **identical greedy generations, 4/4 prompts**
within each model.

**Index integrity** on every checkpoint above: each `weight_map` key
resolves to the shard actually holding it; 0 missing, 0 extra, 0
mis-routed. Tensor equality alone never exercises that, and it is the
one artifact per-layer export builds differently.

Resume state stays bounded: **332 KB beside 22 GB** of shards on the
35B, **396 KB beside 19 GB** on the 30B — the committed boundary's
activations only, not one set per layer.

Not covered: the `trust_remote_code` `*.py` copy path.
Nemotron-Nano-12B-v2-Base fails with a CUDA illegal memory access on
these cards, on the whole-model baseline too, so it is an environment
limit rather than a result.

**Comparing the configs is new, and it caught a real bug.**
`get_quant_config` reports on the quantizer modules, which
`export_layer` replaces as it goes, so reading it in `finalize()`
described a model with no quantizers left: the checkpoint advertised
`quant_algo: null` while its weights were packed NVFP4, and under the
shipped experts-only recipe `hf_quant_config.json` was not written at
all. It is snapshotted in `__init__` now, beside the kv-cache format
already captured there — which is why that one field was correct while
the rest were not. Uniform FP8 and NVFP4 hid it because their configs
survive the conversion; only a mixed model loses its algo, and mixed is
what every shipped layerwise-export recipe is. Reverting the fix fails
`test_moe_export_matches` and passes the ten uniform-format cases,
matching what the 35B shows.

**24 GPU tests** in `tests/gpu/torch/export/test_layerwise_export.py`.
The equivalence oracle is a cross-product: {FP8, NVFP4, NVFP4 +
`get_qdq_activations_from_prev_layer`, mixed FP8/NVFP4, KV-cache} ×
{fresh, resumed-after-interruption}, each compared tensor-for-tensor
against `export_hf_checkpoint`. Plus MoE export; resume fail-fast;
resume artifacts replaced and pruned; complete-manifest finalize-only;
shards-without-manifest refusal; shards-from-a-different-run refusal
(format and module selection); identity-without-shards does not block a
rerun; export-does-not-mutate-the-model; index routes every key to the
shard holding it; AWQ refusal (from config, and after calibration);
export-without-`checkpoint_dir`.

**Unit tests** in `tests/examples/hf_ptq/test_example_utils.py` cover
the list-valued `algorithm` shapes: which entry owns export, whose
`checkpoint_dir` is derived, per-entry resume bases, both ambiguity
refusals, and the recipe shapes `recipe_layerwise_blocks` normalizes
(dict, list order, config object, and the empty cases).

`tests/gpu/torch/export/` 150 passed / 2 skipped (pre-existing env
skips) · `tests/unit/recipe` 284 · `tests/unit/torch/export` 186 ·
`test_layerwise_calibrate` 33 · `test_example_utils` 42 · pre-commit
clean.

Also verified: the exported directory reloads through
`AutoModelForCausalLM` and runs a forward.

Not a speed win: per-layer export was slower than the streaming export
in one offload pairing (271s vs 208s, the per-layer fusion probe),
though those runs shared GPUs so the magnitude is not cleanly measured.

### Before your PR is "*Ready for review*"

- Is this change backward compatible?: ✅ — `export_dir` defaults to
`None`; existing paths unchanged when unset, except the batch-size
change noted above.
- If you copied code from any other sources or added a new PIP
dependency, did you follow guidance in `CONTRIBUTING.md`: N/A
- Did you write any new necessary tests?: ✅
- Did you update
[Changelog](https://github.com/NVIDIA/Model-Optimizer/blob/main/CHANGELOG.rst)?:
✅
- Did you get Claude approval on this PR?: ❌ — not yet; draft.

### Additional Information

**Pre-existing bug found on the way, not fixed here.** Layerwise
calibration leaves `self_attn.o_proj`'s input amax at `0.0` on every
layer but the last, so a full-NVFP4 layerwise model cannot be exported
by *any* path. `get_qdq_activations_from_prev_layer=True` avoids it,
pinning the cause to the pre-`calib_func` capture pass — which also
explains why only the last layer, the one that skips it, is correct.
That combination now works with per-layer export (it asserted on layer 0
until review caught it). Hidden until now because the shipped NVFP4
layerwise recipes are experts-only; the NVFP4 tests here exclude
`o_proj` for the same reason. Deserves its own issue.

---------

Signed-off-by: Fridah-nv <201670829+Fridah-nv@users.noreply.github.com>
Co-authored-by: Claude Opus 5 <noreply@anthropic.com>
|
||
|
Rohan Joshi
|
424f47b871 |
Add QAD example for Alpamayo (#2271)
### What does this PR do?

Add `examples/alpamayo/qad.py` which distills the quantized Alpamayo
checkpoint's VLM against the FP16 VLM of the original with ModelOpt's
QADTrainer, and shards student and teacher with FSDP2 for multi-GPU
runs. Only the VLM is trained; the action expert stays frozen.


Type of change: new example

<!-- Details about the change. -->

### Usage

```
torchrun --standalone --nproc_per_node 8 qad.py \
    --student_ckpt ./alpamayo-auto \
    --output_dir ./alpamayo-auto-qad \
    --parquet ./train_clips.parquet \
    --max_steps 500 --fsdp2 --grad_ckpt --export
```

### Testing
Tested end-to-end on public Alpamayo-1 checkpoint

### Before your PR is "*Ready for review*"

Make sure you read and follow [Contributor
guidelines](https://github.com/NVIDIA/Model-Optimizer/blob/main/CONTRIBUTING.md)
and your commits are signed (`git commit -s -S`).

Make sure you read and follow the [Security Best
Practices](https://github.com/NVIDIA/Model-Optimizer/blob/main/SECURITY.md#security-coding-practices-for-contributors)
(e.g. avoiding hardcoded `trust_remote_code=True`, `torch.load(...,
weights_only=False)`, `pickle`, etc.).

- Is this change backward compatible?: ✅ / ❌ / N/A <!--- If ❌, explain
why. -->
- If you copied code from any other sources or added a new PIP
dependency, did you follow guidance in `CONTRIBUTING.md`: ✅ / ❌ / N/A
<!--- Mandatory -->
- Did you write any new necessary tests?: ✅ / ❌ / N/A <!--- Mandatory
for new features or examples. -->
- Did you update
[Changelog](https://github.com/NVIDIA/Model-Optimizer/blob/main/CHANGELOG.rst)?:
✅ / ❌ / N/A <!--- Very short summary of changes only for new features,
backward breaking changes, deprecations, or fixes for critical bugs
present in previous releases. -->
- Did you get Claude approval on this PR?: ✅ / ❌ / N/A <!--- Run
`/claude review`. NVIDIA org members can self-trigger for complex
changes; orthogonal to CodeRabbit. -->

### Additional Information
<!-- E.g. related issue. -->

<!-- This is an auto-generated comment: release notes by coderabbit.ai
-->
## Summary by CodeRabbit

- **New Features**
- Added a quantization-aware distillation workflow for AlpamayoR1
models.
- Supports prompt-only or rollout-inclusive distillation, FSDP2
training, dataset slicing, revision pinning, and checkpoint resumption.
- Supports exporting trained models as complete, reloadable AlpamayoR1
checkpoints.
- Added optional vision-parameter freezing, trajectory-history fusion,
gradient checkpointing, evaluation, and synchronized training cadence.

- **Documentation**
- Expanded the Alpamayo guide with setup, training, dataset, and export
instructions.
  - Clarified sensitivity-based quantization behavior.
  - Added a version 0.47 quantization changelog entry.
<!-- end of auto-generated comment: release notes by coderabbit.ai -->

Signed-off-by: Rohan Joshi <rohjoshi@nvidia.com>
|
||
|
Keval MorabiaandClaude Opus 5
|
6a2ae5a25b |
Fix the llm_eval timeout: reachable MMLU mirror + no pipe deadlock (#2270)
### What does this PR do? Type of change: Bug fix `tests/examples/llm_eval/test_llm_eval.py::test_qwen3_eval_fp8` has been failing with `Failed: Timeout (>900.0s) from pytest-timeout` on unrelated branches (runs 33027056246 and the one for `ad83a428`, while the 2026-08-24 nightly passed). It is not the test being slow — it is the harness deadlocking, and the deadlock also destroys the diagnostics that would explain the underlying kill. **Mechanism.** The traceback shows `self = <Popen: returncode: -9 args: ['scripts/huggingface_example.sh', ...]>` while still blocked in `stdout.read()`. The launcher was SIGKILLed (nothing in pytest sends SIGKILL — pytest-timeout raises in the main thread, and the test's `finally` `pkill` sends SIGTERM and only runs afterwards — so an OOM kill is the likely source). But `subprocess.run(..., stdout=PIPE, stderr=STDOUT)` waits for **EOF on the pipe**, not for the process, and a surviving grandchild (the TRT-LLM serve/build worker) still holds the write end. EOF never arrives, so the test blocks until the 900 s alarm. Because the pipe is never drained, **every line of child output is discarded**, which is why the CI log says nothing about what the script was doing when it died. Reduced to a self-contained reproducer: ```python script = "sleep 300 & echo 'launcher output'; sleep 0.3; kill -9 $$" subprocess.run(["bash", "-c", script], stdout=PIPE, stderr=STDOUT, text=True, timeout=20) # -> TimeoutExpired: still blocked in communicate() after 20.0s, output lost ``` **Fix.** `_run_capturing` now starts the command in its own session, drains its output on a reader thread (so logs stream as they arrive instead of being buffered until the end), waits on the *process*, and kills the process group if descendants still hold the pipe after a 30 s grace period. A killed launcher now fails in seconds with its logs intact instead of silently burning the test's whole timeout. This does not fix whatever kills the script; it makes it diagnosable. Worth noting separately: `test_qwen3_eval_fp8` took **749.10 s against its 900 s mark** on the last green nightly, so it is fragile regardless and may want its work trimmed or its budget raised once the logs show where the time goes. ### Usage ```python # unchanged public API run_example_command(cmd_parts, example_path="llm_eval") ``` ### Testing Verified against the reproducer above and on the normal paths: | scenario | before | after | | --- | --- | --- | | launcher SIGKILLed, survivor holds the pipe | blocks indefinitely (900 s in CI) | `rc=-9` in 3.5 s, `'launcher output'` captured | | the surviving descendant | keeps running | killed with the process group (stopped ticking, 20 -> 20 bytes) | | normal exit | ok | `rc=0`, stdout and stderr interleaved in order | | non-zero exit | ok | `rc=3`, output captured | The example-test suites that use this helper run through the same code path; `tests/examples/megatron_bridge` (16 passed, 1 skipped) exercised it on nemo:26.08 in the branch this was extracted from. ### Before your PR is "*Ready for review*" - Is this change backward compatible?: ✅ — `_run_capturing` keeps its `(returncode, output)` contract; only the buffering strategy changed. - If you copied code from any other sources or added a new PIP dependency, did you follow guidance in `CONTRIBUTING.md`: N/A - Did you write any new necessary tests?: ❌ — this is test infrastructure; the scenario needs a process that outlives a SIGKILLed parent, which is awkward to assert in CI. Verified manually with the reproducer above. - Did you update [Changelog](https://github.com/NVIDIA/Model-Optimizer/blob/main/CHANGELOG.rst)?: N/A — test-infrastructure fix. - Did you get Claude approval on this PR?: ❌ 🤖 Generated with [Claude Code](https://claude.com/claude-code) <!-- This is an auto-generated comment: release notes by coderabbit.ai --> ## Summary by CodeRabbit * **Bug Fixes** * Improved command execution reliability with real-time output capture. * Ensured lingering child processes are cleaned up after commands exit or are interrupted. * Added warnings when forced cleanup may truncate output. * Prevented hangs when descendant processes keep output streams open. * **Documentation** * Updated MMLU setup instructions to use the Hugging Face dataset repository. * Improved Windows instructions by explicitly using `curl.exe`. * **Examples** * Improved MMLU downloads with retries, separate timeouts, resume support, and automatic temporary-file cleanup. <!-- end of auto-generated comment: release notes by coderabbit.ai --> --- ### Update: the second half of the failure With the streaming fix in place, the next CI run showed the *actual* cause, which the old code had been hiding. That run blocked in `process.wait()` with `<Popen: returncode: None ...>` — child alive and working, not the previous dead-child pipe deadlock — and the now-visible output was: ``` --2026-08-27 18:09:20-- (try: 4) https://people.eecs.berkeley.edu/~hendrycks/data.tar Connecting to people.eecs.berkeley.edu ...|128.32.139.28|:443... failed: Connection timed out. Retrying. --2026-08-27 18:11:40-- (try: 5) ... ``` `huggingface_example.sh` downloads the MMLU tarball from `people.eecs.berkeley.edu`, that host stopped answering around 2026-08-25, and wget's default retry policy (20 tries, ~2 min per connect timeout) consumed the whole 900 s budget. Not runner-specific: the URL also times out from a developer workstation, and the nightlies flipped 08-24 ✅ / 08-25 ✅ / **08-26 ❌ / 08-27 ❌**, matching the outage. So this PR now carries both halves of the same failure: 1. the harness no longer deadlocks and no longer swallows the logs (`985809cc2d`), and 2. the MMLU data comes from HuggingFace's copy of the same tarball, with bounded retries (`40f1d89154`). The mirror is byte-for-byte the same dataset in the same layout the script already expects — verified by running the exact download/extract commands: ``` https://huggingface.co/datasets/cais/mmlu/resolve/main/data.tar -> HTTP 200, 166 MB data/mmlu/{dev,test,val}/ -> 57 subject CSVs each, plus auxiliary_train/ ``` `wget --timeout=20 --tries=3` plus an explicit error means the next dataset-host outage fails in about a minute with "Could not download the MMLU test data. Set MMLU_DATA_PATH to a local copy." instead of silently eating a test's timeout. The same URL is updated in `examples/llm_eval/README.md` so a manual run does not hit the dead host either. --------- Signed-off-by: Keval Morabia <28916987+kevalmorabia97@users.noreply.github.com> Co-authored-by: Claude Opus 5 (1M context) <noreply@anthropic.com> |
||
|
Zhiyu
|
5500999d0b |
Add Kimi-K3 NVFP4 experts and FP8-PB attention recipe (#2206)
### What does this PR do?

Type of change: new example

Adds the calibration-free conversion pipeline and checkpoint-mirror PTQ
recipe used for `nvidia/Kimi-K3-NVFP4`:

- streams the 96-shard Kimi-K3 checkpoint without loading the 2.8T
model;
- casts the source MXFP4 routed experts to NVFP4 with expert
`input_scale=1.0`;
- quantizes the selected KDA and MLA attention weights to 128x128 block
FP8;
- leaves shared/latent experts, routers, convolutions, norms, the vision
tower, `lm_head`, and KV cache unquantized;
- emits mixed-precision Hugging Face metadata for deployment; and
- adds an exact recipe under
`modelopt_recipes/huggingface/models/moonshotai/Kimi-K3/` that directly
configures the streaming converter.

It also fixes `NVFP4QTensor.quantize()` probing CUDA/Blackwell
capability before checking whether the tensor is on CUDA and whether the
optional TensorRT-LLM fast path was requested. That probe broke the
converter's supported CPU path on hosts without a compatible GPU.

### Usage

```bash
python examples/kimi/kimi_k3/quantize_to_nvfp4.py \
    --source_ckpt /models/moonshotai/Kimi-K3 \
    --output_ckpt /models/Kimi-K3-NVFP4 \
    --recipe huggingface/models/moonshotai/Kimi-K3/ptq/nvfp4_experts-fp8_pb_attention \
    --jobs 8
```

The conversion requires no calibration dataset, forward pass, or GPU.
Multi-node shard conversion is also supported through `--rank`,
`--world_size`, and `--run_id`.

### Testing

```bash
uv run --frozen --extra dev python -m pytest -q \
    tests/unit/torch/quantization/test_nvfp4_tensor.py \
    tests/unit/recipe/test_kimi_k3_recipe.py \
    tests/unit/recipe/test_recipe_docs.py \
    tests/unit/torch/export/test_shard_cast_utils.py \
    tests/examples/kimi/test_kimi_k3_quantize_to_nvfp4.py
```

Result: 34 passed.

All pre-commit hooks pass for the changed files, including recipe
validation, Ruff, mypy, Bandit, YAML formatting, and markdownlint.

### Before your PR is "*Ready for review*"

- Is this change backward compatible?: ✅
- If you copied code from any other sources or added a new PIP
dependency, did you follow guidance in `CONTRIBUTING.md`: N/A
- Did you write any new necessary tests?: ✅
- Did you update
[Changelog](https://github.com/NVIDIA/Model-Optimizer/blob/main/CHANGELOG.rst)?:
✅
- Did you get Claude approval on this PR?: N/A

### Additional Information

The resulting checkpoint and model card are available at
https://huggingface.co/nvidia/Kimi-K3-NVFP4.


<!-- This is an auto-generated comment: release notes by coderabbit.ai
-->
## Summary by CodeRabbit

- **New Features**
- Added calibration-free Kimi-K3 MXFP4-to-NVFP4 conversion with optional
FP8 attention quantization and distributed processing.
- Added NVFP4 activation calibration, weight-only quantization recipes,
grouped-expert quantization, compiled quantization options, SFT-masked
distillation, and MLflow tracking.

- **Documentation**
- Updated quantization terminology, recipe catalogs, checkpoint
guidance, and Kimi-K3 conversion instructions.

- **Bug Fixes**
- Improved CPU NVFP4 behavior, tied-weight export handling, EAGLE-3
training compatibility, and checkpoint export reliability.
- Removed deprecated configuration options and legacy evaluation
examples.
<!-- end of auto-generated comment: release notes by coderabbit.ai -->

---------

Signed-off-by: Zhiyu Cheng <zhiyuc@nvidia.com>
|
||
|
Keval MorabiaandClaude Opus 5
|
7ff81dd795 |
Add day-0 verbosity gate + harden release skills from a live run (#2254)
### What does this PR do?

Type of change: Bug fix, new feature, documentation

Day-0 release treats verbosity as a hard gate, but nothing in the skill
measured it — `gate_compare.py` only does accuracy. A run could complete
Step 5 and report a publish recommendation with a gate silently
unmeasured. This adds the missing gate and folds in fixes for problems
that cost GPU-h on a live release run.

**New: `gate_verbosity.py` + Step 5b.** Pure `evaluate_verbosity()` plus
an artifact harvester, matching `gate_compare.py`'s conventions and
`failure_class` vocabulary.

Two details it encodes, both of which produced wrong verdicts before
they were understood:

- **Read `response_stats.avg_completion_tokens`.** The
`reasoning.*_tokens` fields are always `0`, which reads as "the harness
never captured tokens" and pushes you to word counts. Only the
reasoning/content *split* is missing, not the total. Words disagree with
the gate: one task read **+6.10% FAIL** in words and **+1.32% PASS** in
tokens.
- **Two run-hygiene filters.** Pooling a mismatched reasoning-effort run
reported **+43.06% FAIL** on a task that is **+1.24% PASS** matched; one
truncated run (n=200 vs 294) reported **+9.58% FAIL** on a task that is
**+1.71% PASS** without it. Tasks with no common sample count are
reported `not_comparable` rather than as a delta.

**Skill hardening**, each from a specific failure:

- **Step 2b canary** — poll ceiling must exceed load time (a 50 min poll
against a 51 min load failed a checkpoint that serves fine), print an
explicit `RESULT:` on every path (a fall-through exits 0 and reads as
PASS), log to shared storage, and canary the **as-exported** artifact
rather than a copy modified to make it work.
- **Step 4 config parity** — assert the candidate config differs from
the baseline's in nothing but checkpoint path and served-model name. A
mismatched `parallelism` was worth ~2 pp, enough to invert the sign of a
delta, and cost four re-runs.
- **Statistical power** — re-running does not guarantee fresh samples:
with a warm NEL response cache two runs came back bit-identical to 16
digits.
- **Step 6 closeout** — verify the published path against the evaluated
one by inode, and prefix rejected sibling exports.
- **Size gate** — growth is blocking by default and waived only when the
validation summary's
`source_precision` shows an already-sub-8-bit source (which cannot
shrink further under a
4-bit recipe) and the growth is within what that explains.
`source_precision` is now a
recorded field in the ptq validation table, so the waiver is reachable
from the normal
pipeline, and `SIZE_NOT_REDUCED` has a triage row pointing at declaring
it.
- **`ptq.py`** — `--calib_seq` matters more than `--calib_size`, and
`--mse_calibrate` is a no-op under `--cast_mxfp4_to_nvfp4` (it tunes
weight quantizers only, and the cast overwrites `weight_scale`).
- **`.gitignore workspaces/`** — the skills create scratch directories
inside the repo; nothing excluded them.

### Usage

```bash
python "$SKILL_DIR/scripts/gate_verbosity.py" \
    --baseline <baseline_eval_root> --candidate <candidate_eval_root> \
    --glob 'eval_*' --threshold 0.05
```

Exit codes match the sibling gates: `0` pass, `1` the gate ran and
failed, `2` the gate could not
read its input (wrong root, `--glob` matched nothing, everything
excluded). Prints per-task tokens,
delta, `within_threshold`, `sample_count`, run counts,
`dropped_mismatched_runs`, any
`truncated_comparison`, `not_comparable`, `harvest_diagnostics`, and a
`max_abs_delta` summary.

### Testing

- 8 new unit tests in `test_gates.py`, one per real failure mode
(two-sided threshold, partial-run filtering, unequal sample counts,
short-output warning, one-sided tasks, empty input). Full suite: **36
passed**, no GPU or network.
- `gate_verbosity.py` validated end-to-end against a real day-0 run's
artifacts: reproduces the hand-computed result (`max_abs_delta =
0.0171`, pass) and correctly marks the two unequal-sample tasks
`not_comparable`.
- `pre-commit run --files <changed>` clean, including ruff, mypy,
bandit, markdownlint, and the `.claude/skills` symlink sync.
- Verified `max_sample_length` is a real `get_dataset_dataloader`
parameter with default 512, matching `--calib_seq`'s default, so
existing `ptq()` callers are unaffected.

### Before your PR is "*Ready for review*"

- Is this change backward compatible?: ✅ — `--calib_seq` defaults to the
pre-existing 512; `gate_ptq.py` reclassifies size growth from
`QUANT_COVERAGE_FAILURE` to `SIZE_NOT_REDUCED`, which is a more precise
class for an already-4-bit source and is covered by a new test asserting
a real coverage failure still outranks it.
- If you copied code from any other sources or added a new PIP
dependency, did you follow guidance in `CONTRIBUTING.md`: N/A — no new
dependencies, stdlib only.
- Did you write any new necessary tests?: ✅ — 8 new tests for the new
gate.
- Did you update
[Changelog](https://github.com/NVIDIA/Model-Optimizer/blob/main/CHANGELOG.rst)?:
N/A
- Did you get Claude approval on this PR?: ❌ — not yet run.

### Additional Information

The measured figures come from a completed day-0 NVFP4 release
qualification. Model-specific results were removed from the general
skills where the rule stands on its own; two references were kept
deliberately — a model card citation illustrating per-scenario sampling,
and a model-specific vLLM MoE kernel crash where the model name *is* the
evidence.

🤖 Generated with [Claude Code](https://claude.com/claude-code)

<!-- This is an auto-generated comment: release notes by coderabbit.ai
-->
## Summary by CodeRabbit

* **New Features**
* Added configurable calibration sequence-length limits for DeepSeek-V4
quantization.
* Added automated release checks for output verbosity, evaluation
comparability, serving readiness, and configuration parity.

* **Bug Fixes**
* Improved quantization size-ratio reporting by distinguishing
explainable growth from blocking failures.
* Clarified handling of deployment memory-access errors and infeasible
evaluations.

* **Documentation**
* Expanded guidance for calibration, remote execution, workspace
management, evaluation setup, deployment troubleshooting, and
statistical reliability.
* Added task-specific guidance for SciCode and GDPVal feasibility
checks.

* **Chores**
  * Excluded workspace session directories from version control.
<!-- end of auto-generated comment: release notes by coderabbit.ai -->

---------

Signed-off-by: Keval Morabia <28916987+kevalmorabia97@users.noreply.github.com>
Co-authored-by: Claude Opus 5 <noreply@anthropic.com>
|
||
|
Keval MorabiaandClaude Opus 5
|
d73278808b |
Bump nemo container requirement to 26.08 for MBridge examples (#2257)
### What does this PR do? Type of change: Bug fix Bumps the Megatron-Bridge examples, tests and launcher configs to `nemo:26.08` and removes the version-gated fallbacks they carried, plus the fixes needed to make the suites green on that container. **26.08 bump and shim removal** - Examples, CI workflows, `noxfile.py` and the `mbridge_*` launcher configs move to `nemo:26.08`. - `examples/megatron_bridge/_distillation_provider.py` is deleted — 26.08's Megatron-Bridge ships `convert_to_distillation_provider(..., distill_submodule=...)` natively, so `distill.py` imports it directly. - `prune_minitron.py` drops the `AutoBridge.from_hf_config` / config-only-export probing; `--no_moe_grouped_gemm` is no longer needed in the MoE pruning tests, and the Qwen3.5-MoE `skipif` is gone (native MoE expert mappings are in 26.08). - `_DynamicMambaMixer` targets only the raw `conv1d_weight` / `conv1d_bias` parameters that replaced the `conv1d` module in Megatron-Core. **MambaModel / MambaModelProvider removal** Megatron-Core has shipped `HybridModel` since 26.06 and `MambaModel` is a deprecated subclass that shares its `forward`, so `DMRegistry` resolves those instances to the `HybridModel` registration and the separate entry is redundant. Same for `MambaModelProvider` vs `HybridModelProvider` on the bridge side. `MambaMixer` / `MambaLayer` / `ExtendedRMSNorm` are untouched — the layers still exist. The deprecated `get_te_mamba_stack_spec` is removed; use `get_te_hybrid_stack_spec`. **Bug fix: compressed output_layer extra state** `mtq.compress` converts even a *disabled* `output_layer` into a `RealQuantLinear` (its weight is left uncompressed, since `pack_real_quantize_weight` skips disabled quantizers). The guard added in #2112 excluded `RealQuantLinear` by class, so the layer emitted extra state and every worker died in `GPTModel.sharded_state_dict`: ``` RuntimeError: Boolean value of Tensor with more than one value is ambiguous megatron/core/models/gpt/gpt_model.py:896, in sharded_state_dict output_extra_state and output_extra_state.data ``` The guard now keys off whether the weight was actually compressed (`QTensorWrapper`) instead of the class. This took out all 12 `test_homogeneous_compressed_sharded_state_dict` params, and the crashed workers poisoned the pool, which surfaced as unrelated timeouts and NCCL errors in `test_layer_sync_moe_local_experts_amax`, `test_kv_cache_quant`, `test_kv_cache_amax_sync`, `test_convert_mcore_te_gpt_model` and `test_homogeneous_sharded_state_dict_te_spec` — 21 tests in total. The e2e coverage is `skip_flaky_on_blackwell`, so CI never ran it; `test_output_layer_extra_state_empty_when_nothing_quantized` now asserts the contract directly and is not skipped. **Checkpoint import entry point** 26.08 replaced `examples/conversion/convert_checkpoints.py` with `scripts/conversion/convert.sh`, so `tools/launcher/common/megatron_bridge/import/import.sh` and the three README snippets are retargeted. `import.sh` uses the distributed GPU backend with `GPUS_PER_NODE` / `TP` / `PP` / `EP` knobs. **Megatron-LM on nemo:26.06** keeps working: `_get_mamba_conv1d` still dispatches between the `conv1d` module (26.06 and earlier) and the raw parameters (26.08+), so `import_mcore_gpt_from_hf` / `export_mcore_gpt_to_hf` handle NemotronH on both. Only the Megatron-Bridge examples and Minitron pruning of Mamba/hybrid models require 26.08. **Test consolidation** `test_export_distilled_megatron_to_hf.py` is merged into `test_distill.py`: `test_distill_llm` becomes `test_distill_llm_hf_export` and covers the standalone `--export_iterations all` run on the checkpoints it already produces, saving one full distillation (~185 s of CI time). The two mamba-named gpu test files are renamed to `hybrid`. ### Usage ```bash # HF -> Megatron import, via Megatron-Bridge's 26.08 conversion entry point bash /opt/Megatron-Bridge/scripts/conversion/convert.sh import \ --executor local \ --device gpu \ --gpus-per-node 8 \ --hf-model Qwen/Qwen3-8B \ --megatron-path /tmp/Qwen3-8B-megatron ``` ### Testing All on `nvcr.io/nvidia/nemo:26.08`, 2x RTX 6000 Ada, no timeout overrides: - `tests/examples/megatron_bridge`: 16 passed, 1 skipped (28m14s). The skip is the `gemma3vl` QAD param, now `@pytest.mark.manual` since `qwen3_5_moe_vl` covers the VLM QAD path. - `tests/gpu_megatron` (`_extensions`, `distill`, `export`, `opt`, `peft`, `sparsity`, `speculative`, `utils`): 61 passed, 5 xpassed. - `tests/gpu_megatron/torch/export` re-run after the conv1d dispatch change: 27 passed. - The 21 previously failing/hanging quantization tests: 21 passed (12 + 9). - `tests/gpu_megatron/torch/{nas,prune}`: verified separately. `import.sh` equivalence on a toy `qwen3_moe`, comparing all 12 weight tensors after flattening each dist checkpoint with `dcp_to_torch_save` — the GPU backend at 1 GPU, `--tp 2`, `--pp 2`, `--ep 2`, and `import.sh` end-to-end (`GPUS_PER_NODE=2 EP=2`) are all byte-identical to `--device cpu`. `nemo:26.06` compatibility was checked directly in that image: `megatron.core.models.hybrid.HybridModel`, the modelopt hybrid spec and `hybrid_layer_pattern` are all present, while `megatron.bridge.models.hybrid` and the bridge's `distill_submodule` are not. The NemotronH round-trip test failed there before the conv1d dispatch was restored and the dispatch is back in place; per project convention the suites themselves only run on 26.08. ### Before your PR is "*Ready for review*" - Is this change backward compatible?: ⚠️ Megatron-Bridge examples plus Minitron pruning of Mamba/hybrid models now require `nemo:26.08`. Megatron-LM quantization and checkpoint export still run on `nemo:26.06`. - If you copied code from any other sources or added a new PIP dependency, did you follow guidance in `CONTRIBUTING.md`: N/A - Did you write any new necessary tests?: ✅ — `test_output_layer_extra_state_empty_when_nothing_quantized` for the compress fix; existing tests extended for the merged export coverage. - Did you update [Changelog](https://github.com/NVIDIA/Model-Optimizer/blob/main/CHANGELOG.rst)?: ✅ - Did you get Claude approval on this PR?: ❌ 🤖 Generated with [Claude Code](https://claude.com/claude-code) <!-- This is an auto-generated comment: release notes by coderabbit.ai --> ## Summary by CodeRabbit * **New Features** * Added guidance for importing Hugging Face checkpoints into Megatron distributed format. * Expanded distillation workflows to export selected or all checkpoint iterations. * **Improvements** * Expanded Hybrid model support across Megatron workflows. * Updated distributed import tooling with GPU and parallelism options. * Updated supported environments and examples to NVIDIA NeMo 26.08. * **Bug Fixes** * Corrected output-layer quantization state handling when quantization is disabled. * **Documentation** * Added compatibility guidance for current and legacy NeMo containers. <!-- end of auto-generated comment: release notes by coderabbit.ai --> --------- Signed-off-by: Keval Morabia <28916987+kevalmorabia97@users.noreply.github.com> Co-authored-by: Claude Opus 5 (1M context) <noreply@anthropic.com> |
||
|
Keval MorabiaandClaude Opus 5
|
449a39922b |
Pin nemo_automodel below 0.6 for the fastgen example (#2260)
### What does this PR do? Type of change: Bug fix `nemo_automodel` 0.6.0 removed `nemo_automodel.recipes.diffusion.train.is_main_process` without a replacement (it was a three-line rank-zero predicate in 0.5.0, and 0.6.0 defines no equivalent anywhere in the package). `examples/diffusers/fastgen/dmd2_recipe.py` imports it, so the example's import guard fires and **every** test in `tests/examples/diffusers/` errors at collection: ``` ImportError: cannot import name 'is_main_process' from 'nemo_automodel.recipes.diffusion.train' tests/examples/diffusers/fastgen/test_resume_dataloader.py E ImportError: The DMD2 fastgen example requires `nemo_automodel`. ... collected 42 items / 1 error ``` The requirement was `>=0.4.0,<1.0`, so CI picked 0.6.0 as soon as it was published and the `onnx (diffusers)` job started failing on every PR (e.g. runs 33020467654, 33019418460, 33010815298, 33007613265, 33006944292 — all unrelated branches). Capping at `<0.6` restores the tested range. Every other `nemo_automodel` symbol the example imports still exists in 0.6.0 (`_diffusers.auto_diffusion_pipeline.NeMoAutoDiffusionPipeline`, `recipes.diffusion.train.TrainDiffusionRecipe`, and the four `components.datasets.diffusion.*` helpers), so `is_main_process` is the only blocker; the alternative is defining that predicate locally and widening the cap again, which is worth doing separately if the example is meant to track 0.6. ### Usage ```bash pip install -r examples/diffusers/fastgen/requirements.txt ``` ### Testing Reproduced the break by diffing the published wheels: `is_main_process` is defined at `nemo_automodel/recipes/diffusion/train.py:692` in 0.5.0 and absent from 0.6.0 (`grep -rn "def is_main_process"` over the unpacked 0.6.0 wheel returns nothing). Confirmed the remaining imported symbols are all still present in 0.6.0. CI on this PR exercises the fix directly: the `onnx (diffusers)` job installs from this requirements file and is the job that has been failing. ### Before your PR is "*Ready for review*" - Is this change backward compatible?: ✅ - If you copied code from any other sources or added a new PIP dependency, did you follow guidance in `CONTRIBUTING.md`: N/A — existing dependency, tightened bound. - Did you write any new necessary tests?: N/A — the existing `tests/examples/diffusers/` suite is what this unblocks. - Did you update [Changelog](https://github.com/NVIDIA/Model-Optimizer/blob/main/CHANGELOG.rst)?: N/A — dependency-pin fix for a break introduced and fixed within the same unreleased cycle. - Did you get Claude approval on this PR?: ❌ 🤖 Generated with [Claude Code](https://claude.com/claude-code) <!-- This is an auto-generated comment: release notes by coderabbit.ai --> ## Summary by CodeRabbit * **Bug Fixes** * Fixed dependency compatibility for the FastGen diffusion example. * Prevented installation of versions that could cause the example to fail at startup. <!-- end of auto-generated comment: release notes by coderabbit.ai --> Signed-off-by: Keval Morabia <28916987+kevalmorabia97@users.noreply.github.com> Co-authored-by: Claude Opus 5 (1M context) <noreply@anthropic.com> |
||
|
h-guo18
|
5db2682519 |
[Example]: Calibration-free FP8/NVFP4 PTQ for speculative-decoding drafters (#2027)
### What does this PR do? Type of change: new example Adds `examples/speculative_decoding/scripts/quantize_drafter.py`, a CLI that quantizes an exported speculative-decoding drafter to FP8 or NVFP4 — weight-only or weight+activation — with no calibration data. It needs no modeling code either. Exported drafters such as [`nvidia/MiniMax-M3-DSpark`](https://huggingface.co/nvidia/MiniMax-M3-DSpark) have no importable model class, so each 2-D weight is wrapped in a throwaway `nn.Linear` under its checkpoint key and ModelOpt's usual `quantizer_name` patterns select over those names. Works for any drafter layout (DSpark / DFlash / EAGLE3 / Medusa). **Formats:** `w4a16_nvfp4`, `nvfp4`, `fp8`, `fp8_pc_pt` — the ModelOpt formats vLLM's backend can actually serve. AWQ is deliberately not offered, since `awq_lite` silently degrades to plain RTN without a `forward_loop`. **Static activation scales without calibration.** `fp8` and `nvfp4` normally need an activation amax *measured* on calibration data; a fixed `input_scale` of 1.0 is applied instead. That works because acceptance length is governed almost entirely by **clipping**, not resolution: Sweeping the fixed scale over three decades (same setup as the Testing section below; bf16 baseline 3.1423): | `input_scale` | amax | FP8 AL | vs bf16 | NVFP4 AL | vs bf16 | |---|---|---|---|---|---| | 0.003 | 1.3 | 2.2204 | -29.34% | 2.2076 | -29.75% | | 0.01 | 4.5 | 2.6719 | -14.97% | 2.6641 | -15.22% | | 0.03 | 13.4 | 2.9751 | -5.32% | 2.9259 | -6.89% | | 0.1 | 44.8 | 3.1013 | -1.31% | 3.0206 | -3.88% | | 0.2 | 89.6 | 3.1178 | -0.78% | 3.0015 | -4.48% | | 0.3 | 134.4 | 3.1370 | -0.17% | 3.0222 | -3.82% | | 0.5 | 224.0 | 3.1268 | -0.50% | 3.0360 | -3.38% | | **1.0 (default)** | **448.0** | **3.1457** | **+0.11%** | **3.0193** | **-3.91%** | | 2.0 | 896.0 | 3.1354 | -0.22% | 3.0172 | -3.98% | | 4.0 | 1792.0 | 3.1245 | -0.57% | 3.0034 | -4.42% | Both formats fall off a cliff below ~0.03, where the declared range sits far under the activations' true magnitude and most of the tensor is clipped. Both then sit on a flat plateau from ~0.3 to 4.0 **with no drop-off at the top**, so the scale only has to be big enough. 1.0 is the middle of that plateau, which is why it is hardcoded rather than exposed. NVFP4 trails FP8 by a roughly constant 3.5% across the plateau — that gap is the 4-bit resolution cost, and no choice of scale recovers it. Deriving the amax from the weights instead was tried and does not work: `max|W|` averages 0.79 while a RMSNorm'd activation is O(1) with outlier channels in the tens, so the range lands 1–2 orders of magnitude low and clips, measuring -31% to -46% AL. **Where calibration would go.** All of this sits behind `resolve_activation_scales()`, the single place deciding where a static amax comes from. Real calibration slots in ahead of the fixed fallback with no change to the CLI or the call site, and composes because `set_static_activation_amax()` skips quantizers that already have an amax: ```python if calib_forward_loop is not None: mtq.calibrate(root, quant_cfg["algorithm"], forward_loop=calib_forward_loop) set_static_activation_amax(root) # fills in what calibration did not reach ``` **Serving a quantized drafter.** Four things had to be written into the exported checkpoint before vLLM would load one: - emit `quant_method` (`modelopt_fp4` / `modelopt`) — vLLM reads that key, ModelOpt writes only `quant_algo` - emit the exclusion list under `ignore` too — that is the key read from the flat `quantization_config`; `exclude_modules` alone yields an empty exclusion set - add `*<name>` wildcards so exclusions match a runtime's nested module prefix (`model.fc`) rather than the checkpoint key (`fc`) - add `*qkv_proj` / `*gate_up_proj` aliases for layers a runtime fuses, whose names appear in no checkpoint key Nothing is then needed on the caller side. **This closes the open question left in the previous revision of this PR: vLLM does read `quantization_config` off the draft checkpoint.** `ModelConfig._verify_quantization` fills `quantization` in from `quant_method` when it is unset, so once the export declares that key — the first fix above — detection works on its own. Verified on Nemotron-3.5-Lightning passing nothing: `Detected ModelOpt NVFP4 checkpoint (quant_algo=NVFP4)` → `FlashInferCuteDslNvFp4LinearKernel`, AL 4.278 against 4.203 measured earlier. `specdec_bench` also gains a `DSPARK` algorithm, which it did not have: an exported `Qwen3DSparkModel` would otherwise have to go through `DFLASH` and be built with vLLM `method="dflash"`. The branch sets `method="dspark"` and leaves `draft_sample_method` on vLLM's own default of `greedy`. A target whose fused-collective workspace (sized at CUDA-graph capture) overflows at large speculative batches can disable graphs with `--runtime_params '{"engine_args": {"enforce_eager": true}}'`. For DFlash-family drafters, `qwen3_dflash.py` builds its fused context-KV projection by reading `qkv_proj.weight` raw and calling `F.linear`, which cannot consume a packed weight. Keep those layers in bf16 with `--exclude '*q_proj*' '*k_proj*' '*v_proj*' '*qkv_proj*'`; `o_proj` and the MLP — the bulk of the drafter — still quantize. That exclusion is mandatory, not a tuning choice. `fc` (the projection from the target's captured layers into the draft) is the one real knob, and it is a genuine trade rather than a free win — see the Testing section for both models' numbers. The examples quantize it; add `'*fc*'` to the exclude list to keep it in bf16. `embed_tokens`, `markov_head` and `confidence_head` are excluded by default: they are 2-D so the flat view treats them as GEMMs, but they are embeddings or a single-output projection. `lm_head` is excluded by the preset itself — unlike on a base model it is 37% of this drafter's parameters, so `--quantize_lm_head` is a real lever (~1.9 GiB), but measure AL first. The flag re-enables both of `lm_head`'s quantizers; re-enabling only the weight one would ship a W+A checkpoint whose `lm_head` has no `input_scale` while the config still advertises it as quantized. ### Usage ```bash # weight+activation FP8, calibration-free, lossless on both models measured below python scripts/quantize_drafter.py \ --drafter_path deepseek-ai/dspark_qwen3_8b_block7 \ --qformat fp8 \ --export_path ./dspark-qwen3-8b-fp8 \ --exclude '*q_proj*' '*k_proj*' '*v_proj*' '*qkv_proj*' # smallest: weight-only NVFP4 python scripts/quantize_drafter.py \ --drafter_path nvidia/MiniMax-M3-DSpark \ --qformat w4a16_nvfp4 \ --export_path ./MiniMax-M3-DSpark-W4A16 ``` Or end to end on Slurm — quantize, then measure AL — via the launcher examples added here, one per target: ```bash uv run launch.py --yaml examples/Qwen/Qwen3-8B/hf_dspark_ptq_nvfp4.yaml --yes uv run launch.py --yaml examples/nvidia/NVIDIA-Nemotron-3.5-Lightning-30B-A3B-BF16/hf_dspark_ptq_nvfp4.yaml --yes ``` Serving one, if you are not going through `specdec_bench`: ```python speculative_config = { "method": "dspark", "model": "./dspark-qwen3-8b-fp8", # quantization is read from its config.json "num_speculative_tokens": 7, } ``` ### Testing Two targets with different architectures, so the conclusions are not one model's quirk: * **Qwen3-8B** (dense transformer) + [`deepseek-ai/dspark_qwen3_8b_block7`](https://huggingface.co/deepseek-ai/dspark_qwen3_8b_block7), `block_size` 7, TP1. * **Nemotron-3.5-Lightning-30B-A3B** (hybrid Mamba-MoE) + [`nvidia/NVIDIA-Nemotron-3.5-Lightning-30B-A3B-BF16-DSpark`](https://huggingface.co/nvidia/NVIDIA-Nemotron-3.5-Lightning-30B-A3B-BF16-DSpark), `block_size` 8, TP8, with the mamba engine settings the model card pins (`mamba_backend=flashinfer`, `mamba_ssm_cache_dtype=float16`, stochastic SSM-cache rounding). Both: MT-Bench 80 questions, greedy, one vLLM instance per point. | recipe | activations | Qwen3-8B AL | vs bf16 | Nemotron-3.5 AL | vs bf16 | |---|---|---|---|---|---| | bf16 baseline | — | 3.1423 | — | 4.3296 | — | | **`fp8`** | static, `input_scale` 1.0 | **3.1457** | **+0.11%** | **4.3289** | **-0.02%** | | `fp8_pc_pt` | dynamic per-token | 3.1228 | -0.62% | 4.3411 | +0.26% | | `w4a16_nvfp4`, `fc` in bf16 | bf16 (weight-only) | 3.0392 | -3.28% | 4.2899 | -0.92% | | `w4a16_nvfp4`, `fc` quantized | bf16 (weight-only) | 3.0186 | -3.94% | 4.2334 | -2.22% | | **`nvfp4`** | static, `input_scale` 1.0 | **3.0193** | **-3.91%** | **4.2030** | **-2.92%** | **FP8 weight+activation at the fixed `input_scale` of 1.0 is lossless on both.** +0.11% and -0.02% are both inside run-to-run noise — the Nemotron baseline was measured twice under identical settings and the two runs differ by 0.94% (4.3093 / 4.3499), which sets the resolution of that column. On the same reading, `fp8` and `fp8_pc_pt` are indistinguishable on Nemotron; the dynamic variant only pulls ahead on Qwen3. NVFP4 costs 3-4% on Qwen3 and 2-3% on Nemotron, i.e. the 4-bit weight resolution is the real price and it is model-dependent but bounded. Whether to quantize `fc` is a per-model call rather than a general recommendation — it buys a few percent of size for an AL cost that differs by ~2x between these two drafters: | `fc` bf16 → quantized | Qwen3-8B | Nemotron-3.5 | |---|---|---| | checkpoint size | 3.293 → 3.181 GiB (-3.4%) | 1.316 → 1.258 GiB (-4.4%) | | AL | 3.0392 → 3.0186 (-0.68%) | 4.2899 → 4.2334 (-1.32%) | `fc` itself is only 3.5% (Qwen3) / 4.5% (Nemotron) of drafter parameters; `embed_tokens` is the bulk (26% / 36%) and is excluded by default. The Qwen3 `w4a16_nvfp4` rows were measured in a later session than the rest of that column; the `fc`-in-bf16 run reproduced the original number to four decimals (3.0392), so the column is internally comparable. Also validated on `nvidia/MiniMax-M3-DSpark`: `w4a16_nvfp4` runs in 67 s on CPU, 9.98 GiB (fp32) -> 3.51 GiB; all 43 quantized tensors round-trip within 0.0952 relative error; the 29 untouched tensors are bit-identical to `bf16(source)`. ### Before your PR is "*Ready for review*" - Is this change backward compatible?: ✅ (example-only) - If you copied code from any other sources or added a new PIP dependency, did you follow guidance in `CONTRIBUTING.md`: N/A - Did you write any new necessary tests?: ❌ — validated manually as above. Can add a `tests/examples/speculative_decoding/` test over a small synthetic drafter if wanted before merge. - Did you update [Changelog](https://github.com/NVIDIA/Model-Optimizer/blob/main/CHANGELOG.rst)?: N/A (example-only) - Did you get Claude approval on this PR?: ❌ (not yet run) ### Additional Information The measurements above are one drafter on one target with one benchmark; the plateau's location and the ~3.5% NVFP4 gap should be re-measured before assuming they carry to a different drafter. Note when reading an exported checkpoint: `input_scale` is `amax/448` for FP8 but `amax/(6*448)` for NVFP4, so the one fixed amax records as 1.0 in an FP8 checkpoint and 0.1667 in an NVFP4 one. Both mean the same activation range. Signed-off-by: h-guo18 <67671475+h-guo18@users.noreply.github.com> |
||
|
h-guo18
|
2b296b2f62 |
Support fine-tuning released DFlash/DSpark drafters (causal SWA, attention sink, warm start) (#2149)
# Support fine-tuning released DFlash/DSpark drafters (causal SWA, attention sink, warm start) ### What does this PR do? Type of change: New feature + bug fix Adds what ModelOpt was missing to fine-tune an already-published DFlash/DSpark draft model. The concrete target is [`nvidia/NVIDIA-Nemotron-3.5-Lightning-30B-A3B-BF16-DSpark`](https://huggingface.co/nvidia/NVIDIA-Nemotron-3.5-Lightning-30B-A3B-BF16-DSpark) on its hybrid Mamba/attention/MoE base, but every change is generic. Before this PR that checkpoint could not be trained faithfully — or even loaded: its attention-sink tensors were dropped as unexpected keys, its block-causal attention had no implementation, and its capture layers were silently overwritten with ModelOpt's defaults. **New user-facing options** (all default to today's behavior, so existing runs are unchanged): | Option | Values | Purpose | | --- | --- | --- | | `dflash_draft_attention` | `bidirectional` (default) / `causal` | Block-internal attention pattern. `causal` restricts a query at block position `i` to draft positions `<= i`. | | `dflash_attention_sink` | `false` (default) / `true` | Learnable per-head `attention_sink_bias [num_heads]` on every draft layer — one extra logit appended before the softmax and dropped after, so a head can put probability mass nowhere instead of being forced to attend inside its window (the GPT-OSS formulation). | | `dflash_init_checkpoint` | path | Warm-start the draft from an exported checkpoint instead of a random init. Any missing/unexpected/wrong-shaped tensor raises rather than warns. | | `dflash_architecture_config.target_layer_ids` | list | Which base layers feed the draft's `fc`. Previously recomputed unconditionally with no override. | **Bugs fixed along the way** (each one silently corrupts training rather than failing): - The exporter hard-coded `dflash_config.causal: False` and only wrote it under SWA, so even a correctly-trained causal draft would be served non-causally. It now reflects the trained setting, and emits `attention_sink_bias` when enabled. - `_build_generate_swa_mask` returned `None` whenever `swa_window_size` was unset, which would have dropped the causal structure at generation time while training used it. - `target_layer_ids` was recomputed from the uniform default on every convert. The released drafter uses `[1,5,19,29,41,51]`; the default for a 52-layer base is `[1,11,20,30,39,49]` — *different layers*. Here it surfaced as a matmul shape error only because the plane counts disagreed; with a matching count it would have trained on the wrong features silently. - The streaming dataset assumed the draft's aux layers all sit below the base's final layer (`aux = planes[:-1]`, `target = planes[-1]`). A draft whose top aux id *is* the final layer cannot get an extra plane — vLLM captures each layer once — so `final_aux_is_base_hidden` now lets the last plane serve both roles. It is derived from the model, not configured by hand. - DSpark head weights load from either the flat layout ModelOpt exports (upstream DeepSpec convention) or the nested `markov_head.` layout the NVIDIA release uses. Without the remap the two `[131072, 512]` Markov tables — ~14% of the draft's parameters — stay randomly initialized while everything else warm-starts, with no error. - `nemotron_h` is enabled in `_FINAL_NORM_TYPE_BY_MODEL_TYPE`: despite the hybrid stack, `NemotronHModel.norm_f` is a plain RMSNorm, and without the entry the offline/streaming fake base raises instead of reconstructing the distillation target. ### Usage ```yaml dflash: dflash_init_checkpoint: /path/to/NVIDIA-Nemotron-3.5-Lightning-30B-A3B-BF16-DSpark dflash_draft_attention: causal dflash_attention_sink: true dflash_swa_window_size: 1024 dflash_block_size: 8 dflash_mask_token_id: 990 dflash_architecture_config: target_layer_ids: [1, 5, 19, 29, 41, 51] ``` A full worked example is at `modelopt_recipes/general/speculative_decoding/dspark_nemotron35_warmstart.yaml`. ### Testing **Unit tests** — 124 pass (`test_hf_dflash.py`, `test_hf_dspark.py`, `test_hf_domino.py`, `test_hf_dflash_offline.py`, `test_modeling_final_norm.py`), 32 of them new: causal mask structure (lower-triangular per block, no cross-block leakage, context visibility unchanged), the sink math (degenerates to plain attention at `-inf`, absorbs mass monotonically, receives gradient), warm-start load/reject paths, Markov key remapping, and explicit `target_layer_ids`. **Checkpoint compatibility** — the released drafter loads with zero missing/unexpected keys and zero shape mismatches; all 77 tensors (6 attention sinks and both Markov tables included) match bit-exactly, and a training step runs with gradients reaching the sink and Markov parameters. **End-to-end streaming training** — Nemotron-3.5 base served by vLLM (1 node, TP8) feeding 8 trainer GPUs over NIXL; the draft warm-starts from the released checkpoint and trains with `causal` + sink + SWA 1024. 128 Daring-Anteater conversations, 20 epochs (the plot shows the first 5, where the trend is clearest — the curves flatten after that): 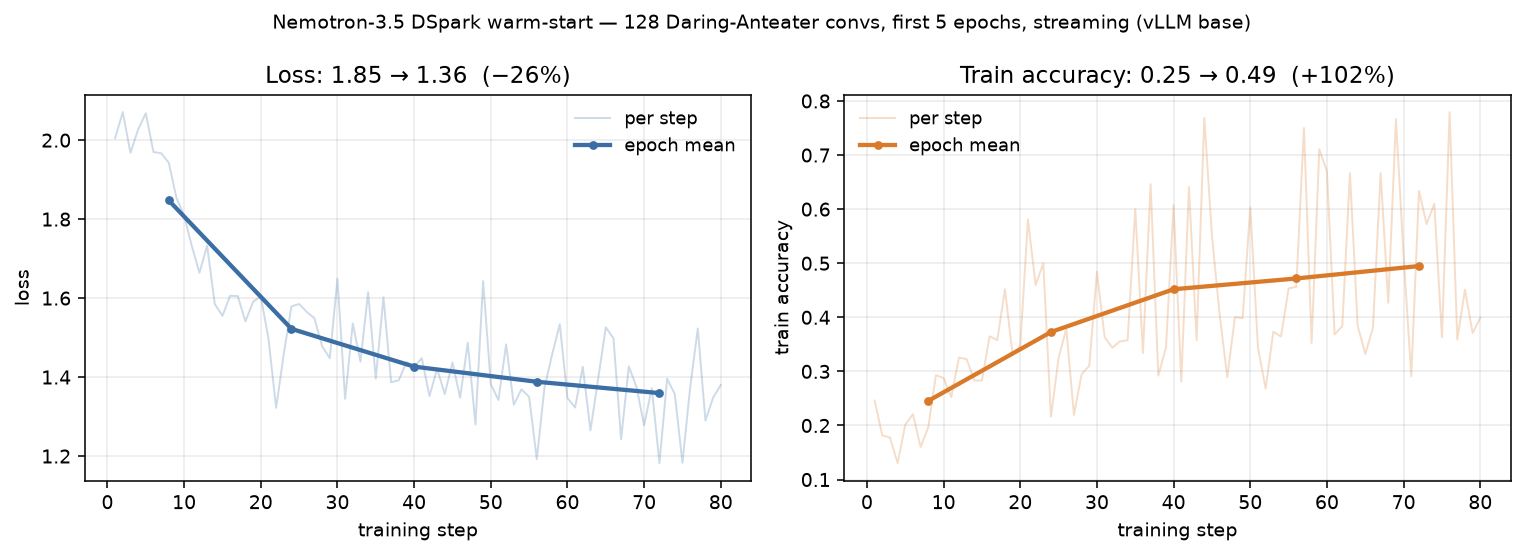 Over the first 5 epochs loss falls **1.85 → 1.36** and train accuracy rises **0.25 → 0.49**; across the full 20 epochs they reach **1.21** and **0.48** (peak 0.54) before flattening. This validates the pipeline end-to-end — capture layers, plane split, mask direction, sink loading and warm-start weights all have to be right for this curve to appear. It is *not* a model-quality result: 128 samples over 20 epochs overfits by construction, and the corpus is not generated by the base model, so the absolute numbers are not meaningful. ### TODO (follow-up) **A complete, robust checkpoint/config converter.** Both conversions are handled ad hoc here: - *Draft config → training config.* The recipe transcribes ~15 fields by hand from the drafter's `config.json`. Only the shape-bearing ones (`num_hidden_layers`, `num_attention_heads`, `intermediate_size`, `markov_rank`) fail loudly when mistyped; the rest — `mask_token_id`, `causal`, `swa_window_size`, `block_size` — train "successfully" on a wrong value and only surface later as a mysteriously low acceptance length. A converter should derive the whole block from the checkpoint, including its aliases (`pard_token`, `dspark_markov_rank`, `dflash_query_causal`, top-level `sliding_window` / `attention_sink_bias`) and duplicated fields. - *Weight layout.* The `markov_head.` remap is a load-time hook. A converter should normalize layouts explicitly, and decide whether export should also emit the release's aliases so a round-trip reproduces the original format (today it renames `architectures` to `DFlashDraftModel`). - *Base config.* Serving this base on vLLM needs its `config.json` layer-type vocabulary updated for the transformers-5 path (`mamba` → `linear_attention`, `attention` → `full_attention`, plus a matching `hybrid_override_pattern`). That is done by hand today and is not covered by this PR. ### Before your PR is "*Ready for review*" - **Make sure you read and follow [Contributor guidelines](https://github.com/NVIDIA/TensorRT-Model-Optimizer/blob/main/CONTRIBUTING.md)** and your commits are signed. - **Is this change backward compatible?**: Yes - **Did you write any new necessary tests?**: Yes - **Did you add or update any necessary documentation?**: Yes - **Did you update [Changelog](https://github.com/NVIDIA/TensorRT-Model-Optimizer/blob/main/CHANGELOG.rst)?**: No <!-- This is an auto-generated comment: release notes by coderabbit.ai --> ## Summary by CodeRabbit * **New Features** * Added configurable causal or bidirectional attention for DFlash models. * Added optional attention sinks, checkpoint warm starts, and explicit target-layer selection. * Improved streaming data handling for shared auxiliary and base hidden states. * Added Nemotron-3.5 Lightning DSpark warm-start training and serving recipes. * **Bug Fixes** * Preserved configured attention behavior during model export. * Prevented warm-start checkpoints from being reapplied during restoration. * Improved checkpoint compatibility, validation, and attention-mask handling. <!-- end of auto-generated comment: release notes by coderabbit.ai --> Signed-off-by: h-guo18 <67671475+h-guo18@users.noreply.github.com> |
||
|
Keval MorabiaandClaude Opus 5
|
fbcdc16c2d |
Remove deprecations marked in 0.45 and 0.46 (#2182)
### What does this PR do?

Type of change: Backward breaking change (deprecation removal)

Ahead of the 0.47 code freeze, this removes every deprecation still
outstanding from the previous two releases (0.45 and 0.46). Two are
intentionally left in place: the **Python 3.10** drop and the
**transformers 4.x** drop

| Deprecation | Marked in | Replacement |
| --- | --- | --- |
| `--auto_quantize_bits` / `_method` / `_score_size` / `_cost_model` /
`_active_moe_expert_ratio` | 0.46 | AutoQuantize `--recipe` |
| `examples/llm_ptq` symlink + `examples/vlm_ptq/` forwarder | 0.46 |
`examples/hf_ptq` (`--vlm` for VLMs) |
| `QuantizationArgumentsWithConfig` alias | 0.45 |
`QuantizationArguments` |
| `QFORMAT_ALIASES` short names | 0.45 | canonical preset basenames |
| `layerwise` bool + flat `layerwise_checkpoint_dir` | 0.45 | nested
`layerwise: {enable, checkpoint_dir}` |
| in-trainer `quant_cfg` / `--quant_cfg` | 0.45 | `--recipe` |

#### Two things worth a closer look

**1. The `use_sequential` alias goes too.** It is the pre-#1251 alias on
`QuantizeAlgorithmConfig.layerwise` and only ever carried a bool. Once
the bool form is rejected it cannot accept a valid value, so keeping it
would only produce a differently-worded validation error. Note the
direction is breaking either way (`extra="forbid"`): a pre-0.45
`modelopt_state` carrying `use_sequential: True` or a top-level
`layerwise_checkpoint_dir` now fails validation instead of being
migrated.

**2. Removing in-trainer `--quant_cfg` required two new recipes.** The
`examples/gpt-oss` QAT flow ran on `--quant_cfg
MXFP4_MLP_WEIGHT_ONLY_CFG` and no `general/ptq/` recipe covered it. This
PR adds `general/ptq/mxfp4_mlp_weight_only` and
`general/ptq/nvfp4_mlp_weight_only`, verified to `model_dump` identical
to `mtq.MXFP4_MLP_WEIGHT_ONLY_CFG` / `mtq.NVFP4_MLP_WEIGHT_ONLY_CFG`,
and migrates the gpt-oss README, both SFT configs, `sft.py` and
`tests/examples/gpt-oss/test_gpt_oss_qat.py`. `examples/llm_qat` was
already recipe-only.

### Usage

```bash
# AutoQuantize: --auto_quantize_* flags -> an AutoQuantize recipe
scripts/huggingface_example.sh --model $HF_PATH \
  --recipe general/auto_quantize/nvfp4_fp8_at_5p4bits --calib_batch_size 4

# --qformat / --quant_cfg: short name -> canonical preset basename
#   int8_sq -> int8_smoothquant                nvfp4_mse           -> nvfp4_w4a4_weight_mse_fp8_sweep
#   int8_wo -> int8_weight_only                nvfp4_local_hessian -> nvfp4_w4a4_weight_local_hessian
#   w4a8_awq -> w4a8_awq_beta                  fp8_pb_wo           -> fp8_2d_blockwise_weight_only
#   nvfp4_awq -> nvfp4_awq_lite                fp8_pc_pt           -> fp8_per_channel_per_token
scripts/huggingface_example.sh --model $HF_PATH --quant int8_smoothquant

# VLM PTQ: examples/vlm_ptq -> examples/hf_ptq with --vlm
scripts/huggingface_example.sh --model $HF_PATH --quant fp8 --vlm

# gpt-oss QAT: --quant_cfg <CFG name> -> --recipe <recipe path>
accelerate launch --config_file configs/zero3.yaml sft.py \
  --config configs/sft_full.yaml --model_name_or_path openai/gpt-oss-20b \
  --recipe general/ptq/mxfp4_mlp_weight_only --output_dir gpt-oss-20b-qat
```

```python
# Layerwise calibration: bool / flat key -> nested LayerwiseConfig
quant_cfg["algorithm"] = {"method": "gptq", "layerwise": {"enable": True, "checkpoint_dir": "/path"}}
```

### Testing

- `tests/unit/recipe` (229 passed),
`tests/unit/torch/quantization/test_config_validation.py` (79 passed),
`tests/examples/hf_ptq/test_hf_ptq_args.py` (23 passed).
- Verified the two new recipes `model_dump` identical to the `mtq.*_CFG`
constants they replace.
- `ruff check modelopt/ examples/ tests/` clean; `ruff format --check`
clean on all changed Python files.
- GPU suites
(`tests/gpu/torch/export/test_unified_hf_export_and_check_safetensors.py`,
`test_accelerate_gpu.py`, `test_gptq.py`) had their preset / layerwise
literals updated but were not run locally — relying on CI.
- `examples/llm_qat/ARGUMENTS.md` is hand-edited to match what the
`generate-arguments-md` hook emits; the generator could not run locally
(missing `transformers` package metadata in this environment).

### Before your PR is "*Ready for review*"

- Is this change backward compatible?: ❌ — that is the point of the PR:
it removes shims deprecated in 0.45/0.46. Callers must move to the
replacements in the table above. Additionally, a pre-0.45
`modelopt_state` carrying `use_sequential` or a top-level
`layerwise_checkpoint_dir` will now fail config validation.
- If you copied code from any other sources or added a new PIP
dependency, did you follow guidance in `CONTRIBUTING.md`: N/A
- Did you write any new necessary tests?: ✅ — existing tests migrated to
the surviving APIs;
`TestLayerwiseNestedConfig::test_legacy_forms_rejected` pins that the
bool form, the `use_sequential` alias and the flat checkpoint-dir key
are all rejected. Tests covering the removed shims were deleted.
- Did you update
[Changelog](https://github.com/NVIDIA/Model-Optimizer/blob/main/CHANGELOG.rst)?:
✅
- Did you get Claude approval on this PR?: ❌

### Additional Information

Follow-up: the transformers 4.x drop deprecated in 0.46 is still
outstanding and will need its own PR.

🤖 Generated with [Claude Code](https://claude.com/claude-code)


<!-- This is an auto-generated comment: release notes by coderabbit.ai
-->
## Summary by CodeRabbit

## New Features
- Added MXFP4 and NVFP4 weight-only quantization recipes for MLP and MoE
layers.
- Added shared layer exclusions for more accurate effective-bits
calculations.

## Improvements
- Updated PTQ, QAT, GPT-OSS, deployment, and quantization-format
examples with current recipe names and configuration formats.
- Standardized layerwise settings under nested configuration fields.

## Breaking Changes
- Removed deprecated AutoQuantize options, `quant_cfg` usage, format
aliases, legacy layerwise settings, and compatibility example paths.
- Recipe-based and nested configuration forms are now required.
<!-- end of auto-generated comment: release notes by coderabbit.ai -->

---------

Signed-off-by: Keval Morabia <28916987+kevalmorabia97@users.noreply.github.com>
Co-authored-by: Claude Opus 5 (1M context) <noreply@anthropic.com>
|
||
|
Keval MorabiaandClaude Opus 4.8
|
58ad6edc5f |
Fix pruned-HF export fallback + add Nemotron-3.5-Lightning launcher examples (#2196)
### What does this PR do? Type of change: Bug fix + new example Two related changes for the Megatron-Bridge Minitron prune/quantize launcher flows: 1. **Fix pruned-HF export crash on containers that reject config-only save.** `#2159` added a config-only HF export path gated only on `hasattr(AutoBridge, "from_hf_config")`. Some Megatron-Bridge versions (e.g. `nemo:26.04`) expose `from_hf_config` but reject a config-only `save_hf_pretrained` (`ValueError: save_hf_pretrained requires a pretrained HuggingFace model`), so `prune_minitron.py` crashed instead of using the intended dummy-model fallback. Now it attempts the config-only save and falls back to the dummy-model path on `ValueError`. 2. **Add Nemotron-3.5-Lightning-30B-A3B launcher examples** (`mbridge_prune.yaml`, `mbridge_quantize.yaml`) on `nemo:26.08`. Prune targets 3B active with an MMLU gate; quantize runs W4A16 NVFP4 4/6 PTQ via the `w4a16_nvfp4_4o6` recipe with `tp_size=1` (static-block NVFP4 MSE is unsupported with TP>1). ### Usage ```shell uv run launch.py --yaml examples/nvidia/NVIDIA-Nemotron-3.5-Lightning-30B-A3B-BF16/mbridge_prune.yaml --yes uv run launch.py --yaml examples/nvidia/NVIDIA-Nemotron-3.5-Lightning-30B-A3B-BF16/mbridge_quantize.yaml --yes ``` ### Testing Verified end-to-end on OCI-HSG: - **Nano prune (`nemo:26.04`)** — exercises the fallback path: config-only save raised the `ValueError`, the fallback caught it and exported via the dummy-model path. `mmlu_10pct_bs32 = 0.5196` (gate 0.50) PASS; vLLM gen PASS. - **Lightning prune (`nemo:26.08`)** — config-only export path: `score = 0.6000` (gate 0.58) PASS, 3.00B active params; vLLM gen PASS. - **Lightning quantize (`nemo:26.08`)** — recipe PTQ + unified-HF export; MMLU `0.7741` (gate 0.75) PASS. ### Before your PR is "*Ready for review*" - Is this change backward compatible?: ✅ - If you copied code from any other sources or added a new PIP dependency, did you follow guidance in `CONTRIBUTING.md`: N/A - Did you write any new necessary tests?: N/A <!-- launcher example configs + fallback path exercised by CI prune/quantize jobs --> - Did you update [Changelog](https://github.com/NVIDIA/Model-Optimizer/blob/main/CHANGELOG.rst)?: N/A <!-- fix is for a bug introduced in the same unreleased cycle (#2159); rest are example configs --> - Did you get Claude approval on this PR?: ❌ <!-- pending /claude review --> ### Additional Information The fallback fix addresses the `mbridge_prune` launcher CI failure introduced by #2159. <!-- This is an auto-generated comment: release notes by coderabbit.ai --> ## Summary by CodeRabbit - **New Features** - Added a pruning workflow for Nemotron-3.5-Lightning-30B-A3B with calibration, quality scoring, checkpoint export, and multi-GPU generation. - Added a four-GPU NVFP4 W4A16 quantization workflow with Hugging Face conversion and MMLU evaluation. - **Bug Fixes** - Improved hybrid model export by falling back to dummy-model export for supported configuration-only export failures. - Added clearer logging and handling for supported export failures while preserving unrelated errors for investigation. <!-- end of auto-generated comment: release notes by coderabbit.ai --> --------- Signed-off-by: Keval Morabia <28916987+kevalmorabia97@users.noreply.github.com> Co-authored-by: Claude Opus 4.8 <noreply@anthropic.com> |
||
|
skierat
|
c4129b6e03 |
Add Cosmos3 Nano DFlash multimodal training recipe (#2053)
### What does this PR do? Type of change: new example Adds an end-to-end Cosmos3 Nano DFlash training recipe for multimodal speculative decoding. - Adds a notebook that prepares data, launches synthetic generation in Slurm, trains a DFlash draft model, exports it, and provides a vLLM smoke-test command. - Adds PAI-Understanding, VQA v2, and multilingual prompt sharding and distributed-generation helpers. - Adds an atomic, multimodal-safe merge and conservative deduplication flow. - Extends the VLM data collator to handle structured image/video messages, configurable visual bounds, and fixed DFlash sequence lengths. - Hardens generation launch scripts and preserves truncated generated responses. ### Usage ```bash cd examples/speculative_decoding/recipes export MODEL_PATH=/path/to/cosmos3-nano export PLAIN_TEXT_INPUT=/path/to/nemotron-chat-or-approved-user-data.jsonl jupyter lab train_dflash_cosmos3_nano.ipynb Run the notebook in order: 1. Configure paths. 2. Prepare prompts on a CPU-only node and generate target completions in a Slurm GPU allocation. 3. Merge the four required sources and submit training. 4. Export a saved checkpoint and run the vLLM deployment smoke test. ### Testing - jq empty examples/speculative_decoding/recipes/train_dflash_cosmos3_nano.ipynb - bash -n on the modified launch, worker, and recipe shell scripts. - Ran a two-step Cosmos3 Nano DFlash Slurm smoke job; it completed and wrote modelopt_state.pth. - Not run: pytest tests/unit/torch/speculative/plugins/test_hf_speculative_offline.py (pytest is unavailable in the current environment). ### Before your PR is "Ready for review" - Is this change backward compatible?: ✅ - If you copied code from any other sources or added a new PIP dependency, did you follow guidance in CONTRIBUTING.md?: N/A - Did you write any new necessary tests?: ✅ - Did you update CHANGELOG.rst?: N/A - Did you get Claude approval on this PR?: N/A ### Additional Information Security follow-up required before marking ready: the notebook hardcodes model.trust_remote_code=true and --trust_remote_code. Either parameterize this with a default of false, or obtain and document a security exception. <!-- This is an auto-generated comment: release notes by coderabbit.ai --> ## Summary by CodeRabbit * **New Features** * Added end-to-end multimodal workflows for dataset preparation, distributed generation, result merging, training, export, and deployment testing. * Added support for image and video inputs, multiple dataset formats, resumable JSONL generation, configurable serving, and parallel processing. * Added configurable prompt, media, token, sequence, temperature, and tensor-parallel settings. * **Bug Fixes** * Improved truncated-response handling, assistant-label processing, validation, health checks, cleanup, deduplication, media resolution, atomic outputs, and failure reporting. <!-- end of auto-generated comment: release notes by coderabbit.ai --> --------- Signed-off-by: Slawomir Kierat <skierat@nvidia.com> |
||
|
Jenny Chen
|
a57fb44d46 |
Preserve HF PTQ checkpoint sidecar files [NV BUG 6491822] (#2060)
### What does this PR do? Type of change: Bug fix In `hf_ptq.py` when exporting a PTQ checkpoint, it would drop some files from the original BF16 checkpoint because it uses a whitelist pattern to allow certain files. However that is brittle and can drop files such as reasoning parsers. Now we make hf_ptq.py match Megatron-Core export behavior by copying all non-safe tensor files, but filter only allowed non-safetensor files for more safety. ### Usage ```python # Add a code snippet demonstrating how to use this ``` ### Testing <!-- Mention how have you tested your change if applicable. --> ### Before your PR is "*Ready for review*" Make sure you read and follow [Contributor guidelines](https://github.com/NVIDIA/Model-Optimizer/blob/main/CONTRIBUTING.md) and your commits are signed (`git commit -s -S`). Make sure you read and follow the [Security Best Practices](https://github.com/NVIDIA/Model-Optimizer/blob/main/SECURITY.md#security-coding-practices-for-contributors) (e.g. avoiding hardcoded `trust_remote_code=True`, `torch.load(..., weights_only=False)`, `pickle`, etc.). - Is this change backward compatible?: ✅ / ❌ / N/A <!--- If ❌, explain why. --> - If you copied code from any other sources or added a new PIP dependency, did you follow guidance in `CONTRIBUTING.md`: ✅ / ❌ / N/A <!--- Mandatory --> - Did you write any new necessary tests?: ✅ / ❌ / N/A <!--- Mandatory for new features or examples. --> - Did you update [Changelog](https://github.com/NVIDIA/Model-Optimizer/blob/main/CHANGELOG.rst)?: ✅ / ❌ / N/A <!--- Only for new features, API changes, critical bug fixes or backward incompatible changes. --> - Did you get Claude approval on this PR?: ✅ / ❌ / N/A <!--- Run `/claude review`. NVIDIA org members can self-trigger for complex changes; orthogonal to CodeRabbit. --> ### Additional Information <!-- E.g. related issue. --> <!-- This is an auto-generated comment: release notes by coderabbit.ai --> ## Summary by CodeRabbit * **Bug Fixes** * Improved Hugging Face checkpoint handling to preserve eligible sidecar files while excluding weights, indexes, stale quantization metadata, and unsupported artifacts. * Preserved existing export files and applied consistent file filtering. * Improved snapshot resolution when remote code is disabled. * Ensured unified exports handle generation configuration files correctly. * **Tests** * Added coverage for sidecar copying, exclusions, existing-file preservation, supported file patterns, and snapshot downloads. <!-- end of auto-generated comment: release notes by coderabbit.ai --> --------- Signed-off-by: Jennifer Chen <jennifchen@nvidia.com> |
||
|
yueshen2016
|
686da8d893 |
feat(megatron-bridge): SFT-masked data support in distillation (#2113)
## What does this PR do ?

**Type of change:** New feature

**Overview:** Adds SFT-masked data support to the Megatron-Bridge
distillation example, so a
model can be distilled on prompt/response pairs with the loss masked to
the response.

Today `examples/megatron_bridge/distill.py` only consumes
pretraining-style data — `GPTDataset`
over pre-tokenized blends with `NullTokenizer` — so the loss is computed
over every token. When
distilling an instruction-tuned model it is usually preferable to train
on prompt/response pairs
and mask the loss to the response, matching how the model was
fine-tuned.

## Usage

```bash
python examples/megatron_bridge/distill.py \
  --teacher_hf_path <teacher> --student_hf_path <student> \
  --sft --sft_dataset_root /path/to/data \
  ...
```

where `/path/to/data` holds `training.jsonl` / `validation.jsonl` of
records:

```json
{"input": "<prompt>", "output": "<response>"}
```

## How it works

Switches the data path to Bridge's `FinetuningDatasetConfig` (NeMo-style
`GPTSFTDataset`):

* `prompt_template="{input}{output}"` tokenizes input+output verbatim —
adjacent placeholders,
  no separator — so the text is fed exactly as provided
* `label_key="output"` with `answer_only_loss=True` masks the loss to
the response
  (`answer_start_idx == len(context_ids)`)
* `truncation_field="input"` truncates the context when a pair exceeds
`seq_length`

Two supporting changes, both scoped to `--sft`:

* **Tokenizer.** SFT reads raw text, so it uses the model's real
HuggingFace tokenizer. The
pretraining path consumes pre-tokenized data and keeps `NullTokenizer`.
* **Loss reduction.** A response-only mask requires per-token loss to
combine correctly across
context-parallel ranks, so `calculate_per_token_loss` is enabled and
`average_in_collective`
  is disabled. Both are untouched on the pretraining path.

## Testing

Used for quantization-aware distillation of Nemotron-Nano-3 (W4A16
NVFP4) at `seq_length=32768`
with CP>1: 200 iterations, logits-distillation loss `3.37e-2 -> 1.91e-2`
monotonically, router
`seq_load_balancing_loss` steady, and the resulting checkpoint exports
and serves correctly.

Opt-in: without `--sft` the existing mock/blend data path is unchanged.

## Before your PR is "Ready for review"

- **Make sure you read and follow [Contributor
guidelines](https://github.com/NVIDIA/Model-Optimizer/blob/main/CONTRIBUTING.md)**
and your commits are signed.
- **Is this change backward compatible?**: Yes — purely additive and
opt-in behind `--sft`.
- **Did you write any new necessary tests?**: No
- **Did you add or update any necessary documentation?**: No
- **Did you update
[Changelog](https://github.com/NVIDIA/Model-Optimizer/blob/main/CHANGELOG.rst)?**:
No

🤖 Generated with [Claude Code](https://claude.com/claude-code)


<!-- This is an auto-generated comment: release notes by coderabbit.ai
-->
## Summary by CodeRabbit

* **New Features**
* Added supervised fine-tuning (SFT) support for distillation workflows.
* Added configuration and validation for SFT dataset locations and
supported inputs.
* Added raw prompt/completion JSONL datasets with response-only loss
masking.
* Added truncation, end-of-sequence handling, and student-tokenizer
support without automatic chat templates or BOS tokens.
  * Added matching student and teacher vocabulary validation.
  * Preserved existing mock and GPT dataset modes for non-SFT runs.

* **Documentation**
* Documented required filenames, record format, tokenizer behavior, and
completion-only loss masking.
<!-- end of auto-generated comment: release notes by coderabbit.ai -->

---------

Signed-off-by: James Shen <yueshen@nvidia.com>
|
||
|
Chenjie Luo
|
b96841db3e |
Add optional MLflow tracking to the vLLM fake-quant server (#2120)
### What does this PR do? Type of change: new feature Wires `examples/vllm_serve/vllm_serve_fakequant.py` up to `modelopt.torch.utils.mlflow` via `--mlflow <tracking-uri>`, the same way #2023 did for `hf_ptq.py`, so a fake-quant serve records **what it actually quantized** and an evaluation of that endpoint can be traced back to a recipe. Without the flag, behavior is unchanged — every hook is gated on it. Three design points worth review: 1. **The run is recorded in the vLLM worker, not the launcher.** `vllm_serve_fakequant.py` is the API-server frontend; the engine and its workers are separate processes whose stdout it never sees, so a run opened there would capture none of the calibration. The launcher instead only settles the tracking configuration — validating the URI, naming the experiment, recording the command the user actually typed — and publishes it through the environment, which is how every other setting in this example (`QUANT_CFG`, `RECIPE_PATH`, …) already reaches the workers. Global rank 0 opens the run, so a TP-8 serve produces one run. 2. **The run covers load-through-warm-up, not the server's lifetime.** It opens *before the weights load*, so an unreachable server or a missing token fails in seconds rather than after a load and a full calibration, and it closes `FINISHED` once the model is quantized and warmed up. A run that stayed open for the serving lifetime would never close cleanly on SIGTERM. 3. **`recipe/quant_cfg.yaml` is only written on the preset path.** With `RECIPE_PATH`, `get_quant_config` returns the recipe's `quantize` section unchanged and `resolved_recipe.yaml` already carries it. With `QUANT_CFG`/`KV_QUANT_CFG` it is the *only* record of what ran: the params carry the preset names, while the config reaching `mtq.quantize` is those two deep-copied, merged, and — for an MLA model — extended at runtime with `*kv_c_bmm_quantizer` / `*k_pe_bmm_quantizer` by inspecting the loaded model. Uploaded artifacts: | Artifact | Contents | | --- | --- | | `command.txt` | The launcher's invocation, copy-pasteable, credentials masked | | `version.txt` | The ModelOpt version that ran | | `recipe/resolved_recipe.yaml` | `RECIPE_PATH` with its `$import`s expanded | | `recipe/quant_cfg.yaml` | Merged `QUANT_CFG`/`KV_QUANT_CFG` + MLA fixup (preset path only) | | `logs/<script>.log` | The rank-0 worker's stdout/stderr, including a crash traceback | | `summary/quant_summary.txt` | The per-quantizer summary | Plus the quantization *and* serving settings as searchable params, and `user` / `hostname` / `modelopt_version` / `git_sha` / `vllm_version` tags. The `checkpoint_path` tag matches the one `hf_ptq.py` sets, so a checkpoint's PTQ run and every serve of it join up. Two small library additions, both consumed by the new example module: - `command_text(argv=None)` — records another process's invocation, since a spawned worker's own `sys.argv` is vLLM plumbing rather than anything a user typed. - `MlflowRunLogger.log_text()` — uploads a value settled midway through a run, so a crash during calibration still keeps the config that caused it. The example `Dockerfile` installs the `mlflow` extra; the client remains optional and is imported only once tracking is enabled. ### Usage ```bash RECIPE_PATH=<recipe.yaml> python vllm_serve_fakequant.py <model_path> -tp 8 \ --host 0.0.0.0 --port 8000 \ --mlflow https://<your-mlflow-server>/ ``` ``` [mlflow] tracking to https://<your-mlflow-server>, experiment $USER/vllm_serve_fakequant/<model>-<recipe> (Worker_TP0) [mlflow] run: https://<your-mlflow-server>/#/experiments/19/runs/1c6679448f25... ``` `--mlflow-experiment` / `--mlflow-run-name` override the defaults. `$MLFLOW_TRACKING_URI` enables tracking on its own and is best-effort; an explicit `--mlflow` overrides it and fails loudly. > This is the **quantization** tracking server. It is unrelated to any server an evaluation harness exports its scores to — NeMo Evaluator Launcher has its own `export.mlflow.tracking_uri`. The README calls this out. ### Testing **Unit — 87 passing** (`tests/examples/vllm_serve/test_vllm_mlflow_utils.py`, 33 new; `tests/unit/torch/utils/test_mlflow.py`, +5). `vllm_mlflow_utils` deliberately imports no vLLM, so the whole launcher→worker handover is covered without a GPU, a server, or the mlflow client. **End to end on aws-cmh** (4× GB300, `simple_evals.gpqa_diamond`, Nemotron-3.5-Lightning-30B-A3B-BF16 fake-quantized with `general/ptq/nvfp4_mlp_only-kv_fp8_cast`): run `FINISHED` in 261.5 s, opened by `Worker_TP0` only, all artifacts present and verified by content — `command.txt` held the launcher's invocation rather than the worker's spawn argv, and `resolved_recipe.yaml` was 6797 B against 1845 B of source. 104 quantizers enabled (92 NVFP4 dynamic block-16 expert weight/input with calibrated amax, 12 FP8 KV bmm). The eval then ran to completion against the served endpoint, 22/22 requests HTTP 200. Two bugs the hardware run caught, both fixed here with regression tests: - `--mlflow_run_name` was rejected. vLLM's `FlexibleArgumentParser.parse_args` rewrites **every** `--foo_bar` to `--foo-bar` before matching, so a flag registered only under the underscored spelling is unreachable from its CLI. Both spellings are now registered. A unit test on a plain `ArgumentParser` could not have caught this. - `recipe/quant_cfg.yaml` uploaded a Python `repr` blob under a `.yaml` name: a recipe's `quantize` is a `QuantizeConfig`, `yaml.safe_dump` raises `RepresenterError` on it, and the old JSON fallback stringified the object. `_dump_yaml` now unwraps pydantic via `model_dump(mode="json")` and raises otherwise, with the caller downgrading that to a warning so a bad config cannot take down a serve. **Known coverage gap:** the preset (`QUANT_CFG`/`KV_QUANT_CFG`) path — the only one that now writes `recipe/quant_cfg.yaml` — is covered by unit test but has not been exercised on hardware; the canary used `RECIPE_PATH`. Likewise the case where `$MLFLOW_TRACKING_URI` is present *inside* the deployment container and `--mlflow` overrides it is unit-tested only: NeMo Evaluator Launcher forwards only declared env vars, so the eval server's URI never entered the container in the canary. ### Before your PR is "*Ready for review*" - Is this change backward compatible?: ✅ — new optional flags only; no `--mlflow` means no behavior change. - If you copied code from any other sources or added a new PIP dependency, did you follow guidance in `CONTRIBUTING.md`: ✅ — no new dependency. Uses the existing optional `nvidia-modelopt[mlflow]` extra (`mlflow-skinny`, Apache-2.0) added in #2023; the example `Dockerfile` now installs it. No code copied from other sources. - Did you write any new necessary tests?: ✅ — 38 new tests. - Did you update [Changelog](https://github.com/NVIDIA/Model-Optimizer/blob/main/CHANGELOG.rst)?: ✅ — 0.47 Misc. - Did you get Claude approval on this PR?: ❌ — `/claude review` not yet run. ### Additional Information Follows #2023, which added `MlflowRunLogger` and the `hf_ptq.py` integration. Note for anyone tracking from an OCI cluster: `mlflow-modelopt.nvidia.com` is unreachable from oci-nrt and oci-hsg. TCP 443 completes and the connection is then reset on the first application byte, regardless of SNI or protocol, one RTT away — the PDX PaaS ingress appears to apply a source-IP policy, and the OCI clusters egress from Oracle-owned addresses (`155.248.190.0`, `168.110.199.1`) rather than NVIDIA's. gcp-nrt, aws-cmh and cw-dfw all reach it. This is an infrastructure matter, not a property of this change, but it determines where the feature is usable today. 🤖 Generated with [Claude Code](https://claude.com/claude-code) <!-- This is an auto-generated comment: release notes by coderabbit.ai --> ## Summary by CodeRabbit * **New Features** * Added optional MLflow tracking for vLLM fake-quantization serving runs. * Records serving, quantization, worker, and invocation metadata, including configuration and summary artifacts. * Supports tracking URI, credentials, environment, and command-line configuration. * Added command and text artifact logging for active MLflow runs. * **Documentation** * Documented setup, configuration, recorded artifacts, lifecycle, and fallback behavior. * Updated the example container to include MLflow support. * **Tests** * Added comprehensive coverage for tracking configuration, logging, failures, and disabled tracking. <!-- end of auto-generated comment: release notes by coderabbit.ai --> --------- Signed-off-by: Chenjie Luo <chenjiel@nvidia.com> |
||
|
ZhiyuandClaude Opus 5
|
6261f854aa |
docs: rebuild the unified HF deployment support matrix from the deploy test suite (NVBug 6550792) (#2087)
### What does this PR do? Type of change: documentation Fixes [NVBug 6550792](https://nvbugspro.nvidia.com/bug/6550792) / OMNIML-5693. The **Unified HF Checkpoint Deployment Model Support Matrix** listed 9 model families and **no VLMs**, while `tests/examples/hf_ptq/test_deploy.py` declares deployment cases for ~80 checkpoints across TRT-LLM, vLLM, and SGLang — including `Qwen2.5-VL`, `Qwen3-VL-235B`, and `Nemotron-3-Nano-Omni`. QA (the filer) could not use the doc to scope testing, and users could not tell what is actually covered. Filing also surfaced that the matrix lived in **three places that had drifted apart**: only the `.rst` listed Qwen3-VL, only the README listed Qwen3.5 MoE, and the skill reference had neither. #### Changes 1. **Rebuilt the matrix in `docs/source/deployment/3_unified_hf.rst`** from `test_deploy.py`, split into language models, vision-language/multimodal, speculative decoding drafters, and diffusion. 2. **Stated plainly what the matrix is and is not.** Review established that the original "CI-validated" framing claimed more than the suite substantiates, so a *What this matrix is based on* section now leads with two limits: - The suite is marked `release` and collects only under `--run-release`, which **no workflow passes** — these are declared cases, not PR-gated coverage. - Each case is a **load-and-generate smoke check on the text path**: no accuracy, no image/audio input, no diffusion output, no verification that speculative decoding engages. The legend follows from that: ✅ = declared in the suite, ⚠ = expected to work but not a suite entry (or an entry that does not exercise the feature the row names), `-` = not in the suite. Sections that would otherwise over-read carry their own qualifiers — VLM rows are labelled text-only smoke coverage, and Medusa and Wan 2.2 are ⚠ with the reason stated. 3. **Removed the two duplicate copies**, replacing them with links, so there is one table to maintain. 4. **Fixed stale prose**: the deployment tabs still claimed FP8-only support on vLLM v0.6.5 and a source build of SGLang main from Jan 2025, both contradicting the version table above them. The TRT-LLM floor moves to v1.2.0, qualified as the oldest version stated rather than the oldest that works. 5. **Dropped the Phi series** from the deployment matrix, following #2115 (NVBug 6563509) and confirmation that Phi-4 is being deprecated. ### Usage N/A — documentation only. ### Testing - `docutils` parse of the modified `.rst`: no warnings or errors from the new content; all 5 tables parse with every cell in the correct column. - Cell contents cross-checked against `test_deploy.py` by AST-parsing the `ModelDeployerList(...)` calls rather than by eye; the scope caveats were each verified against `tests/_test_utils/deploy_utils.py`. - `pre-commit run --files …` passes; `build-docs` green. ### Before your PR is "*Ready for review*" - Is this change backward compatible?: ✅ - If you copied code from any other sources or added a new PIP dependency, did you follow guidance in `CONTRIBUTING.md`: N/A - Did you write any new necessary tests?: N/A - Did you update [Changelog](https://github.com/NVIDIA/Model-Optimizer/blob/main/CHANGELOG.rst)?: N/A — documentation only - Did you get Claude approval on this PR?: ❌ — not yet run ### Additional Information **Two known follow-ups, neither in scope here:** 1. **Nothing enforces that the doc matrix tracks `test_deploy.py`.** Consolidating to one copy removes the three-way drift but not the doc-vs-test drift; a generator plus a CI check would close it. 2. **The release deployment suite does not run in CI.** Wiring it into per-backend release CI is what would let ✅ mean "verified to pass" rather than "declared". That needs GPU capacity across three backends and should be tracked on its own. **For the filer (@Kenny Kang):** the ✅ cells are the scope the release deploy suite declares, and `test_deploy.py` carries the checkpoint, TP size, and minimum SM version per entry — but please read the legend first, since those cases are not currently executed by CI. --------- Signed-off-by: Zhiyu Cheng <zhiyuc@nvidia.com> Co-authored-by: Claude Opus 5 (1M context) <noreply@anthropic.com> |
||
|
Keval Morabia
|
bee497de03 |
Fix EAGLE3 offline dump skipping all conversations on newer transformers (#2172)
### What does this PR do? Type of change: Bug fix **Fix EAGLE3 offline hidden-state dump silently skipping every conversation on newer `transformers`.** `tokenizer.apply_chat_template(...)` returns a **`BatchEncoding`** (dict of `input_ids` + `attention_mask`) on `transformers>=5` rather than a `list[int]`, so `len(input_ids)` evaluated to **2** (the number of dict fields), tripping the `num_input_tokens <= 10` "too short" filter for **every** conversation. The dump wrote **zero `.pt` files** and offline EAGLE3 training aborted with `No .pt files found`. The token-id extraction is consolidated into `modelopt.torch.speculative.utils.get_conversation_input_ids`, which normalizes the result to a flat `list[int]` (unwrapping `BatchEncoding` / 2-D tensor / batch-wrapped list, asserting the shape so a future `transformers` change fails loudly instead of silently). It is called from all three offline-dump entry points that shared the bug: - `examples/speculative_decoding/collect_hidden_states/compute_hidden_states_trtllm.py` - `examples/speculative_decoding/collect_hidden_states/send_conversations_for_hiddens.py` - `examples/speculative_decoding/scripts/send_conversation_vllm.py` (the two `send_conversation*` scripts additionally indexed/`decode()`d the `BatchEncoding`). Also fixes the `add_generation_template` -> `add_generation_prompt` typo at each site. ### Testing - `tests/unit/torch/speculative/test_speculative_utils.py` — asserts the helper returns the exact token-id sequence of the rendered chat prompt, and pins every `apply_chat_template` return shape (`BatchEncoding`, 2-D tensor, batch-wrapped list, plain list) to a flat `list[int]` via deterministic stubs, so the fixed branch is covered regardless of the installed `transformers` version. - **End-to-end on ComputeLab (H100, TRT-LLM 1.3.0rc20):** reran the exact dump on the 100 conversations that previously failed. Before: 0/100 (0 `.pt` files). After: **97/100** (97 `.pt` files; the 3 skips are genuinely `> max_seq_len`). ### Before your PR is "*Ready for review*" - Is this change backward compatible?: ✅ - If you copied code from any other sources or added a new PIP dependency, did you follow guidance in `CONTRIBUTING.md`: N/A - Did you write any new necessary tests?: ✅ (`tests/unit/torch/speculative/test_speculative_utils.py`) - Did you update Changelog?: N/A - Did you get Claude approval on this PR?: 🔄 `/claude review` run; findings addressed, re-review pending ### Additional Information Surfaced by an nmm-sandbox CI run where `Qwen3-8B_EAGLE3_offline` failed after the container bump to `tensorrt-llm/release:1.3.0rc20`; the auto-blame heuristic mis-attributed it to an unrelated MLflow commit. `compute_hidden_states_vllm.py` is unaffected (it routes through `common.tokenize_with_loss_mask`, which passes `return_dict=True`). --------- Signed-off-by: Keval Morabia <28916987+kevalmorabia97@users.noreply.github.com> |
||
|
Sepehr Sameni
|
10145db53f |
Add link to puzzletron_v2 (#1996)
<!-- This is an auto-generated comment: release notes by coderabbit.ai --> ## Summary by CodeRabbit * **Documentation** * Added a top-level Puzzletron overview with a link to the step-by-step algorithm tutorial. * Added a reference to the experimental Puzzletron branch for advanced, production-scale usage. <!-- end of auto-generated comment: release notes by coderabbit.ai --> --------- Signed-off-by: Sepehr Sameni <ssameni@nvidia.com> |
||
|
Keval MorabiaandClaude Opus 5
|
f99523279a |
Minitron pruning fixes for Nemotron-3.5-Lightning-30B-A3B and Deepseek (#2159)
### What does this PR do?

Type of change: Bug fix + new feature

Two model families that could not be pruned end-to-end now can:

- **Nemotron-3.5-Lightning**
(`nvidia/NVIDIA-Nemotron-3.5-Lightning-30B-A3B-BF16`) — a native
`NemotronHForCausalLM` that ships without remote code and carries MTP
heads. Fixes a calibration crash and HF-export failures on the modern
Megatron-Bridge / transformers stack.
- **DeepSeek-V3** — fixes an MLA Q-LoRA crash during calibration, and
adds a `candidate_filter` search option to `mcore_minitron` so its
MoE-FFN dimensions stay prunable while remaining representable in HF.

Also makes a rank-local failure under pipeline parallelism fail fast
instead of stalling.

#### 1. Nemotron Lightning: prune + HF export
(`examples/megatron_bridge/prune_minitron.py`)

1. **MTP calibration crash.** On newer Megatron-LM, `mtp_process` is
derived from the hybrid *pattern*, not from `mtp_num_layers`. Setting
only `mtp_num_layers=0` in the calibration provider overrides was
insufficient: the provider's `finalize()` re-appended the MTP suffix to
`hybrid_layer_pattern` (because `mtp_hybrid_override_pattern` was still
set and `mtp_use_repeated_layer=True`), so `mtp_process=True` while
`mtp_num_layers=0` and the calibration forward hit `assert
self.config.mtp_num_layers > 0`. Fix: also clear
`mtp_hybrid_override_pattern` in the calibration overrides so MTP is
fully disabled (MTP heads are dropped from the pruned model, as before).

2. **HF export via a config-only bridge (hybrid models only).** The old
export built a *dummy* HF model to obtain the bridge, then streamed
weights. This breaks on native NemotronH because (a) native
`NemotronHConfig` makes `hybrid_override_pattern` a read-only property,
and (b) transformers 5.12 saves the input embedding under a different
key than the bridge mapping expects (`backbone.embedding` vs
`backbone.embeddings`); the mismatch made `build_conversion_tasks` drop
the embedding task on its owning rank, leaving an owner-less PP
placeholder that crashed `save_hf_weights` with `Object must exist on at
least one PP rank`. Fix: stream weights through a **config-only** bridge
(`AutoBridge.from_hf_config(hf_cfg).save_hf_pretrained(...)`), available
since Megatron-Bridge 0.5.0 (nemo:26.06). A config-only bridge has
`hf_keys=None`, so the embedding task is never dropped, no dummy model
is built, and the output uses the canonical HF key names.

This is **restricted to hybrid providers**, which are the only models
that need it; non-hybrids keep the dummy-model path that CI has always
exercised.

Writing the source artifacts is now rank-0-only. Every rank used to
write the source `config.json`, which races with the pruned
`config.json` that `save_hf_pretrained` writes from rank 0 alone: a late
write from another rank leaves a checkpoint whose config does not match
its weights. This reproduced intermittently on both Qwen3 and NemotronH
before the fix, and 3/3 clean runs after.

`save_hf_pretrained` takes no `trust_remote_code` argument — it reads
the flag **off the bridge** to fetch the source checkpoint's artifacts,
and `from_hf_config` cannot infer it because
`AutoConfig.from_pretrained` consumes the kwarg rather than storing it
on the config. So the flag is set explicitly on the bridge instance;
otherwise remote-code models would silently lose it.

3. **Config write-back correctness:**
- `hybrid_override_pattern` is only written for older remote-code
configs that lack `layer_types`; native configs carry the cadence in
`layer_types` (read-only `hybrid_override_pattern` is skipped).
- `n_shared_experts` is preserved (a fixed count) instead of being
re-derived by `moe_shared_expert_intermediate_size //
moe_ffn_hidden_size`, which is DeepSeek-style logic that would corrupt
NemotronH's count.

Non-hybrids, VLMs, and Megatron-Bridge builds without config-only export
keep the dummy-model path, with a `warn_rank_0` when a hybrid has to
fall back. The README's `transformers<5` workaround is **removed**: it
existed because the dummy-model path broke on transformers 5, and the
config-only path handles NemotronH on every supported container.

#### 2. `candidate_filter` for `mcore_minitron`
(`modelopt/torch/prune/plugins/mcore_minitron.py`)

DeepSeek-style MoE configs have no explicit shared-expert-size field:
they size the shared expert as `n_shared_experts *
moe_intermediate_size`, where `moe_intermediate_size` is the (also
prunable) **routed** expert size. So only candidates with
`moe_shared_expert_intermediate_size % moe_ffn_hidden_size == 0` can be
written back to HF at all.

Candidates come from a Cartesian `product()` of independent per-hparam
choice lists, so no per-hparam restriction can express a constraint
*between* two hparams. New optional `candidate_filter` search-config key
(default `None`, so existing behaviour is unchanged): a callable that
rejects candidate configs before the metric computation, making the
search cheaper rather than more expensive. It receives **every**
supported hparam, with non-searched ones filled in from the model
config, so a filter still works when one of its hparams was skipped or
had a single choice.

Rejected candidates are not cached, so — like `score_func`, whose cached
scores are reused without re-validation — the filter is assumed
unchanged when resuming from a `checkpoint`.

`prune_minitron.py` wires this up for DeepSeek-style configs, so
**both** `moe_ffn_hidden_size` and `moe_shared_expert_intermediate_size`
stay prunable (the search then only picks shared sizes that are a
multiple of the routed one). A `--prune_export_config` that violates the
constraint never reaches the filter, so the export path now raises
`ValueError` instead of writing a checkpoint whose config disagrees with
its weights.

#### 3. MLA Q-LoRA pruning
(`modelopt/torch/prune/plugins/mcore_minitron.py`)

Pruning any MLA model with `q_lora_rank` set died during calibration
with `AttributeError: 'tuple' object has no attribute 'view'`.

`hidden_size` importance estimation blanket-patches every
`TELayerNormColumnParallelLinear` with `return_layernorm_output=True` to
capture post-layernorm activations. When `q_lora_rank` is set, MCore
builds `linear_q_up_proj` as a `TELayerNormColumnParallelLinear` — the
Q-LoRA layernorm is fused into it, which is why `q_layernorm` is
`IdentityOp` — so it was patched too, even though its layernorm is over
the **latent rank**, not `hidden_size`. TE then returns `((out, ln_out),
bias)` and MCore's `q, _ = self.linear_q_up_proj(...)` leaves `q` a
tuple.

Isolated by probing the module before and after dynamic conversion:

| Setup | `linear_q_up_proj` returns | Forward |
| --- | --- | --- |
| Before conversion | `tuple(Tensor, NoneType)` | — |
| After conversion, no hooks | `tuple(Tensor, NoneType)` | OK |
| After conversion **+ importance hooks** | `tuple(tuple(Tensor,
Tensor), NoneType)` | AttributeError |

So conversion is innocent; registering the importance hooks is the
trigger. Fix: exclude MLA's Q/KV up-projections from both the patch and
unpatch loops. `test_mcore_mla_pruning` did not catch this because it
builds MLA without `q_lora_rank`, where MCore uses a plain
`linear_q_proj` and nothing is patched.

#### 4. Fail fast instead of stalling on a rank-local error under PP
(`modelopt/torch/utils/distributed.py`)

A rank raising inside a distributed entrypoint left the whole job
stalled until the process group timed out, with **no diagnostic output
at all**: the failing rank blocked in `cleanup()`'s barrier while its
peers blocked in `recv_from_prev_pipeline_rank_`, and Python only prints
a traceback once the enclosing `finally` returns. A crash on one rank
was indistinguishable from a slow job.

- `dist.cleanup()` skips the barrier when unwinding from an exception.
- New `dist.abort()` prints the traceback, flushes and exits
immediately. Skipping the barrier alone is **not** enough — a stack dump
showed the failing rank then blocking in `destroy_process_group` for the
same reason — so the error path must not tear the process group down at
all. `SystemExit` is re-raised rather than aborted, so an intentional
exit (e.g. the `--score_lower_bound` gate) keeps its exit code and
prints no traceback. Kept out of `cleanup()` so no library caller gets a
surprise process exit.
- Called from the entrypoints that wrap `main()` in `try/finally`: the
five `examples/megatron_bridge` scripts.

Measured on a 2-GPU PP run whose rank 0 raises during calibration: **10
min timeout kill with no visible error → 31s, exit 1, real traceback.**
This is a latent, pre-existing issue (the `try/finally` predates this
PR); it only surfaces on a failing PP run, which is why CI never hit it.

### Usage

```bash
torchrun --nproc_per_node 4 examples/megatron_bridge/prune_minitron.py \
    --hf_model_name_or_path nvidia/NVIDIA-Nemotron-3.5-Lightning-30B-A3B-BF16 \
    --pp_size 4 \
    --prune_target_active_params 3e9 \
    --output_hf_path /path/to/Nemotron-3.5-Lightning-30B-A3B-Pruned-A3.0B
```

### Testing

- **End-to-end on nemo:26.08.rc6** (4× GB300, transformers 5.12.1,
Megatron-Bridge with config-only export): pruning + export complete
(`EXIT=0`, "Saved pruned model … Done!"). The exported checkpoint has
canonical **plural** `backbone.embeddings.weight` keys, **0 MTP
tensors**, and a config that reloads correctly (`num_hidden_layers=52`
from `layers_block_type`, `n_shared_experts=1`,
`num_nextn_predict_layers=0`, pruned `hidden_size`/`mamba_*`/MoE dims,
reconstructed `hybrid_override_pattern`).

  <details>
<summary>Pruning search log (<code>--prune_target_active_params
3e9</code>)</summary>

  ```text
Top 10 Candidates with Scores

┏━━━━┳━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━┳━━━━━━━━━━━━━━━┳━━━━━━━━┳━━━━━━━━┓
┃ # ┃ export_config ┃ active_params ┃ params ┃ score ┃

┡━━━━╇━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━╇━━━━━━━━━━━━━━━╇━━━━━━━━╇━━━━━━━━┩
│ 1 │ {'num_layers': 46, 'hidden_size': 2560, 'mamba_num_heads': 56,
'mamba_head_dim': 56, 'num_moe_experts': 104, │ 3.00B │ 23.49B │ 0.5406
│
│ │ 'moe_ffn_hidden_size': 1856, 'moe_shared_expert_intermediate_size':
3584} │ │ │ │
│ 2 │ {'num_layers': 52, 'hidden_size': 2688, 'mamba_num_heads': 56,
'mamba_head_dim': 48, 'num_moe_experts': 96, │ 3.00B │ 20.09B │ 0.2427 │
│ │ 'moe_ffn_hidden_size': 1536, 'moe_shared_expert_intermediate_size':
3072} │ │ │ │
│ 3 │ {'num_layers': 52, 'hidden_size': 2688, 'mamba_num_heads': 48,
'mamba_head_dim': 56, 'num_moe_experts': 104, │ 3.00B │ 21.61B │ 0.2643
│
│ │ 'moe_ffn_hidden_size': 1536, 'moe_shared_expert_intermediate_size':
3072} │ │ │ │
│ 4 │ {'num_layers': 52, 'hidden_size': 2560, 'mamba_num_heads': 48,
'mamba_head_dim': 64, 'num_moe_experts': 96, │ 3.00B │ 19.28B │ 0.4552 │
│ │ 'moe_ffn_hidden_size': 1536, 'moe_shared_expert_intermediate_size':
3712} │ │ │ │
│ 5 │ {'num_layers': 52, 'hidden_size': 2304, 'mamba_num_heads': 64,
'mamba_head_dim': 64, 'num_moe_experts': 104, │ 3.00B │ 22.28B │ 0.5860
│
│ │ 'moe_ffn_hidden_size': 1856, 'moe_shared_expert_intermediate_size':
3072} │ │ │ │
│ 6 │ {'num_layers': 52, 'hidden_size': 2560, 'mamba_num_heads': 48,
'mamba_head_dim': 48, 'num_moe_experts': 96, │ 3.00B │ 21.99B │ 0.2294 │
│ │ 'moe_ffn_hidden_size': 1792, 'moe_shared_expert_intermediate_size':
3328} │ │ │ │
│ 7 │ {'num_layers': 48, 'hidden_size': 2560, 'mamba_num_heads': 56,
'mamba_head_dim': 56, 'num_moe_experts': 104, │ 3.00B │ 23.68B │ 0.5231
│
│ │ 'moe_ffn_hidden_size': 1792, 'moe_shared_expert_intermediate_size':
3072} │ │ │ │
│ 8 │ {'num_layers': 46, 'hidden_size': 2560, 'mamba_num_heads': 56,
'mamba_head_dim': 56, 'num_moe_experts': 96, │ 3.00B │ 21.81B │ 0.5042 │
│ │ 'moe_ffn_hidden_size': 1856, 'moe_shared_expert_intermediate_size':
3584} │ │ │ │
│ 9 │ {'num_layers': 52, 'hidden_size': 2688, 'mamba_num_heads': 48,
'mamba_head_dim': 56, 'num_moe_experts': 96, │ 3.00B │ 20.09B │ 0.2462 │
│ │ 'moe_ffn_hidden_size': 1536, 'moe_shared_expert_intermediate_size':
3072} │ │ │ │
│ 10 │ {'num_layers': 52, 'hidden_size': 2304, 'mamba_num_heads': 64,
'mamba_head_dim': 64, 'num_moe_experts': 96, │ 3.00B │ 20.70B │ 0.5685 │
│ │ 'moe_ffn_hidden_size': 1856, 'moe_shared_expert_intermediate_size':
3072} │ │ │ │

└────┴───────────────────────────────────────────────────────────────────────────────────────────────────────────────────────┴───────────────┴────────┴────────┘


╭────────────────────────────────────────────────────────────────────────
Best Subnet
─────────────────────────────────────────────────────────────────────────╮
│ export_config {'num_layers': 52, 'hidden_size': 2304,
'mamba_num_heads': 64, 'mamba_head_dim': 64, 'num_moe_experts': 104,
'moe_ffn_hidden_size': 1856, │
│ 'moe_shared_expert_intermediate_size': 3072} │
│ active_params 3.00B │
│ params 22.28B │
│ score 0.5860 │

╰──────────────────────────────────────────────────────────────────────────────────────────────────────────────────────────────────────────────────────────────╯

╭────────────────────────────────────────────────────── Pruned Model
Stats ───────────────────────────────────────────────────────╮
│ Total Parameters 22.28B │
│ Active Parameters 3.00B │
│ Memory (BF16, seq_length=8192, batch_size=8) weights: 42489.7 MB,
kv_cache: 384.0 MB, mamba_state: 190.5 MB, Total: 43064.2 MB │

╰─────────────────────────────────────────────────────────────────────────────────────────────────────────────────────────────────╯
  ```

  </details>

- **`tests/examples/megatron_bridge/test_prune_minitron.py`** —
`nemotron_h` now exports to HF and reloads (previously it stopped at a
Megatron checkpoint, since the dummy-model path needed
`transformers<5`), plus an `n_shared_experts` config assertion; the dead
`megatron_format` branch is gone. It runs on the CI container:
**verified on nemo:26.06.01 (transformers 5.8.1) and nemo:26.08.rc6.**
-
**`tests/gpu_megatron/torch/prune/plugins/test_mcore_mamba_minitron_pruning.py`**
— the `nas_memory_mb` search test now passes a `candidate_filter` and
asserts the exact number of rejected candidates (256 of the 512-combo
grid) plus the surviving candidates' validity; its `expected_top_k`
goldens are regenerated accordingly. Because
`moe_shared_expert_intermediate_size` is in that test's skip list, this
also covers the model-config fallback for hparams that are not in the
search space.

Verified on 2 GPUs, on both the CI container (nemo:26.06.01) and
nemo:26.08.rc6:

| Test | Result |
| --- | --- |
| `test_prune_minitron[qwen3]` | PASSED on 26.06.01 and 26.08.rc6 |
| `test_prune_minitron[deepseek_v3]` | PASSED (52s) — MLA Q-LoRA +
`candidate_filter` end-to-end |
| `test_prune_minitron[nemotron_h]` | PASSED on 26.06.01 (58s) and
26.08.rc6 (61s) |
| `test_mcore_mamba_hybrid_pruning_nas_memory_mb` | PASSED |
| `test_mcore_mamba_hybrid_pruning_nas_params` | PASSED (unchanged
sibling, run to check the regenerated goldens did not disturb it) |
| 2-GPU PP run failing on rank 0 | fails in 31s with a real traceback
(was a 10 min stall) |


### Before your PR is "*Ready for review*"

- Is this change backward compatible?: ✅ — `candidate_filter` defaults
to `None` (existing searches unchanged), and the config-only export is
limited to hybrid providers on nemo:26.08+, so dense / MoE / VLM exports
keep the path they use today.
- If you copied code from any other sources or added a new PIP
dependency, did you follow guidance in `CONTRIBUTING.md`: N/A
- Did you write any new necessary tests?: ✅
- Did you update Changelog?: N/A
- Did you get Claude approval on this PR?: ✅

### Additional Information

Enables the Prune + Distill workflow for
`NVIDIA-Nemotron-3.5-Lightning-30B-A3B-BF16` (native, no-remote-code
`NemotronHForCausalLM` with MTP heads). Pruning-time MTP support was
scoped and intentionally deferred — MTP heads are dropped and can be
re-derived via a short SFT with `mtp_num_layers=1` on the
pruned+distilled model.

---------

Signed-off-by: Keval Morabia <28916987+kevalmorabia97@users.noreply.github.com>
Co-authored-by: Claude Opus 5 (1M context) <noreply@anthropic.com>
|
||
|
sugunav14andClaude Opus 5
|
a21173a4d5 |
Bug fix: 6542481 (#2064)
### What does this PR do? Type of change: Bug fix Fixes `AssertionError: Model already has modelopt state!` when exporting a QLoRA checkpoint (NVBug 6542481). The QLoRA output is adapter-only, so `from_pretrained` resolves the quantized base model and already restores the ModelOpt state; `export.py` then restored a second time. Fixing that exposed two more breakages on the same path, also fixed here: - `_restore_qtensor_wrappers` missed every module — PEFT renames the compressed linears to `<name>.base_layer`, so no weight got re-wrapped and the packed NVFP4 weight hit a shape error. - `postprocess_state_dict` dropped `weight_scale_2` (missing from the QLoRA rename map), leaving the exported checkpoint impossible to dequantize. ### Usage No API change — `examples/llm_qat/export.py --pyt_ckpt_path <qlora_ckpt> --export_path <out>` now completes on the documented quantize → train → export flow. ### Testing Reproduced in the reported environment (TRT-LLM 1.3.0rc22, transformers 5.5.4, NVFP4). - Added the missing export step to `test_qwen3_qlora_nvfp4` and a unit test for the QLoRA `base_layer` rename; both fail without the fix. - Exported base model is byte-identical to a plain PTQ export; dequantized NVFP4 weights match the bf16 original (worst rel. error 0.10). - No regressions: `tests/gpu/torch/export/test_export.py` (49 passed), save/load plugin tests. ### Before your PR is "*Ready for review*" - Is this change backward compatible?: ✅ - If you copied code from any other sources or added a new PIP dependency: N/A - Did you write any new necessary tests?: ✅ - Did you update Changelog?: ❌ — can add if wanted - Did you get Claude approval on this PR?: ❌ — not run yet ### Additional Information Fixes NVBug 6542481. <!-- This is an auto-generated comment: release notes by coderabbit.ai --> ## Summary by CodeRabbit * **Bug Fixes** * Improved QLoRA checkpoint export and restoration across supported model configurations. * Preserved secondary weight-scale information and other deployment tensors in exported checkpoints. * Corrected handling of quantized base-layer weights after adapter reparenting. * Prevented duplicate state restoration when checkpoints already include the required model state. * Removed internal adapter prefixes and quantizer details from exported state data. * **Tests** * Added validation for packed weights, quantization metadata, required scales, and removal of embedded adapter layers. * Added regression coverage for QLoRA state processing and quantized weight restoration. <!-- end of auto-generated comment: release notes by coderabbit.ai --> --------- Signed-off-by: Suguna Velury <178320438+sugunav14@users.noreply.github.com> Co-authored-by: Claude Opus 5 (1M context) <noreply@anthropic.com> |
||
|
Chenjie LuoandClaude Opus 5
|
9220fac053 |
[NVBug: 6563509] Drop Phi-3-vision / Phi-4-multimodal PTQ support (#2115)
### What does this PR do?
Type of change: Deprecation
Resolves [NVBug 6563509](https://nvbugspro.nvidia.com/bug/6563509),
where
`hf_ptq.py` on Phi-4-multimodal-instruct died with
`RuntimeError: Tensor.item() cannot be called on meta tensors`.
The crash is real but not fixable on our side, and it is not the reason
the model
is unusable. Phi-4-multimodal's bundled remote code predates
Transformers v5 and
does not load on **any** version in our supported range
(`transformers>=4.57,<5.15`):
| Blocker | Where |
|---|---|
| `peft.get_peft_model` reads `prepare_inputs_for_generation`, gone
since transformers 4.52 dropped `GenerationMixin` from `PreTrainedModel`
| `modeling_phi4mm.py:1959` |
| `_tied_weights_keys` declared as a list; Transformers 5.x calls
`.keys()` on it in `post_init` | `modeling_phi4mm.py:1937` |
| `int(torch.tensor(...))` in `__init__`, which cannot run on a meta
device — the reported crash | `speech_conformer_encoder.py:1435` |
The model card pins `transformers==4.48.2` / `peft==0.13.2`, so there is
no
overlap with our floor and nothing on our side can bridge it. The model
is
therefore dropped rather than worked around.
**Phi-3-vision is dropped alongside it because it is the older,
superseded model
in the same family** — with its successor unsupportable there is no
reason to
keep carrying the predecessor. This is a product-scope call, not a
separate
compatibility finding: Phi-3-vision shares the list-valued
`_tied_weights_keys`
defect (`modeling_phi3_v.py:1214`) and so is likewise broken on
Transformers 5.x,
but it does **not** hit the `peft` blocker, and it was not re-verified
on 4.57.
Per the 0.46 changelog we have already bumped the floor to 4.57 and
noted that
"Transformers 4.x support will be dropped in a future release", so any
remaining
window closes on its own. Same reasoning already applied to VILA / NVILA
in this
release.
**Removed**
- the support-matrix row in `examples/hf_ptq/README.md`
- `"Phi4MMForCausalLM": "phi4mm"` from `MODEL_NAME_TO_TYPE`
- the multimodal-detection heuristics that only ever matched these two —
`vision_lora`, `audio_processor`, `embd_layer.image_embd_layer`, and the
`phi4mm` model-type check — in both `is_multimodal_model` and
`_is_multimodal_config`
- the `Phi3Image` / `PhiImage` exclusions in `is_embedding`
- the phi4mm input-mode warning in `hf_ptq.py`
- `modelopt_recipes/huggingface/phi4mm/` and its references in
`modelopt_recipes/ptq.md`
**Not changed:** the device-map sizing path (meta-device skeleton,
`infer_auto_device_map`, and the `--gpu_max_mem_percentage` cap) keeps
its
original behavior. That cap is wanted exactly where it already fires —
when the
model is already offloading to CPU, where it costs little and the
headroom is
required. With the affected checkpoints removed, there is no supported
model
that trips the meta-device build, so there is nothing to work around
here.
Text-only **Phi-3/Phi-4** and **Phi-3.5-MoE** are natively supported by
transformers and are untouched.
### Testing
On H200, `nvcr.io/nvidia/tensorrt-llm/release` (torch 2.12, transformers
5.5.4),
against the real checkpoint:
- **Version matrix** (vanilla transformers, no modelopt) — Phi-4-MM
loads at
4.48.2 / 4.49.0 / 4.50.0 / 4.51.3 and fails at 4.53.3 / 4.56.2 / 4.57.1
(`AttributeError: 'Phi4MMModel' object has no attribute
'prepare_inputs_for_generation'`) and at 5.5.4 (meta-init, then
tied-keys).
This is what establishes that no supported version works.
- `tests/examples/hf_ptq/test_example_utils.py` — 28 passed.
- **Sweep**: `tests/examples/hf_ptq` + `tests/unit/torch/export` —
failure set
identical to the pre-change tree (GPU/model-dependent `test_vlm_ptq`,
plus
`test_quant_aware_conversion` scoped-mapping tests), so none are
introduced
here.
- `pre-commit` clean on all changed files, including recipe validation.
### Before your PR is "*Ready for review*"
- Is this change backward compatible?: ❌ — PTQ for Phi-3-vision and
Phi-4-multimodal is removed, along with the `huggingface/phi4mm/ptq/*`
recipes. Phi-4-multimodal is already unloadable on every supported
transformers
version, so no working workflow regresses; Phi-3-vision is a deliberate
scope
removal as its superseded predecessor.
- If you copied code from any other sources or added a new PIP
dependency, did you follow guidance in `CONTRIBUTING.md`: N/A
- Did you write any new necessary tests?: N/A — this is a deletion; the
existing
`test_get_model_*` / `test_resolve_init_config_*` tests are unchanged
and still
pass.
- Did you update
[Changelog](https://github.com/NVIDIA/Model-Optimizer/blob/main/CHANGELOG.rst)?:
✅
- Did you get Claude approval on this PR?: ❌ — not yet run.
### Additional Information
Two related references were left in place deliberately; say the word and
I'll
fold them in:
- `tests/examples/hf_ptq/test_deploy.py` still deploys the
already-published
`nvidia/Phi-4-multimodal-instruct-{NVFP4,FP8}` checkpoints. Those
artifacts
exist and serve fine; this PR only removes the ability to *produce*
them.
- `examples/torch_onnx/README.md` still lists Phi-4-multimodal-instruct.
That
is a separate ONNX pipeline that does not go through `get_model()` and
was not
tested here.
Earlier revisions of this branch also reworked the device-map sizing so
the
meta-tensor crash could not occur. That was reverted in
|
||
|
Chenjie LuoandClaude Opus 5
|
9b8caf623a |
Use lm-eval 0.4.12's built-in trtllm backend, deprecate lm_eval_tensorrt_llm.py (#2066)
### What does this PR do?

Type of change: documentation / example update (with a behaviour fix)

lm-evaluation-harness **0.4.12** is the first release that ships a
TensorRT-LLM backend
(`lm_eval.models.trtllm_causallms`, registered as `trtllm`) — it is
absent in 0.4.10 and
0.4.11. This example no longer maintains its own, so:

- Pin `lm_eval[api,ifeval]>=0.4.12,<0.5` (the 0.5.0.dev line drops the
file) and bump
  `lm_eval_hf.py`'s version guard to match.
- **Delete** `examples/llm_eval/lm_eval_tensorrt_llm.py` (the `trt-llm`
model). Replace
`python lm_eval_tensorrt_llm.py --model trt-llm --model_args
tokenizer=<tok>,checkpoint_dir=<ckpt>`
with `python lm_eval_trtllm.py --model trtllm --model_args
model=<ckpt>,tokenizer=<tok>`.
- Add `examples/llm_eval/lm_eval_trtllm.py`, whose entire content is one
corrected
`_parse_logprobs` plus `cli_evaluate()` (see below). `lm_eval_hf.py`
stays HF-only.
- `examples/hf_ptq/scripts/huggingface_example.sh` and the docs use the
upstream backend.
`parser.sh` gains `--input` (`BUILD_MAX_INPUT_LEN`, default 4096) — it
already *echoed*
that variable but never parsed or defaulted it, so it printed empty on
every run.

#### Why `lm_eval_trtllm.py` exists: an upstream off-by-one

TensorRT-LLM aligns `prompt_logprobs` to the *next* token.
`executor/base_worker.py`:

```python
# Pass prompt_token_ids with an offset of 1 for correct mapping to the context logits
prompt_token_ids = generation_result._generation_request.prompt_token_ids[1:] + first_generation_token
```

So entry `i` is the distribution that predicted `tokens[i + 1]`, and
`_topk_logprobs`
appends that token's id when it is not in the top-k. lm-eval's
`_parse_logprobs` instead
reads `prompt_logprobs[i][tokens[i]]` and applies its own shift on top,
which raises
`KeyError` on the **first request of every loglikelihood task**
(hellaswag, mmlu, arc, ...):

```
File ".../lm_eval/models/trtllm_causallms.py", line 324, in _parse_logprobs
    current_token_logprob = prompt_logprob[tokens[i]]
KeyError: 6503
```

Probed against TRT-LLM 1.3.0rc23 with a 14-token prompt for
`prompt_logprobs` 0, 1 and 2:
`tokens[i]` is missing at **every** position, `tokens[i+1]` is present
at every position.
Only `generate_until` tasks work unpatched. **This wants an upstream
issue against
EleutherAI/lm-evaluation-harness.**

The override also fails loudly rather than quietly: it checks
`prompt_logprobs` covers
every prompt token and raises on a missing token, instead of skipping
the term and
silently inflating the reported accuracy.

#### Defaults that must be set explicitly

`TRTLLM.__init__` accepts `**kwargs` but forwards only a fixed set to
the **TensorRT-LLM
`LLM` API**, so extra `--model_args` aimed at the engine are silently
dropped. (lm-eval's
own named parameters — `max_gen_toks`, `batch_size`, `truncation_side`,
... — are honored
normally.) Two engine defaults are unsafe for few-shot eval:

- `tensor_parallel_size` defaults to **1** (the deleted wrapper used
every visible GPU).
- `max_input_len` defaults to **2048**, and longer prompts are silently
left-truncated —
  5-shot MMLU/gsm8k prompts exceed that.

### Usage

```bash
python lm_eval_trtllm.py --model trtllm \
    --model_args model=<quantized checkpoint dir>,tokenizer=<HF model folder>,tensor_parallel_size=<tp>,max_batch_size=<bs>,max_input_len=4096,max_output_len=512 \
    --tasks hellaswag,gsm8k \
    --batch_size <bs>
```

Flat arguments (no `run` subcommand) are what 0.4.12's
`HarnessCLI.parse_args` inserts
`run` for automatically (`_cli/harness.py:48-51`); this is the exact
command form used for
the results below.

### Testing

**Unit** — `tests/examples/llm_eval/test_lm_eval_trtllm.py`, no GPU and
no `tensorrt_llm`
install: stubs the response object and pins the `i-1` alignment, the
`rank != 1` →
`is_greedy` rule, the `ctxlen=0` edge, and both `RuntimeError` paths.
Mutation-checked —
dropping the `-1` shift is caught by 5/5 cases, ignoring `ctxlen` by
4/5. A sixth test is a
**tripwire**: it asserts lm-eval's own implementation is still
misaligned, so a future
0.4.x that fixes the bug fails the test and says to delete this file
rather than being
silently re-broken by the override.

**End to end** — `nvidia/Qwen3.5-122B-A10B-NVFP4` (NVFP4 MoE, 256
experts) on **4x B300**,
TRT-LLM 1.3.0rc23, lm-eval 0.4.12, `--limit 32`:

| run | hellaswag acc | hellaswag acc_norm | gsm8k flexible | gsm8k
strict |
|---|---|---|---|---|
| deleted impl (`trt-llm`), tp=4 | 0.7188 | 0.7812 | 0.8438 | 0.7812 |
| `lm_eval_trtllm.py`, tp=1 | 0.7188 | 0.7812 | 0.8438 | 0.8125 |
| `lm_eval_trtllm.py`, tp=2 | 0.7188 | 0.7812 | 0.9062 | 0.8125 |
| `lm_eval_trtllm.py`, tp=4 | 0.7188 | 0.7812 | 0.8750 | 0.8438 |

- hellaswag (the loglikelihood path this PR fixes) is **identical at
every tp and identical
to the deleted implementation** — the alignment fix is exact, not
approximate.
- gsm8k varies by 1–2 samples out of 32 (generation path: upstream uses
native `stop=`
sequences and per-request `SamplingParams`; the old wrapper used
beam-search-of-1 with
  post-hoc string truncation).
- Without the override, every hellaswag run above dies with the
`KeyError`.
- Re-verified at tp=4 after the code moved out of `lm_eval_hf.py` into
`lm_eval_trtllm.py`.

Note: NVFP4 fused-MoE has no CUTLASS tactic on Hopper (`No supported MoE
GEMM tactic
remains after replacing unsupported NO_SMEM epilogues.`), so this had to
be validated on
Blackwell.

### Feature parity notes

Gained from upstream: `loglikelihood_rolling` (was
`NotImplementedError`), pipeline
parallelism, `add_bos_token` auto-detection, prompt truncation,
per-request sampling params,
`prompt_logprobs` instead of full-vocab context logits (much lower
memory), thinking-tag
handling, `batch_size=auto`.

Not reachable through the upstream backend (were set by
`modelopt.deploy.llm.LLM`):
`enable_attention_dp` for MoE, `CudaGraphConfig`,
`enable_chunked_prefill`,
`moe_expert_parallel_size=1`, and `free_gpu_memory_fraction=0.7` with a
capped
`kv_cache.max_tokens` — upstream uses the TRT-LLM default 0.9 (observed
allocating 218 GiB
of paged KV cache on B300), so OOM risk is higher on smaller GPUs. This
is documented in
`examples/llm_eval/README.md`, and `huggingface_example.sh` honours a
preset `LM_EVAL_TP`
so users can lower the tensor-parallel size without editing the script.

### Before your PR is "*Ready for review*"

- Is this change backward compatible?: ❌ — `lm_eval_tensorrt_llm.py` is
removed and the CLI changes (`--model trt-llm` → `trtllm`,
`checkpoint_dir=` → `model=`). Migration command is in the README and
CHANGELOG.
- If you copied code from any other sources or added a new PIP
dependency, did you follow guidance in `CONTRIBUTING.md`: ✅ — no new
dependency; existing `lm_eval` pin tightened.
- Did you write any new necessary tests?: ✅ —
`tests/examples/llm_eval/test_lm_eval_trtllm.py` (6 cases, no GPU).
- Did you update
[Changelog](https://github.com/NVIDIA/Model-Optimizer/blob/main/CHANGELOG.rst)?:
✅ — under 0.47 *Deprecations*.
- Did you get Claude approval on this PR?: ✅ — reviewed, feedback
addressed in `dcedd37b4` and `622b97c26`.

🤖 Generated with [Claude Code](https://claude.com/claude-code)


<!-- This is an auto-generated comment: release notes by coderabbit.ai
-->
## Summary by CodeRabbit

* **New Features**
* Added TensorRT-LLM evaluation through lm-evaluation-harness’s `trtllm`
backend.
* Added configurable input/output lengths, batching, tensor parallelism,
and build input length.
* Improved prompt log-probability alignment for more accurate evaluation
results.

* **Documentation**
* Updated evaluation instructions, truncation guidance, backend
limitations, and configuration examples.

* **Deprecations**
  * Removed the legacy TensorRT-LLM evaluation script and entry point.

* **Updates**
  * lm-evaluation-harness now requires versions 0.4.12 through 0.4.x.
<!-- end of auto-generated comment: release notes by coderabbit.ai -->

---------

Signed-off-by: Chenjie Luo <chenjiel@nvidia.com>
Co-authored-by: Claude Opus 5 (1M context) <noreply@anthropic.com>
|
||
|
kinjalpatel27
|
bd3798a794 |
[6562078]: fix calibration for vLLM 0.26.0 (#2093)
### What does this PR do? Type of change: Bug fix Fixes calibration failures when running fake-quantization with vLLM 0.26.0. Two root causes are addressed: 1. **`finish_requests` must be called explicitly after `add_requests`.** In vLLM 0.26.0 the scheduler calls `finish_requests` *before* `add_requests` inside `execute_model`, so request IDs are not registered yet and cleanup never runs. The calibration loop now calls `finish_requests` directly after each batch using `dataclasses.replace`. Wrapped in `try/finally` with an inner `try/except` so it always runs and never masks the original exception. A warning is emitted when `finish_requests` is absent so the regression is self-diagnosing on future vLLM API changes. 2. **`NewRequestData` gained a `prefill_token_ids` field.** vLLM 0.26.0 added this required argument; the calibration helper now passes it. Additional: - Dockerfile updated to vLLM 0.26.0 with `USER vllm` (non-root). - README updated to include vLLM 0.26.0 in tested versions. ### Usage ```bash cd examples/vllm_serve QUANT_CFG=FP8_DEFAULT_CFG QUANT_CALIB_SIZE=8 CALIB_BATCH_SIZE=1 \ python3 vllm_serve_fakequant.py Qwen/Qwen1.5-MoE-A2.7B-Chat -tp 1 \ --host 0.0.0.0 --port 8000 ``` ### Testing Tested end-to-end FQ calibration with vLLM 0.26.0 using the Docker image built from `examples/vllm_serve/Dockerfile`. ### Before your PR is "*Ready for review*" - Is this change backward compatible?: ✅ - If you copied code from any other sources or added a new PIP dependency, did you follow guidance in `CONTRIBUTING.md`: N/A - Did you write any new necessary tests?: N/A (examples change only) - Did you update [Changelog](https://github.com/NVIDIA/Model-Optimizer/blob/main/CHANGELOG.rst)?: N/A - Did you get Claude approval on this PR?: N/A ### Additional Information Changes are confined to `examples/vllm_serve/` and do not affect the core library. <!-- This is an auto-generated comment: release notes by coderabbit.ai --> ## Summary by CodeRabbit ## Summary by CodeRabbit * **New Features** * Added compatibility with vLLM 0.26.0 in the serving example. * Improved calibration request handling and cleanup after model execution. * Enabled the serving container to run with a non-root user. * **Bug Fixes** * Calibration cleanup failures no longer obscure the original model execution error. * Added warnings when calibration cleanup cannot be completed. * **Documentation** * Updated the serving example documentation to list vLLM 0.26.0 among tested versions. <!-- end of auto-generated comment: release notes by coderabbit.ai --> --------- Signed-off-by: Kinjal Patel <kinjalpravin@nvidia.com> |
||
|
Ajinkya RasaneandCodex
|
ccf44ea67a |
[OMNIML-5562] Add FAR3D ONNX PTQ and accuracy evaluation example (#2012)
### What does this PR do? Type of change: new example Adds an end-to-end FAR3D ONNX PTQ example under `examples/onnx_ptq/far3d`. The example prepares Argoverse 2 validation metadata and calibration batches, quantizes the image encoder to INT8, builds TensorRT engines, and evaluates 3D object detection accuracy. It also provides a reproducible FAR3D runtime image, preserves accuracy-sensitive encoder layers in high precision, and supports temporal decoder state during evaluation. ### Usage ```bash python prepare_metadata.py /path/to/av2 python prepare_calibration.py /path/to/far3d.py far3d_calibration python quantize.py far3d.encoder.onnx far3d_calibration python evaluate.py /path/to/far3d.py \ far3d.encoder.int8.engine far3d.decoder.fp16.engine ``` ### Testing - Ran all configured pre-commit hooks on the changed files. - Ran synthetic calibration-reader and graph-exclusion tests. - Built the documented FAR3D runtime image and verified TensorRT 10.11, Argoverse 2 imports, and TensorRT engine execution. - Ran the complete workflow on the Argoverse 2 validation split using 500 calibration batches and 23,522 evaluation frames. The INT8 encoder and FP16 decoder produced 0.238 mAP. ### Before your PR is "*Ready for review*" Make sure you read and follow [Contributor guidelines](https://github.com/NVIDIA/Model-Optimizer/blob/main/CONTRIBUTING.md) and your commits are signed (`git commit -s -S`). Make sure you read and follow the [Security Best Practices](https://github.com/NVIDIA/Model-Optimizer/blob/main/SECURITY.md#security-coding-practices-for-contributors) (e.g. avoiding hardcoded `trust_remote_code=True`, `torch.load(..., weights_only=False)`, `pickle`, etc.). - Is this change backward compatible?: ✅ - If you copied code from any other sources or added a new PIP dependency, did you follow guidance in `CONTRIBUTING.md`: ✅ - Did you write any new necessary tests?: N/A - Did you update [Changelog](https://github.com/NVIDIA/Model-Optimizer/blob/main/CHANGELOG.rst)?: N/A ### Additional Information - [NVIDIA DL4AGX FAR3D TensorRT reference](https://github.com/NVIDIA/DL4AGX/tree/master/AV-Solutions/far3d-trt) > 🤖 _Generated by Codex (AI agent)._ <!-- This is an auto-generated comment: release notes by coderabbit.ai --> ## Summary by CodeRabbit * **New Features** * Added an end-to-end FAR3D ONNX post-training quantization workflow for Argoverse 2, including calibration batch generation, INT8/FP8 quantization, TensorRT engine inference, and mAP evaluation. * Added a dedicated FAR3D example Docker environment plus detailed README instructions. * Added FAR3D evaluation, calibration preparation, metadata preparation, and quantization scripts. * **Bug Fixes** * Improved handling when flash-attention is unavailable, with clearer error messaging. * **Chores** * Updated pre-commit exclusions and refreshed third-party license attribution. * Added an Experimental changelog entry for the FAR3D example. <!-- end of auto-generated comment: release notes by coderabbit.ai --> --------- Signed-off-by: ajrasane <131806219+ajrasane@users.noreply.github.com> Co-authored-by: Codex <codex@openai.com> |
||
|
Keval MorabiaandClaude Opus 5
|
22b6a148b0 |
Fix EAGLE-3 context-parallel training and re-enable its tests (#2086)
### What does this PR do?

Type of change: Bug fix

**EAGLE-3 context-parallel training (`--cp_size > 1`) is fixed, and its
tests run again.** CP has been broken since `accelerate` 1.13, and the
tests never caught it: the guard compared `Version("2.10.0a0")` against
`Version("2.10.0")`, which is False on every NGC alpha torch build, so
`test_llama_eagle3[cp_size=2]` has never actually run in CI.

Five fixes:

- **`main.py`** — rebuild the FSDP2 plugin accelerate requires for
`cp_size > 1`. The `--fsdp full_shard --fsdp_config` launcher flags that
used to supply it were dropped from `launch_train.sh`, so CP could not
start at all. Also pass the CP degree to the draft model.
- **`modeling_eagle.py`** — apply the draft model's first input norm
inside `layers[0]`'s own forward, where FSDP2 has actually unsharded its
weights, and only stash the input embeds on the path whose pre-hook
consumes them.
- **`hf_eagle.py`** — skip the dense eagle attention mask under CP
(causal masking comes from `is_causal`, TTT masking from the
ring-attention patch), and warn that padded positions are therefore
unmasked. Also stop `(eagle_loss or 0)` replacing a `0.0` loss tensor
with a plain `int`, which detached the graph.
- **`eagle_utils.py`** — key TTT-mask injection off the backward call's
`grad_out` kwarg, since newer torch omits `attn_bias` on the forward
call, silently disabling TTT masking.
- **`utils.py`** — CUDNN-only SDPA under CP; the `MATH` backend
decomposes SDPA and breaks on DTensors. Scoped to `cp_size > 1`, since
this context manager wraps every training forward and CPU has no cudnn
backend.

**Drops the `speculative_decoding` 26.01 container override.** It was
added when the lane ran 25.06 and spec-dec needed something *newer* — a
floor. Later bumps moved the default past it, so it had silently become
a ceiling holding spec-dec on a 6-month-old image.

### Testing

Ran `tests/examples/speculative_decoding` in
`nvcr.io/nvidia/pytorch:26.07-py3` on 2 GPUs, reproducing the CI install
steps (`pip uninstall -y nvidia-modelopt`, `pip install -e
".[hf,dev-test]"`, example requirements): **16 passed, 2 skipped** — the
2 skipped being pre-existing `--run-manual` tests. All four
`test_llama_eagle3` cases pass, including both `cp_size=2` ones.

### Before your PR is "*Ready for review*"

- Is this change backward compatible?: ✅
- If you copied code from any other sources or added a new PIP
dependency, did you follow guidance in `CONTRIBUTING.md`: N/A
- Did you write any new necessary tests?: N/A — the existing `cp_size=2`
tests are re-enabled
- Did you update
[Changelog](https://github.com/NVIDIA/Model-Optimizer/blob/main/CHANGELOG.rst)?:
✅
- Did you get Claude approval on this PR?: ❌ — not yet run

Signed-off-by: Keval Morabia <28916987+kevalmorabia97@users.noreply.github.com>
Co-authored-by: Claude Opus 5 <noreply@anthropic.com>
|
||
|
Frida HouandClaude Sonnet 4.6
|
6a8102591e |
Single gpu disk offload PTQ for DSR1/Ultra (#2008)
### What does this PR do? Type of change: New feature, bug fix, new tests Enables single-GPU PTQ for models too large to fit in VRAM (e.g. Nemotron-Ultra-550B at 1.1 TB BF16, DeepSeek-R1 at 642 GB BF16) by adding accelerate disk/CPU offload support to the HF PTQ example and fixing the export path to correctly handle offloaded models. **G1 Offload-aware unified HF export (`modelopt/torch/export/unified_export_hf.py`)** The existing `_export_transformers_checkpoint` removed accelerate hooks before materializing weights, silently writing meta tensors (empty weights) to the checkpoint. Fix: - `_has_accelerate_offload(model)`detects any disk/CPU-offload accelerate hook in the model tree. - `_process_quantized_modules_offloaded(model, dtype)` new export path for offloaded models: materializes one decoder layer at a time via `enable_weight_access_and_writeback`, dispatches export handlers inside the context window, and snapshots the layer state dict before hooks re-offload the weights. A second pass collects non-decoder modules that are also disk-offloaded (embed, norm, lm_head) to avoid meta tensors in the returned state dict. Hooks are removed only after the full state dict is assembled. - Meta-tensor guard in `_export_quantized_weight` raises `RuntimeError` on meta input instead of silently corrupting the checkpoint. **G2 Disk-offload CLI (`examples/hf_ptq/hf_ptq.py`, `example_utils.py`)** Three new arguments to `hf_ptq.py`: - `--offload_folder PATH` enable accelerate disk offload; shards spill here. - `--max_gpu_memory_gb N` VRAM budget for the accelerate device map. - `--max_cpu_memory_gb N` CPU RAM budget for the accelerate device map. Validation: `--offload_folder` is incompatible with `--low_memory_mode` and `--use_seq_device_map`. **G3 Streaming shard writer for 80 GB CPU RAM (`modelopt/torch/export/unified_export_hf.py`)** The G1 path accumulated the entire quantized state dict in CPU RAM before writing (~764 GiB for Ultra 550B), blocking the 80 GB target. New streaming path writes shard files layer-by-layer. Peak memory = 1 decoder layer + 1 shard buffer instead of the full checkpoint: | Model | Old peak CPU RAM | New peak CPU RAM | |-------|-----------------|-----------------| | Ultra NemotronH 550B | ~764 GiB | ~57 GB | | DeepSeek-R1 | ~630 GiB | ~55 GB | Key pieces: - `_StreamingShardWriter(export_dir, max_shard_size)` buffers tensors up to `max_shard_size` bytes, flushes to numbered temp files (`__shard_part_NNNNN.safetensors`), renames to canonical shard names at `finalize()`, writes `model.safetensors.index.json`. Single-shard exports produce `model.safetensors` with no index file. - `_postprocess_single_tensor(key, value, ...)` per-tensor extraction of `postprocess_state_dict` logic (KV amax scale, skip/rename, squeeze) for streaming use. - `_parse_shard_size(size)` converts `"10GB"` / `"500MB"` strings to bytes. - `_export_transformers_checkpoint_streaming(model, dtype, export_dir, max_shard_size)` streams decoder layers via `enable_weight_access_and_writeback`, applies per-tensor postprocessing + name reversal + tied-alias filter, writes shard files directly. Non-decoder offloaded modules and GPU-resident tensors are handled in separate passes. - `export_hf_checkpoint` dispatches to the streaming path when `_has_accelerate_offload(model)` is true; `hf_quant_config.json`, quant-config name reversal, and `config.json` update are shared between paths. `export_hf_checkpoint` accepts a new `max_shard_size` parameter (default `"10GB"`) that controls the shard size for both paths. **Supporting changes** - `modelopt/torch/quantization/plugins/huggingface.py` `get_nemotron_h_decoder_layers` now checks both `model.backbone.layers` (remote-code variant) and `model.model.layers` (native HF variant), fixing layer discovery for NemotronH when loaded without `trust_remote_code`. - `modelopt_recipes/general/ptq/nvfp4_experts_only-kv_fp8_layerwise_offload.yaml` new recipe combining NVFP4 W4A4 on MoE experts, FP8 KV cache, and layerwise calibration with `calib_mutates_weights: false` (required for disk-offload compatibility). - `example_utils.py` `_FP8BF16Fallback` shim: dequantizes block-scaled FP8 expert weights to BF16 for calibration forward passes when the `kernels` package is unavailable (e.g. DSR1 on nodes without finegrained FP8 kernel support). ### Usage ```python # Single-GPU PTQ for a model too large to fit in VRAM, using disk offload python examples/hf_ptq/hf_ptq.py \ --pyt_ckpt_path /path/to/NVIDIA-Nemotron-3-Ultra-550B-A55B-BF16 \ --recipe general/ptq/nvfp4_experts_only-kv_fp8_layerwise_offload \ --export_path /path/to/output \ --offload_folder /path/to/offload \ --max_gpu_memory_gb 170 \ --max_cpu_memory_gb 500 \ --trust_remote_code \ --calib_size 8 --batch_size 1 --skip_generate ``` ### Testing **Unit tests** (`tests/unit/torch/export/test_offload_export.py`, 7 tests, CPU-only): - `_has_accelerate_offload` detection (true/false/nested-module cases) - `_export_quantized_weight` meta-tensor guard (raises on meta, passes on real) - `_process_quantized_modules_offloaded` with disk-offloaded embed + GPU-resident decoder layer: verifies no meta tensor in returned state dict **GPU integration tests** (`tests/gpu/torch/export/test_offload_export.py`, 2 tests): - Tiny 2-layer LLaMA with CPU offload: FP8 quantization + export, asserts no meta tensors and valid `hf_quant_config.json` - Same with layerwise FP8 (`calib_mutates_weights=False`): disk-offload path end-to-end ## End-to-end validation Verified with DSR1 that the non-layerwise path provide identical checkpoint before and after this change, also the layerwise with cpu off-load path produce same identical checkpoint (with same max calibration setting). Two production-scale checkpoints were quantized end-to-end using the new disk-offload PTQ path on a single GB200 GPU (189 GiB VRAM). ### DeepSeek-R1 (671B, MoE) | | | |---|---| | **Checkpoint** | `DeepseekV3ForCausalLM`, 671B params, 61 decoder layers | | **Input size** | 642 GB BF16 | | **Recipe** | `nvfp4_experts_only-kv_fp8_layerwise_offload` | | **`--max_gpu_memory_gb`** | 80 | | **`--max_cpu_memory_gb`** | 80 | | **`--calib_size` / `--batch_size`** | 8 / 1 | | **`--trust_remote_code`** | no (built-in transformers) | | **Wall-clock** | 40 min 12 s (load ~14 min, calib ~12 min, export ~14 min) | | **Peak GPU memory** | 88.9 GB | | **Peak process RSS** | 376 GB | | **Output** | 40 shards x ~10 GB = 403 GB (~37% compression) | <img width="1783" height="2532" alt="image" src="https://github.com/user-attachments/assets/fe515035-c880-453f-af1c-2d98395c9197" /> ### NVIDIA-Nemotron-3-Ultra-550B-A55B-BF16 (550B, NemotronH MoE + Mamba) | | | |---|---| | **Checkpoint** | `NemotronHForCausalLM`, ~550B params, 108 decoder layers | | **Input size** | ~1.1 TB BF16 | | **Recipe** | `nvfp4_experts_only-kv_fp8_layerwise_offload` | | **`--max_gpu_memory_gb` / `--max_cpu_memory_gb`** | 170 / 500 and **80 / 80** | | **`--calib_size` / `--batch_size`** | 8 / 1 | | **`--trust_remote_code`** | yes (`NemotronHForCausalLM`) | | | 170 GB GPU / 500 GB CPU | **80 GB GPU / 80 GB CPU** | |---|---|---| | **Wall-clock** | 41 min 13 s | **47 min 16 s** | | **Peak GPU memory** | 165.8 GB | **76.7 GB** | | **Peak RSS (load)** | 789 GB transient | **345 GB transient** | | **Steady-state RSS** | ~454-496 GB | **~50 GB** | | **Output** | 34 shards x ~11 GB = 365 GB | 34 shards x ~11 GB = 365 GB | <img width="1783" height="2532" alt="image" src="https://github.com/user-attachments/assets/da4771b8-b522-4549-8e40-7f975bd6f9b1" /> ### Before your PR is "*Ready for review*" Make sure you read and follow [Contributor guidelines](https://github.com/NVIDIA/Model-Optimizer/blob/main/CONTRIBUTING.md) and your commits are signed (`git commit -s -S`). Make sure you read and follow the [Security Best Practices](https://github.com/NVIDIA/Model-Optimizer/blob/main/SECURITY.md#security-coding-practices-for-contributors) (e.g. avoiding hardcoded `trust_remote_code=True`, `torch.load(..., weights_only=False)`, `pickle`, etc.). - Is this change backward compatible?: ✅ - If you copied code from any other sources or added a new PIP dependency, did you follow guidance in `CONTRIBUTING.md`: ✅ - Did you write any new necessary tests?: ✅ - Did you update [Changelog](https://github.com/NVIDIA/Model-Optimizer/blob/main/CHANGELOG.rst)?: ✅ / ❌ / N/A <!--- Only for new features, API changes, critical bug fixes or backward incompatible changes. --> - Did you get Claude approval on this PR?: ✅ / ❌ / N/A <!--- Run `/claude review`. NVIDIA org members can self-trigger for complex changes; orthogonal to CodeRabbit. --> ### Additional Information <!-- E.g. related issue. --> <!-- This is an auto-generated comment: release notes by coderabbit.ai --> ## Summary by CodeRabbit * **New Features** * Added disk/CPU/GPU memory-limited offload model loading. * Added offload-aware streaming Hugging Face checkpoint export with sharded output. * Added an NVFP4 expert-only PTQ recipe with FP8 KV-cache support. * Improved Nemotron-H model layout support. * **Bug Fixes** * Improved DeepSeek bundled-code selection based on remote-code trust. * Strengthened handling of meta/offloaded weights, tied-weight deduplication, and export post-processing. * **Tests** * Added coverage for offload exports and DeepSeek loading behavior. <!-- end of auto-generated comment: release notes by coderabbit.ai --> --------- Signed-off-by: Fridah-nv <fridah@nvidia.com> Signed-off-by: Fridah-nv <201670829+Fridah-nv@users.noreply.github.com> Co-authored-by: Claude Sonnet 4.6 <noreply@anthropic.com> |
||
|
realAsma
|
fed1980b29 |
Pin Accelerate below 1.14 for llm_qat (#2067)
### What does this PR do? Type of change: Bug fix Pins Accelerate below 1.14 for the `llm_qat` example. Accelerate 1.14 introduced an FSDP2 regression for models whose input embeddings and output head share a parameter; the shared weight can be assigned to two FSDP groups and training fails before the first step. The pin is example-local. The project-wide Hugging Face dependency range and unrelated examples remain unchanged. ### Usage No usage change. Installing the `llm_qat` requirements now resolves Accelerate to the existing supported range below 1.14. ### Testing - Reproduced the duplicate shared-parameter FSDP2 failure with Accelerate 1.14.0 on two ranks. - Verified Accelerate 1.13.0 completes a distillation training step with the otherwise-identical environment and a clean `main` source tree. - Verified the combined requirements resolve to `accelerate>=1.0.0,<1.14` and select 1.13.0. - `pre-commit run --files examples/llm_qat/requirements.txt` - `git diff --check` ### Before your PR is "*Ready for review*" Make sure you read and follow [Contributor guidelines](https://github.com/NVIDIA/Model-Optimizer/blob/main/CONTRIBUTING.md) and your commits are signed (`git commit -s -S`). Make sure you read and follow the [Security Best Practices](https://github.com/NVIDIA/Model-Optimizer/blob/main/SECURITY.md#security-coding-practices-for-contributors). - Is this change backward compatible?: ✅ - If you copied code from any other sources or added a new PIP dependency, did you follow guidance in `CONTRIBUTING.md`: N/A - Did you write any new necessary tests?: N/A — dependency-only change validated by an exact two-rank A/B run. - Did you update [Changelog](https://github.com/NVIDIA/Model-Optimizer/blob/main/CHANGELOG.rst)?: N/A - Did you get Claude approval on this PR?: ❌ — draft PR; automated review is pending. ### Additional Information This is a scoped compatibility pin while the upstream Accelerate regression remains unresolved. <!-- This is an auto-generated comment: release notes by coderabbit.ai --> ## Summary by CodeRabbit * **Chores** * Constrained the Accelerate dependency to versions below 1.14 to improve compatibility for the LLM question-answering example. <!-- end of auto-generated comment: release notes by coderabbit.ai --> --------- Signed-off-by: realAsma <akuriparambi@nvidia.com> |
||
|
|
2d4be28818 |
fix(hf_ptq): use no_grad instead of inference_mode in export_quantized (NVBug 6537702) (#2047)
### What does this PR do? Type of change: Bug fix Fixes [NVBug 6537702](https://nvbugspro.nvidia.com/bug/6537702) / [OMNIML-5658](https://jirasw.nvidia.com/browse/OMNIML-5658) — multi-node FSDP2 PTQ export fails on all ranks: ``` hf_ptq.py:910 export_quantized -> export_hf_checkpoint unified_export_hf.py:1446 _export_transformers_checkpoint -> get_model_state_dict modelopt/torch/opt/_hooks.py:88 _get_model_state_dict_with_dm_check torch/distributed/checkpoint/state_dict.py:481 _get_model_state_dict torch/nn/modules/module.py:2160 _save_to_state_dict destination[prefix + name] = param if keep_vars else param.detach() RuntimeError: Cannot set version_counter for inference tensor ``` **Root cause.** `export_quantized` wrapped its whole body in `torch.inference_mode()`. On the FSDP2 path (`--use_fsdp2`), `get_model_state_dict(full_state_dict=True)` gathers the full params *inside* that context, so the gathered tensors are inference tensors. Inference tensors have no version counter, so the subsequent `state_dict()` → `param.detach()` raises. **Fix.** Use `torch.no_grad()` for the export context. It still disables autograd, but the gathered params stay normal tensors with an intact version counter, so `detach()` works. FSDP2-only failure — the non-FSDP2 path never hit it because its params already exist outside the context. The one-line fix is originally by @shengliangx (`b0e4328` on `shengliangx/distributed-unified`); this PR retargets it to the post-rename `examples/hf_ptq/` path and adds a changelog entry and a regression guard. ### Usage ```bash # 2 nodes x 8 GB200, previously failed at export on every rank torchrun --nnodes=2 --node_rank=0 --master_addr=$MASTER --master_port=6000 --nproc_per_node=8 \ hf_ptq.py --model Llama-3.1-8B-Instruct --dataset cnn_dailymail \ --recipe general/ptq/fp8_default-kv_fp8 --batch_size 8 --calib_size 512 \ --export_path ./Llama-3.1-8B-Instruct-fp8_default-kv_fp8 --use_fsdp2 ``` ### Testing - End-to-end on 2 nodes by @shengliangx on the original branch: dense Qwen3-8B and Qwen3-30B-A3B (MoE) FSDP2 PTQ fp8 checkpoints export successfully. - Added `tests/examples/hf_ptq/test_export_quantized_context.py`, a CPU-only guard asserting `export_quantized` enters `torch.no_grad()` and not `torch.inference_mode()`. A functional regression test would need a 2-node FSDP2 job, which CI does not run, so this encodes the invariant instead. - `pre-commit run --files` clean on all three changed files. Reporter (Kenny Kang, GPU SWQA) still needs to confirm on the original 2x8 GB200 Llama-3.1-8B repro. ### Before your PR is "*Ready for review*" - Is this change backward compatible?: ✅ - If you copied code from any other sources or added a new PIP dependency, did you follow guidance in `CONTRIBUTING.md`: N/A - Did you write any new necessary tests?: ✅ - Did you update [Changelog](https://github.com/NVIDIA/Model-Optimizer/blob/main/CHANGELOG.rst)?: ✅ - Did you get Claude approval on this PR?: ❌ ### Additional Information Keyword `Committed_ModelOpt_0.46.0` on the bug — should land for 0.46. 🤖 Generated with [Claude Code](https://claude.com/claude-code) <!-- This is an auto-generated comment: release notes by coderabbit.ai --> ## Summary by CodeRabbit * **Bug Fixes** * Fixed multi-node quantized model exports to prevent runtime errors when gathering and detaching parameters. * Improved compatibility with FSDP2 during Hugging Face PTQ exports. * **Tests** * Added coverage to verify the export process uses the compatible gradient context. <!-- end of auto-generated comment: release notes by coderabbit.ai --> Signed-off-by: Zhiyu Cheng <zhiyuc@nvidia.com> Co-authored-by: Shengliang Xu <shengliangx@nvidia.com> Co-authored-by: Claude Opus 5 (1M context) <noreply@anthropic.com> |
||
|
Keval Morabia
|
5dde396bdf |
Fix vLLM 0.24+ compatibility: registry TypeError and MoE RoutedExperts port (#2054)
### What does this PR do? Type of change: Bug fix vLLM 0.24 (as shipped in `nemo:26.08`) reworked the fused-MoE layer, which broke ModelOpt in two ways: 1. **`FusedMoE` became a factory function** returning a `MoERunner` pipeline. Registering it put a plain function into `QuantModuleRegistry`, so *every* later registry lookup raised `TypeError: issubclass() arg 2 must be a class, ...` — taking down large parts of `tests/gpu_megatron` (TE, Megatron chaining, MSE calibrator) that have nothing to do with vLLM. 2. **Expert weights moved onto a `RoutedExperts` submodule** of `MoERunner`, and `UnquantizedFusedMoEMethod` moved modules, so the MoE fakequant path had no valid registration target. Changes: - `_DMRegistryCls.register` now asserts keys are `nn.Module` subclasses, so a future upstream change fails at the registration site instead of as a confusing `TypeError` at lookup. - Register `RoutedExperts` (vLLM >= 0.24) while keeping the `FusedMoE` / `SharedFusedMoE` registrations for older releases; both go through the same `_QuantFusedMoEBase`. `MoERunner` calls `forward_modular` / `forward_monolithic` directly (`RoutedExperts.forward` raises by design), so those are hooked instead of `forward`. - The fused-MoE kernel patch now covers `experts.triton_moe` in addition to `fused_moe`. 0.24's launcher binds the kernel names at import time, so patching only the defining module would leave fakequant **silently inactive**. - `UnquantizedFusedMoEMethod` is resolved from either module layout. - `examples/vllm_serve/vllm_reload_utils.py`: quantizer module paths are now `mlp.experts.routed_experts.*`, so HF→vLLM expert key mapping inserts a matching `.routed_experts` infix when that layout is present. - CI `gpu_vllm` now runs on **two** containers: `v0.24.0` (first release with the FusedMoE-factory / `RoutedExperts` layout — `v0.24.1` was never released, `nemo:26.08` ships a `0.24.1.dev0` build of the same layout) and `v0.20.0`, which keeps the legacy `FusedMoE`/`SharedFusedMoE` branches covered. Test fixes for the newer vLLM (not product bugs): - The tiny Llama fixture used `hidden_size=32 / 16 heads` → `head_dim=2`, which `FLEX_ATTENTION` (the only backend available in this image) rejects with `NYI: embedding dimension ... must be at least 16`, killing the engine core at warmup. Now `head_dim=64`, matching the Qwen3-MoE fixture. - The FlashInfer metadata-builder stub used `causal=False`, which in 0.24 forces the FI-native path (`all_uses_trtllm = causal and ...`) requiring workspace buffers and real wrapper planning. Keep it on the all-TRTLLM path it was originally exercising; the stashed `_modelopt_*` fields are path-independent. ### Usage No API change — existing `mtq.quantize` / `examples/vllm_serve` flows work unmodified on both old and new vLLM. ### Testing All runs in the `nemo:26.08.rc3` container (vLLM `0.24.1.dev0+gee0da84ab`, the same 0.24.1 the CI job now pins). **Suites** - `tests/gpu_vllm`: **73 passed, 1 skipped** (was 70 passed / 3 failed). - `tests/gpu_megatron`: all pass (previously ~120 failures, all from the registry `TypeError` — TE, Megatron chaining and MSE-calibrator tests that never touch vLLM). - `tests/unit/torch/opt/test_dynamic.py`: 2 passed, including the new `test_register_rejects_non_module_classes` (rejects a factory function and a non-`nn.Module` class, and asserts no partial registration). - `pre-commit` clean on all touched files. **MoE fakequant verified by module-tree probe, not just by test assertions** After `mtq.quantize(..., NVFP4_DEFAULT_CFG)` inside the vLLM worker, every weight-owning module was enumerated on tiny DeepSeek-V3 (MLA + routed MoE + shared experts) and tiny Qwen3-MoE: ``` model.layers.0.mlp.experts.routed_experts [QuantRoutedExperts] w13_input_quantizer=3.484 w13_weight_quantizer=0.0840 w2_input_quantizer=0.1060 w2_weight_quantizer=0.0845 model.layers.0.mlp.shared_experts.gate_up_proj [QuantMergedColumnParallelLinear] ✅ model.layers.0.mlp.shared_experts.down_proj [QuantRowParallelLinear] ✅ ``` Weight amax being populated (not just input amax) means the `B is self.w13_weight` identity check and the Parameter-swap weight-fakequant branch actually execute through 0.24's kernel path — i.e. `forward_modular`/`forward_monolithic` really are the live entry points and the `experts.triton_moe` patch target is the one that fires. Unquantized modules were only the expected ones: embeddings, RMSNorms, MoE router `gate`, `lm_head`. Registration parity vs. older vLLM: Row/Column/MergedColumn/QKV `ParallelLinear` and all four attention types (`Attention`, `CrossAttention`, `EncoderOnlyAttention`, `MLAAttention`) register unchanged; `FusedMoE` → `RoutedExperts`; `SharedFusedMoE` has no counterpart because the `shared_fused_moe` module no longer exists in 0.24 — shared experts are now a plain MLP whose linears we already quantize (confirmed above). **Known gaps (pre-existing, not regressions from this PR)** - `DeepSeekV2FusedQkvAProjLinear` is not quantized: it subclasses `MergedColumnParallelLinear` but overrides `forward`, so the registry's shared-forward rule declines it. Pre-0.24 the equivalent (`q_a_proj` / `kv_a_proj_with_mqa`) were `ReplicatedLinear`, which ModelOpt never quantized — effective coverage is unchanged. - MoE fakequant hooks only the Triton expert kernels; FlashInfer/CUTLASS/DeepGEMM MoE backends bypass them (why the fixtures pin `moe_backend="triton"`). - `_setup` still requires a plain `UnquantizedFusedMoEMethod`; a `FusedMoEModularMethod` swap (some DP/all2all configs) still asserts. **Not covered by tests** - `examples/vllm_serve/vllm_reload_utils.py` — the expert key mapping is now asserted in `test_tiny_qwen3_moe_quantize` against the quantizer module paths of a booted MoE model, so a stale infix fails loudly instead of silently serving uncalibrated experts. The rest of the reload path is still inspection-only. Note the registry key moved `vllm_FusedMoE` → `vllm_RoutedExperts` and quantizer paths gained `.routed_experts`, so a `modelopt_state` saved under an older vLLM will not restore onto 0.24 as-is. - The legacy `FusedMoE`/`SharedFusedMoE` branches are covered by the second CI entry; the `v0.20.0` job is green on this PR. ### Before your PR is "*Ready for review*" - Is this change backward compatible?: ✅ — all new paths are feature-detected; older vLLM keeps the `FusedMoE` registration. - If you copied code from any other sources or added a new PIP dependency, did you follow guidance in `CONTRIBUTING.md`: N/A - Did you write any new necessary tests?: N/A — existing `tests/gpu_vllm` coverage exercises the new registration path. - Did you update [Changelog](https://github.com/NVIDIA/Model-Optimizer/blob/main/CHANGELOG.rst)?: N/A - Did you get Claude approval on this PR?: ❌ ### Additional Information Found while bumping the Megatron test environment from `nemo:26.06` to `nemo:26.08.rc3`. <!-- This is an auto-generated comment: release notes by coderabbit.ai --> ## Summary by CodeRabbit * **New Features** * Added compatibility for newer vLLM MoE implementations, module layouts, and routed-expert configurations. * Improved model reload support for models using routed-expert submodules. * **Bug Fixes** * Improved detection and patching of vLLM MoE execution paths across supported configurations. * Registry validation now rejects invalid module registrations without partially applying changes. * **Tests** * Expanded GPU coverage for vLLM 0.24.0, dynamic module validation, and causal attention metadata paths. <!-- end of auto-generated comment: release notes by coderabbit.ai --> --------- Signed-off-by: Keval Morabia <28916987+kevalmorabia97@users.noreply.github.com> |
||
|
Keval MorabiaandClaude Opus 5
|
9e3425de05 |
Fix saving pruned Nemotron-3-Nano hybrid_override_pattern with MTP or Pipe symbols (#2061)
Saving pruned Nemotron-3-Nano (with MTP) to HF format raised an assertion which is fixed here Tested on nemo:26.04 with transformers 4.57 <!-- This is an auto-generated comment: release notes by coderabbit.ai --> ## Summary by CodeRabbit * **Bug Fixes** * Improved exported hybrid layer patterns for pruned models by removing MTP and pipeline-parallel markers. * Ensured exported configurations accurately represent the model’s main layers. * **Tests** * Added coverage for pruning models with an MTP prediction layer and hybrid override patterns. <!-- end of auto-generated comment: release notes by coderabbit.ai --> --------- Signed-off-by: Keval Morabia <28916987+kevalmorabia97@users.noreply.github.com> Co-authored-by: Claude Opus 5 (1M context) <noreply@anthropic.com> |
||
|
Chenjie LuoandClaude Opus 5
|
77dbeb1872 |
Add optional MLflow tracking to hf_ptq.py (#2023)
### What does this PR do? Type of change: new feature Adds `modelopt.torch.utils.mlflow.MlflowRunLogger`, a reusable helper for recording a script run on an MLflow tracking server, and wires `examples/hf_ptq/hf_ptq.py` up to it via `--mlflow <tracking-uri>` so a PTQ run can be reproduced from its MLflow entry alone. Without the flag, behavior is unchanged — every hook is gated on it. The logger lives in the library rather than the example so other scripts can record runs the same way: it takes a tracking URI, an experiment name and an explicit `enabled` flag, with params, tags and artifacts passed in. `hf_ptq.py` supplies only the PTQ-specific pieces (its params, the resolved recipe, the quantization summaries). `mlflow` is an optional dependency, imported only once tracking is enabled, so it is not a new requirement for the library. The run is opened **before the model loads**, so a bad URI or an unreachable server fails in seconds rather than after hours of calibration. The invocation and the recipe are uploaded at that point too, which keeps a crashed run useful: it is still recorded, with status `FAILED` and its log attached. Uploaded artifacts: | Artifact | Contents | | --- | --- | | `command.txt` | The full invocation, copy-pasteable | | `version.txt` | The ModelOpt version that ran (also a searchable tag) | | `recipe/resolved_recipe.yaml` | The `--recipe` with `$import`s expanded | | `logs/hf_ptq.log` | Everything the run printed, including a crash traceback | | `summary/quant_summary.txt` | Per-quantizer summary (unless `--no-verbose`) | | `summary/moe.html` | Per-expert calibration token counts, when the run produces them | Plus model / format / calibration settings as searchable params, and `user` / `hostname` / `modelopt_version` / `git_sha` tags. Three design points worth review: 1. **The recipe is uploaded resolved, not verbatim.** A recipe may be a directory or use `$import`s, so the source file is not self-contained. For `huggingface/qwen3_6_moe/auto_quantize/w4a16_nvfp4_fp8_at_6p0bits-active_moe` the source is 2,230 B / 58 lines against 7,563 B / 308 lines resolved — the raw file records under 30% of what actually ran. 2. **`hf_ptq.py` has no logging framework** (bare `print()`), so the log is produced by teeing stdout/stderr. Handlers that libraries bound to `sys.stderr` at import time are re-pointed at the tee for the run's duration and handed back afterwards; without that, `transformers` / `huggingface_hub` warnings reach the console but never the log. Native (C-level) output is still not captured — documented in the README. 3. **The recipe upload lives in the caller, not the library.** That keeps `modelopt.recipe` out of `modelopt.torch.utils`, which would otherwise risk a `modelopt.torch.utils` → `modelopt.recipe` → `modelopt.torch.quantization` → `modelopt.torch.utils` import cycle. 4. **MLflow failures never fail the quantization.** Startup validation is fatal by design (it is before any GPU work); the end-of-run upload is best-effort. Only the main rank uploads, so `--use_fsdp2` runs produce a single run. ### Usage ```bash python hf_ptq.py \ --pyt_ckpt_path <huggingface_model_card> \ --recipe general/ptq/nvfp4_default-kv_fp8_cast \ --export_path <quantized_ckpt_path> \ --mlflow https://<your-mlflow-server>/ ``` ``` [mlflow] experiment: $USER/hf_ptq/<checkpoint basename>-<recipe name> [mlflow] run: https://<your-mlflow-server>/#/experiments/13/runs/c243352e... ``` `--mlflow_experiment` and `--mlflow_run_name` override the defaults (`$USER/hf_ptq/<basename>-<recipe name or --qformat>`, and the UTC start time). Passing `--mlflow` with no value uses `$MLFLOW_TRACKING_URI`. Authentication uses MLflow's own env vars. ### Testing **Unit** — 51 tests in `tests/unit/torch/utils/test_mlflow.py` for the library, plus 13 in `tests/examples/hf_ptq/test_hf_ptq_args.py` for the hf_ptq wiring. CPU-only, no network and no `mlflow` dependency (driven against a stub module). Covers experiment-name derivation and sanitization, URI accept/reject, tee pass-through, the pre-bound-handler redirect, artifact renaming, skipping absent optional outputs, the disabled path, and `version.txt`. 85 tests pass together with the existing `test_hf_ptq_args.py` / `test_example_utils.py`. **Hardware** — real PTQ runs against a live MLflow server: | Run | Result | | --- | --- | | Qwen3-0.6B, NVFP4 PTQ, 1×B200 | `FINISHED`, all artifacts, sane post-quant generations | | Qwen3.6-35B-A3B MoE, AutoQuantize `w4a16_nvfp4_fp8_at_6p0bits-active_moe`, 2×B200 | `FINISHED` in 63 min, search hit `effective bits: 6.00`; 106 KB log capturing every per-layer decision, 4.4 MB quant summary | | Qwen3.6-35B-A3B, plain NVFP4 PTQ, 2×B200 | `FINISHED` | | Qwen3-0.6B re-run after the library move, 1×H200 | `FINISHED`, all five artifacts including `version.txt` | | Run **without** `--mlflow` after the review fixes | exactly 1 `[load_recipe]` line and 0 `[mlflow]` lines, confirming the untracked path is untouched | | Two runs sharing one `--export_path`, second crashed early | second run uploads **no** summary — the first run's 124 KB file on disk is correctly not attributed to it, and its traceback is in the log | | Crash mid-run (gated HF dataset) | `FAILED` recorded with log + traceback attached, summaries correctly absent | | Malformed URI | Rejected by `argparse` with a `Did you mean https://…?` hint | | Unreachable host | Fails in 9.9 s total, before any model load | | No `--mlflow` | Exit 0, no MLflow output, unchanged export | **Coverage gap, stated plainly:** `summary/moe.html` is verified only against a synthetic file (unit test + a real upload). It could not be produced naturally — `expert_token_count` buffers live on `_QuantSparseSequentialMoe`, while Qwen3.5/3.6 experts take the fused `_QuantFusedExperts` path, so no such file is written for these models regardless of `--moe_calib_experts_ratio`. The uploader's conditional is correct; the branch simply had no natural input available here. ### Before your PR is "*Ready for review*" - Is this change backward compatible?: ✅ — new optional flags only; no `--mlflow` means no behavior change. - If you copied code from any other sources or added a new PIP dependency, did you follow guidance in `CONTRIBUTING.md`: ✅ — adds `mlflow` as an optional extra in `pyproject.toml` (`nvidia-modelopt[mlflow]`, folded into `all`) and to `examples/hf_ptq/requirements.txt`. Apache-2.0 (permissive). Imported lazily, so it is not required to install or import ModelOpt. No code copied from other sources. - Did you write any new necessary tests?: ✅ — 29 new unit tests. - Did you update [Changelog](https://github.com/NVIDIA/Model-Optimizer/blob/main/CHANGELOG.rst)?: ✅ — 0.47 New Features. - Did you get Claude approval on this PR?: ❌ — `/claude review` not yet run. A self-review was done first and its six findings are fixed in the third commit (the notable one: gathering the MLflow inputs re-read the recipe on *every* run, including without `--mlflow`). ### Additional Information The one deliberate coverage gap is `summary/moe.html`, described under Testing: no model available here takes the sparse-sequential MoE path that writes it, so it is covered by unit test and a synthetic upload rather than a natural one. The uploader treats it as an optional output and skips it when absent, which is exercised by test. 🤖 Generated with [Claude Code](https://claude.com/claude-code) --------- Signed-off-by: Chenjie Luo <chenjiel@nvidia.com> Co-authored-by: Claude Opus 5 (1M context) <noreply@anthropic.com> |
||
|
Keval MorabiaandClaude Opus 4.8
|
93b9e4b176 |
Add Megatron-Bridge prune & quantize launcher pipelines (#2031)
### What does this PR do? Type of change: new example + small launcher / modelopt-example features (backward compatible) Adds end-to-end ModelOpt **launcher** pipelines for the Megatron-Bridge flow on Nemotron-3-Nano-30B-A3B, the minimal launcher features to run them wrapper-free from YAML, and an **in-step accuracy gate** for Minitron pruning. **New launcher examples** (`tools/launcher/examples/nvidia/NVIDIA-Nemotron-3-Nano-30B-A3B-BF16/`): - `mbridge_prune.yaml` — Minitron prune **with an in-step MMLU gate** → vLLM sanity gen (2 tasks) - `mbridge_quantize.yaml` — FP8 quantize → unified-HF export → MMLU gate on the vLLM backend, which doubles as the deploy sanity check (3 tasks). Matches the [tutorial](https://github.com/NVIDIA/Model-Optimizer/blob/main/examples/megatron_bridge/tutorials/NVIDIA-Nemotron-3-Nano-30B-A3B-BF16/README.md). **Prune accuracy gate** (reuses the search's own score — no separate eval step): - `modelopt/torch/prune/plugins/mcore_minitron.py` — `MCoreMinitronSearcher` now stores the exported best `CandidateSubnet` under `state_dict["best"]` (additive; sits beside the existing `sorted_layers` key). - `examples/megatron_bridge/prune_minitron.py` — new `--score_lower_bound`: reads `pruning_scores["best"].score` and exits non-zero if the exported model is below the floor. Score-agnostic (any `--prune_score_func`); rejected with `--prune_export_config` (manual pruning has no score). **Launcher (`tools/launcher`)** — run single-node Megatron-Bridge one-liners directly from YAML: - `SandboxTask.inline` — a command in the YAML, no `common/**/*.sh` wrapper (single-line; folded scalar) - `SandboxTask.reqs` / `reqs_file` — pip-install deps in the container before the command (shell-safe; on Slurm the install is rank-0-guarded so multi-rank tasks don't race) - `SlurmConfig.docker_user` — local-Docker user (e.g. `root`); ignored on Slurm - `get_default_env` honors `HF_HOME` / `TRITON_CACHE_DIR` env overrides, so a non-CI user can point caches at a writable path (the shared `/cicd/hf-cache` is owned by the CI account) - reject `args` together with `inline` **`examples/llm_eval/lm_eval_hf.py`**: - `--accuracy_lower_bound` — gate on the single requested task's `acc` (used by the quantize MMLU step; exits non-zero if below) - drop ModelOpt (hf-only) args for non-`hf` backends, so `--model vllm` works on a deployable quantized checkpoint ### Usage ```bash cd tools/launcher # Prune (in-step MMLU gate) -> vLLM gen uv run launch.py --yaml examples/nvidia/NVIDIA-Nemotron-3-Nano-30B-A3B-BF16/mbridge_prune.yaml --yes # FP8 quantize -> unified-HF export -> MMLU gate (vLLM) uv run launch.py --yaml examples/nvidia/NVIDIA-Nemotron-3-Nano-30B-A3B-BF16/mbridge_quantize.yaml --yes ``` ### Testing - Launcher unit tests for `inline`, `reqs`/`reqs_file`, `docker_user`, the `args`+`inline` guard, and example-resolve; ruff / mypy / bandit clean. `tests/examples/megatron_bridge/test_prune_minitron.py` now passes `--score_lower_bound=0.01` to exercise the gate path on the tiny models. - **End-to-end on the real Nemotron-3-Nano-30B-A3B (4×B200, OCI-HSG):** - Prune 30B → 3B-active: `[score_gate] mmlu_10pct = 0.5196 >= 0.45 PASS`; vLLM gen coherent. - FP8 quantize → unified-HF export (`Detected ModelOpt fp8 checkpoint`) → MMLU on the vLLM backend `acc = 0.7077 >= 0.60 PASS`. - Earlier smoke on **Qwen3-0.6B** in `nemo:26.06` through the same flow. ### Before your PR is "*Ready for review*" - Is this change backward compatible?: ✅ (new state-dict key is additive; new CLI args default to off) - If you copied code from any other sources or added a new PIP dependency, did you follow guidance in `CONTRIBUTING.md`: N/A - Did you write any new necessary tests?: ✅ - Did you update [Changelog](https://github.com/NVIDIA/Model-Optimizer/blob/main/CHANGELOG.rst)?: N/A <!-- tooling/examples + additive searcher state key --> - Did you get Claude approval on this PR?: ❌ <!-- pending --> ### Additional Information - **Container pinning:** saving a pruned Nemotron-H to HF requires `transformers<5`, so `mbridge_prune.yaml` runs on `nemo:26.04` (26.06 drops it); quantize/export run on `nemo:26.06`. - **`docker_user: root`** is set on all example tasks — local-Docker only (ignored on Slurm), needed so downstream tasks can read task_0's root-owned checkpoints and to read the image's root-only `/opt/Megatron-Bridge`. - The quantize MMLU step passes `enforce_eager=True` to vLLM — for a run-once eval this skips ~17 min of CUDA-graph capture / `torch.compile` with no accuracy change. 🤖 Generated with [Claude Code](https://claude.com/claude-code) <!-- This is an auto-generated comment: release notes by coderabbit.ai --> ## Summary by CodeRabbit - **New Features** - Added inline shell commands and per-task Python dependency installation for launcher workflows. - Added configurable Docker user selection and preservation of existing cache environment settings. - Added evaluation accuracy and pruning score gates that fail workflows below configured thresholds. - Added NVIDIA Nemotron pruning and quantization workflow examples. - Improved backend-specific handling of ModelOpt options. - **Documentation** - Documented inline commands, dependencies, variable substitution, and configuration examples. - **Bug Fixes** - Strengthened task execution validation and configuration checks. <!-- end of auto-generated comment: release notes by coderabbit.ai --> --------- Signed-off-by: Keval Morabia <28916987+kevalmorabia97@users.noreply.github.com> Co-authored-by: Claude Opus 4.8 <noreply@anthropic.com> |
||
|
Juhi MittalandClaude Opus 5
|
302a7ad4ea |
[NVBug: 6524370] use sequential device_map for DiffusionGemma (#2041)
### What does this PR do? Type of change: Bug fix Fixes NVBug 6524370. `DiffusionGemma` ties weights between its encoder and decoder. `get_model` loads with `device_map="auto"` (`examples/hf_ptq/example_utils.py`), and `"auto"` is an alias for `"balanced"` — accelerate splits the model evenly across all visible GPUs by size, with no awareness of tied parameters. On multi-GPU it can place the two sides of a tied pair on different devices; the tie then cannot be honored and one side is left on the `meta` device. The pre-quantization preview in `pre_quantize` then reaches `(input_ids == self.config.image_token_id).any()` in `generation_diffusion_gemma.py` and fails: ``` RuntimeError: Tensor.item() cannot be called on meta tensors ``` This is multi-GPU-only by construction: with one visible GPU the balanced split is trivial, nothing is separated, and nothing lands on `meta`. This PR detects DiffusionGemma configs in `get_model` and selects `device_map="sequential"`, which fills one GPU before spilling to the next and so keeps tied modules together. It mirrors the existing per-model handling for `bart` and `t5`, where `device_map="auto"` similarly mis-shards tied encoder/decoder weights. Detection reads `model_type` and `architectures` from the config and ignores underscores, since the family is spelled `diffusion_gemma` in the Transformers module path and `DiffusionGemma` in the class name. ### Usage No API change. Previously this needed the flag passed manually: ```bash python hf_ptq.py --model <diffusion-gemma-ckpt> --recipe <recipe> \ --export_path <out> --trust_remote_code --use_seq_device_map ``` It is now selected automatically, and the model load logs: ``` Detected DiffusionGemma model. Using device_map='sequential'; the balanced 'auto' mapping can split its tied encoder/decoder weights across GPUs. ``` Passing `--use_seq_device_map` explicitly still works and is unaffected. ### Testing - Reproduced on 4x GB200 with `diffusiongemma-26B-A4B-it` and the `nvfp4_experts_only` recipe; `--use_seq_device_map` resolves the crash, confirming the device-mapping cause. - Validated on oci-hsg (4x GB200): with this patch and no CLI flag, `diffusiongemma-26B-A4B-it` loads correctly and the meta-tensor crash no longer reproduces. - `is_diffusion_gemma` checked against both config spellings, `architectures=None`, `architectures=[]`, and a `gemma3` negative to confirm no over-match — `get_model_type` already orders `DiffusionGemma` before `Gemma` for exactly this substring-collision reason. - `pre-commit run --files examples/hf_ptq/example_utils.py` passes (ruff, ruff-format, mypy, bandit). ### Before your PR is "*Ready for review*" - Is this change backward compatible?: ✅ - If you copied code from any other sources or added a new PIP dependency, did you follow guidance in `CONTRIBUTING.md`: N/A - Did you write any new necessary tests?: ❌ — no existing unit coverage for `get_model` device-map selection; happy to add a config-level test for `is_diffusion_gemma` if wanted. - Did you update [Changelog](https://github.com/NVIDIA/Model-Optimizer/blob/main/CHANGELOG.rst)?: N/A - Did you get Claude approval on this PR?: ❌ — pending ### Additional Information NVBug 6524370. Same class of failure as the existing `t5` workaround in `get_model`; a general "any tied encoder/decoder model" rule was considered but rejected, since `tie_word_embeddings=True` holds for most decoder-only LLMs where `auto` is fine and forcing sequential would regress large-model runs. 🤖 Generated with [Claude Code](https://claude.com/claude-code) <!-- This is an auto-generated comment: release notes by coderabbit.ai --> ## Summary by CodeRabbit * **Bug Fixes** * Improved DiffusionGemma model loading on multi-GPU systems by keeping related model weights together. * Added more reliable DiffusionGemma model recognition across supported configurations. * Preserved existing automatic device allocation for single-GPU systems and other supported models. * Improved loading reliability by applying appropriate memory limits during multi-GPU setup. <!-- end of auto-generated comment: release notes by coderabbit.ai --> Signed-off-by: Juhi Mittal <juhim@nvidia.com> Co-authored-by: Claude Opus 5 (1M context) <noreply@anthropic.com> |
||
|
Chenjie LuoandClaude Opus 5
|
7ed91540fa |
[NVBug: 6538278] Pass trust_remote_code to the TRT-LLM model load in deploy/eval examples (#2056)
### What does this PR do? Type of change: Bug fix Fixes [nvbug 6538278](https://nvbugspro.nvidia.com/bug/6538278). `examples/hf_ptq/run_tensorrt_llm.py` loaded the **tokenizer** with `args.trust_remote_code` but constructed `LLM()` without it, so it defaulted to `False`. Deploying any checkpoint that ships custom modeling code (`auto_map`) — e.g. `Llama-3.3-Nemotron-Super-49B-v1` (DeciLM) — failed at executor init: ``` Failed to initialize executor on rank 0: The repository ... contains custom code which must be executed to correctly load the model ... Please pass the argument trust_remote_code=True. -> ValueError -> Executor worker returned error -> run_tensorrt_llm.py subprocess exit 1 ``` The `modelopt.deploy.llm.LLM` wrapper already accepts and forwards `trust_remote_code` (`modelopt/deploy/llm/generate.py:153`), and `scripts/huggingface_example.sh` already forwards `--trust_remote_code` to the script — only the call site dropped it. The same omission exists in the sibling TRT-LLM deploy paths driven by the same launcher and the same checkpoints, so they are fixed together: | File | Fix | | --- | --- | | `examples/hf_ptq/run_tensorrt_llm.py` | the reported bug | | `examples/llm_eval/lm_eval_tensorrt_llm.py` | `LLM()` ignored the `trust_remote_code` that lm-eval injects into `model_args` | | `examples/llm_eval/mmlu.py` | `LLM()` ignored it (the tokenizer already used it) | | `examples/hf_ptq/scripts/huggingface_example.sh` | the `mmlu` stage never forwarded the flag at all | All four propagate the **user-provided** flag; none hardcode `trust_remote_code=True` (per SECURITY.md). ### Usage No API change. Existing flag now takes effect on the model load: ```bash scripts/huggingface_example.sh --model <Llama-3.3-Nemotron-Super-49B-v1> \ --quant fp8 --tasks quant --trust_remote_code ``` ### Testing - New CPU regression test `tests/examples/hf_ptq/test_run_tensorrt_llm.py` stubs the `tensorrt_llm`-dependent import and asserts both the tokenizer **and** the model load receive the flag, parametrized over `True`/`False`. Confirmed it fails without the fix (`KeyError: 'trust_remote_code'`) and passes with it. - Verified against the real `fire` package that a bare `--trust_remote_code` maps to `True` in `mmlu.py`'s `**kwargs`, and is absent (defaulting to `False`) when not passed. - Simulated the launcher's argument assembly both ways: with `TRUST_REMOTE_CODE=false` the emitted commands are byte-identical to before this change. - `bash -n` on the launcher; full pre-commit clean. - GPU deploy of the `fp8` DeciLM checkpoint was verified by the bug reporter on GB10 with this one-line change (model loaded, TRT engine built, generation succeeded, deploy exit 0). The `mmlu` / `lm_eval` stages are not GPU-verified here. ### Before your PR is "*Ready for review*" - Is this change backward compatible?: ✅ - If you copied code from any other sources or added a new PIP dependency, did you follow guidance in `CONTRIBUTING.md`: N/A - Did you write any new necessary tests?: ✅ - Did you update [Changelog](https://github.com/NVIDIA/Model-Optimizer/blob/main/CHANGELOG.rst)?: N/A <!-- examples-only bug fix --> - Did you get Claude approval on this PR?: ❌ <!-- not yet run --> ### Additional Information nvbug 6538278 / OMNIML-5659. Reported against modelopt 0.46.0rc0 on GB10 / DGX Spark (`tensorrt-llm/release:1.3.0rc22`). <!-- This is an auto-generated comment: release notes by coderabbit.ai --> ## Summary by CodeRabbit * **Bug Fixes** * Added consistent handling of the `trust_remote_code` setting across TensorRT-LLM inference and MMLU evaluation workflows. * Ensured tokenizer and model loading receive the configured remote-code behavior. * **Tests** * Added coverage validating remote-code settings and preserving KV-cache behavior when context logits are requested. <!-- end of auto-generated comment: release notes by coderabbit.ai --> Signed-off-by: Chenjie Luo <chenjiel@nvidia.com> Co-authored-by: Claude Opus 5 (1M context) <noreply@anthropic.com> |
||
|
mxinO
|
9d360af34f |
Add ModelOpt QAD skill for Slurm workflows (#2010)
### What does this PR do?

Type of change: new feature

Adds a general Slurm-only QAD skill based on the supported Megatron
Bridge
workflow. The skill:

- starts from a measured BF16-to-PTQ benchmark gap and preserves the
preceding
  PTQ configuration or recipe;
- gates QAD on exact Megatron Bridge model support and successful
Megatron PTQ,
using its master-rank quantizer summary as a scoped `amax` sanity check;
- requires model- and hardware-derived TP/PP/CP/EP/ETP topology
selection;
- streams and randomly samples only the required
`nvidia/Nemotron-Cascade-2-SFT-Data` token budget and uses Megatron
sequence
  packing;
- defaults to 32K sequences, LR `1e-5` with cosine decay, a 1000-step
cap, and
  GBS 512;
- requires explicit user authorization because QAD is costly, validates
two
batches every 25 steps, saves every 50 steps, and monitors a decreasing
  smoothed loss trend;
- evaluates an early checkpoint around step 150 and continues only when
  benchmark recovery and the loss trend justify more training;
- follows the established common Slurm and remote-execution guidance
instead of
  duplicating mutable commands from the Megatron Bridge README.

Also exposes Megatron Bridge `save_interval`, `exit_interval`, and
`exit_duration_in_mins` through `examples/megatron_bridge/distill.py`,
with example-test coverage for checkpoint
and ModelOpt-state preservation at an early exit.

### Usage

```text
Use the QAD skill to recover the measured BF16-to-PTQ benchmark gap for
<model> on <Slurm cluster>, preserving the validated PTQ recipe.
```

### Testing

- `PYTHONPATH=$PWD pre-commit run --all-files`
- Passed every hook on the rebased branch, including Ruff, Ruff format,
mypy,
YAML/recipe validation, launcher reference validation, Bandit, generated
    arguments, symlink synchronization, and Markdown lint.
- `python
~/.codex/skills/.system/skill-creator/scripts/quick_validate.py
.agents/skills/qad`
  - `Skill is valid!`

Qwen3-0.6B result-bearing validation:

- Resources: one exclusive node, 8 H100 GPUs
- Container: `nvcr.io/nvidia/nemo:26.06`
- Quantization: NVFP4, group size 16, embedding excluded
- QAD topology: TP=1, PP=1, CP=4, EP=1, DP=2
- Training validation configuration: sequence length 32768, MBS=1,
GBS=8,
`train_iters=1000`, LR `1e-5` / minimum LR `1e-6`, 50 warmup iterations,
  cosine decay, `eval_interval=150`, `exit_interval=150`,
  `exit_duration_in_mins=220`
- This result-bearing run used the then-current coupled eval/save
cadence. The
final skill now validates two batches every 25 steps and saves every 50;
the
  example test covers the independent checkpoint cadence.
- The reduced GBS 8 is intentionally validation-only; the skill retains
GBS 512
  as the production default.
- Data: exactly 10,000,000 sampled tokens from four
  `nvidia/Nemotron-Cascade-2-SFT-Data` configs:
  - math: 2,306,011 tokens / 364 documents
  - science: 1,191,257 tokens / 285 documents
  - chat: 6,142,077 tokens / 1,800 documents
  - instruction following: 360,655 tokens / 411 documents
- Megatron built packed 32K GPT samples from the materialized prefixes;
the full
  dataset was not downloaded.
- QAD loss was finite and decreased from `0.2640341` at iteration 10 to
`0.1060580` at iteration 150. Final gradient norm was `0.747`, with zero
  skipped and zero NaN iterations. Validation distillation loss was
  `0.09715855`.
- The iteration-150 checkpoint saved successfully with `modelopt_state`,
and
  both PTQ and QAD-150 exported to unified Hugging Face format.
- Identical full MMLU 0-shot comparison through the Megatron evaluator:

  | Model | Accuracy |
  | --- | ---: |
  | BF16 | 0.39517164 |
  | PTQ | 0.32851446 |
  | QAD-150 | 0.38740921 |

QAD-150 recovered `0.05889475 / 0.06665718 = 88.35%` of the measured PTQ
gap,
so validation stopped at the early evidence gate rather than continuing
  blindly toward 1000 iterations.

### Before your PR is "*Ready for review*"

- Is this change backward compatible?: ✅
- If you copied code from any other sources or added a new PIP
dependency, did
  you follow guidance in `CONTRIBUTING.md`: N/A
- Did you write any new necessary tests?: ✅
- Did you update Changelog?: N/A — this adds an agent skill and
example-only
  lifecycle flags.
- Did you get Claude approval on this PR?: N/A

### Additional Information

All seven branch commits are cryptographically signed and include a
`Signed-off-by` trailer.


<!-- This is an auto-generated comment: release notes by coderabbit.ai
-->
## Summary by CodeRabbit

* **New Features**
* Updated the QAD skill documentation with a clear “Execute in this
order” workflow, including a revised default recovery training policy.
* Added a new `nemotron-cascade-2` dataset blend configuration with an
increased token budget.
* Enhanced the MeGatron Bridge distillation CLI with stricter interval
argument validation and support for configurable save-and-exit controls.
* **Documentation**
* Expanded Megatron Bridge README guidance for dataset preparation,
token-budget recalculation, and resume expectations.
* **Tests**
* Improved distillation and QAD tests to validate early-exit behavior
and checkpoint expectations.
  * Added unit tests covering distillation CLI interval validation.
<!-- end of auto-generated comment: release notes by coderabbit.ai -->

---------

Signed-off-by: Meng Xin <mxin@nvidia.com>
|
||
|
|
a23390dbb6 |
[5726458] [Experimental] Add NVFP4 projection-output-quantizer recipe and HF embedding ONNX export example (#1981)
### What does this PR do?

Type of change: new example

Without output-side quantization, TensorRT's quantized GEMMs emit FP16
activations: every quantized GEMM input adds a low-precision copy *on
top of* the FP16 tensors instead of replacing them, so FP8/FP4 engines
can use as much or more activation memory than an unquantized FP16
engine ([5726458]). Quantizing the projection-Linear outputs makes the
engine carry inter-layer activations in the low-precision format. This
PR ships that as recipes for the Llama-Nemotron embedding/reranking
family (NVFP4 and FP8 variants) plus an end-to-end example.

Measured on RTX PRO 6000 Blackwell with TensorRT 10.16 (strongly-typed
engines, 5 dynamic-shape profiles up to 32x512), activation memory per
profile:

| Model | FP16 | `fp8` preset | **fp8 recipe** | `nvfp4` preset |
**nvfp4 recipe** |

|-------|-----:|-------------:|---------------:|---------------:|-----------------:|
| llama-nemotron-embed-1b-v2 | 1040 MiB | 1392 MiB | **1096 MiB** | 1040
MiB | **516 MiB** |
| llama-nemotron-rerank-1b-v2 | 1040 MiB | 1392 MiB | **1096 MiB** | 520
MiB | **331 MiB** |

Engine sizes (dominated by weights): FP16 ≈ 2374 MiB, FP8 ≈ 1453 MiB,
NVFP4 ≈ 1050–1075 MiB. The presets only shrink weights — their
activation memory matches (or exceeds, for FP8) the FP16 engine because
every quantized GEMM still emits FP16; the output-quantizer recipes are
what reduce activation memory (fp8: −21% vs its preset; nvfp4: −50% vs
its preset and 2x below FP16).

-
**`modelopt_recipes/huggingface/nemotron_llama/ptq/nvfp4_output_quant_proj.yaml`**
— the general `nvfp4` preset plus dynamic NVFP4 output quantizers scoped
to the projection Linears (`*_proj.output_quantizer`). Scoping matters:
a `DynamicQuantize` on non-GEMM outputs (embedding lookup, pooling)
fails to compile in TensorRT. The sequence-classification `score` head
is kept unquantized: final heads stay in high precision like `lm_head`,
and its `[1, hidden]` weight cannot be packed by the NVFP4 exporter.
-
**`modelopt_recipes/huggingface/nemotron_llama/ptq/fp8_output_quant_proj.yaml`**
— the FP8 twin: per-tensor FP8 output quantizers on the projection
Linears, switching the engine from FP16-out GEMMs
(`e4m3f16..._bias_f16`) to FP8-out GEMMs (`e4m3e4m3_e4m3`).
- **`examples/torch_onnx/hf_embedding_quant_to_onnx.py`** — minimal
end-to-end recipe-driven quantize → ONNX export for HF bidirectional
Llama embedding and reranking encoders (auto-detected from the model
architecture; embedding models export mean-pooled L2-normalized
embeddings, rerankers export relevance logits), with the export shims
needed for a TensorRT-fusable graph (bidirectional sdpa symbolic with
single-precision attention constants; static blocked-axis extents for
`Reshape → TRT_FP4DynamicQuantize`).
- **`modelopt/torch/quantization/export_onnx.py`** —
`configure_linear_module_onnx_quantizers` now types output quantizers as
`"dynamic"` (they previously fell to the static path, which the NVFP4
weight exporter rejects on activations), and the sdpa symbolic's
`JitScalarType` import is fixed for torch >= 2.11.
- **`examples/torch_onnx/torch_quant_to_onnx.py`** — replaces the
`mtq.*_CFG` module-constant table with YAML recipe loading and adds a
`--recipe` flag (preset basename or `QuantizeConfig` YAML path);
`--auto_quantization_formats` values switch from config-constant names
to preset basenames.
- **`tests/examples/torch_onnx/test_hf_embedding_quant_to_onnx.py`** —
end-to-end example test running both model kinds through quantize →
export with tiny random-weight stand-ins (plain Llama encoder and
`LlamaForSequenceClassification`, sized to the NVFP4 block size).
- README section for the new example, including the results table and
trtexec engine-build steps; CHANGELOG entry.

### Usage

```bash
# Embedding model (default recipe: nvfp4 + projection output quantizers)
python examples/torch_onnx/hf_embedding_quant_to_onnx.py \
    --model_path=nvidia/llama-nemotron-embed-1b-v2 \
    --trust_remote_code \
    --onnx_save_path=llama_nemotron_embed_nvfp4.onnx

# Reranking model (auto-detected), FP8 variant of the recipe
python examples/torch_onnx/hf_embedding_quant_to_onnx.py \
    --model_path=nvidia/llama-nemotron-rerank-1b-v2 \
    --trust_remote_code \
    --recipe=huggingface/nemotron_llama/ptq/fp8_output_quant_proj \
    --onnx_save_path=llama_nemotron_rerank_fp8.onnx

# Build a strongly-typed TensorRT engine (Blackwell, TensorRT >= 10.11)
trtexec --onnx=llama_nemotron_embed_nvfp4.onnx --stronglyTyped \
    --saveEngine=llama_nemotron_embed_nvfp4.plan \
    --minShapes=input_ids:1x2,attention_mask:1x2 \
    --optShapes=input_ids:32x128,attention_mask:32x128 \
    --maxShapes=input_ids:32x512,attention_mask:32x512
```

### Testing

- New end-to-end example test `test_hf_embedding_quant_to_onnx.py` runs
both model kinds (embedding + reranking) through quantize → ONNX export
on tiny random-weight checkpoints; `test_torch_onnx_recipe_flag` covers
the `--recipe` flag.
- Ran the example end-to-end on GPU for both real models and both
recipes; each graph parses with TensorRT strongly-typed mode (NVFP4
graphs carry 112 input-side + 112 output-side `TRT_FP4DynamicQuantize`;
FP8 graphs carry the matching static Q/DQ placement).
- Built strongly-typed 5-profile engines on RTX PRO 6000 Blackwell with
TensorRT 10.16 for FP16 and both presets/recipes on both models;
compared per-profile activation memory via
`ICudaEngine.get_device_memory_size_for_profile_v2` (table above) and
verified kernel selection (FP8 recipe → `e4m3e4m3_e4m3` FP8-out GEMMs;
NVFP4 → block-scaled GEMMs).
- Recipes pass `tools/precommit/check_modelopt_recipes.py`; `pre-commit`
green on all changed files.

### Before your PR is "*Ready for review*"

Make sure you read and follow [Contributor
guidelines](https://github.com/NVIDIA/Model-Optimizer/blob/main/CONTRIBUTING.md)
and your commits are signed (`git commit -s -S`).

Make sure you read and follow the [Security Best
Practices](https://github.com/NVIDIA/Model-Optimizer/blob/main/SECURITY.md#security-coding-practices-for-contributors)
(e.g. avoiding hardcoded `trust_remote_code=True`, `torch.load(...,
weights_only=False)`, `pickle`, etc.).

- Is this change backward compatible?: ❌ — `torch_quant_to_onnx.py`'s
`--auto_quantization_formats` values are renamed from config-constant
names (e.g. `NVFP4_AWQ_LITE_CFG`) to preset basenames (e.g.
`nvfp4_awq_lite`); the loaded configs are identical. Core APIs are
backward compatible (the output-quantizer export typing is additive).
- If you copied code from any other sources or added a new PIP
dependency, did you follow guidance in `CONTRIBUTING.md`: N/A
- Did you write any new necessary tests?: ✅
(`test_hf_embedding_quant_to_onnx` for both model kinds,
`test_torch_onnx_recipe_flag`)
- Did you update
[Changelog](https://github.com/NVIDIA/Model-Optimizer/blob/main/CHANGELOG.rst)?:
✅

### Additional Information

The target model family requires remote modeling code, so the usage
examples opt in explicitly with `--trust_remote_code`. Accuracy parity
(embedding quality / reranking scores) of the output-quantized recipes
has not been evaluated yet and should be validated before recommending
them as defaults.

🤖 Generated with [Claude Code](https://claude.com/claude-code)
> 🤖 _Generated by Claude (AI agent)._

<!-- This is an auto-generated comment: release notes by coderabbit.ai
-->
## Summary by CodeRabbit

* **New Features**
* Added NVFP4 and FP8 projection-output PTQ recipes for Llama-Nemotron
embedding/reranking.
* Added an end-to-end Hugging Face “quantize-to-ONNX” CLI workflow for
TensorRT export.
* Enhanced Torch→ONNX quantization with YAML-driven recipes via a new
`--recipe` flag and improved auto-quantization format handling.
* **Bug Fixes**
* Improved ONNX export and TensorRT DynamicQuantize compatibility for
scaled dot-product attention and quantizer export behavior.
* **Documentation**
* Updated Torch→ONNX example docs and PTQ recipe guidance (including
Nemotron Llama).
* **Tests**
* Strengthened ONNX graph checks for recipe and Hugging Face export
flows.
<!-- end of auto-generated comment: release notes by coderabbit.ai -->

> 🤖 _Generated by Codex (AI agent)._

---------

Signed-off-by: ajrasane <131806219+ajrasane@users.noreply.github.com>
Co-authored-by: Claude Fable 5 <noreply@anthropic.com>
Co-authored-by: OpenAI Codex <noreply@openai.com>
|
||
|
Frida HouandClaude Opus 4.8
|
c062b3f829 |
Add sidecar GPU/CPU memory+utilization monitor for HF PTQ (#2000)
### What does this PR do?

**Type of change:** New feature (developer tool) + new tests

Adds a **standalone, cross-process resource monitor** —
`tools/resource_monitor.py` —
that samples a workload's GPU and CPU usage *from the outside* while it
runs, so
we can verify per-run memory budgets (e.g. the single-GPU layerwise PTQ
target of
≤80 GB GPU / ≤80 GB CPU for OMNIML-4947) without instrumenting
`hf_ptq.py` itself.

The monitor wraps any command, samples at a fixed interval, and on exit
writes a
CSV timeseries plus a peak/mean/min summary:

- **GPU** (per device, via NVML with an `nvidia-smi` fallback): used
memory,
  utilization %, power draw (W), temperature (°C).
- **CPU** (via `psutil`): system total/used/free memory + utilization %,
and the
  monitored process tree's RSS + CPU %.

It is opt-in from `examples/hf_ptq/scripts/huggingface_example.sh` via
`MODELOPT_MEM_MONITOR=1` (off by default → byte-for-byte identical
behavior). When
enabled it wraps the `hf_ptq.py` run and writes the trace/summary to a
**sibling**
`${SAVE_PATH}_mem_monitor/` directory, kept out of the exported
checkpoint that is
uploaded and consumed downstream.

**Files:**
- `tools/resource_monitor.py` — the sidecar (NVML + `nvidia-smi`
fallback; `psutil`).
- `tests/unit/tools/test_resource_monitor.py` — CPU-only unit tests (run
in the `unit` nox lane).
- `examples/hf_ptq/scripts/huggingface_example.sh` — opt-in
`MODELOPT_MEM_MONITOR=1` wrapper.
- `examples/hf_ptq/requirements.txt` — adds `psutil`.
- `pyproject.toml` — adds `psutil` to the `dev-test` extra
(deterministic import in the unit lane).
- `.github/workflows/unit_tests.yml` — adds `tools/resource_monitor.py`
to the unit-test path filters.

#### Why a new tool instead of extending
`modelopt/torch/utils/memory_monitor.py`?

The existing `GPUMemoryMonitor` is a fundamentally different tool and
cannot serve
this use case by extension:

| | `modelopt.torch.utils.memory_monitor.GPUMemoryMonitor` |
`tools/resource_monitor.py` (this PR) |
|---|---|---|
| Scope | **In-process** thread inside the workload | **Cross-process**
— wraps an external command |
| Survives workload OOM/SIGKILL | ❌ dies with the process | ✅ keeps
sampling, still writes the summary |
| Import cost | Pulls `torch` (~19 s) — lives in the workload |
Torch-free (`psutil`+`pynvml`, ~0.03 s) |
| Metrics | GPU device memory only | GPU mem/util/**power/temp** +
**CPU** mem/util + process-tree RSS |
| Output | In-memory / logs | CSV timeseries + peak/mean/min summary |

Merging the two would force `torch` into a standalone sidecar (defeating
the point)
or split the in-process monitor's threading model. A future refactor may
factor out
a **shared torch-free sampling core with two thin frontends**
(in-process + sidecar);
that is tracked as a follow-up rather than blocking this monitoring
harness, which
PR #2008 (single-GPU disk-offload PTQ) depends on.

### Usage

```bash
# Wrap mode (preferred): monitor exits with the workload's return code
python tools/resource_monitor.py --gpus 2,3 --out mem.csv --summary peak.txt -- \
    python hf_ptq.py --pyt_ckpt_path=<model> --qformat=nvfp4 ...

# Opt-in from the HF PTQ example (off by default):
MODELOPT_MEM_MONITOR=1 CUDA_VISIBLE_DEVICES=2,3 CUDA_DEVICE_ORDER=PCI_BUS_ID \
    bash examples/hf_ptq/scripts/huggingface_example.sh <args>
# -> writes ${SAVE_PATH}_mem_monitor/mem_trace.csv and mem_peak.txt
```

### Testing

- **Unit (CPU-only, in the `unit` nox lane):** `pytest
tests/unit/tools/test_resource_monitor.py`
— 11 tests covering `--gpus` parsing (CSV + space-separated, UUID/MIG
rejection),
the disabled/`nvidia-smi` sampling paths (including `[N/A]` → `None` and
the
smi-failure-yields-empty guard), CPU sampling, the accumulator, and
end-to-end
  CSV/summary + exit-code propagation in wrap mode.
- **GPU-validated** on a B200 node (GPUs 2,3): confirmed the `gpu{i}_*`
memory /
utilization / power / temperature columns populate and the summary is
written.

### Before your PR is "*Ready for review*"

- Is this change backward compatible?: ✅ — new tool; the example wrapper
is off unless `MODELOPT_MEM_MONITOR=1`.
- If you copied code from any other sources or added a new PIP
dependency, did you follow guidance in `CONTRIBUTING.md`: ✅ — `psutil`
added to `dev-test` + the hf_ptq example requirements;
`pynvml`/`nvidia-ml-py` is an optional runtime dep (graceful
`nvidia-smi` fallback).
- Did you write any new necessary tests?: ✅ —
`tests/unit/tools/test_resource_monitor.py`.
- Did you update Changelog?: N/A — repo-level `tools/` script, not
shipped in the wheel.
- Did you get Claude approval on this PR?: ❌ <!-- run /claude review -->

### Additional Information

Part of **OMNIML-4947** (single-GPU disk-offload PTQ). This is PR 1 of
the stack —
the monitoring harness that PR #2008 (disk-offload layerwise PTQ +
offload-aware
export) builds on.

---------

Signed-off-by: Fridah-nv <201670829+Fridah-nv@users.noreply.github.com>
Co-authored-by: Claude Opus 4.8 (1M context) <noreply@anthropic.com>
|
||
|
skieratandh-guo18
|
c94405e602 |
add Qwen3-VL support for DFlash training (#1975)
### What does this PR do?

  Type of change: new feature

Adds online DFlash training support for Qwen3-VL–style vision-language
models.

  Changes include:

- Load VLMs through the Transformers 5 `AutoModelForImageTextToText`
API, while retaining compatibility with the legacy VLM auto-model API.
- Run the base model through its top-level multimodal forward when
image/video inputs are present, ensuring vision embeddings are injected
before collecting DFlash target hidden states.
  - Extend `VisionLanguageDataCollator` to:
- propagate `answer_only_loss`, chat-template, and DFlash
label-alignment settings;
    - apply `VLM_MIN_PIXELS` / `VLM_MAX_PIXELS` processor limits;
- derive assistant-only masks from ChatML/Llama chat boundaries when
processor generation masks are unavailable;
- enforce the fixed `training_seq_len` required by DFlash block
training.
- Preserve the existing text-only DFlash path.

### Usage

```bash
python -m torch.distributed.run \
--nproc_per_node 4 \
examples/speculative_decoding/main.py \
--config modelopt_recipes/general/speculative_decoding/dflash.yaml \
model.model_name_or_path=/path/to/qwen3-vl-model \
model.trust_remote_code=true \
data.data_path=/path/to/train.jsonl \
data.vlm_processor=/path/to/qwen3-vl-model \
data.vlm_img_dir=/path/to/image/root \
training.training_seq_len=4096 \
training.answer_only_loss=true \
dflash.dflash_block_size=8 \
dflash.dflash_mask_token_id=151669


### Testing
- git diff --check
- Parsed all modified Python modules successfully.
- Ran iterative multi-node Slurm smoke tests with a Qwen3-VL-family model and mixed multimodal data:
    - validated VLM model loading with Transformers 5;
    - validated distributed initialization, DFlash conversion, and VLM collation paths;
    - identified and addressed processor padding/truncation behavior required by fixed-size DFlash blocks.
This PR remains draft pending a completed end-to-end training smoke test and automated regression coverage.

### Before your PR is "Ready for review"
Make sure you read and follow Contributor guidelines (https://github.com/NVIDIA/Model-Optimizer/blob/main/CONTRIBUTING.md) and your commits are signed (git commit -s -S).
Make sure you read and follow the Security Best Practices (https://github.com/NVIDIA/Model-Optimizer/blob/main/SECURITY.md#security-coding-practices-for-contributors) (e.g. avoiding hardcoded trust_remote_code=True, torch.load(...,
weights_only=False), pickle, etc.).
- Is this change backward compatible?: ✅
- If you copied code from any other sources or added a new PIP dependency, did you follow guidance in CONTRIBUTING.md: N/A
- Did you write any new necessary tests?: ❌ — automated Qwen3-VL/DFlash regression coverage still needs to be added before review.
- Did you update Changelog (https://github.com/NVIDIA/Model-Optimizer/blob/main/CHANGELOG.rst)?: ❌ — evaluate and add an entry before marking ready for review if this is considered user-facing speculative-decoding support.
- Did you get Claude approval on this PR?: N/A
### Additional Information
The PR intentionally excludes local Slurm launch scripts, logs, model paths, datasets, and environment-specific configuration.


<!-- This is an auto-generated comment: release notes by coderabbit.ai -->
## Summary by CodeRabbit

* **New Features**
  * Expanded VLM data-collation controls, including `shift_labels` and more robust `answer_only_loss` masking.
  * Improved Qwen3-VL speculative decoding for Transformers 5.3+ with correct video frame grouping and safer position-id handling.
  * Improved DFlash RoPE export to reliably read `rope_theta` from newer config formats.

* **Bug Fixes**
  * Hardened multimodal preprocessing and training loss masking to keep label/attention alignment consistent.
  * Improved behavior when anchor sampling yields no valid blocks.
  * More resilient VLM model loading when certain Transformers auto classes are unavailable.

* **Tests**
  * Added coverage for RoPE export, Qwen3-VL position-id logic across Transformers versions, and VLM label-mode/collator options.
<!-- end of auto-generated comment: release notes by coderabbit.ai -->

---------

Signed-off-by: Slawomir Kierat <skierat@nvidia.com>
Signed-off-by: h-guo18 <67671475+h-guo18@users.noreply.github.com>
Co-authored-by: h-guo18 <67671475+h-guo18@users.noreply.github.com>
|
||
|
Rishi Khare
|
943c0b2f7d |
docs(puzzletron): install lm-eval in container setup (#2020)
### What does this PR do? Type of change: documentation The container setup section uninstalls `nvidia-lm-eval` and the note above it states that it is "replaced with `lm-eval` from the repo", but none of the install commands actually install `lm-eval`. Following the README therefore leaves the environment without `lm-eval`, which the [Evaluation](https://github.com/NVIDIA/Model-Optimizer/blob/main/examples/puzzletron/README.md#evaluation) step requires. `lm-eval` ships in `examples/llm_eval/requirements.txt`, so this adds that one install line to the setup block. ### Usage N/A ### Testing Traced the dependency graph to confirm `lm-eval` is reachable from no install path the README has currently: - `puzzletron` extra: `fire`, `hydra-core`, `immutabledict`, `lru-dict`, `pandas`, `typeguard` - `dev-test` extra: pytest/coverage tooling, `timm`, `torchprofile`, `torchvision`, `torch-geometric` - `examples/puzzletron/requirements.txt`: `math-verify`, `ray`, `transformers<5.0` `lm_eval[api,ifeval]>=0.4.10` appears only in `examples/llm_eval/requirements.txt`. `pre-commit run --files examples/puzzletron/README.md` passes (markdownlint included). ### Before your PR is "*Ready for review*" - Is this change backward compatible?: ✅ - If you copied code from any other sources or added a new PIP dependency, did you follow guidance in `CONTRIBUTING.md`: N/A - Did you write any new necessary tests?: N/A - Did you update [Changelog](https://github.com/NVIDIA/Model-Optimizer/blob/main/CHANGELOG.rst)?: N/A <!-- docs-only --> - Did you get Claude approval on this PR?: N/A <!-- not an NVIDIA org member, cannot self-trigger --> ### Additional Information Fixes #1786 <!-- This is an auto-generated comment: release notes by coderabbit.ai --> ## Summary by CodeRabbit * **Documentation** * Updated Puzzletron container setup instructions to include installing the LLM evaluation dependencies. * Clarified the setup sequence before running smoke tests. <!-- end of auto-generated comment: release notes by coderabbit.ai --> Signed-off-by: Rishi Khare <rishiskhare@gmail.com> |
||
|
vishalpandya1990
|
87c9f8cf83 |
Update documentation guide for ONNX INT4 PTQ on Windows cuda13 host (#2022)
### What does this PR do? Type of change: Documentation update - Update documentation guide for ONNX INT4 PTQ on Windows cuda13 host - mention about compatible onnxruntim-gpu and cupy-cuda13x packages. ### Testing - Windows's onnx_ptq\genai_llm INT4 PTQ example with a 1B genai-cuda-ep ONNX model + local doc building ### Before your PR is "*Ready for review*" Make sure you read and follow [Contributor guidelines](https://github.com/NVIDIA/Model-Optimizer/blob/main/CONTRIBUTING.md) and your commits are signed (`git commit -s -S`). Make sure you read and follow the [Security Best Practices](https://github.com/NVIDIA/Model-Optimizer/blob/main/SECURITY.md#security-coding-practices-for-contributors) (e.g. avoiding hardcoded `trust_remote_code=True`, `torch.load(..., weights_only=False)`, `pickle`, etc.). - Is this change backward compatible?: ✅ / ❌ / N/A <!--- If ❌, explain why. --> - If you copied code from any other sources or added a new PIP dependency, did you follow guidance in `CONTRIBUTING.md`: ✅ / ❌ / N/A <!--- Mandatory --> - Did you write any new necessary tests?: ✅ / ❌ / N/A <!--- Mandatory for new features or examples. --> - Did you update [Changelog](https://github.com/NVIDIA/Model-Optimizer/blob/main/CHANGELOG.rst)?: ✅ / ❌ / N/A <!--- Only for new features, API changes, critical bug fixes or backward incompatible changes. --> - Did you get Claude approval on this PR?: ✅ / ❌ / N/A <!--- Run `/claude review`. NVIDIA org members can self-trigger for complex changes; orthogonal to CodeRabbit. --> ### Additional Information <!-- E.g. related issue. --> <!-- This is an auto-generated comment: release notes by coderabbit.ai --> ## Summary by CodeRabbit * **Documentation** * Clarified Windows CUDA prerequisites for calibration and GPU-accelerated quantization. * Added setup guidance for CUDA 12 and CUDA 13.x, including compatible packages and cuDNN requirements. * Expanded installation verification steps for CUDA, ONNX Runtime, and CuPy. * Updated the GenAI LLM example with CUDA version compatibility guidance. * **Enhancements** * Added runtime logging of detected CUDA environment paths and version details during quantization. <!-- end of auto-generated comment: release notes by coderabbit.ai --> Signed-off-by: vipandya <vipandya@nvidia.com> |
||
|
|
33d05b0c44 |
FSDP2 calibration with hf_ptq.py [1/2] (#1563)
### What does this PR do?

Type of change: New feature (+ refactor/removal of the legacy multi-node
path) <!-- Use one of the following: Bug fix, new feature, new example,
new tests, documentation. -->

<!-- Details about the change. -->
Consolidates multi-node FSDP2 post-training quantization into the
standard hf_ptq.py entry point behind a --use_fsdp2 flag, and removes
the separate
Accelerate-based multinode_ptq.py script and fsdp2.yaml config. FSDP2
PTQ is now launched with torchrun and supports single-node multi-GPU and
multi-node out
  of the box.

  Highlights:
- --use_fsdp2 / --cpu_offload on hf_ptq.py — calibration runs under
PyTorch FSDP2; decoder layers are sharded (root stays replicated), with
optional CPU
  offload of decoder shards between forwards.
- New modelopt/torch/utils/model_load_utils.py — parallel, round-robin
safetensors loading: each rank reads only the decoder layers it owns
from disk, then
broadcasts them so every rank can shard its slice. Non-decoder weights
(embed/lm_head/norm) are read on rank 0 and broadcast.
- New FSDP2 helpers in modelopt/torch/utils/distributed.py — fsdp2_wrap,
shard_dataloader, fsdp_aware_forward_loop, broadcast_state_dict.
- Distributed export (unified_export_hf.py) — replaces the Accelerate
get_state_dict gather with get_model_state_dict(full_state_dict,
cpu_offload,
broadcast_from_rank0); rank 0 writes files, other ranks sync on a
barrier.
- core_utils.py — relaxes the stale "root must be an FSDPModule" assert
(only decoder layers are wrapped), and adds a CPU↔GPU mirror so weight
access/writeback
  works for CPU-offloaded shards.
- Docs — rewritten examples/llm_ptq/README.md FSDP2 section and the
SLURM PTQ reference, both using torchrun --use_fsdp2.

v1 scope: standard causal-LM checkpoints only. --use_fsdp2 raises
NotImplementedError for VILA, multimodal/VL,
pack-quantized/compressed-tensors, speculative decoding, MTP,
auto-quantize, and sparsity.

Design Notes

1. Why a custom parallel-safetensors loader instead of HF device_map /
accelerate

AutoModelForCausalLM.from_pretrained(device_map="auto" | "cpu") and
accelerate.load_checkpoint_in_model both load the full checkpoint on
every rank from disk (per-rank CPU peak ≈ full model size). For 70B
that's ~140 GiB/rank; for 200B+ it OOMs the node before sharding can
run. parallel_load_and_prepare_fsdp2 round-robins decoder layers across
ranks so each rank reads only ~model_size / world_size from disk, then
per-layer broadcasts to peers. Per-rank CPU peak is bounded by the
largest single layer + transient broadcast, not the full model. This is
what makes 200B+ FSDP2 PTQ feasible on commodity nodes; HF/accelerate's
existing entry points don't expose this composition.

2. Why a custom FSDP2 stack instead of keeping multinode_ptq.py +
accelerate launch

The deleted multinode_ptq.py ran on accelerate launch --config_file
fsdp2.yaml and duplicated hf_ptq.py's load → calibrate → export path.
Two consequences:
- Two divergent scripts for the same operation: CLI surface, calibration
loop, and export rewrites had to land twice. They had already drifted.
  - Users had to know which script applied at which scale.

The new code path unifies under hf_ptq.py --use_fsdp2. Going direct to
FSDP2 primitives (fully_shard, CPUOffloadPolicy, MixedPrecisionPolicy)
instead of
  routing through accelerate's wrappers buys:
- Direct control over mp_policy and offload_policy (accelerate's plugin
layer hides them).
- The parallel-read loader above (incompatible with accelerate's
per-rank full load).
  - No YAML config file in the example dir.
  -
The "custom stack" is intentionally thin: fsdp2_wrap is a 5-line wrapper
over fully_shard; the rest is pure torch.distributed. We're not
reimplementing FSDP2 —just composing the public PyTorch surface directly
rather than via accelerate's adapter.

3. fsdp_aware_forward_loop ↔ transformers_trainer.py:_quantize_model
duplication
Both implement the same trick: mtq.quantize unwraps the FSDP module
before calling the user's forward_loop, and forwarding through the
unwrapped module bypasses FSDP2's pre/post-forward hooks (no all-gather
→ broken calibration). Both capture the outer wrapped model and forward
through it instead. This PR extracts the pattern into
fsdp_aware_forward_loop (in distributed.py) as the canonical helper. The
QLoRA path (transformers_trainer.py:_quantize_model) keeps its inlined
version this PR because the QLoRA forward loop has training-specific
quirks (batch shape, loss accumulation, gradient flow) that need a
careful pass to share the helper cleanly. The TODO in the helper's
docstring marks the consolidation target.

### Usage

```python
 # Single node, multiple GPUs
  torchrun --standalone --nproc_per_node=<num_gpus> hf_ptq.py \
      --pyt_ckpt_path <model> \
      --qformat nvfp4 \
      --export_path <out> \
      --use_fsdp2

  # Multi-node (run on each node)
  torchrun \
      --nnodes=<N> --node_rank=<rank> \
      --master_addr=<node0_ip> --master_port=<port> \
      --nproc_per_node=<gpus_per_node> \
      hf_ptq.py \
      --pyt_ckpt_path <model> --qformat nvfp4 \
      --export_path <out> --use_fsdp2 --cpu_offload   # --cpu_offload for very large models
```

### Testing
<!-- Mention how have you tested your change if applicable. -->
- tests/gpu/torch/quantization/test_fsdp2.py:
test_writeback_root_unwrapped (assert relaxation, root unwrapped) and
test_writeback_cpu_offload (CPU↔GPU mirror
  round-trip under CPUOffloadPolicy).
- tests/unit/torch/utils/test_model_load_utils.py: pure-function tests
for weight_map_for (sharded / single-file / missing) and
read_safetensors_subset.
- Manual end-to-end PTQ runs on single- and multi-node torchrun (FP8 /
NVFP4 / NVFP4 layerwise), with and without --cpu_offload.

### Before your PR is "*Ready for review*"

Make sure you read and follow [Contributor
guidelines](https://github.com/NVIDIA/Model-Optimizer/blob/main/CONTRIBUTING.md)
and your commits are signed (`git commit -s -S`).

Make sure you read and follow the [Security Best
Practices](https://github.com/NVIDIA/Model-Optimizer/blob/main/SECURITY.md#security-coding-practices-for-contributors)
(e.g. avoiding hardcoded `trust_remote_code=True`, `torch.load(...,
weights_only=False)`, `pickle`, etc.).

- Is this change backward compatible?: ❌ <!--- If ❌, explain why. -->
hf_ptq.py is fully backward compatible (FSDP2 is opt-in via a new flag),
but the legacy examples/llm_ptq/multinode_ptq.py script and fsdp2.yaml
are removed. Users of the old multi-node entry point must migrate to
hf_ptq.py --use_fsdp2
- If you copied code from any other sources or added a new PIP
dependency, did you follow guidance in `CONTRIBUTING.md`: N/A <!---
Mandatory -->
- Did you write any new necessary tests?: ✅ <!--- Mandatory for new
features or examples. -->
- Did you update
[Changelog](https://github.com/NVIDIA/Model-Optimizer/blob/main/CHANGELOG.rst)?:
❌<!--- Only for new features, API changes, critical bug fixes or
backward incompatible changes. -->
- Did you get Claude approval on this PR?: ✅ / ❌ / N/A <!--- Run
`/claude review`. NVIDIA org members can self-trigger for complex
changes; orthogonal to CodeRabbit. -->

### Additional Information
<!-- E.g. related issue. -->


<!-- This is an auto-generated comment: release notes by coderabbit.ai
-->
## Summary by CodeRabbit

* **New Features**
* FSDP2-enabled PTQ: torchrun single-/multi-node execution, CPU offload,
and NVFP4 layerwise calibration; distributed model loading and export
support.

* **Documentation**
* Rewritten PTQ guide and SLURM notes with explicit torchrun/FSDP2
instructions.

* **Removed**
  * Legacy Accelerate-based multinode PTQ workflow and YAML config.

* **Tests**
* Added FSDP2-focused tests for quantization writeback and safetensors
distributed loading.
<!-- end of auto-generated comment: release notes by coderabbit.ai -->

---------

Signed-off-by: Suguna Velury <178320438+sugunav14@users.noreply.github.com>
Signed-off-by: sugunav14 <178320438+sugunav14@users.noreply.github.com>
Co-authored-by: Claude Opus 4.8 (1M context) <noreply@anthropic.com>
Co-authored-by: realAsma <86726418+realAsma@users.noreply.github.com>
|
||
|
h-guo18
|
6105fe84e9 |
[Examples]: MiniMax-M3 DSpark (#1965)
### What does this PR do?

Type of change: new example + bug fixes

Adds a **MiniMax-M3 DSpark streaming training recipe** under
`tools/launcher/examples/MiniMaxAI/MiniMax-M3/`, plus the four fixes it
needs to actually run. Each fix addresses a failure mode that is silent
or misleading without it:

1. **Gemma-style final norm for the fake base**
(`modeling_final_norm.py`, `modeling_fakebase.py`): M3 uses a
gemma-style final RMSNorm (`(1 + weight)` scale, fp32
multiply-then-cast). Selecting the norm by `model_type` alone picks
plain `rmsnorm` — MiniMax's VL remote code coerces its `model_type`-less
`text_config` to **mixtral** — which silently drops the `+1` and
corrupts the distillation target. New `_FinalGemmaRMSNorm` + selection
by the explicit `use_gemma_norm` config flag (only MiniMax sets it).
2. **Loud failure for un-maskable `answer_only_loss`**
(`hf_streaming_dataset.py`): with a fast tokenizer whose chat template
has no `{% generation %}` tags,
`apply_chat_template(return_assistant_tokens_mask=True)` only warns and
returns an **all-zero mask** — training runs at zero loss on every
sample with no other symptom. Now raises at tokenization with an
actionable message.
3. **`SERVE_BLOCK_SIZE` knob** (`train_eagle_streaming.sh`): nemo_run
exports env values unquoted, so a multi-token
`SERVE_EXTRA_ARGS="--trust-remote-code --block-size 128"` loses
everything after the first token. M3's MSA sparse attention requires KV
block 128 (`ValueError: No common block size for 16` at engine init
otherwise), so `--block-size` gets a dedicated single-token knob.
4. **Relax the speculative_decoding `transformers` pin to `<5.13`**
(match `pyproject.toml`): the old `<5.4` pin downgrades recent vLLM
containers (e.g. transformers 5.12.1, which also provides in-tree
`minimax_m3_vl`) and breaks `vllm serve` (`ALLOWED_LAYER_TYPES` needs
>=5.5.3).

The example itself encodes the validated M3 specifics: generation-tagged
chat template copy (required for `answer_only_loss` — see fix 2), draft
dims + base `rope_theta=5e6` set explicitly (not inherited), mask token
200063 (reserved slot; added tokens end at 200060), `EAGLE_CAPTURE_IDS`
= draft default `target_layer_ids+1` + final layer, `trust_remote_code`
at serve/export, and AWS-EFA NIXL notes (UCX segfaults at agent init on
EFA nodes; LIBFABRIC required there).

### Usage

```bash
cd tools/launcher
export SLURM_HOST=localhost SLURM_ACCOUNT=<account> SLURM_PARTITION=<partition> \
       SLURM_HF_LOCAL=<hf_models_dir> SLURM_JOB_DIR=<experiments_dir> NEMORUN_HOME=$PWD
uv run launch.py --yaml examples/MiniMaxAI/MiniMax-M3/hf_streaming_dspark_multi_node.yaml \
       identity=$HOME/.ssh/id_ecdsa detach=True --yes
```

### Testing

- `tests/unit/torch/speculative/plugins/`: **129 passed** inside a
current vLLM x86_64 nightly container (transformers 5.12.1), including 3
new tests for the assistant-mask guard.
- Generation-tagged template verified against real corpus samples:
`input_ids` identical to the original template, mask covers exactly the
assistant turns (think prefix + content + eos), contiguous, no
user-prompt leak.
- The recipe is exercised end-to-end by a live M3 DSpark training run
(this yaml modulo cluster paths): streaming serve + NIXL transport +
resume all healthy; drafter MT-Bench AL exceeds our Kimi-K2.6 DSpark
reference by ~8k steps.
- `ruff check` / `ruff format` (0.15.20) clean.

### Before your PR is "*Ready for review*"

- Is this change backward compatible?: ✅ (norm selection only changes
models with `use_gemma_norm=True`, previously mis-normed; the guard
turns a silent zero-loss run into an error; `SERVE_BLOCK_SIZE` is
opt-in; the pin relax widens the allowed range)
- Did you write any new necessary tests?: ✅
- Did you update
[Changelog](https://github.com/NVIDIA/Model-Optimizer/blob/main/CHANGELOG.rst)?:
❌ (can add if desired)

🤖 Generated with [Claude Code](https://claude.com/claude-code)


<!-- This is an auto-generated comment: release notes by coderabbit.ai
-->
## Summary by CodeRabbit

- **New Features**
- Added Gemma-style RMS normalization support for speculative decoding.
- Added MiniMax-M3 multi-node training configuration, including a full
Jinja chat template for tool calls, multimodal content, and thinking
modes.
  - Added optional `SERVE_BLOCK_SIZE` support for vLLM serve launches.
- **Bug Fixes**
- Improved `answer_only_loss` masking validation: now fails fast with
clear errors when required `{% generation %}` markers are missing or
when using a non-fast tokenizer.
- **Compatibility**
- Expanded the supported Transformers version range for speculative
decoding examples.
<!-- end of auto-generated comment: release notes by coderabbit.ai -->

---------

Signed-off-by: h-guo18 <67671475+h-guo18@users.noreply.github.com>
|
||
|
Keval MorabiaandClaude Opus 4.8
|
d143276c39 |
Support efficient TEGroupedMLP (moe_grouped_gemm=True) for Minitron Pruning (#1955)
### What does this PR do?

Type of change: New feature

Add Minitron pruning support for MoE models loaded with the efficient
fused **grouped GEMM** experts (`TEGroupedMLP`), in addition to the
existing `TESequentialMLP` path.

- New `_DynamicTEGroupedLinear` + `_DynamicTEGroupedMLP` dynamic modules
slice the per-expert grouped weights (`num_moe_experts` /
`moe_ffn_hidden_size` / `hidden_size`) and reorder/drop experts via
`num_gemms`, mirroring the SequentialMLP path with a minimal
DynamicModule diff.
- Since Minitron prunes homogeneously, a single shared
`moe_ffn_hidden_size` is pruned across experts (SequentialMLP keeps one
per expert). Same pruned width and independent per-expert weights; only
the kept-channel index set is shared.
- `examples/megatron_bridge/prune_minitron.py` uses grouped GEMM by
default (`--no_moe_grouped_gemm` to fall back to SequentialMLP).

### Usage

```bash
torchrun --nproc_per_node 2 prune_minitron.py \
    --hf_model_name_or_path <moe-model> \
    --prune_target_active_params 3e9 \
    --output_hf_path /tmp/pruned   # add --no_moe_grouped_gemm to use SequentialMLP
```

### Testing

Verified in an `nvcr.io/nvidia/nemo:26.06` + MBridge main (as of 23 Jul)
mounted so it mimics nemo:26.08 behavior.

- GPT MoE dynamic-module + pruning + parameter-sorting tests
parametrized over both expert impls.
- Mamba hybrid NAS metric tests: params-based now covers grouped GEMM,
memory-based stays SequentialMLP (exact param counts / top-k /
search-space-size assertions hold identically).
- NemotronH end-to-end `test_prune_minitron` exercises real-forward NAS
without grouped GEMM (to be enabled in 26.08 container)

- Compared Nemotron-3-Nano-30B-A3B pruning: SequentialMLP vs GroupedGEMM
on 4x B300 (accuracy + speed)

| Metric | TESequentialMLP (old) | TEGroupedLinear (new) |
|---|---|---|
| Calibration time | 6.5 mins | 3.5 mins|
| Time to evaluate Top-10 pruned candidates | 23 mins | 11 mins |

Top-10 Pruned Candidates — MMLU Scores

| # | export_config | params | TESequentialMLP (old) | TEGroupedLinear
(new) |
|---|---|---|---|---|
| 1 | L52, h2688, mamba 56×48, 96 experts, ffn 1536, shared 3072 |
20.09B | 0.2713 | 0.2846 |
| 2 | L52, h2688, mamba 48×56, 104 experts, ffn 1536, shared 3072 |
21.61B | 0.2580 | 0.2594 |
| 3 | L52, h2560, mamba 48×64, 96 experts, ffn 1536, shared 3712 |
19.28B | 0.3951 | 0.3895 |
| 4 | L52, h2304, mamba 64×64, 104 experts, ffn 1856, shared 3072 |
22.28B | 0.4951 | 0.4944 |
| 5 | L52, h2560, mamba 48×48, 96 experts, ffn 1792, shared 3328 |
21.99B | 0.2685 | 0.2580 |
| 6 | L48, h2560, mamba 56×56, 104 experts, ffn 1792, shared 3072 |
23.68B | 0.4741 | 0.4657 |
| 7 | L46, h2560, mamba 64×56, 104 experts, ffn 1792, shared 3072 |
23.68B | 0.2385 | 0.2371 |
| 8 | L52, h2688, mamba 48×56, 96 experts, ffn 1536, shared 3072 |
20.09B | 0.2587 | 0.2622 |
| 9 | L52, h2304, mamba 64×64, 96 experts, ffn 1856, shared 3072 |
20.70B | 0.4888 | 0.4860 |
| 10 | L50, h2560, mamba 48×48, 104 experts, ffn 1792, shared 3712 |
23.68B | 0.2517 | 0.2531 |

### Before your PR is "*Ready for review*"

- Is this change backward compatible?: ✅
- Did you write any new necessary tests?: ✅
- Did you update
[Changelog](https://github.com/NVIDIA/Model-Optimizer/blob/main/CHANGELOG.rst)?:
✅
- Did you get Claude approval on this PR?: ✅


<!-- This is an auto-generated comment: release notes by coderabbit.ai
-->
## Summary by CodeRabbit

## Summary by CodeRabbit

* **New Features**
* Improved MoE pruning and NAS/search-space handling to support both
grouped-GEMM and sequential expert layouts, including optimized
grouped-GEMM execution for Minitron.
* Added `--no_moe_grouped_gemm` to force the sequential expert path when
required.
* **Bug Fixes**
* Tightened `--prune_score_func` parsing for MMLU to accept only
`mmlu_<N>pct_bs<bs>`.
* Added a safety check in Megatron prefill to prevent int32 indexing
overflow by asking to reduce calibration batch size.
* **Tests**
* Expanded GPT and Mamba GPU pruning/search-space tests to cover both
MoE modes.
* **Documentation**
* Updated release notes and bridge/pruning guidance for the grouped-GEMM
behavior.
<!-- end of auto-generated comment: release notes by coderabbit.ai -->

Signed-off-by: Keval Morabia <28916987+kevalmorabia97@users.noreply.github.com>
Co-authored-by: Claude Opus 4.8 <noreply@anthropic.com>
|
||
|
Gwena Cunha
|
d984de3795 |
[6008361][ONNX][Quantization] Clarify autotune guidance (#1989)
### What does this PR do? Type of change: documentation This PR clarifies when users should use ONNX quantization with Autotune enabled versus the direct Autotune entry point. - Adds a warning to the Autotune guide explaining that direct Autotune is a lower-level Q/DQ placement tool and does not replace calibrated ONNX PTQ. - Updates the ONNX quantization guide to show `autotune=True` in the Python API and explain that it uses default Autotune settings. - Updates ONNX PTQ example documentation to prefer `python -m modelopt.onnx.quantization ... --autotune=<mode>` for accuracy-sensitive PTQ from an unquantized model. - Updates the direct Autotune CLI help text to point users back to the full ONNX quantization workflow when calibration data and accuracy validation are required. ### Usage ```python N/A — documentation/help text change. ``` ### Testing - Ran `python -m py_compile modelopt/onnx/quantization/autotune/__main__.py`. - Built the Sphinx documentation with `python -m sphinx -b html docs/source docs/build/html`; build succeeded. Remaining warnings are from optional documentation imports and existing cross-reference labels. ### Before your PR is "*Ready for review*" Make sure you read and follow [Contributor guidelines](https://github.com/NVIDIA/Model-Optimizer/blob/main/CONTRIBUTING.md) and your commits are signed (`git commit -s -S`). Make sure you read and follow the [Security Best Practices](https://github.com/NVIDIA/Model-Optimizer/blob/main/SECURITY.md#security-coding-practices-for-contributors) (e.g. avoiding hardcoded `trust_remote_code=True`, `torch.load(..., weights_only=False)`, `pickle`, etc.). - Is this change backward compatible?: ✅ - If you copied code from any other sources or added a new PIP dependency, did you follow guidance in `CONTRIBUTING.md`: N/A - Did you write any new necessary tests?: N/A - Did you update [Changelog](https://github.com/NVIDIA/Model-Optimizer/blob/main/CHANGELOG.rst)?: N/A <!-- This is an auto-generated comment: release notes by coderabbit.ai --> ## Summary by CodeRabbit * **Documentation** * Clarified that Direct Autotune is an advanced tool for Q/DQ placement experiments, not a replacement for full calibrated ONNX quantization. * Added guidance on when to use Direct Autotune versus the end-to-end ONNX PTQ workflow. * Documented the optional `autotune=True` setting, expected calibration-time impact, and representative calibration data requirements. * Expanded links and guidance across ONNX PTQ examples and updated CLI help text with the recommended workflow. <!-- end of auto-generated comment: release notes by coderabbit.ai --> --------- Signed-off-by: Gwenaelle Cunha Sergio <gcunhasergio@nvidia.com> |
||
|
Daniel Korzekwa
|
d39f385fb8 |
Save hf checkpoint at every valitation iteration during distillation. (#1897)
### What does this PR do? Save hf checkpoint at every valitation iteration during distillation. Addition functionality: - added `--validate_only` in `examples/megatron_bridge/distill.py` to enable computing validation losses for iter 0 - added `--reset_optimizer` in `examples/megatron_bridge/distill.py` to enable not using presaved optimizer, e.g., when changing the number of train iters. ### Usage - examples/megatron_bridge/distill.py - examples/megatron_bridge/README.md (line 228) ### Testing - tests/examples/megatron_bridge/test_distill.py ### Before your PR is "*Ready for review*" - Is this change backward compatible?: ✅ - Did you write any new necessary tests?: ✅ <!-- This is an auto-generated comment: release notes by coderabbit.ai --> ## Summary by CodeRabbit * **New Features** * Added `--validate_only` for student-only validation at iteration 0. * Added `--hf_validation_export_path` with `--hf_validation_export_interval` to export validated student HuggingFace artifacts during distillation. * Added `prepare_data_blend.py` for YAML-driven token-budgeted data blends. * Added `--max_tokens` to stop Megatron preprocessing after a token budget. * **Bug Fixes** * Validation exports avoid duplicate checkpoints, preserve the student architecture/config, and export only student artifacts. * **Documentation** * Expanded researcher and tutorial guides for iterative workflows and token-budgeted blends. * **Tests** * Updated distillation/blend/max_tokens test coverage, including validate-only and interval-based exports. <!-- end of auto-generated comment: release notes by coderabbit.ai --> --------- Signed-off-by: Daniel Korzekwa <dkorzekwa@nvidia.com> |
