mirror of
https://github.com/NVIDIA/Model-Optimizer.git
synced 2026-10-02 03:14:52 +08:00
main
103
Commits
| Author | SHA1 | Message | Date | |
|---|---|---|---|---|
 sychen52 |
333ace1bc9 |
Fix multi-turn synthetic generation and mark incomplete outputs (#2571)
### What does this PR do?

  Type of change: Bug fix

Fixes synthetic conversation generation that assumed alternating user
and assistant messages. That assumption skipped user turns in prompt
skeletons and mishandled
  leading system messages.

• Preserve conversation history. Regenerate every user turn while
retaining system messages and generated reasoning for subsequent
requests.
• Expose generation controls. Support model-specific request parameters,
configurable timeouts, and server-managed response budgets.
• Handle failures explicitly. Reject empty final answers and unsupported
tool calls. Failed conversations remain retryable without duplicating
saved output.
• Identify incomplete outputs. Mark length- and repetition-stopped
conversations as truncated, preserve stop metadata, and stop generating
follow-up turns.

  ### Usage

Run from the repository root against a compatible Qwen server with
reasoning parsing enabled:

  python examples/speculative_decoding/scripts/server_generate.py \
      --data_path input_conversations/train.jsonl \
      --output_path synthetic/train.jsonl \
      --url http://localhost:8000/v1 \
      --model model \
      --max_tokens 0 \
      --request_timeout 3600 \
--extra_body
'{"chat_template_kwargs":{"enable_thinking":true,"preserve_thinking":true}}'

The model name must match the server’s configured name. Filter truncated
conversations before training.

  ### Testing

  Focused regression tests: 15 passed.

The tests execute the command-line entry point using the real OpenAI
client library with mocked HTTP transport.

Coverage includes multi-turn generation, system prompts, reasoning
preservation, request parameters, failure recovery, resume
deduplication, truncation, and invalid
  responses.

  python -m pytest \
      --confcutdir=tests/examples/speculative_decoding \
      tests/examples/speculative_decoding/test_server_generate.py -q

The isolated test configuration avoids an unrelated parent configuration
import failure. All applicable pre-commit checks passed for the
generator, tests, and
  documentation.

  ### Before your PR is "Ready for review"

• Is this change backward compatible?: ✅ Existing valid inputs,
defaults, conversation output structure, and resume behavior remain
supported. Invalid inputs and
    failed requests now raise errors instead of being silently accepted.

• Copied code or new PIP dependencies?: N/A. No new third-party code or
dependencies were added.
• Did you write any new necessary tests?: ✅ Added focused command-line
regression tests.
• Did you update Changelog?: N/A. These are example-script correctness
fixes, not critical released library fixes.
  • Did you get Claude approval on this PR?: ❌ Not yet obtained.

  ### Additional Information


<!-- This is an auto-generated comment: release notes by coderabbit.ai
-->
## Summary by CodeRabbit

* **New Features**
* Data generation supports `conversations` and `messages` inputs,
preserves reasoning content, and accepts additional chat settings and
configurable request timeouts.
* Failed conversations are recorded separately, with options to retry
failures or exit when errors occur. Resume behavior distinguishes
retryable failures from rejected inputs.
* Outputs identify conversations truncated by length or repetition
limits.

* **Documentation**
* Updated data preparation guides with generation setup, input formats,
failure handling, resuming, and training guidance.
<!-- end of auto-generated comment: release notes by coderabbit.ai -->

---------

Signed-off-by: Shiyang Chen <shiychen@nvidia.com>
|
||
|
h-guo18andClaude Opus 5
|
87f7d1432f |
fix(speculative): hold the DFlash draft's fp32 master weights in the optimizer (#2483)
### What does this PR do? Type of change: Bug fix **Follow-up to #2342**, which split this out on review (commit `c67784d9`), and a rethink of how the flag is implemented. `dflash_fp32_master_weights` exists because the DFlash draft is cast to the frozen bf16 target's dtype, so AdamW allocates its moments in bf16 — and bf16 is too coarse to hold them. At `beta2=0.999` a single step changes `v` by at most **0.100%**, while the smallest change bf16 can represent near `v` is **0.164% mean / 0.388% max** (measured): every decrease rounds away, `v` only grows, and the effective step size decays on its own from step 1. #2342 fixed that by **promoting the draft model to fp32**. Everything else followed from giving the model a dtype the rest of it does not have — a bf16 autocast at every entry point, two transformers loader hints so `from_pretrained(dtype="auto")` would not round the draft away, a post-condition check because those hints fail silently, and a doubled DDP gradient all-reduce. **This PR puts the fp32 in the optimizer instead**, where Megatron-LM, DeepSpeed and apex put it. `MasterWeightAdamW` holds an fp32 master copy of each non-fp32 parameter plus fp32 moments in `self.state[p]`, steps on the master, and copies back at the parameter's dtype. The model is never anything but the base dtype, so every one of those follow-on pieces is deleted, gradients stay bf16, and the exported drafter is unchanged. What the placement costs is that wiring the optimizer becomes the training loop's job: `EagleTrainerWithAccLog.create_optimizer` builds it, and `VerifyMasterWeightsCallback` raises at the end of step 1 if the moments are not fp32. **The default flips to `True`** — the flag now changes optimizer memory and optimizer arithmetic and nothing else. Flipping it on the model-promoted implementation turns **25 of 259** unit tests red; flipping it here is **259 passed**. Set it to `False` to reclaim the memory, about 12 bytes per draft parameter instead of 4. <details> <summary>Three drive-by fixes, independent of the above</summary> - `_place_draft` is folded back into `modify()` — it fused the draft's dtype, its device and an eager rotary buffer behind one meta guard. - The module docstring's claim that `DFlashModule` has an `_apply` meta-buffer fix is removed (`grep "def _apply"` matches nothing, and never did). - #2342's field description no longer lists `evaluation` as a broken path — `forward` short-circuits to the base model when `not self.training`, so the draft never runs there. </details> ### Usage No API change. `dflash_fp32_master_weights` now means the *optimizer* holds fp32 master weights rather than the draft model being fp32. ### Testing **1 · The refactor is arithmetically a no-op.** Both implementations run AdamW on an fp32 tensor, so given the same starting values and the same gradients the trajectories are identical — 1000 steps, `weight_decay=0.01`: ``` old fp32 parameter vs new fp32 master : bitwise equal = True (max |diff| 0.0e+00) exp_avg / exp_avg_sq : bitwise equal = True optimizer state dtypes : ['torch.float32'] model parameter dtype : torch.bfloat16 ``` Initial values have to be matched at bf16 first, or the bf16 arm's one-time rounding of the draw shows up as a 2e-4 "difference" that is not arithmetic. With that controlled, the two implementations differ only in their *inputs*: gradient precision (fp32 vs bf16 — torch 2.10 requires `grad.dtype == param.dtype`) and that one-time rounding. **2 · End to end on GPU: the effect survives the refactor.** Qwen3-1.7B base, real corpus, one GPU per arm, three arms — pure bf16 (flag off), the #2342 implementation, and this one — on two algorithms trained independently, sharing seed, data order and initialisation within an algorithm. <img width="2925" height="960" alt="image" src="https://github.com/user-attachments/assets/40d37059-ab8a-4924-b049-85f76b70b156" /> The two fp32 arms sit on top of each other for the whole run while bf16 stays above both, and the old-vs-new gap is 10–23× smaller than the fp32-vs-bf16 effect it has to be compared against. **Acceptance length says the same thing, and settles what the loss could not.** All six drafters at the end of those curves were exported and served under vLLM against the same base, and measured on MT-Bench (80 prompts, 8 categories, greedy, one request at a time, `num_speculative_tokens` = trained `block_size` − 1, every knob but the drafter held fixed): | | pure bf16 | fp32 in model (#2342) | fp32 in optimizer (this PR) | new − old | fp32 − bf16 | |---|---|---|---|---|---| | `dflash` | 1.3068 | 1.3708 | **1.3666** | −0.0042 `t=−0.90` | +0.0619 `t=+13.8` | | `lilicorr` | 1.2536 | 1.2814 | **1.2882** | +0.0068 `t=+1.42` | +0.0312 `t=+9.2` | Paired by prompt, n=80. On both algorithms the new-vs-old 95% CI straddles zero (`dflash` [−0.0134, +0.0051], `lilicorr` [−0.0028, +0.0164]) while fp32-vs-bf16 does not come close to it, and the sign of new-vs-old **flips between the two algorithms** — what a rounding difference looks like, not a bias. This is also the comparison the training loss could not give: all three arms are **exported and served in bf16**, so the old implementation's fp32 draft weights are rounded at export exactly as they would be for deployment, and the "its loss was computed on a more precise forward" caveat below does not apply. `lilicorr` needs [vllm-project/vllm#57934](https://github.com/vllm-project/vllm/pull/57934), applied as an overlay so that both algorithms are measured on one engine build. The right panel is the mechanism, and the one signal that depends on neither the seed nor the choice of loss statistic: Adam's updates to the draft's RMSNorm gains are smaller than the bf16 ULP at 1.0 (0.0078), so in the bf16 arm every one of them rounds away and the gains never move — not one of `dflash`'s 14 in 30000 steps, and two of `lilicorr`'s 20 by 3e-06. Both fp32 arms move all of them, by the same amount. Two results behind the figure rather than in it. **fp32-vs-bf16 grows with the horizon** while old-vs-new does not — on `dflash` −0.129 at 1500 steps → −0.262 at 15000 → −0.341 at 30000, and on `lilicorr` −0.191 → −0.220 → −0.285, against an old-vs-new difference that stays near 0.02 at every horizon and changes sign between them (−0.026 → +0.028 on `lilicorr`). That is what a compounding bias and a rounding difference respectively should look like, and it is the reason the longer runs were worth doing. And **across seeds**, the paired old-vs-new difference at 1500 steps is +0.0003 (n=6) on `dflash` and +0.0643 (n=10) on `lilicorr`, both with a 95% CI straddling zero. <details> <summary>Limits of the above, stated rather than smoothed over</summary> At 5 seeds the `lilicorr` paired difference read +0.1610 ± 0.0557 (t=+2.89, 4/5 seeds in the same direction) — nominally significant, suggesting the new implementation was genuinely worse there. Four further `lilicorr` seeds were run against that pre-declared question; two came back strongly negative and the estimate settled at +0.0643 (95% CI [−0.086, +0.214]). The earlier reading was small-sample noise. At 1500 steps on `lilicorr` that CI is *not* narrower than the fp32-vs-bf16 effect it is being compared against, so the 1500-step sweep alone cannot certify equivalence there — `lilicorr` is still at loss 9.3 and deep in its early transient, and it is the long runs that resolve it. On `dflash` the 1500-step CI (±0.031) is already 4× tighter than the effect (−0.129). One asymmetry the loss comparison cannot separate: the old implementation held the draft weights in fp32 *at forward time*, so its training loss was computed on a more precise forward, while both implementations export bf16. Any residual advantage it appears to have is therefore an upper bound. </details> **3 · Unit tests.** `tests/unit/torch/speculative/` — **259 passed** on **transformers 5.0.0** and **5.3.0**, both ends of the supported `>=5.0,<5.13` (CPU, torch 2.10). `TestDFlashFp32MasterWeights` is rewritten for the new mechanism; the two that would have caught the traps in this design are `test_resume_does_not_round_the_master_back_down` (`Optimizer.load_state_dict` casts float state to its parameter's dtype, so a naive subclass rounds the master and both moments to bf16 on *every* resume, silently, with the loss still falling) and `test_the_callback_refuses_a_loop_that_forgot_the_optimizer`. The rest cover the draft's dtype with the flag either way, that no forward path needs an autocast any more, that plain AdamW really does leave the moments in bf16, and that an fp32 model allocates no redundant master. A sharded FSDP2 `DTensor` keeps an fp32 master and fp32 moments through a step. ### Before your PR is "*Ready for review*" - Is this change backward compatible?: ✅ for artifacts, with one intentional default change. The draft's stored dtype goes back to matching the base, as it was before #2342; existing checkpoints load unchanged and the exported drafter is unaffected. The flag now defaults to **`True`** — the measurements above are the reason, and the cost is fp32 master + fp32 moments for the draft only. A training loop that builds its own optimizer instead of using the shipped `create_optimizer` gets plain AdamW and none of this; `VerifyMasterWeightsCallback` makes that fail loudly at step 1 rather than skip the feature quietly. - If you copied code from any other sources or added a new PIP dependency, did you follow guidance in `CONTRIBUTING.md`: ✅ — no new dependencies. - Did you write any new necessary tests?: ✅ - Did you update [Changelog](https://github.com/NVIDIA/Model-Optimizer/blob/main/CHANGELOG.rst)?: ✅ - Did you get Claude approval on this PR?: ❌ — draft; will run `/claude review` before marking ready. ### Additional Information **On the 7–14% acceptance-length gain quoted in #2342:** that was measured on the fp32-model arithmetic and is not re-derived here. What is measured above is the like-for-like comparison this PR has to answer — same corpus, same horizon, same serving path, one implementation swapped. **History:** commits 1–3 restore the autocast design as it was split out; commits 4–6 replace it. Happy to squash before review. <details> <summary>Alternatives measured and rejected, so they do not get re-proposed</summary> - **Swapping `p.data` to the master and calling `super().step()`** (reuses all of AdamW, ~20 lines instead of ~50): bit-identical on ordinary parameters over 25 steps, but silently wrong under FSDP2 — assigning `.data` on a `DTensor` parameter updates the wrapper's reported dtype while the local shard keeps the model's, so `p.dtype` reads fp32, `p.data.dtype` reads bf16, and `zeros_like(p)` allocates the moments in bf16 anyway. CPU tests pass either way. - **Narrowing the autocast from `__call__` to `forward`** (while it still existed): turns 10 Domino/DSpark tests red — the variants apply their heads in their own `forward` overrides, outside `DFlashModule.forward`. - **Building the rotary buffer on meta and letting the loader materialise it**: makes RoPE correctness depend on transformers selecting a branch by class-name substring (`"RotaryEmbedding" in module.__class__.__name__`), and the `if not hasattr` guard is then permanently satisfied, so a later `to_empty()` leaves garbage forever — measured `4.56e-41`, i.e. cos=1 / sin=0, no positional encoding at all. - **Building it eagerly in `DFlashModule.__init__`**: lands before the dtype cast, so `Module.to` rounds the RoPE frequencies to bf16 on the default path — measured `0.8659643530845642` → `0.8671875`, loss `3.47230935097` → `3.47114777565`. </details> 🤖 Generated with [Claude Code](https://claude.com/claude-code) <!-- This is an auto-generated comment: release notes by coderabbit.ai --> ## Summary by CodeRabbit - **New Features** - DFlash now uses FP32 optimizer master weights and Adam moments by default while keeping draft parameters in the base model’s dtype. - Master-weight training preserves optimizer precision when restoring checkpoints. - The feature can be disabled to reduce optimizer memory usage. - Draft models consistently follow the base model’s dtype and device. - **Bug Fixes** - DFlash workflows now support operation without autocast. - Added validation for compatible AdamW-family optimizers and master-weight precision, including resumed training runs. <!-- end of auto-generated comment: release notes by coderabbit.ai --> --------- Signed-off-by: h-guo18 <67671475+h-guo18@users.noreply.github.com> Co-authored-by: Claude Opus 5 (1M context) <noreply@anthropic.com> |
||
|
|
835c041c58 |
fix(specdec): resolve the eagle aux-layer preset in the vLLM hidden-state dump (#2410)
### What does this PR do? Type of change: Bug fix Fixes `nvbugs/6753684`, filed against #2080 by the ModelOpt QA Sentinel. The vLLM offline hidden-state dump rejected `--aux-layers eagle` — **the flag's own default** — so the documented invocation aborted before writing any state: ``` File "collect_hidden_states/compute_hidden_states_vllm.py", line 76, in _resolve_aux_layers_standalone ids = sorted({int(t) for t in aux_layers.split(',') if t.strip()}) ValueError: invalid literal for int() with base 10: 'eagle' ``` **Root cause.** `compute_hidden_states_vllm.py` runs in a stock vLLM container, where importing `modelopt.torch` fails (the full init chain pulls in omegaconf and friends). It therefore carries `_resolve_aux_layers_standalone`, a local copy of the preset logic in `common.resolve_aux_layers`. That copy implemented the `dflash` preset and explicit id lists, but never `eagle` — while `add_aux_layers_args` defaults to `eagle`. The HF and TRT-LLM dumps call the shared helper and were unaffected; only the vLLM path forked, and nothing compared the fork against its source. This PR resolves `eagle` inline, mirroring `hf_eagle.default_eagle_aux_layer_ids`. It also fixes a second defect the bug exposes: the function already had a message naming the accepted values, but it was unreachable, because `int()` raised first. An unrecognised preset now reports what it accepts instead of surfacing the raw `int()` error — which is what made the original failure opaque. ### Usage The previously-broken documented invocation now works: ```bash cd examples/speculative_decoding python collect_hidden_states/compute_hidden_states_vllm.py \ --model Qwen/Qwen2.5-0.5B-Instruct \ --input-data ../dataset/synthetic_conversations_1k.jsonl \ --output-dir /tmp/hs_vllm \ --max-seq-len 512 --tp 1 ``` `--aux-layers dflash` and explicit lists such as `--aux-layers 2,5,8` are unchanged. ### Testing Added `tests/unit/examples/test_vllm_hidden_states_aux_layers.py`, which pins the standalone copy to the shared implementation it mirrors: - `eagle` matches `hf_eagle.default_eagle_aux_layer_ids` across layer counts 4, 6, 8, 12, 24, 28, 32, 36, 48, 52, 61, 80 — deliberately including counts small enough that the `max(0, ...)` clamps collapse ids together. - A named regression case for `nvbugs/6753684`. - `dflash` and explicit-list behaviour unchanged. - Unknown specs (`bogus`, `EAGLE3`, `eagle3`, empty) raise the actionable message. - Out-of-range ids still rejected. Divergence here is silent — the dump would write plausible-looking hidden states from the *wrong* layers, surfacing much later as a poor acceptance rate. Hence pinning to the reference rather than asserting hardcoded lists alone. All 20 assertions verified and every pre-commit hook passes (`ruff`, `mypy`, `bandit`, RST lint, license headers). One caveat worth stating plainly: **pytest could not be run locally.** `tests/unit/conftest.py` imports `modelopt.torch.utils.distributed`, which needs `CPUOffloadPolicy` from `torch.distributed.fsdp` — absent in this machine's torch. Each assertion was executed directly against the real module instead, but CI is the first genuine pytest run. ### Before your PR is "*Ready for review*" - Is this change backward compatible?: ✅ — strictly widens accepted input; `dflash` and explicit lists behave identically. - If you copied code from any other sources or added a new PIP dependency, did you follow guidance in `CONTRIBUTING.md`: N/A - Did you write any new necessary tests?: ✅ - Did you update [Changelog](https://github.com/NVIDIA/Model-Optimizer/blob/main/CHANGELOG.rst)?: ✅ — bug fix for a defect present in a previous release. - Did you get Claude approval on this PR?: ❌ — not yet run. ### Additional Information The underlying fragility is the duplicated implementation, not this one missing branch. The function's own `TODO: drop this once common.resolve_aux_layers is decoupled from the heavy modelopt.torch import chain` is the real fix; the new test narrows the gap but does not close it. Worth tracking separately if the vLLM dump is expected to keep pace with new presets. 🤖 Generated with [Claude Code](https://claude.com/claude-code) <!-- This is an auto-generated comment: release notes by coderabbit.ai --> ## Summary by CodeRabbit * **Bug Fixes** * Fixed `--aux-layers eagle` for vLLM offline hidden-state collection. * Added support for the documented `eagle` preset alongside `dflash` and explicit layer IDs. * Improved invalid-option errors to clearly list accepted formats. * Rejects `dflash` configurations when the target model has too few layers. * Continues rejecting layer IDs outside the model’s available range. * **Documentation** * Added a v0.48.0 changelog entry for the fix. <!-- end of auto-generated comment: release notes by coderabbit.ai --> --------- Signed-off-by: Ye Yu <yeyu@nvidia.com> Co-authored-by: Claude Opus 5 <noreply@anthropic.com> Co-authored-by: Keval Morabia <28916987+kevalmorabia97@users.noreply.github.com> |
||
|
yeyu-nvidiaandClaude Opus 4.8
|
9d0df45849 |
specdec: config_overrides for nested text_config checkpoints + load VLM-capable bases in merge_lora (#2289)
### What does this PR do?

Type of change: New feature + bug fix

Two related gaps, both hit while enabling EAGLE3 on a checkpoint whose
config nests its text dims.

**1. `config_overrides` for checkpoints whose `text_config` dims don't
propagate.**
Some multimodal checkpoints carry the real text-tower dims only under
`config.text_config`, leaving the parent fields `None`.
`from_pretrained` then builds a text tower with the wrong shape.
`load_vlm_or_llm` gains an optional `config_overrides` dict applied to
*both* the parent config and its `text_config` before instantiation, and
the three entrypoints that load checkpoints — `ar_validate.py`,
`export_hf_checkpoint.py`, `merge_lora.py` — get a `--config_overrides`
passthrough. `main.py` threads it from `ModelArguments`.

**2. `merge_lora.py` could not merge into any VLM base.**
It loaded via `AutoModelForCausalLM`, which cannot load architectures
absent from the CausalLM Auto map — every VLM base failed. It now goes
through `load_vlm_or_llm`, which routes VLMs to
`AutoModelForVision2Seq`/`AutoModelForImageTextToText` and plain LLMs to
`AutoModelForCausalLM` with the same `dtype`/`device_map`, so LLM
behavior is byte-for-byte unchanged.

Also adds an optional `transformers_cosmos3` import so `cosmos3_omni` is
registered with `AutoConfig` before use, and dispatches that
`model_type` to its model class directly — that plugin registers only a
*config*, never a model under `Auto*`, so `AutoModelForCausalLM` raised
`KeyError('cosmos3_omni')` regardless of imports. The import is wrapped
in `contextlib.suppress(ImportError)`, so it is a no-op when the plugin
isn't installed.

### Usage

```bash
# Checkpoint whose real dims live under config.text_config
python examples/speculative_decoding/scripts/ar_validate.py \
    --model_path <ckpt> --trust_remote_code \
    --config_overrides '{"num_hidden_layers": 36, "intermediate_size": 12288, "num_key_value_heads": 8}'

# Same flag on export and merge
python examples/speculative_decoding/scripts/export_hf_checkpoint.py \
    --model_path <ckpt> --export_path <out> --config_overrides '{"num_hidden_layers": 36}'
python examples/speculative_decoding/scripts/merge_lora.py \
    --base_model_path <base> --exported_lora_dir <out> --output_path <merged> \
    --config_overrides '{"num_hidden_layers": 36}'
```

```python
model = load_vlm_or_llm(path, config_overrides={"num_hidden_layers": 36})  # default None
```

### Testing

Exercised end-to-end on a Cosmos3-Nano (16B, 36-layer text tower) EAGLE3
LoRA run:

- **Training** — the base loads with all 36 text layers and correct
dims; two 4-epoch co-training runs completed (46,816 steps each).
- **Export + merge** — produced `adapter_model.safetensors` and a merged
base. Verified correct by per-layer weight diff: a `start_layer=18` run
changed **exactly** layers 18-35, with layers 0-17 bit-identical to the
base.
- **AR validation** — `--config_overrides` loads the trained checkpoint;
80/80 MT-Bench samples, AR 3.42.
- **Regression check** — `merge_lora` via `load_vlm_or_llm` produces a
base loadable by `lm_eval`; ifeval/arc_challenge/winogrande all ran to
completion.

No local unit-test run: `nvidia-modelopt` isn't installed in my
checkout, so `tests/conftest.py` fails to import. Relying on CI.

### Before your PR is "*Ready for review*"

- Is this change backward compatible?: ✅ — `config_overrides` defaults
to `None`; the `merge_lora` loader swap keeps the same class, dtype and
device_map for plain LLMs.
- If you copied code from any other sources or added a new PIP
dependency, did you follow guidance in `CONTRIBUTING.md`: N/A — no new
dependency; `transformers_cosmos3` is an optional import guarded by
`contextlib.suppress`.
- Did you write any new necessary tests?: ❌ — exercising these paths
needs a checkpoint with a nested `text_config`, which the unit suite has
no fixture for. Happy to add one if a reviewer can point me at a small
suitable model.
- Did you update
[Changelog](https://github.com/NVIDIA/Model-Optimizer/blob/main/CHANGELOG.rst)?:
❌ — can add a *Speculative Decoding* entry for the `merge_lora` VLM fix
if you consider it changelog-worthy.
- Did you get Claude approval on this PR?: ❌ — not yet run.

<!-- This is an auto-generated comment: release notes by coderabbit.ai
-->
## Summary by CodeRabbit

- **New Features**
- Added JSON-based model configuration overrides across speculative
decoding, training, validation, export, and LoRA workflows.
  - Overrides can update primary model and text configuration settings.
- Expanded support for vision-language models and Cosmos3 Omni
checkpoints.

- **Bug Fixes**
- Improved configuration handling for offline loading and
checkpoint-based initialization.
- Restored draft-model precision during checkpoint loading and model
conversion.
- Added validation for malformed, unsupported, and non-finite override
values.
- Standardized configuration override guidance across command-line
workflows.
<!-- end of auto-generated comment: release notes by coderabbit.ai -->

---------

Signed-off-by: Ye Yu <yeyu@nvidia.com>
Co-authored-by: Claude Opus 4.8 (1M context) <noreply@anthropic.com>
|
||
|
yeyu-nvidiaandClaude Opus 4.8
|
279d510616 |
fix(specdec): correct resume and bound staging in the vLLM hidden-state dump (#2080)
### What does this PR do?

**Type of change:** Bug fix

Fixes two issues in the vLLM offline hidden-state dump

(`examples/speculative_decoding/collect_hidden_states/compute_hidden_states_vllm.py`).
Both are invisible on small dumps and only bite at scale, which is why
they survived until
now — they were found while dumping ~194k conversations for a MiniMax-M3
draft.

**1. Resume silently re-processed already-finished work.**

`keep_conversation` skips conversations whose `.pt` already exists, but
that predicate reads
**on-disk state**, which is not part of the fingerprint `datasets`
computes for `filter()`
(it hashes the function and the dataset). With a persistent HF cache
reused across a resumed
or requeued run, the cached *"keep everything"* result from an earlier
run — computed when
few or no `.pt` files existed — is replayed. The run then re-generates
and **overwrites**
conversations it had already completed, and reports `Removed 0
conversations due to existing
output files` while doing so.

Observed on a 194k-conversation dump: ~62k `.pt` rewritten over a
two-hour window with the
total output count completely flat.

Fix: pass `load_from_cache_file=False` so the filter re-checks the disk
on every run.

**2. Staging exhausted `/dev/shm` partway through large dumps.**

The script generated the **entire** dataset before saving anything. The
KV connector stages
each conversation's hidden states under its `shared_storage_path`
(`/dev/shm`, i.e. RAM, by
default) and they are only freed by `cleanup_hidden_states()` in the
save loop — so every
conversation stayed staged simultaneously. On a large dump this exhausts
the space and the
connector starts failing writes:

```
Hidden-states write failed for req_id=...:
  SafetensorError('Error while serializing: I/O error: No space left on device (os error 28)')
```

Fix: generate and save in chunks of `--save-chunk-size` (default 256),
so at most one chunk
is staged at a time. As a side benefit the dump becomes **incrementally
durable** — an
interrupted run (walltime limit, node failure) keeps its finished
conversations and the
resume path above continues from them, instead of losing the whole run's
work.

### Testing

- Reproduced both failures on a 194k-conversation MiniMax-M3 dump (8-way
DP, TP8), and
confirmed both fixes on the same workload: after the change the output
count advanced
monotonically across requeues (123k → 194k) with no rewrites, and
`/dev/shm` stayed bounded
  through completion.
- `pre-commit run --files ...` passes (ruff check/format, mypy, bandit,
license, rst checks).
- Behavior is unchanged for a fresh single-shot dump other than the
chunked generate calls;
  the default `--save-chunk-size 256` is the only new knob.

### Additional Information

Extracted from #1749, which is otherwise superseded by the streaming
DFlash/DSpark path — these
two fixes are model-agnostic and apply to any offline dump, so they are
worth landing on their
own.

### Before your PR is "*Ready for review*"

- **Make sure you read and follow [Contributor
guidelines](https://github.com/NVIDIA/Model-Optimizer/blob/main/CONTRIBUTING.md)**
and your commits are signed.
- **Is this change backward compatible?**: Yes
- **Did you write any new necessary tests?**: No — the failure modes are
multi-process/at-scale (datasets cache reuse across runs, connector RAM
staging) and are not reproducible in the unit-test harness.
- **Did you add or update any necessary documentation?**: Yes —
CHANGELOG entry.
- **Did you update
[Changelog](https://github.com/NVIDIA/Model-Optimizer/blob/main/CHANGELOG.rst)?**:
Yes


<!-- This is an auto-generated comment: release notes by coderabbit.ai
-->
## Summary by CodeRabbit

* **New Features**
  * Added chunked hidden-state generation for large vLLM offline runs.
* Added a configurable save-chunk size, defaulting to 256 conversations.
  * Enabled incremental saving and resumption of hidden-state outputs.

* **Bug Fixes**
* Improved resume filtering to accurately detect existing output files.
  * Reduced memory usage by saving and releasing each generated chunk.
* Ensured temporary files are cleaned up after interrupted or skipped
saves.
  * Added atomic output-file replacement to prevent incomplete results.
* Added validation to prevent invalid conversation IDs from creating
unsafe paths.
<!-- end of auto-generated comment: release notes by coderabbit.ai -->

---------

Signed-off-by: Ye Yu <yeyu@nvidia.com>
Co-authored-by: Claude Opus 4.8 <noreply@anthropic.com>
|
||
|
yeyu-nvidia
|
56af187565 |
ar_validate: fail loudly when every sample fails (#2288)
### What does this PR do?

Type of change: Bug fix

`validate_ar()` catches per-sample exceptions, prints a `WARNING`, and
returns whatever succeeded. When *every* sample failed it returned an
empty list, and the reporting block was guarded by `if results and
accelerator.is_main_process:` — so the script printed no results and
exited **0**. A run where 100% of samples failed was indistinguishable
from a successful one.

This bit us on a real run: an EAGLE3 checkpoint loaded with
`device_map="auto"` was sharded across 8 GPUs, every one of the 80
samples died with `Expected all tensors to be on the same device`, and
the job still exited 0 with no AR number anywhere in the log — the
wrapper stamped it PASS.

Now it raises, so the caller sees a non-zero exit. Any previously
"passing" run that printed no AR number was never meaningful.

### Usage

No API change. Existing invocations are unaffected when at least one
sample succeeds:

```bash
python examples/speculative_decoding/scripts/ar_validate.py \
    --model_path <ckpt> --steps 3 --osl 1024 --num_samples 80
```

### Testing

Reproduced the silent-pass on a Cosmos3-Nano EAGLE3 checkpoint (80/80
samples failing): before this change the job exited 0 and stamped PASS;
after it, the job exits non-zero with the sample failures visible.
Confirmed the normal path is unchanged by a subsequent run that
completed 80/80 and printed AR 3.42.

### Before your PR is "*Ready for review*"

- Is this change backward compatible?: ✅ — only affects the
all-samples-failed case, which previously produced no output and a
misleading exit 0.
- If you copied code from any other sources or added a new PIP
dependency, did you follow guidance in `CONTRIBUTING.md`: N/A
- Did you write any new necessary tests?: ❌ — the failure path requires
a model that errors during AR validation; the existing suite has no
harness for that.
- Did you update
[Changelog](https://github.com/NVIDIA/Model-Optimizer/blob/main/CHANGELOG.rst)?:
N/A — behavior fix in an example script, not a released-feature change.
- Did you get Claude approval on this PR?: ❌ — not yet run.

<!-- This is an auto-generated comment: release notes by coderabbit.ai
-->
## Summary by CodeRabbit

* **Bug Fixes**
  * Improved validation error handling when all samples fail.
  * Validation now rejects non-positive sample counts before processing.
* Empty validation results are clearly distinguished from cases where
all samples fail.
* Error messages report the actual number of validation samples
attempted, capped at the available dataset size.
  * Empty validation results are no longer reported as successful.
<!-- end of auto-generated comment: release notes by coderabbit.ai -->

---------

Signed-off-by: Ye Yu <yeyu@nvidia.com>
|
||
|
|
2d35643452 |
LiLiCorr training (#2342)
### What does this PR do? Type of change: new feature Adds **LiLiCorr**, a candidate-lattice reranker for DFlash drafts, as a new `projector_type` on the existing `dflash` mode — plus three DFlash-wide improvements that apply to every variant, and an optional composition with DFlash2's grouped convolutions. A DFlash drafter is trained on per-position marginals rather than on the joint block distribution, so its drafted tokens are individually plausible yet jointly incoherent. LiLiCorr keeps the top-`k` candidates the backbone already produces at each block position, scores transitions between adjacent candidates with a small two-layer transformer, and commits a path through the lattice greedily. Serving is unchanged in kind: verify still checks every drafted token against the target, so the emitted distribution is untouched and only acceptance length moves. - Paper: [LiLiCorr: Lightweight Likelihood Correlation of Parallel Drafts for Speculative Decoding](https://arxiv.org/abs/2608.20530) (arXiv:2608.20530) - Blog: https://research.nvidia.com/labs/nemotron/lilicorr/ - **Companion PR — serving support:** [sgl-project/sglang#37462](https://github.com/sgl-project/sglang/pull/37462) This PR is the **training** half. It trains the drafters and exports them; the companion PR above is what serves the resulting checkpoints, and is what the comparison table below was measured through. **What is in the commits** | | | | --- | --- | | LiLiCorr draft variant | `hf_lilicorr.py`, `modeling_lilicorr.py`, conversion routing, config fields, export | | Three DFlash-wide features | fp32 master weights for the draft, draft activation checkpointing, and a DDP hang fix — all default-off or behaviour-preserving, all applying to `dflash`, `domino`, `dspark` and `dflash2` alike | | Optional grouped convolutions | composes LiLiCorr with DFlash2's `DFlashGroupedConv`; see the dependency note below | | Two recipes | `lilicorr.yaml` and `lilicorr_conv.yaml` | | CPU unit tests, CHANGELOG, one launcher example | | **⚠️ The convolutions depend on the DFlash2 branch, and cannot run until it merges.** `modeling_lilicorr.py` imports `DFlashGroupedConv` from `modeling_dflash2`, which today exists only on `haoguo/dflash2-support`. The class is **imported rather than copied on purpose** — it is the only way the two variants cannot drift apart arithmetically — but the consequence is that the convolutional recipe cannot run against `main` as it stands. So the import is **deferred into `_install_sublayer_convs`** rather than taken at module scope. Everything else in this PR, including the plain LiLiCorr reranker, has no DFlash2 dependency at all and works on `main` today; an eager import would have made the whole plugin unimportable for the sake of one optional feature. Requesting the convolutions without DFlash2 present raises an `ImportError` naming the two config keys to remove, rather than failing at import time. **This PR carries two of @h-guo18's commits, with authorship and sign-off preserved.** Both are independent of DFlash2 itself and both are needed here: - `1419d47e`, the no-op sublayer seam. Without it `DFlashDecoderLayer.forward` never calls the wrappers the convolutions install onto, so the modules would be built, counted and exported while computing nothing. It is arithmetically an identity on its own. - `ba377e7a`, the RoPE-θ fix. On Transformers 5 a config carries both a top-level `rope_theta` and a `rope_parameters` dict; the real base lives in the dict while the class default (10,000 for Qwen3) stays visible as the flat attribute. Reading the flat field first builds a draft whose RoPE base is 100× off a Qwen3-8B target's, which trains and exports without complaint. Both the training-side enforcement and the exporter's `_get_rope_theta` are affected on `main` today. Both are @h-guo18's work and belong to their branches; they are carried here only so that this PR stands on its own. **If those branches land first, this PR can be rebased onto them and the two commits dropped**, and they can equally be split out now if that is easier to review. The same applies to `dflash_fp32_master_weights`, which is also in flight on `haoguo/dflash-fp32-master-weights`. The field name is shared deliberately so that there is only ever one knob rather than two spellings of it, and both versions default to off. Whichever lands first, this PR can be rebased onto it. ### Usage Train with the shipped recipe: ```python from modelopt.recipe import load_recipe config = load_recipe("general/speculative_decoding/lilicorr.yaml") # Qwen3-8B target, 6 epochs, block size 16 (15 drafted slots, 16 verified), # DFlash decay objective at gamma 7.0, fp32 master weights for the draft. ``` Or convert directly: ```python import modelopt.torch.speculative as mtsp config = { "dflash_block_size": 16, "dflash_loss_objective": "decay", "dflash_loss_decay_factor": 7.0, "dflash_fp32_master_weights": True, "dflash_lilicorr_w_ce": 0.25, "dflash_lilicorr_w_margin": 0.0, "dflash_lilicorr_w_pen": 0.25, "dflash_architecture_config": { "num_hidden_layers": 5, "projector_type": "lilicorr", "lilicorr_candidate_topk": 8, # Optional, and all-or-nothing: adding these two keys wraps every draft # sublayer in DFlash2's grouped convolution. Requires the DFlash2 variant. # "conv_kernel_size": 2, # "conv_group_size": 16, }, } mtsp.convert(model, [("dflash", config)]) ``` ### Results Six drafters for a **Qwen3-8B** target, all trained **in ModelOpt on one matched contract** — the same corpus, schedule and block geometry for every arm, so no row carries a training advantage. Training data is NVIDIA's [Nemotron Post-Training Dataset v2](https://huggingface.co/datasets/nvidia/Nemotron-Post-Training-Dataset-v2) with the multilingual split excluded, generated from the target with **thinking disabled**; **6 epochs**; block size 16 (15 drafted slots, 16 verified); DFlash decay objective at gamma 7; **8 nodes × 8 H100, global batch size 64** (one sequence per device, no gradient accumulation). All six were then exported and served through SGLang on a **single H100 80GB**, `tp_size 1`, at concurrency 1, greedy, `fa3`, mean of two replicates, with the whole node held exclusive per benchmark. Speedup is output tokens/s against an autoregressive baseline measured in the same allocation. Cells are `acceptance length / speedup-vs-AR`; **★ fastest, ☆ second fastest**: | benchmark | LiLiCorr+conv | LiLiCorr | DSpark | DFlash2 | Domino | DFlash | |---|---|---|---|---|---|---| | gsm8k | ★ 7.715 / 5.26x | ☆ 7.557 / 5.22x | 7.375 / 4.86x | 7.252 / 5.06x | 7.225 / 4.87x | 6.341 / 4.59x | | math500 | ★ 9.241 / 6.54x | ☆ 9.064 / 6.52x | 9.012 / 6.15x | 8.999 / 6.49x | 8.976 / 6.25x | 7.909 / 5.88x | | aime25 | ★ 8.285 / 6.03x | ☆ 8.156 / 6.03x | 8.043 / 5.61x | 7.967 / 5.91x | 8.066 / 5.77x | 7.126 / 5.44x | | humaneval | ★ 7.393 / 4.01x | 7.077 / 3.93x | 7.163 / 3.72x | ☆ 7.081 / 3.95x | 6.864 / 3.73x | 6.156 / 3.68x | | mbpp_sanitized | ★ 5.999 / 4.18x | ☆ 5.849 / 4.13x | 5.888 / 3.95x | 5.685 / 4.05x | 5.679 / 3.91x | 5.027 / 3.70x | | livecodebench | ★ 7.975 / 5.40x | ☆ 7.754 / 5.33x | 7.775 / 5.10x | 7.601 / 5.26x | 7.553 / 5.04x | 6.808 / 4.88x | | alpaca_eval | ☆ 3.697 / 2.69x | ★ 3.656 / 2.70x | 3.588 / 2.52x | 3.467 / 2.58x | 3.627 / 2.59x | 3.222 / 2.46x | | mtbench | ★ 4.014 / 2.94x | ☆ 3.939 / 2.93x | 3.957 / 2.78x | 3.748 / 2.80x | 3.948 / 2.84x | 3.478 / 2.67x | **Against every other approach in the table, LiLiCorr with convolutions is the fastest on all eight benchmarks.** Plain LiLiCorr is the fastest on seven of the eight; the exception is humaneval, a 164-prompt slice, where DFlash2 is ahead by 0.5%. `DFlash` is the deliberately head-free control; every head clears it by +7.60% to +21.67% on acceptance, which is the check that a head actually loaded. Reproducing the `LiLiCorr+conv` column additionally needs the DFlash2 variant. Acceptance length is bit-reproducible under greedy decoding and its replicate spread here was 0.00% on every benchmark; throughput has a ~0.2% floor. ### What `dflash_fp32_master_weights` does, and what it is worth Today the draft is cast to the frozen base model's dtype — bf16 — before the optimizer is built. AdamW then allocates its moments with `zeros_like(p)`, so the **optimizer state becomes bf16 too**. That is the problem: bf16 has too few mantissa bits to represent the small updates Adam's second moment accumulates, so those updates round away and the effective step size decays on its own, independently of the learning-rate schedule. The flag is standard mixed precision instead: the draft's master weights stay in fp32 while the matmuls run in bf16. It requires a bf16 autocast around the forward, which HF `Trainer` supplies under `TrainingArguments.bf16`. Paths that do not go through the Trainer — evaluation, `pseudo_speculative_generate`, a plain `convert()` and forward — currently need the caller to supply it, and no shipped recipe exercises those (`estimate_ar: false`, `do_eval: false`). Making the draft supply its own autocast is a follow-up, held back from here on review because it touches every DFlash variant and wants e2e coverage of the existing recipes. Compute speed is unchanged. The cost is memory, about 12 bytes per parameter for the weight plus Adam's two moments instead of 6, plus a doubled gradient all-reduce under DDP, since fp32 parameters mean fp32 gradients. Under FSDP2 that second cost is what `MixedPrecisionPolicy(reduce_dtype=...)` exists to control. It is worth **7 to 14 percent of acceptance length**, measured at the end of training on gsm8k, and it helps every projector type: | arm | bf16 | fp32 | Δ acceptance length | | --- | ---: | ---: | ---: | | LiLiCorr | 6.8670 | 7.5573 | **+10.05%** | | DFlash2 | 6.7396 | 7.2518 | **+7.60%** | | Domino | 6.5854 | 7.2252 | **+9.71%** | | DSpark | 6.4621 | 7.3752 | **+14.13%** | | DFlash | 5.9030 | 6.3412 | **+7.42%** | Every arm in the comparison table above was trained with it on, and **both shipped recipes set it `true`**, so the documented path gets it. It defaults to **off**, so no existing DFlash, Domino or DSpark run changes behaviour. Both shipped LiLiCorr recipes set it `true`, which is the arithmetic their numbers were trained with. Flipping the default is a reasonable follow-up once the autocast above is in. The draft is drawn in fp32 and, under this flag, kept there; an unpromoted run rounds the same draw to the base model's dtype. So the bf16 and fp32 rows of the table above start from the same initialization at the precision each trains in, rather than from two different draws. A unit test pins that. The flag also survives a resume. `modify()` runs under `from_pretrained` with the base model still on meta and cannot place the draft at all, so `restore_draft_precision` re-applies the dtype, the device and the rotary buffer once the weights are loaded and before the Trainer builds the optimizer — the last point that can still decide the Adam moment dtype. It also reloads the draft's tensors at the dtype they were saved in, since checkpoints store the draft in fp32 while the base is bf16 and `dtype="auto"` gives every tensor one dtype. @h-guo18 has the same field in flight on `haoguo/dflash-fp32-master-weights`, plus an HF-format-resume fix this PR does not have. The name is shared deliberately so there is only ever one knob; whichever lands first, the other should be dropped rather than merged. ### Testing - **257 CPU unit tests pass** across `tests/unit/torch/speculative/`, including the existing DFlash, Domino, DSpark and Eagle suites. 48 of them are new and cover LiLiCorr specifically: conversion routing, head geometry, the required-field validation, the three-term objective and its absolute weights, gradient reach into both the head and the drafter body, and the export contract. - Both recipes load and validate through `modelopt.recipe.load_recipe`. - The three DFlash-wide changes are covered behaviourally: the fp32 flag is checked on the optimizer's moment dtypes rather than only on parameters, since the moments are the point of the change, and on the initialization described above; activation checkpointing is asserted to leave draft gradients bit-identical with the flag on and off; and the rotary buffer is asserted present after `modify()` on a real device while still deferred on meta, which is the case the laziness existed for. - The resume path has its own test: after a `save_pretrained` / `from_pretrained` round trip, `restore_draft_precision` is asserted to return the draft to fp32 with its stored weights intact and its Adam moments in fp32. Without it the draft comes back in the base dtype with the flag still set, which is the failure it exists to prevent. - `TestDFlashLazyRotaryEmb` was updated rather than left passing: it asserted the rotary buffer does *not* exist after convert, and the DDP fix deliberately changes that on non-meta devices. The replacement pins the refined invariant in both directions. - The published checkpoints were trained with this arithmetic, verified rather than assumed: a fingerprint over draft initialisation, loss and gradients is compared against the pre-review tree for both `dflash` and `lilicorr`. Loss and gradients are **bitwise identical**. Initialisation moves, by less than bf16 resolution, and that is the single-dtype change described above. ### Before your PR is "*Ready for review*" - Is this change backward compatible?: ✅ — every addition is opt-in. The new `projector_type` is selected only by config, `dflash_fp32_master_weights` defaults to off, and the activation-checkpointing and DDP fixes preserve behaviour. No existing default changes. - If you copied code from any other sources or added a new PIP dependency, did you follow guidance in `CONTRIBUTING.md`: ✅ — no new dependencies. Four files carry `# Adapted from https://github.com/sgl-project/SpecForge/...` headers for the DFlash backbone and loss they derive from (Apache-2.0), matching the attribution already on `hf_dflash.py` in this repo. The two commits described above are @h-guo18's, cherry-picked with authorship and sign-off preserved. - Did you write any new necessary tests?: ✅ — 48 new CPU tests, plus the updated rotary test. - Did you update [Changelog](https://github.com/NVIDIA/Model-Optimizer/blob/main/CHANGELOG.rst)?: ✅ - Did you get Claude approval on this PR?: ❌ — will run `/claude review` once opened. ### Additional Information The convolutional recipe is the memory worst case: at an 8B target, combined with fp32 master weights, it may need `training.gradient_checkpointing: true` to fit on 80 GiB, and it fits without at 4B. Checkpointing is mathematically neutral — same objective, same data order, same resulting model — but it trades step time for memory, so a run using it is not step-time-comparable with one that does not. The recipe header says so. <!-- This is an auto-generated comment: release notes by coderabbit.ai --> ## Summary by CodeRabbit * **New Features** * Added LiLiCorr speculative decoding with candidate-lattice reranking, configurable objectives, metrics, export support, and optional grouped convolutions. * Added FP32 master-weight support with improved mixed-precision behavior and gradient checkpointing. * Added LiLiCorr training recipes and a Qwen3-8B launcher configuration. * **Bug Fixes** * Improved rotary-embedding configuration handling and corrected DFlash distributed-training hangs. * Added validation for invalid LiLiCorr configurations and improved exported reranking metadata. * **Documentation** * Expanded guidance for FP32 master weights, training workflows, and LiLiCorr configuration. * **Tests** * Expanded coverage across training, evaluation, generation, export, and checkpoint workflows. <!-- end of auto-generated comment: release notes by coderabbit.ai --> --------- Signed-off-by: mrusanovsky <mrusanovsky@nvidia.com> Signed-off-by: h-guo18 <67671475+h-guo18@users.noreply.github.com> Co-authored-by: h-guo18 <67671475+h-guo18@users.noreply.github.com> Co-authored-by: Claude Opus 5 (1M context) <noreply@anthropic.com> |
||
|
h-guo18
|
5db2682519 |
[Example]: Calibration-free FP8/NVFP4 PTQ for speculative-decoding drafters (#2027)
### What does this PR do? Type of change: new example Adds `examples/speculative_decoding/scripts/quantize_drafter.py`, a CLI that quantizes an exported speculative-decoding drafter to FP8 or NVFP4 — weight-only or weight+activation — with no calibration data. It needs no modeling code either. Exported drafters such as [`nvidia/MiniMax-M3-DSpark`](https://huggingface.co/nvidia/MiniMax-M3-DSpark) have no importable model class, so each 2-D weight is wrapped in a throwaway `nn.Linear` under its checkpoint key and ModelOpt's usual `quantizer_name` patterns select over those names. Works for any drafter layout (DSpark / DFlash / EAGLE3 / Medusa). **Formats:** `w4a16_nvfp4`, `nvfp4`, `fp8`, `fp8_pc_pt` — the ModelOpt formats vLLM's backend can actually serve. AWQ is deliberately not offered, since `awq_lite` silently degrades to plain RTN without a `forward_loop`. **Static activation scales without calibration.** `fp8` and `nvfp4` normally need an activation amax *measured* on calibration data; a fixed `input_scale` of 1.0 is applied instead. That works because acceptance length is governed almost entirely by **clipping**, not resolution: Sweeping the fixed scale over three decades (same setup as the Testing section below; bf16 baseline 3.1423): | `input_scale` | amax | FP8 AL | vs bf16 | NVFP4 AL | vs bf16 | |---|---|---|---|---|---| | 0.003 | 1.3 | 2.2204 | -29.34% | 2.2076 | -29.75% | | 0.01 | 4.5 | 2.6719 | -14.97% | 2.6641 | -15.22% | | 0.03 | 13.4 | 2.9751 | -5.32% | 2.9259 | -6.89% | | 0.1 | 44.8 | 3.1013 | -1.31% | 3.0206 | -3.88% | | 0.2 | 89.6 | 3.1178 | -0.78% | 3.0015 | -4.48% | | 0.3 | 134.4 | 3.1370 | -0.17% | 3.0222 | -3.82% | | 0.5 | 224.0 | 3.1268 | -0.50% | 3.0360 | -3.38% | | **1.0 (default)** | **448.0** | **3.1457** | **+0.11%** | **3.0193** | **-3.91%** | | 2.0 | 896.0 | 3.1354 | -0.22% | 3.0172 | -3.98% | | 4.0 | 1792.0 | 3.1245 | -0.57% | 3.0034 | -4.42% | Both formats fall off a cliff below ~0.03, where the declared range sits far under the activations' true magnitude and most of the tensor is clipped. Both then sit on a flat plateau from ~0.3 to 4.0 **with no drop-off at the top**, so the scale only has to be big enough. 1.0 is the middle of that plateau, which is why it is hardcoded rather than exposed. NVFP4 trails FP8 by a roughly constant 3.5% across the plateau — that gap is the 4-bit resolution cost, and no choice of scale recovers it. Deriving the amax from the weights instead was tried and does not work: `max|W|` averages 0.79 while a RMSNorm'd activation is O(1) with outlier channels in the tens, so the range lands 1–2 orders of magnitude low and clips, measuring -31% to -46% AL. **Where calibration would go.** All of this sits behind `resolve_activation_scales()`, the single place deciding where a static amax comes from. Real calibration slots in ahead of the fixed fallback with no change to the CLI or the call site, and composes because `set_static_activation_amax()` skips quantizers that already have an amax: ```python if calib_forward_loop is not None: mtq.calibrate(root, quant_cfg["algorithm"], forward_loop=calib_forward_loop) set_static_activation_amax(root) # fills in what calibration did not reach ``` **Serving a quantized drafter.** Four things had to be written into the exported checkpoint before vLLM would load one: - emit `quant_method` (`modelopt_fp4` / `modelopt`) — vLLM reads that key, ModelOpt writes only `quant_algo` - emit the exclusion list under `ignore` too — that is the key read from the flat `quantization_config`; `exclude_modules` alone yields an empty exclusion set - add `*<name>` wildcards so exclusions match a runtime's nested module prefix (`model.fc`) rather than the checkpoint key (`fc`) - add `*qkv_proj` / `*gate_up_proj` aliases for layers a runtime fuses, whose names appear in no checkpoint key Nothing is then needed on the caller side. **This closes the open question left in the previous revision of this PR: vLLM does read `quantization_config` off the draft checkpoint.** `ModelConfig._verify_quantization` fills `quantization` in from `quant_method` when it is unset, so once the export declares that key — the first fix above — detection works on its own. Verified on Nemotron-3.5-Lightning passing nothing: `Detected ModelOpt NVFP4 checkpoint (quant_algo=NVFP4)` → `FlashInferCuteDslNvFp4LinearKernel`, AL 4.278 against 4.203 measured earlier. `specdec_bench` also gains a `DSPARK` algorithm, which it did not have: an exported `Qwen3DSparkModel` would otherwise have to go through `DFLASH` and be built with vLLM `method="dflash"`. The branch sets `method="dspark"` and leaves `draft_sample_method` on vLLM's own default of `greedy`. A target whose fused-collective workspace (sized at CUDA-graph capture) overflows at large speculative batches can disable graphs with `--runtime_params '{"engine_args": {"enforce_eager": true}}'`. For DFlash-family drafters, `qwen3_dflash.py` builds its fused context-KV projection by reading `qkv_proj.weight` raw and calling `F.linear`, which cannot consume a packed weight. Keep those layers in bf16 with `--exclude '*q_proj*' '*k_proj*' '*v_proj*' '*qkv_proj*'`; `o_proj` and the MLP — the bulk of the drafter — still quantize. That exclusion is mandatory, not a tuning choice. `fc` (the projection from the target's captured layers into the draft) is the one real knob, and it is a genuine trade rather than a free win — see the Testing section for both models' numbers. The examples quantize it; add `'*fc*'` to the exclude list to keep it in bf16. `embed_tokens`, `markov_head` and `confidence_head` are excluded by default: they are 2-D so the flat view treats them as GEMMs, but they are embeddings or a single-output projection. `lm_head` is excluded by the preset itself — unlike on a base model it is 37% of this drafter's parameters, so `--quantize_lm_head` is a real lever (~1.9 GiB), but measure AL first. The flag re-enables both of `lm_head`'s quantizers; re-enabling only the weight one would ship a W+A checkpoint whose `lm_head` has no `input_scale` while the config still advertises it as quantized. ### Usage ```bash # weight+activation FP8, calibration-free, lossless on both models measured below python scripts/quantize_drafter.py \ --drafter_path deepseek-ai/dspark_qwen3_8b_block7 \ --qformat fp8 \ --export_path ./dspark-qwen3-8b-fp8 \ --exclude '*q_proj*' '*k_proj*' '*v_proj*' '*qkv_proj*' # smallest: weight-only NVFP4 python scripts/quantize_drafter.py \ --drafter_path nvidia/MiniMax-M3-DSpark \ --qformat w4a16_nvfp4 \ --export_path ./MiniMax-M3-DSpark-W4A16 ``` Or end to end on Slurm — quantize, then measure AL — via the launcher examples added here, one per target: ```bash uv run launch.py --yaml examples/Qwen/Qwen3-8B/hf_dspark_ptq_nvfp4.yaml --yes uv run launch.py --yaml examples/nvidia/NVIDIA-Nemotron-3.5-Lightning-30B-A3B-BF16/hf_dspark_ptq_nvfp4.yaml --yes ``` Serving one, if you are not going through `specdec_bench`: ```python speculative_config = { "method": "dspark", "model": "./dspark-qwen3-8b-fp8", # quantization is read from its config.json "num_speculative_tokens": 7, } ``` ### Testing Two targets with different architectures, so the conclusions are not one model's quirk: * **Qwen3-8B** (dense transformer) + [`deepseek-ai/dspark_qwen3_8b_block7`](https://huggingface.co/deepseek-ai/dspark_qwen3_8b_block7), `block_size` 7, TP1. * **Nemotron-3.5-Lightning-30B-A3B** (hybrid Mamba-MoE) + [`nvidia/NVIDIA-Nemotron-3.5-Lightning-30B-A3B-BF16-DSpark`](https://huggingface.co/nvidia/NVIDIA-Nemotron-3.5-Lightning-30B-A3B-BF16-DSpark), `block_size` 8, TP8, with the mamba engine settings the model card pins (`mamba_backend=flashinfer`, `mamba_ssm_cache_dtype=float16`, stochastic SSM-cache rounding). Both: MT-Bench 80 questions, greedy, one vLLM instance per point. | recipe | activations | Qwen3-8B AL | vs bf16 | Nemotron-3.5 AL | vs bf16 | |---|---|---|---|---|---| | bf16 baseline | — | 3.1423 | — | 4.3296 | — | | **`fp8`** | static, `input_scale` 1.0 | **3.1457** | **+0.11%** | **4.3289** | **-0.02%** | | `fp8_pc_pt` | dynamic per-token | 3.1228 | -0.62% | 4.3411 | +0.26% | | `w4a16_nvfp4`, `fc` in bf16 | bf16 (weight-only) | 3.0392 | -3.28% | 4.2899 | -0.92% | | `w4a16_nvfp4`, `fc` quantized | bf16 (weight-only) | 3.0186 | -3.94% | 4.2334 | -2.22% | | **`nvfp4`** | static, `input_scale` 1.0 | **3.0193** | **-3.91%** | **4.2030** | **-2.92%** | **FP8 weight+activation at the fixed `input_scale` of 1.0 is lossless on both.** +0.11% and -0.02% are both inside run-to-run noise — the Nemotron baseline was measured twice under identical settings and the two runs differ by 0.94% (4.3093 / 4.3499), which sets the resolution of that column. On the same reading, `fp8` and `fp8_pc_pt` are indistinguishable on Nemotron; the dynamic variant only pulls ahead on Qwen3. NVFP4 costs 3-4% on Qwen3 and 2-3% on Nemotron, i.e. the 4-bit weight resolution is the real price and it is model-dependent but bounded. Whether to quantize `fc` is a per-model call rather than a general recommendation — it buys a few percent of size for an AL cost that differs by ~2x between these two drafters: | `fc` bf16 → quantized | Qwen3-8B | Nemotron-3.5 | |---|---|---| | checkpoint size | 3.293 → 3.181 GiB (-3.4%) | 1.316 → 1.258 GiB (-4.4%) | | AL | 3.0392 → 3.0186 (-0.68%) | 4.2899 → 4.2334 (-1.32%) | `fc` itself is only 3.5% (Qwen3) / 4.5% (Nemotron) of drafter parameters; `embed_tokens` is the bulk (26% / 36%) and is excluded by default. The Qwen3 `w4a16_nvfp4` rows were measured in a later session than the rest of that column; the `fc`-in-bf16 run reproduced the original number to four decimals (3.0392), so the column is internally comparable. Also validated on `nvidia/MiniMax-M3-DSpark`: `w4a16_nvfp4` runs in 67 s on CPU, 9.98 GiB (fp32) -> 3.51 GiB; all 43 quantized tensors round-trip within 0.0952 relative error; the 29 untouched tensors are bit-identical to `bf16(source)`. ### Before your PR is "*Ready for review*" - Is this change backward compatible?: ✅ (example-only) - If you copied code from any other sources or added a new PIP dependency, did you follow guidance in `CONTRIBUTING.md`: N/A - Did you write any new necessary tests?: ❌ — validated manually as above. Can add a `tests/examples/speculative_decoding/` test over a small synthetic drafter if wanted before merge. - Did you update [Changelog](https://github.com/NVIDIA/Model-Optimizer/blob/main/CHANGELOG.rst)?: N/A (example-only) - Did you get Claude approval on this PR?: ❌ (not yet run) ### Additional Information The measurements above are one drafter on one target with one benchmark; the plateau's location and the ~3.5% NVFP4 gap should be re-measured before assuming they carry to a different drafter. Note when reading an exported checkpoint: `input_scale` is `amax/448` for FP8 but `amax/(6*448)` for NVFP4, so the one fixed amax records as 1.0 in an FP8 checkpoint and 0.1667 in an NVFP4 one. Both mean the same activation range. Signed-off-by: h-guo18 <67671475+h-guo18@users.noreply.github.com> |
||
|
h-guo18
|
2b296b2f62 |
Support fine-tuning released DFlash/DSpark drafters (causal SWA, attention sink, warm start) (#2149)
# Support fine-tuning released DFlash/DSpark drafters (causal SWA, attention sink, warm start) ### What does this PR do? Type of change: New feature + bug fix Adds what ModelOpt was missing to fine-tune an already-published DFlash/DSpark draft model. The concrete target is [`nvidia/NVIDIA-Nemotron-3.5-Lightning-30B-A3B-BF16-DSpark`](https://huggingface.co/nvidia/NVIDIA-Nemotron-3.5-Lightning-30B-A3B-BF16-DSpark) on its hybrid Mamba/attention/MoE base, but every change is generic. Before this PR that checkpoint could not be trained faithfully — or even loaded: its attention-sink tensors were dropped as unexpected keys, its block-causal attention had no implementation, and its capture layers were silently overwritten with ModelOpt's defaults. **New user-facing options** (all default to today's behavior, so existing runs are unchanged): | Option | Values | Purpose | | --- | --- | --- | | `dflash_draft_attention` | `bidirectional` (default) / `causal` | Block-internal attention pattern. `causal` restricts a query at block position `i` to draft positions `<= i`. | | `dflash_attention_sink` | `false` (default) / `true` | Learnable per-head `attention_sink_bias [num_heads]` on every draft layer — one extra logit appended before the softmax and dropped after, so a head can put probability mass nowhere instead of being forced to attend inside its window (the GPT-OSS formulation). | | `dflash_init_checkpoint` | path | Warm-start the draft from an exported checkpoint instead of a random init. Any missing/unexpected/wrong-shaped tensor raises rather than warns. | | `dflash_architecture_config.target_layer_ids` | list | Which base layers feed the draft's `fc`. Previously recomputed unconditionally with no override. | **Bugs fixed along the way** (each one silently corrupts training rather than failing): - The exporter hard-coded `dflash_config.causal: False` and only wrote it under SWA, so even a correctly-trained causal draft would be served non-causally. It now reflects the trained setting, and emits `attention_sink_bias` when enabled. - `_build_generate_swa_mask` returned `None` whenever `swa_window_size` was unset, which would have dropped the causal structure at generation time while training used it. - `target_layer_ids` was recomputed from the uniform default on every convert. The released drafter uses `[1,5,19,29,41,51]`; the default for a 52-layer base is `[1,11,20,30,39,49]` — *different layers*. Here it surfaced as a matmul shape error only because the plane counts disagreed; with a matching count it would have trained on the wrong features silently. - The streaming dataset assumed the draft's aux layers all sit below the base's final layer (`aux = planes[:-1]`, `target = planes[-1]`). A draft whose top aux id *is* the final layer cannot get an extra plane — vLLM captures each layer once — so `final_aux_is_base_hidden` now lets the last plane serve both roles. It is derived from the model, not configured by hand. - DSpark head weights load from either the flat layout ModelOpt exports (upstream DeepSpec convention) or the nested `markov_head.` layout the NVIDIA release uses. Without the remap the two `[131072, 512]` Markov tables — ~14% of the draft's parameters — stay randomly initialized while everything else warm-starts, with no error. - `nemotron_h` is enabled in `_FINAL_NORM_TYPE_BY_MODEL_TYPE`: despite the hybrid stack, `NemotronHModel.norm_f` is a plain RMSNorm, and without the entry the offline/streaming fake base raises instead of reconstructing the distillation target. ### Usage ```yaml dflash: dflash_init_checkpoint: /path/to/NVIDIA-Nemotron-3.5-Lightning-30B-A3B-BF16-DSpark dflash_draft_attention: causal dflash_attention_sink: true dflash_swa_window_size: 1024 dflash_block_size: 8 dflash_mask_token_id: 990 dflash_architecture_config: target_layer_ids: [1, 5, 19, 29, 41, 51] ``` A full worked example is at `modelopt_recipes/general/speculative_decoding/dspark_nemotron35_warmstart.yaml`. ### Testing **Unit tests** — 124 pass (`test_hf_dflash.py`, `test_hf_dspark.py`, `test_hf_domino.py`, `test_hf_dflash_offline.py`, `test_modeling_final_norm.py`), 32 of them new: causal mask structure (lower-triangular per block, no cross-block leakage, context visibility unchanged), the sink math (degenerates to plain attention at `-inf`, absorbs mass monotonically, receives gradient), warm-start load/reject paths, Markov key remapping, and explicit `target_layer_ids`. **Checkpoint compatibility** — the released drafter loads with zero missing/unexpected keys and zero shape mismatches; all 77 tensors (6 attention sinks and both Markov tables included) match bit-exactly, and a training step runs with gradients reaching the sink and Markov parameters. **End-to-end streaming training** — Nemotron-3.5 base served by vLLM (1 node, TP8) feeding 8 trainer GPUs over NIXL; the draft warm-starts from the released checkpoint and trains with `causal` + sink + SWA 1024. 128 Daring-Anteater conversations, 20 epochs (the plot shows the first 5, where the trend is clearest — the curves flatten after that): 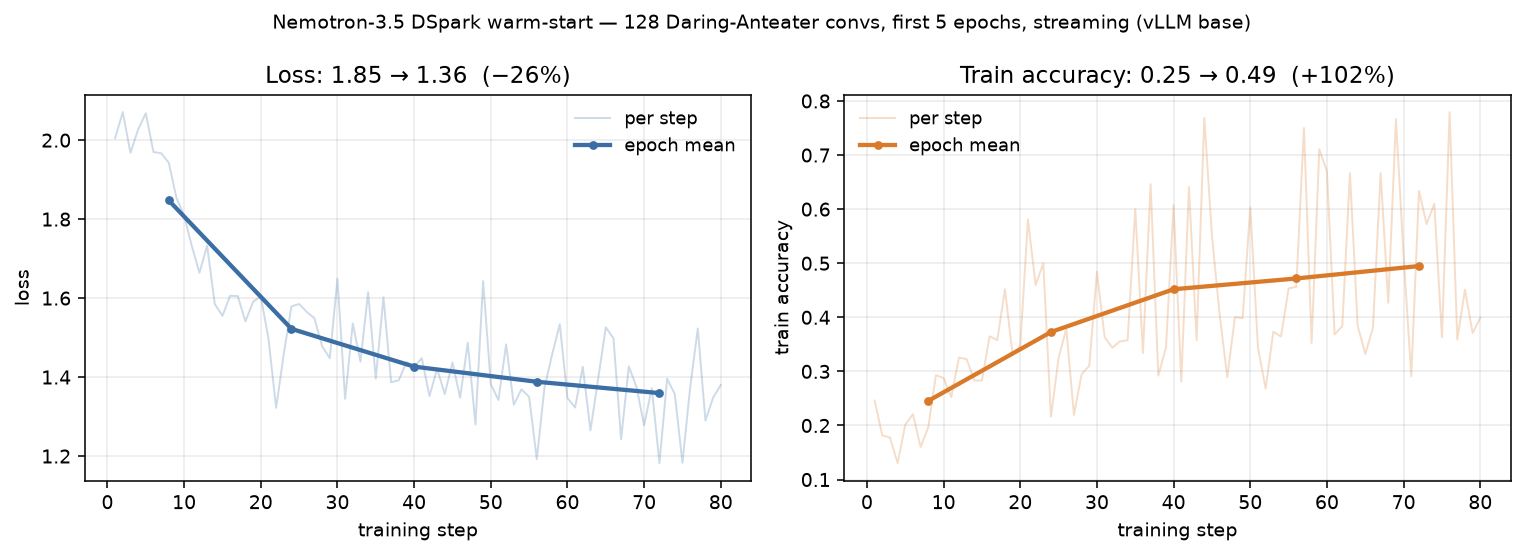 Over the first 5 epochs loss falls **1.85 → 1.36** and train accuracy rises **0.25 → 0.49**; across the full 20 epochs they reach **1.21** and **0.48** (peak 0.54) before flattening. This validates the pipeline end-to-end — capture layers, plane split, mask direction, sink loading and warm-start weights all have to be right for this curve to appear. It is *not* a model-quality result: 128 samples over 20 epochs overfits by construction, and the corpus is not generated by the base model, so the absolute numbers are not meaningful. ### TODO (follow-up) **A complete, robust checkpoint/config converter.** Both conversions are handled ad hoc here: - *Draft config → training config.* The recipe transcribes ~15 fields by hand from the drafter's `config.json`. Only the shape-bearing ones (`num_hidden_layers`, `num_attention_heads`, `intermediate_size`, `markov_rank`) fail loudly when mistyped; the rest — `mask_token_id`, `causal`, `swa_window_size`, `block_size` — train "successfully" on a wrong value and only surface later as a mysteriously low acceptance length. A converter should derive the whole block from the checkpoint, including its aliases (`pard_token`, `dspark_markov_rank`, `dflash_query_causal`, top-level `sliding_window` / `attention_sink_bias`) and duplicated fields. - *Weight layout.* The `markov_head.` remap is a load-time hook. A converter should normalize layouts explicitly, and decide whether export should also emit the release's aliases so a round-trip reproduces the original format (today it renames `architectures` to `DFlashDraftModel`). - *Base config.* Serving this base on vLLM needs its `config.json` layer-type vocabulary updated for the transformers-5 path (`mamba` → `linear_attention`, `attention` → `full_attention`, plus a matching `hybrid_override_pattern`). That is done by hand today and is not covered by this PR. ### Before your PR is "*Ready for review*" - **Make sure you read and follow [Contributor guidelines](https://github.com/NVIDIA/TensorRT-Model-Optimizer/blob/main/CONTRIBUTING.md)** and your commits are signed. - **Is this change backward compatible?**: Yes - **Did you write any new necessary tests?**: Yes - **Did you add or update any necessary documentation?**: Yes - **Did you update [Changelog](https://github.com/NVIDIA/TensorRT-Model-Optimizer/blob/main/CHANGELOG.rst)?**: No <!-- This is an auto-generated comment: release notes by coderabbit.ai --> ## Summary by CodeRabbit * **New Features** * Added configurable causal or bidirectional attention for DFlash models. * Added optional attention sinks, checkpoint warm starts, and explicit target-layer selection. * Improved streaming data handling for shared auxiliary and base hidden states. * Added Nemotron-3.5 Lightning DSpark warm-start training and serving recipes. * **Bug Fixes** * Preserved configured attention behavior during model export. * Prevented warm-start checkpoints from being reapplied during restoration. * Improved checkpoint compatibility, validation, and attention-mask handling. <!-- end of auto-generated comment: release notes by coderabbit.ai --> Signed-off-by: h-guo18 <67671475+h-guo18@users.noreply.github.com> |
||
|
skierat
|
c4129b6e03 |
Add Cosmos3 Nano DFlash multimodal training recipe (#2053)
### What does this PR do? Type of change: new example Adds an end-to-end Cosmos3 Nano DFlash training recipe for multimodal speculative decoding. - Adds a notebook that prepares data, launches synthetic generation in Slurm, trains a DFlash draft model, exports it, and provides a vLLM smoke-test command. - Adds PAI-Understanding, VQA v2, and multilingual prompt sharding and distributed-generation helpers. - Adds an atomic, multimodal-safe merge and conservative deduplication flow. - Extends the VLM data collator to handle structured image/video messages, configurable visual bounds, and fixed DFlash sequence lengths. - Hardens generation launch scripts and preserves truncated generated responses. ### Usage ```bash cd examples/speculative_decoding/recipes export MODEL_PATH=/path/to/cosmos3-nano export PLAIN_TEXT_INPUT=/path/to/nemotron-chat-or-approved-user-data.jsonl jupyter lab train_dflash_cosmos3_nano.ipynb Run the notebook in order: 1. Configure paths. 2. Prepare prompts on a CPU-only node and generate target completions in a Slurm GPU allocation. 3. Merge the four required sources and submit training. 4. Export a saved checkpoint and run the vLLM deployment smoke test. ### Testing - jq empty examples/speculative_decoding/recipes/train_dflash_cosmos3_nano.ipynb - bash -n on the modified launch, worker, and recipe shell scripts. - Ran a two-step Cosmos3 Nano DFlash Slurm smoke job; it completed and wrote modelopt_state.pth. - Not run: pytest tests/unit/torch/speculative/plugins/test_hf_speculative_offline.py (pytest is unavailable in the current environment). ### Before your PR is "Ready for review" - Is this change backward compatible?: ✅ - If you copied code from any other sources or added a new PIP dependency, did you follow guidance in CONTRIBUTING.md?: N/A - Did you write any new necessary tests?: ✅ - Did you update CHANGELOG.rst?: N/A - Did you get Claude approval on this PR?: N/A ### Additional Information Security follow-up required before marking ready: the notebook hardcodes model.trust_remote_code=true and --trust_remote_code. Either parameterize this with a default of false, or obtain and document a security exception. <!-- This is an auto-generated comment: release notes by coderabbit.ai --> ## Summary by CodeRabbit * **New Features** * Added end-to-end multimodal workflows for dataset preparation, distributed generation, result merging, training, export, and deployment testing. * Added support for image and video inputs, multiple dataset formats, resumable JSONL generation, configurable serving, and parallel processing. * Added configurable prompt, media, token, sequence, temperature, and tensor-parallel settings. * **Bug Fixes** * Improved truncated-response handling, assistant-label processing, validation, health checks, cleanup, deduplication, media resolution, atomic outputs, and failure reporting. <!-- end of auto-generated comment: release notes by coderabbit.ai --> --------- Signed-off-by: Slawomir Kierat <skierat@nvidia.com> |
||
|
Keval Morabia
|
bee497de03 |
Fix EAGLE3 offline dump skipping all conversations on newer transformers (#2172)
### What does this PR do? Type of change: Bug fix **Fix EAGLE3 offline hidden-state dump silently skipping every conversation on newer `transformers`.** `tokenizer.apply_chat_template(...)` returns a **`BatchEncoding`** (dict of `input_ids` + `attention_mask`) on `transformers>=5` rather than a `list[int]`, so `len(input_ids)` evaluated to **2** (the number of dict fields), tripping the `num_input_tokens <= 10` "too short" filter for **every** conversation. The dump wrote **zero `.pt` files** and offline EAGLE3 training aborted with `No .pt files found`. The token-id extraction is consolidated into `modelopt.torch.speculative.utils.get_conversation_input_ids`, which normalizes the result to a flat `list[int]` (unwrapping `BatchEncoding` / 2-D tensor / batch-wrapped list, asserting the shape so a future `transformers` change fails loudly instead of silently). It is called from all three offline-dump entry points that shared the bug: - `examples/speculative_decoding/collect_hidden_states/compute_hidden_states_trtllm.py` - `examples/speculative_decoding/collect_hidden_states/send_conversations_for_hiddens.py` - `examples/speculative_decoding/scripts/send_conversation_vllm.py` (the two `send_conversation*` scripts additionally indexed/`decode()`d the `BatchEncoding`). Also fixes the `add_generation_template` -> `add_generation_prompt` typo at each site. ### Testing - `tests/unit/torch/speculative/test_speculative_utils.py` — asserts the helper returns the exact token-id sequence of the rendered chat prompt, and pins every `apply_chat_template` return shape (`BatchEncoding`, 2-D tensor, batch-wrapped list, plain list) to a flat `list[int]` via deterministic stubs, so the fixed branch is covered regardless of the installed `transformers` version. - **End-to-end on ComputeLab (H100, TRT-LLM 1.3.0rc20):** reran the exact dump on the 100 conversations that previously failed. Before: 0/100 (0 `.pt` files). After: **97/100** (97 `.pt` files; the 3 skips are genuinely `> max_seq_len`). ### Before your PR is "*Ready for review*" - Is this change backward compatible?: ✅ - If you copied code from any other sources or added a new PIP dependency, did you follow guidance in `CONTRIBUTING.md`: N/A - Did you write any new necessary tests?: ✅ (`tests/unit/torch/speculative/test_speculative_utils.py`) - Did you update Changelog?: N/A - Did you get Claude approval on this PR?: 🔄 `/claude review` run; findings addressed, re-review pending ### Additional Information Surfaced by an nmm-sandbox CI run where `Qwen3-8B_EAGLE3_offline` failed after the container bump to `tensorrt-llm/release:1.3.0rc20`; the auto-blame heuristic mis-attributed it to an unrelated MLflow commit. `compute_hidden_states_vllm.py` is unaffected (it routes through `common.tokenize_with_loss_mask`, which passes `return_dict=True`). --------- Signed-off-by: Keval Morabia <28916987+kevalmorabia97@users.noreply.github.com> |
||
|
Keval MorabiaandClaude Opus 5
|
22b6a148b0 |
Fix EAGLE-3 context-parallel training and re-enable its tests (#2086)
### What does this PR do?

Type of change: Bug fix

**EAGLE-3 context-parallel training (`--cp_size > 1`) is fixed, and its
tests run again.** CP has been broken since `accelerate` 1.13, and the
tests never caught it: the guard compared `Version("2.10.0a0")` against
`Version("2.10.0")`, which is False on every NGC alpha torch build, so
`test_llama_eagle3[cp_size=2]` has never actually run in CI.

Five fixes:

- **`main.py`** — rebuild the FSDP2 plugin accelerate requires for
`cp_size > 1`. The `--fsdp full_shard --fsdp_config` launcher flags that
used to supply it were dropped from `launch_train.sh`, so CP could not
start at all. Also pass the CP degree to the draft model.
- **`modeling_eagle.py`** — apply the draft model's first input norm
inside `layers[0]`'s own forward, where FSDP2 has actually unsharded its
weights, and only stash the input embeds on the path whose pre-hook
consumes them.
- **`hf_eagle.py`** — skip the dense eagle attention mask under CP
(causal masking comes from `is_causal`, TTT masking from the
ring-attention patch), and warn that padded positions are therefore
unmasked. Also stop `(eagle_loss or 0)` replacing a `0.0` loss tensor
with a plain `int`, which detached the graph.
- **`eagle_utils.py`** — key TTT-mask injection off the backward call's
`grad_out` kwarg, since newer torch omits `attn_bias` on the forward
call, silently disabling TTT masking.
- **`utils.py`** — CUDNN-only SDPA under CP; the `MATH` backend
decomposes SDPA and breaks on DTensors. Scoped to `cp_size > 1`, since
this context manager wraps every training forward and CPU has no cudnn
backend.

**Drops the `speculative_decoding` 26.01 container override.** It was
added when the lane ran 25.06 and spec-dec needed something *newer* — a
floor. Later bumps moved the default past it, so it had silently become
a ceiling holding spec-dec on a 6-month-old image.

### Testing

Ran `tests/examples/speculative_decoding` in
`nvcr.io/nvidia/pytorch:26.07-py3` on 2 GPUs, reproducing the CI install
steps (`pip uninstall -y nvidia-modelopt`, `pip install -e
".[hf,dev-test]"`, example requirements): **16 passed, 2 skipped** — the
2 skipped being pre-existing `--run-manual` tests. All four
`test_llama_eagle3` cases pass, including both `cp_size=2` ones.

### Before your PR is "*Ready for review*"

- Is this change backward compatible?: ✅
- If you copied code from any other sources or added a new PIP
dependency, did you follow guidance in `CONTRIBUTING.md`: N/A
- Did you write any new necessary tests?: N/A — the existing `cp_size=2`
tests are re-enabled
- Did you update
[Changelog](https://github.com/NVIDIA/Model-Optimizer/blob/main/CHANGELOG.rst)?:
✅
- Did you get Claude approval on this PR?: ❌ — not yet run

Signed-off-by: Keval Morabia <28916987+kevalmorabia97@users.noreply.github.com>
Co-authored-by: Claude Opus 5 <noreply@anthropic.com>
|
||
|
skieratandh-guo18
|
c94405e602 |
add Qwen3-VL support for DFlash training (#1975)
### What does this PR do?

  Type of change: new feature

Adds online DFlash training support for Qwen3-VL–style vision-language
models.

  Changes include:

- Load VLMs through the Transformers 5 `AutoModelForImageTextToText`
API, while retaining compatibility with the legacy VLM auto-model API.
- Run the base model through its top-level multimodal forward when
image/video inputs are present, ensuring vision embeddings are injected
before collecting DFlash target hidden states.
  - Extend `VisionLanguageDataCollator` to:
- propagate `answer_only_loss`, chat-template, and DFlash
label-alignment settings;
    - apply `VLM_MIN_PIXELS` / `VLM_MAX_PIXELS` processor limits;
- derive assistant-only masks from ChatML/Llama chat boundaries when
processor generation masks are unavailable;
- enforce the fixed `training_seq_len` required by DFlash block
training.
- Preserve the existing text-only DFlash path.

### Usage

```bash
python -m torch.distributed.run \
--nproc_per_node 4 \
examples/speculative_decoding/main.py \
--config modelopt_recipes/general/speculative_decoding/dflash.yaml \
model.model_name_or_path=/path/to/qwen3-vl-model \
model.trust_remote_code=true \
data.data_path=/path/to/train.jsonl \
data.vlm_processor=/path/to/qwen3-vl-model \
data.vlm_img_dir=/path/to/image/root \
training.training_seq_len=4096 \
training.answer_only_loss=true \
dflash.dflash_block_size=8 \
dflash.dflash_mask_token_id=151669


### Testing
- git diff --check
- Parsed all modified Python modules successfully.
- Ran iterative multi-node Slurm smoke tests with a Qwen3-VL-family model and mixed multimodal data:
    - validated VLM model loading with Transformers 5;
    - validated distributed initialization, DFlash conversion, and VLM collation paths;
    - identified and addressed processor padding/truncation behavior required by fixed-size DFlash blocks.
This PR remains draft pending a completed end-to-end training smoke test and automated regression coverage.

### Before your PR is "Ready for review"
Make sure you read and follow Contributor guidelines (https://github.com/NVIDIA/Model-Optimizer/blob/main/CONTRIBUTING.md) and your commits are signed (git commit -s -S).
Make sure you read and follow the Security Best Practices (https://github.com/NVIDIA/Model-Optimizer/blob/main/SECURITY.md#security-coding-practices-for-contributors) (e.g. avoiding hardcoded trust_remote_code=True, torch.load(...,
weights_only=False), pickle, etc.).
- Is this change backward compatible?: ✅
- If you copied code from any other sources or added a new PIP dependency, did you follow guidance in CONTRIBUTING.md: N/A
- Did you write any new necessary tests?: ❌ — automated Qwen3-VL/DFlash regression coverage still needs to be added before review.
- Did you update Changelog (https://github.com/NVIDIA/Model-Optimizer/blob/main/CHANGELOG.rst)?: ❌ — evaluate and add an entry before marking ready for review if this is considered user-facing speculative-decoding support.
- Did you get Claude approval on this PR?: N/A
### Additional Information
The PR intentionally excludes local Slurm launch scripts, logs, model paths, datasets, and environment-specific configuration.


<!-- This is an auto-generated comment: release notes by coderabbit.ai -->
## Summary by CodeRabbit

* **New Features**
  * Expanded VLM data-collation controls, including `shift_labels` and more robust `answer_only_loss` masking.
  * Improved Qwen3-VL speculative decoding for Transformers 5.3+ with correct video frame grouping and safer position-id handling.
  * Improved DFlash RoPE export to reliably read `rope_theta` from newer config formats.

* **Bug Fixes**
  * Hardened multimodal preprocessing and training loss masking to keep label/attention alignment consistent.
  * Improved behavior when anchor sampling yields no valid blocks.
  * More resilient VLM model loading when certain Transformers auto classes are unavailable.

* **Tests**
  * Added coverage for RoPE export, Qwen3-VL position-id logic across Transformers versions, and VLM label-mode/collator options.
<!-- end of auto-generated comment: release notes by coderabbit.ai -->

---------

Signed-off-by: Slawomir Kierat <skierat@nvidia.com>
Signed-off-by: h-guo18 <67671475+h-guo18@users.noreply.github.com>
Co-authored-by: h-guo18 <67671475+h-guo18@users.noreply.github.com>
|
||
|
h-guo18
|
6105fe84e9 |
[Examples]: MiniMax-M3 DSpark (#1965)
### What does this PR do?

Type of change: new example + bug fixes

Adds a **MiniMax-M3 DSpark streaming training recipe** under
`tools/launcher/examples/MiniMaxAI/MiniMax-M3/`, plus the four fixes it
needs to actually run. Each fix addresses a failure mode that is silent
or misleading without it:

1. **Gemma-style final norm for the fake base**
(`modeling_final_norm.py`, `modeling_fakebase.py`): M3 uses a
gemma-style final RMSNorm (`(1 + weight)` scale, fp32
multiply-then-cast). Selecting the norm by `model_type` alone picks
plain `rmsnorm` — MiniMax's VL remote code coerces its `model_type`-less
`text_config` to **mixtral** — which silently drops the `+1` and
corrupts the distillation target. New `_FinalGemmaRMSNorm` + selection
by the explicit `use_gemma_norm` config flag (only MiniMax sets it).
2. **Loud failure for un-maskable `answer_only_loss`**
(`hf_streaming_dataset.py`): with a fast tokenizer whose chat template
has no `{% generation %}` tags,
`apply_chat_template(return_assistant_tokens_mask=True)` only warns and
returns an **all-zero mask** — training runs at zero loss on every
sample with no other symptom. Now raises at tokenization with an
actionable message.
3. **`SERVE_BLOCK_SIZE` knob** (`train_eagle_streaming.sh`): nemo_run
exports env values unquoted, so a multi-token
`SERVE_EXTRA_ARGS="--trust-remote-code --block-size 128"` loses
everything after the first token. M3's MSA sparse attention requires KV
block 128 (`ValueError: No common block size for 16` at engine init
otherwise), so `--block-size` gets a dedicated single-token knob.
4. **Relax the speculative_decoding `transformers` pin to `<5.13`**
(match `pyproject.toml`): the old `<5.4` pin downgrades recent vLLM
containers (e.g. transformers 5.12.1, which also provides in-tree
`minimax_m3_vl`) and breaks `vllm serve` (`ALLOWED_LAYER_TYPES` needs
>=5.5.3).

The example itself encodes the validated M3 specifics: generation-tagged
chat template copy (required for `answer_only_loss` — see fix 2), draft
dims + base `rope_theta=5e6` set explicitly (not inherited), mask token
200063 (reserved slot; added tokens end at 200060), `EAGLE_CAPTURE_IDS`
= draft default `target_layer_ids+1` + final layer, `trust_remote_code`
at serve/export, and AWS-EFA NIXL notes (UCX segfaults at agent init on
EFA nodes; LIBFABRIC required there).

### Usage

```bash
cd tools/launcher
export SLURM_HOST=localhost SLURM_ACCOUNT=<account> SLURM_PARTITION=<partition> \
       SLURM_HF_LOCAL=<hf_models_dir> SLURM_JOB_DIR=<experiments_dir> NEMORUN_HOME=$PWD
uv run launch.py --yaml examples/MiniMaxAI/MiniMax-M3/hf_streaming_dspark_multi_node.yaml \
       identity=$HOME/.ssh/id_ecdsa detach=True --yes
```

### Testing

- `tests/unit/torch/speculative/plugins/`: **129 passed** inside a
current vLLM x86_64 nightly container (transformers 5.12.1), including 3
new tests for the assistant-mask guard.
- Generation-tagged template verified against real corpus samples:
`input_ids` identical to the original template, mask covers exactly the
assistant turns (think prefix + content + eos), contiguous, no
user-prompt leak.
- The recipe is exercised end-to-end by a live M3 DSpark training run
(this yaml modulo cluster paths): streaming serve + NIXL transport +
resume all healthy; drafter MT-Bench AL exceeds our Kimi-K2.6 DSpark
reference by ~8k steps.
- `ruff check` / `ruff format` (0.15.20) clean.

### Before your PR is "*Ready for review*"

- Is this change backward compatible?: ✅ (norm selection only changes
models with `use_gemma_norm=True`, previously mis-normed; the guard
turns a silent zero-loss run into an error; `SERVE_BLOCK_SIZE` is
opt-in; the pin relax widens the allowed range)
- Did you write any new necessary tests?: ✅
- Did you update
[Changelog](https://github.com/NVIDIA/Model-Optimizer/blob/main/CHANGELOG.rst)?:
❌ (can add if desired)

🤖 Generated with [Claude Code](https://claude.com/claude-code)


<!-- This is an auto-generated comment: release notes by coderabbit.ai
-->
## Summary by CodeRabbit

- **New Features**
- Added Gemma-style RMS normalization support for speculative decoding.
- Added MiniMax-M3 multi-node training configuration, including a full
Jinja chat template for tool calls, multimodal content, and thinking
modes.
  - Added optional `SERVE_BLOCK_SIZE` support for vLLM serve launches.
- **Bug Fixes**
- Improved `answer_only_loss` masking validation: now fails fast with
clear errors when required `{% generation %}` markers are missing or
when using a non-fast tokenizer.
- **Compatibility**
- Expanded the supported Transformers version range for speculative
decoding examples.
<!-- end of auto-generated comment: release notes by coderabbit.ai -->

---------

Signed-off-by: h-guo18 <67671475+h-guo18@users.noreply.github.com>
|
||
|
h-guo18
|
bc5bc1ac5f |
[Feat]: Add Final Norm for vLLM Hidden Extractor (#1846)
### What does this PR do? **Type of change:** Bug fix vLLM captures the final-layer hidden state *before* the model's final norm, but the offline/streaming distillation path fed it straight into `lm_head`, so the reconstructed base logits (the KD target) were computed from un-normed hidden states. This PR re-applies the base model's final norm before `lm_head` when the producer declares a pre-norm capture (`base_hidden_prenorm`), for both DFlash and EAGLE: - Producer sets `base_hidden_prenorm` (streaming: `True`; offline: from the dump). - Consumer (`_maybe_apply_base_final_norm`) re-applies the base final norm, and **fails loud** if pre-norm is declared but the model's norm type isn't supported (no silent corruption). - `FakeBaseModel` now loads the base final norm (+ `rope_theta`/`rms_norm_eps`); norm type is gated by an explicit `model_type` allowlist (gpt_oss excluded pending a matching norm class). ### Testing `tests/unit/torch/speculative/plugins/test_modeling_final_norm.py`; DFlash/EAGLE streaming training verified end-to-end. - Backward compatible?: ✅ (post-norm captures declare `base_hidden_prenorm=False` → unchanged) - New tests: ✅ <!-- This is an auto-generated comment: release notes by coderabbit.ai --> ## Summary by CodeRabbit * **New Features** * Expanded speculative decoding/distillation to reconstruct missing base-model logits by optionally applying a base model’s final pre–LM-head normalization when pre-norm hidden states are provided. * Streaming dataset now emits `base_hidden_prenorm` and can configure RDMA backends from environment settings. * **Bug Fixes** * Rejects mixed `base_hidden_prenorm` values within a batch. * Fails fast on streaming token-length mismatches. * Streaming dataset loading supports directory inputs by expanding sorted JSONL shards (and errors if none are found). * **Tests** * Added/updated unit and dataset tests for final-norm behavior and the new batch field. <!-- end of auto-generated comment: release notes by coderabbit.ai --> Signed-off-by: h-guo18 <67671475+h-guo18@users.noreply.github.com> |
||
|
ZhiyuandClaude Opus 4.8
|
f335459dc0 |
refactor(examples): rename llm_ptq → hf_ptq (symlink for back-compat) (#1759)
## What does this PR do? **Type of change:** refactor / deprecation (examples) Follow-up to #1705 (which consolidated `examples/vlm_ptq` into `examples/llm_ptq`). Since that example now covers Hugging Face **LLM and VLM** PTQ, the `llm_ptq` name is a misnomer. This renames the directory to `examples/hf_ptq` and leaves a relative symlink `examples/llm_ptq → hf_ptq` so existing paths/commands keep working during a deprecation window. Requested by @kevalmorabia97 on #1705 (with the symlink-for-back-compat approach), targeted for the **same 0.46 release** as the consolidation. ### Changes - `git mv examples/llm_ptq → examples/hf_ptq` and `tests/examples/llm_ptq → tests/examples/hf_ptq` (the CI runner maps the matrix name to both `examples/<name>` and `tests/examples/<name>`). - Add a tracked back-compat symlink `examples/llm_ptq → hf_ptq`. - Update CI matrices and all repo **path references** (docs, READMEs, agent skills, launcher/debugger tools, tests) from `llm_ptq` to `hf_ptq`. - Keep Python identifiers / test-util module names (`run_llm_ptq_command`, `llm_ptq_utils`) — they name the LLM-PTQ task, not the directory. - Preserve the CODEOWNERS team slug (`modelopt-examples-llm_ptq-codeowners`) and historical CHANGELOG entries; add a CHANGELOG deprecation note. ### Back-compat caveats (inherent to git directory symlinks) - ✅ Linux/macOS CLI usage and Python `cwd`/pytest resolution work through the symlink. - ⚠️ Windows git checkouts don't materialize symlinks by default (low impact — this example is Linux-only in practice). - ⚠️ GitHub web doesn't follow directory symlinks, so legacy external deep-links to `examples/llm_ptq/...` won't navigate in. All **internal** references are repointed to `hf_ptq`, so the symlink is only for legacy external/CLI use. ### Usage (unchanged via symlink) ```bash # New canonical path cd examples/hf_ptq scripts/huggingface_example.sh --model <hf_model> --quant fp8 # Old path still works (forwards via symlink) cd examples/llm_ptq && scripts/huggingface_example.sh --model <hf_model> --quant fp8 ``` ### Testing - `bash -n` on moved/edited shell scripts (new path + via symlink). - `py_compile` on moved/edited Python; test re-export shim repointed to `examples/hf_ptq/example_utils`. - Verified git tracks `examples/llm_ptq` as a single symlink (mode 120000), not a duplicated tree (no pre-commit / pytest double-processing). - `pre-commit run` on all changed files passes. ### Before your PR is "*Ready for review*" - Is this change backward compatible?: ✅ (relative symlink keeps `examples/llm_ptq` paths valid; see caveats above) - Did you write any new necessary tests?: N/A (pure rename; existing tests moved with the dir) - Did you update Changelog?: ✅ ### Additional Information Follow-up (later release): remove the `examples/llm_ptq` symlink once external references have migrated. 🤖 Generated with [Claude Code](https://claude.com/claude-code) <!-- This is an auto-generated comment: release notes by coderabbit.ai --> ## Summary by CodeRabbit * **New Features** * PTQ guidance now directs to the unified Hugging Face PTQ flow, including VLM quantization via the shared `--vlm` entry point. * **Documentation** * Updated README and guide links, references, and command snippets to use `hf_ptq` (replacing `llm_ptq`). * Deprecated and consolidated `vlm_ptq` into `hf_ptq`; removed VILA/NVILA coverage from the Hugging Face PTQ examples. * **Bug Fixes** * Improved detection and routing so local/manual setup uses the correct PTQ source. * **Tests / Chores** * CI and example tests updated to run the `hf_ptq` variants. <!-- end of auto-generated comment: release notes by coderabbit.ai --> --------- Signed-off-by: Zhiyu Cheng <zhiyuc@nvidia.com> Co-authored-by: Claude Opus 4.8 (1M context) <noreply@anthropic.com> |
||
|
|
c248dd5434 |
[Feat]: Domino support (#1710)
### What does this PR do? Type of change: New feature Adds **Domino** speculative decoding: the parallel DFlash draft backbone plus a lightweight **GRU causal correction head**. The backbone produces *base* logits for a full draft block in one forward; a GRU over the block's teacher-forced tokens produces a causal state that is fused with the backbone hidden state and projected to a vocab-sized logit correction on the block suffix — injecting the intra-block causal dependency the parallel backbone lacks. Trained with a dual loss `(1-λ)*final + λ*base`, where `λ_base` decays linearly 1→0 (curriculum: learn the parallel backbone first, then the correction). Reuses the DFlash mode/config/recipe; selected via `dflash_architecture_config.projector_type=domino` and routed to its own registry so `HFDominoModel` does not shadow `HFDFlashModel`. Exports in the z-lab/SpecForge drafter format (`prefix_gru.*` / `embed_proj.*`). > Note: the inference side (vLLM / AR evaluation) is intentionally **not** wired up yet — the correction head is not applied in serving. To be added once the inference path lands. ### Usage ```bash # Online training (recipe: projector_type=domino) uv run launch.py --yaml examples/Qwen/Qwen3-8B/hf_online_domino.yaml --yes ``` ### Testing CPU unit tests in `tests/unit/torch/speculative/plugins/test_hf_domino.py` cover conversion routing, the training forward (dual loss + grads), the λ schedule, and the export format. Online Qwen3-8B training validated end-to-end (loss curve below). <img width="1803" height="809" alt="image" src="https://github.com/user-attachments/assets/7c9d2001-bd80-4dec-919b-443e61089cca" /> ### Before your PR is "*Ready for review*" - Is this change backward compatible?: ✅ (opt-in via `projector_type=domino`; DFlash path unchanged) - If you copied code from any other sources or added a new PIP dependency, did you follow guidance in `CONTRIBUTING.md`: N/A (no new dependency) - Did you write any new necessary tests?: ✅ - Did you update [Changelog](https://github.com/NVIDIA/Model-Optimizer/blob/main/CHANGELOG.rst)?: ✅ - Did you get Claude approval on this PR?: ❌ ### Additional Information Reference: SpecForge PR #571 (z-lab); drafter format `huggingface.co/Huang2020/Qwen3-8B-Domino-b16`. <!-- This is an auto-generated comment: release notes by coderabbit.ai --> ## Summary by CodeRabbit ## Release Notes * **New Features** * Added Domino speculative-decoding training with a decaying base/final dual-loss curriculum and Domino-specific lambda scheduling (training-only; inference wiring not yet included). * Added Domino draft-head export support for training checkpoints. * **Documentation & Configuration** * Added a Domino speculative-decoding training recipe and an HF Online Domino launcher configuration for Qwen3-8B. * **Refactor** * Updated speculative model conversion/export to route to Domino variants based on the configured projector type. * **Tests** * Added unit tests for Domino conversion, training loss/metrics, lambda decay behavior, and exporter output layout. <!-- end of auto-generated comment: release notes by coderabbit.ai --> --------- Signed-off-by: h-guo18 <67671475+h-guo18@users.noreply.github.com> Signed-off-by: Keval Morabia <28916987+kevalmorabia97@users.noreply.github.com> Co-authored-by: Claude Opus 4.8 (1M context) <noreply@anthropic.com> Co-authored-by: Keval Morabia <28916987+kevalmorabia97@users.noreply.github.com> |
||
|
Keval Morabia
|
b6bf6b7997 |
Update Roadmap Issue link
Signed-off-by: Keval Morabia <28916987+kevalmorabia97@users.noreply.github.com> |
||
|
jzh26andh-guo18
|
48f8d8984f |
Fix conversation loading logic in UltraChat dataset (#1680)
### What does this PR do?
Type of change: Bug fix.

<!-- Details about the change. -->
Previously, only the first user prompt was extracted from each example,
discarding all subsequent turns. UltraChat stores full multi-turn
conversations in the "messages" field, so switching to that field
preserves the complete dialogue rather than truncating to a single user
message.
### Usage

```python
# Add a code snippet demonstrating how to use this
```

### Testing
 python make_dataset.py -f test_cfg.yaml --full
 python make_dataset.py -f test_cfg.yaml
```yaml
      - name: "ultrachat"
        splits:
          train_gen: 100
          train_sft: 100
```
### Before your PR is "*Ready for review*"

Make sure you read and follow [Contributor
guidelines](https://github.com/NVIDIA/Model-Optimizer/blob/main/CONTRIBUTING.md)
and your commits are signed (`git commit -s -S`).

Make sure you read and follow the [Security Best
Practices](https://github.com/NVIDIA/Model-Optimizer/blob/main/SECURITY.md#security-coding-practices-for-contributors)
(e.g. avoiding hardcoded `trust_remote_code=True`, `torch.load(...,
weights_only=False)`, `pickle`, etc.).

- Is this change backward compatible?: ✅ / ❌ / N/A <!--- If ❌, explain
why. -->
- If you copied code from any other sources or added a new PIP
dependency, did you follow guidance in `CONTRIBUTING.md`: ✅ / ❌ / N/A
<!--- Mandatory -->
- Did you write any new necessary tests?: ✅ / ❌ / N/A <!--- Mandatory
for new features or examples. -->
- Did you update
[Changelog](https://github.com/NVIDIA/Model-Optimizer/blob/main/CHANGELOG.rst)?:
✅ / ❌ / N/A <!--- Only for new features, API changes, critical bug fixes
or backward incompatible changes. -->
- Did you get Claude approval on this PR?: ✅ / ❌ / N/A <!--- Run
`/claude review`. NVIDIA org members can self-trigger for complex
changes; orthogonal to CodeRabbit. -->

### Additional Information
<!-- E.g. related issue. -->


<!-- This is an auto-generated comment: release notes by coderabbit.ai
-->
## Summary by CodeRabbit

* **Breaking Changes**
* Removed UltraChat support from the example dataset mixer, so UltraChat
splits can no longer be loaded.

* **Documentation**
* Updated the dataset examples README and the example dataset
configuration to remove UltraChat and adjust split settings for other
datasets.
* Updated the speculative decoding fine-tuning documentation to
reference Daring-Anteater instead of UltraChat.
<!-- end of auto-generated comment: release notes by coderabbit.ai -->

---------

Signed-off-by: jzh26 <226629529+jzh26@users.noreply.github.com>
Signed-off-by: h-guo18 <67671475+h-guo18@users.noreply.github.com>
Co-authored-by: h-guo18 <67671475+h-guo18@users.noreply.github.com>
|
||
|
h-guo18
|
9048d13b86 |
[Feat]:Support DPace (#1724)
### What does this PR do? Type of change: New feature Adds the **D-PACE** (Dynamic Position-Aware Cross-Entropy) loss objective for DFlash speculative-decoding training ([arXiv:2605.18810](https://arxiv.org/abs/2605.18810)). It replaces the static exponential position decay with per-position CE weights derived from the draft's own confidence `q_i = exp(-CE_i)`: smoothed `q̃_i = (1-α)q_i + α` (Eq.7) and weighted by the suffix-sum of prefix products `w_j = Σ_{m≥j} ∏_{i≤m} q̃_i` (Eq.8), which directly targets expected accepted block length and shifts signal toward whichever positions currently limit acceptance. Selected via `dflash_loss_objective` — **D-PACE is now the default** (`dpace`); set `dflash_loss_objective: decay` to restore the previous static schedule. Smoothing via `dflash_dpace_alpha` (default 0.5). Weights are detached from the gradient — training-only, ~2.3% overhead, no architecture or inference change. Mutually exclusive with `dflash_loss_decay_factor`. ### Usage ```yaml # DFlash recipe / training config dflash: dflash_loss_objective: dpace # default: decay dflash_dpace_alpha: 0.5 # smoothing in (0, 1]; stable in [0.3, 0.7] ``` ### Testing CPU unit tests in `tests/unit/torch/speculative/plugins/test_hf_dflash.py`: weights match the paper closed form, are detached and non-increasing, the α smoothing floor keeps later weights non-zero, and convert wires/validates the new fields (rejects bad objective and degenerate α). Training validated on Qwen3-8B (curve below). <img width="1803" height="809" alt="image" src="https://github.com/user-attachments/assets/d34dcd76-9e46-4051-94d4-c880b1987965" /> ### Before your PR is "*Ready for review*" - Is this change backward compatible?: ⚠️ Behavior change — D-PACE is now the **default** objective, so DFlash training loss weighting changes unless you set `dflash_loss_objective=decay` (which reproduces the previous static-decay behavior). - If you copied code from any other sources or added a new PIP dependency, did you follow guidance in `CONTRIBUTING.md`: N/A (no new dependency) - Did you write any new necessary tests?: ✅ - Did you update [Changelog](https://github.com/NVIDIA/Model-Optimizer/blob/main/CHANGELOG.rst)?: ✅ - Did you get Claude approval on this PR?: ❌ ### Additional Information Reference: D-PACE, [arXiv:2605.18810](https://arxiv.org/abs/2605.18810). See `examples/speculative_decoding/doc/dflash.md` for the math and tuning notes. <!-- This is an auto-generated comment: release notes by coderabbit.ai --> ## Summary by CodeRabbit ## Release Notes * **New Features** * Added a **D-PACE** training loss objective for DFlash speculative decoding (`dflash_loss_objective: dpace`), configurable via `dflash_dpace_alpha` (default `0.5`). * **Documentation** * Documented D-PACE’s confidence-derived, dynamically weighted per-position loss behavior (training-only) and noted that `dflash_loss_decay_factor` is ignored with D-PACE. * **Bug Fixes** * Updated DFlash loss to reuse the precomputed per-token cross-entropy in the non-KD path. * **Tests** * Added unit tests for D-PACE weight correctness, masking, gradient detachment, monotonicity, smoothing, and config/validation behavior. <!-- end of auto-generated comment: release notes by coderabbit.ai --> --------- Signed-off-by: h-guo18 <67671475+h-guo18@users.noreply.github.com> |
||
|
h-guo18
|
977d34dc3c |
[Fix](nvbug6304585): specdec README online base-model example should use Instruct model (#1755)
### What does this PR do?

Type of change: Bug fix

The **Training Draft Model with Online/Offline Base Model** examples in
`examples/speculative_decoding/README.md` used
`meta-llama/Llama-3.2-1B`, a
base / pretrained checkpoint that ships **no chat template**. The online
EAGLE3
flow tokenizes conversations through
`tokenizer.apply_chat_template(...)`, so
the data collator fails fast at startup:

```
ValueError: No valid chat template!
```

This PR:

- Switches both README example commands (online and offline) to
  `meta-llama/Llama-3.2-1B-Instruct`, which carries a chat template.
- Makes the collator error message in
`modelopt/torch/utils/plugins/transformers_dataset.py` actionable — it
now
explains the cause (base checkpoints have no chat template) and points
users
  at an Instruct model or a custom `chat_template`.

### Usage

```bash
./launch_train.sh \
    --config ../../modelopt_recipes/general/speculative_decoding/eagle3.yaml \
    model.model_name_or_path=meta-llama/Llama-3.2-1B-Instruct \
    data.data_path=input_conversations/train.jsonl \
    training.output_dir=ckpts/llama-3.2-1b-online
```

### Testing

- Reproduced the original `No valid chat template!` failure with the
base
`Llama-3.2-1B` and confirmed the Instruct variant carries a chat
template.
- Verified the new error message renders correctly when a template is
missing.

### Before your PR is "*Ready for review*"

Make sure you read and follow [Contributor
guidelines](https://github.com/NVIDIA/Model-Optimizer/blob/main/CONTRIBUTING.md)
and your commits are signed (`git commit -s -S`).

Make sure you read and follow the [Security Best
Practices](https://github.com/NVIDIA/Model-Optimizer/blob/main/SECURITY.md#security-coding-practices-for-contributors)
(e.g. avoiding hardcoded `trust_remote_code=True`, `torch.load(...,
weights_only=False)`, `pickle`, etc.).

- Is this change backward compatible?: ✅
- If you copied code from any other sources or added a new PIP
dependency, did you follow guidance in `CONTRIBUTING.md`: N/A
- Did you write any new necessary tests?: N/A
- Did you update
[Changelog](https://github.com/NVIDIA/Model-Optimizer/blob/main/CHANGELOG.rst)?:
N/A
- Did you get Claude approval on this PR?: ❌

### Additional Information

Fixes nvbug 6304585: https://nvbugspro.nvidia.com/bug/6304585


<!-- This is an auto-generated comment: release notes by coderabbit.ai
-->

## Summary by CodeRabbit

## Release Notes

* **Documentation**
* Updated speculative decoding example training commands to reference
the Llama-3.2-1B-Instruct model.

* **Bug Fixes**
* Enhanced error message when chat template configuration is missing,
providing actionable guidance for resolution.

<!-- end of auto-generated comment: release notes by coderabbit.ai -->

Signed-off-by: h-guo18 <67671475+h-guo18@users.noreply.github.com>
|
||
|
h-guo18
|
e6790ef7b4 |
[Examples]: GPT-oss, Qwen3Moe streaming specdec example (#1692)
### What does this PR do?

Type of change: new example

Adds **streaming speculative-decoding examples (EAGLE3 + DFlash)** for
**gpt-oss-20b** and **Qwen3-30B-A3B** to the ModelOpt launcher,
mirroring the existing Qwen3-8B/Kimi examples.

- New yamls:
`tools/launcher/examples/{openai/gpt-oss-20b,Qwen/Qwen3-30B-A3B}/hf_streaming_{eagle3,dflash}_multi_node.yaml`,
plus gpt-oss `chat_template_train.jinja` (generation-tagged, for
`answer_only_loss`).
- `eagle_utils.py`: the streaming path now installs a custom
`data.chat_template` on the tokenizer (the online path already did) —
needed for the tagged template.

### Usage

```bash
cd tools/launcher
export SLURM_HOST=... SLURM_ACCOUNT=... SLURM_HF_LOCAL=... SLURM_JOB_DIR=...
uv run launch.py --yaml examples/openai/gpt-oss-20b/hf_streaming_eagle3_multi_node.yaml --yes
```

### Testing

Pipeline sanity test on **unsynthesized** data (daring-anteater), 1×
H100-80GB, 12k steps. All four train and pass the vLLM acceptance-length
eval:

| Model | Method | Train speed | vLLM AL |
|---|---|---|---|
| Qwen3-30B-A3B | EAGLE3 | 7.12 it/s | **1.74** |
| Qwen3-30B-A3B | DFlash | 2.31 it/s | 1.29 |
| gpt-oss-20b | EAGLE3 | 5.07 it/s | 1.19 |
| gpt-oss-20b | DFlash | 2.01 it/s | 1.14 |

<img width="1300" height="780" alt="image"
src="https://github.com/user-attachments/assets/2be22562-5b77-4a9f-9dc0-6f936a059736"
/>

> Sanity test only, not a quality run. gpt-oss AL is low because it is a
reasoning model (CoT at inference) while daring-anteater has no
reasoning traces and `answer_only_loss` masks all but the final content
— quality runs need synthesized/reasoning data.

### Before your PR is "*Ready for review*"

- Is this change backward compatible?: ✅
- If you copied code from any other sources or added a new PIP
dependency, did you follow guidance in `CONTRIBUTING.md`: N/A
- Did you write any new necessary tests?: N/A
- Did you update
[Changelog](https://github.com/NVIDIA/Model-Optimizer/blob/main/CHANGELOG.rst)?:
N/A
- Did you get Claude approval on this PR?: ❌


<!-- This is an auto-generated comment: release notes by coderabbit.ai
-->

## Summary by CodeRabbit

## Release Notes

* **New Features**
* Added multi-node speculative decoding pipeline configurations for
Qwen3-30B-A3B and gpt-oss-20b with DFlash and EAGLE3 support.
* Introduced chat template training support for improved model
instruction formatting.

* **Enhancements**
* Increased benchmark concurrency from 1 to 32 across Qwen3-8B
configurations for more realistic performance evaluation.
  * Extended training runs from 500 to 2000 steps for Kimi-K2.5 models.
  * Improved chat template handling in speculative decoding workflows.

<!-- end of auto-generated comment: release notes by coderabbit.ai -->

---------

Signed-off-by: h-guo18 <67671475+h-guo18@users.noreply.github.com>
|
||
|
yeyu-nvidiaandClaude Opus 4.6
|
e004d8d90e |
DFlash speculative decoding for MiniMax-M2.7 (FSDP2): auto mask-token, FSDP2 resume fixes, per-checkpoint draft export (#1621)
## What
Brings up DFlash block-diffusion speculative decoding for large MoE
targets (MiniMax-M2.7, 229B) trained under accelerate FSDP2, and fixes
the regressions that broke checkpoint resume and per-checkpoint draft
export.
## Commits
- **auto-add mask token for DFlash** when the tokenizer lacks one
(resize embeddings, restore dtype).
- **requeue support** in `build_slurm_executor` + **FSDP2
cpu_ram_efficient_loading** for 229B on multi-node.
- **FSDP2 buffer patch** (`fsdp2_buffer_patch.py`): handle non-DTensor
buffers in `fsdp2_load_full_state_dict`, broadcast dtype codes from rank
0, and an FSDP2-safe `clip_grad_norm_`. Required because MiniMax-M2.7
pins transformers 4.57.x (no native `ParallelismConfig`).
- **dtype fix**: use the broadcast dtype (rank 0) rather than the local
meta-device param dtype, so non-leader ranks don't cast bf16 back to
fp32 on resume.
- **restore `DFlashExportCallback`** (this PR's headline): the
Pydantic-recipe refactor (
|
||
|
h-guo18
|
46eddab877 |
[Feat]: Specdec Streaming: RDMA + Multinode (#1611)
### What does this PR do? Type of change: New feature Multi-node **streaming** training for speculative decoding (EAGLE3 / DFlash): a live `vllm serve` captures the target model's hidden states and moves them straight to the trainer over **NIXL RDMA** — no disk round-trip. The streaming dataset is map-style — each rank fetches only its own `DistributedSampler` shard (concurrency from `dataloader_num_workers`), round-robins across multiple serve replicas (`server_urls`), and scales to multi-node DDP. Serve-side tensor parallelism (TP>1) is supported: hidden states are replicated across TP ranks, so rank 0 alone owns the pool + transfer. ### How - `RdmaHiddenStatesConnector` — out-of-tree vLLM connector (no vLLM source edits): one pre-registered pinned NIXL pool per serve, a ring slot per request, and a small HTTP sidecar serving transfer metadata. The trainer RDMA-READs the slot into a per-worker buffer. RDMA is the **only** transport (the earlier disk/safetensors path is removed). - Map-style dataset + multi-node accelerate launch (`--machine_rank`, optional Slurm `--segment` to keep nodes in one NVLink domain). ### Usage ```yaml data: mode: streaming streaming_server_url: "http://node0:8000,http://node1:8000" # round-robin ``` ### Validation (Qwen3-8B, oci-nrt H100) sandbox CI: https://gitlab-master.nvidia.com/omniml/integration/nmm-sandbox/-/jobs/337489812 **1. End-to-end convergence — EAGLE3 & DFlash, 5000 steps.** Both algorithms converge and export a deployable draft; the DFlash drafts also serve under vLLM speculative decoding (8/8 smoke prompts pass). | algorithm | topology (nodes) | train loss (step 0 → 5000) | vLLM draft acc-len | |---|---|---|---| | EAGLE3 | 2 serve TP=2 + 2 trainer DDP (4) | 37.1 → 8.20 | — | | DFlash | 1 serve TP=1 + 1 trainer (2) | 11.7 → 5.56 | 1.11 | | DFlash | 2 serve TP=2 + 2 trainer DDP (4) | 10.9 → 5.26 | 1.19 | <!-- Drag these PNGs in here (GitHub turns them into asset URLs): eagle3_streaming_loss.png, dflash_streaming_loss_singlenode.png, dflash_streaming_loss_multinode.png --> **2. Scalability — 1 → 12 nodes (EAGLE3, 200 steps).** Throughput scales ~23× across the sweep below. The step-time growth is cross-node DDP all-reduce, not the streaming path — RDMA (~0.33 ms/req @ 2 MB, ~47 GB/s host-pinned READ) is never the bottleneck. Scale serve + trainer nodes together for near-linear speedup. | serve / trainer | nodes | step time | samples / step | samples / sec (global) | acc @ step 200 | |---|---|---|---|---|---| | 1 serve / 1 rank (co-located, 1 node 2 GPU) | 1 | 0.23 s | 1 | 4.4 | [0.141, 0.094, 0.072] | | 1 serve / 1 rank (cross-node) | 2 | 0.23 s | 1 | 4.3 | [0.137, 0.105, 0.074] | | 2 serve / 8 ranks | 3 | 0.26 s | 8 | 31.1 | [0.215, 0.126, 0.097] | | 4 serve / 16 ranks (2 trainer nodes) | 6 | 0.28 s | 16 | 56.5 | [0.217, 0.148, 0.110] | | 8 serve / 32 ranks (4 trainer nodes) | 12 | 0.31 s | 32 | 101.9 | [0.235, 0.165, 0.137] | **3. Serve-side TP correctness.** TP=1 vs TP=2 draft top-1 accuracy track step-for-step (hidden states are replicated across TP ranks). <img width="910" height="546" alt="serve-tp-acc" src="https://github.com/user-attachments/assets/73df9214-7ff0-4ab4-bf2f-95842b12cd5f" /> ### Before your PR is "*Ready for review*" - Backward compatible?: ❌ — streaming is now RDMA-only; `server_url` → `server_urls`; the disk transport (`HS_TRANSPORT`, `streaming_shared_storage_path`) is removed. - New tests?: ✅ `tests/unit/torch/speculative/plugins/test_hf_streaming_dataset.py` (map-style dataset + mocked RDMA fetch). - Updated Changelog?: ❌ - Claude approval?: ❌ --------- Signed-off-by: h-guo18 <67671475+h-guo18@users.noreply.github.com> |
||
|
yeyu-nvidiaandClaude Opus 4.6
|
5bd04c3876 |
Revert unverified EAGLE3 model examples; keep triage code + baseline (#1623)
### What does this PR do? Type of change: Revert / cleanup (follow-up to #1417) Per review feedback (@h-guo18): `main` should be production-ready and user-facing. Most of the EAGLE3 model example YAMLs added in #1417 are not yet verified to work end-to-end in modelopt (~80% fail at some pipeline stage), which is confusing to ship. The agreed plan is to **land the triage infrastructure now and re-add each model's launcher YAML in a dedicated follow-up PR once it is verified green**. **Removed** (unverified, to be re-added per-model once verified): - Per-model launcher configs (`hf_offline_eagle3.yaml` + `eagle3_quick_check.yaml`) for: DeepSeek-V3.2, GLM-5, MiniMax-M2.5, Ministral-3-8B, Ministral-3-14B, Kimi-K2.5, Kimi-K2.5-NVFP4, GPT-OSS-20B, Qwen3.5-9B, Qwen3.5-27B, Qwen3.5-35B-A3B, Step-3.5-Flash. - Per-model status docs: `tools/launcher/examples/EAGLE3_TRIAGE.md`, `examples/speculative_decoding/pipeline/eagle3/eagle3_triage_chart.md` (volatile status — tracked internally instead). **Kept** (the durable triage infrastructure from #1417): - Verified baseline example `tools/launcher/examples/Qwen/Qwen3-8B/eagle3_quick_check.yaml`. - Launcher common scripts (vLLM native-extractor dump, etc.) and `compute_hidden_states_vllm.py`. - modelopt code fixes: FakeBaseModel VLM detection, `consolidated.safetensors` load, `use_cache` export templates. - New-model triage guide (`eagle3_new_model_triage_guide.md`); its "document results" step now points at the internal tracker rather than the removed chart. ### Testing No code paths change — this only removes example YAMLs and two status docs and edits one doc reference. Pre-commit (ruff/markdownlint/yaml/license) passes on the kept/edited files. ### Before your PR is "*Ready for review*" - Is this change backward compatible?: ✅ (removes unverified examples only; kept infra unchanged) - If you copied code from any other sources or added a new PIP dependency, did you follow guidance in `CONTRIBUTING.md`: N/A - Did you write any new necessary tests?: N/A - Did you update Changelog?: N/A - Did you get Claude approval on this PR?: ❌ (pending) ### Additional Information Follow-up to #1417. Next step (tracked separately): verify each removed model end-to-end in modelopt, then re-add its YAML in a dedicated PR. Note: the nmm-sandbox weekly EAGLE3 CI is being trimmed to the Qwen3-8B baseline to match. 🤖 Generated with [Claude Code](https://claude.com/claude-code) <!-- This is an auto-generated comment: release notes by coderabbit.ai --> ## Summary by CodeRabbit * **Documentation** * Updated EAGLE3 triage guide to streamline the verification workflow; contributors now record test outcomes (status, experiment IDs, errors, and applied fixes) in the team's internal triage tracker before submitting model launcher configurations. * **Chores** * Removed legacy EAGLE3 example pipeline configurations and deprecated triage documentation to reduce maintenance overhead. <!-- end of auto-generated comment: release notes by coderabbit.ai --> Signed-off-by: Ye Yu <yeyu@nvidia.com> Co-authored-by: Claude Opus 4.6 <noreply@anthropic.com> |
||
|
yeyu-nvidiaandClaude Opus 4.6
|
a7b0a92047 |
EAGLE3 new model support: pipeline configs, triage docs, and Ministral-3 fixes (#1417)
## Summary EAGLE3 automation triage work (OKR-30): testing the 4-step EAGLE3 offline pipeline against 12 new model architectures, documenting failure modes, and fixing issues found. ### Code fixes (modelopt) | File | Change | |------|--------| | `modelopt/torch/speculative/utils.py` | Extend VLM detection in `load_vlm_or_llm` to check `text_config`/`llm_config` attrs (catches `mistral3` models) | | `modelopt/torch/speculative/plugins/modeling_fakebase.py` | Add `consolidated.safetensors` fallback for checkpoints with incomplete HF shards | | `modelopt/torch/export/plugins/hf_spec_configs.py` | Set `use_cache=True` in EAGLE export templates (fixes strict `huggingface_hub` validation) | ### Pipeline infrastructure - `examples/speculative_decoding/pipeline/eagle3/` — pipeline scripts and configs: - `offline_training.sh` — training + export with runtime patches for older container modelopt - `dump_offline_data_vllm.sh` — vLLM-based hidden state extraction (with speculators compat patches) - `dump_offline_data.sh`, `dump_offline_data_hf.sh` — alternative dump paths - 18 quick-fail-check YAMLs for 12 models - 4 standalone task1 YAMLs ### Documentation - `eagle3_triage_chart.md` — model test matrix, triage decision tree, per-model results, failure catalog - `eagle3_new_model_triage_guide.md` — step-by-step guide for triaging new models ### Model test results (as of 2026-05-27) | Model | task_0 | task_1 | task_2 | task_3 | Blocker | |-------|--------|--------|--------|--------|---------| | Qwen3-8B | - | - | - | - | Reference (existing) | | Kimi-K2.5 | - | - | - | - | Existing (GB200) | | **Ministral-3-8B** | SKIP | PASS | PASS | FAIL | `use_cache=null` in export (fixed) | | Ministral-3-14B | FAIL | - | - | FAIL | vLLM engine init fails | | Qwen3.5-35B-A3B | TIMEOUT | - | - | - | Data synth too slow | | gpt-oss-20b | FAIL | - | - | - | Tokenizer `HarmonyError` | | Step-3.5-Flash | TIMEOUT | - | - | - | Data synth time limit | | MiniMax-M2.5 | TIMEOUT | - | - | - | `trust_remote_code` needed | | DeepSeek-V3.2 | no log | - | - | - | May not be mirrored | | Qwen3.5-9B | - | - | - | - | Not yet run | | Qwen3.5-27B | - | - | - | - | Not yet run | | GLM-5 | - | - | - | - | Not yet run | ### Issues found and fixed | # | Issue | Fix | |---|-------|-----| | 1 | `mistral3` model type not detected as VLM | Check `text_config`/`llm_config` attrs in `load_vlm_or_llm` | | 2 | Missing HF shard file (Ministral-3-8B) | Fallback to `consolidated.safetensors` with Mistral native key aliases | | 3 | `use_cache=null` in exported EAGLE config | Set `use_cache=True` in export template configs | | 4 | speculators incompatible with vLLM container | Runtime patches in `dump_offline_data_vllm.sh` | | 5 | `offline_training.sh` infra issues | Rewritten with runtime patches for container modelopt | ## Test plan - [x] Ministral-3-8B training passes (`cicd_1779829129`) - [x] Ministral-3-8B export succeeds - [ ] Ministral-3-8B benchmark passes (`cicd_1779901409` — pending with all fixes) - [ ] Dry-run remaining model configs ## Note GitHub secret scanning alert #6 is a **false positive** — `Mistral3ForConditionalGeneration` (a HuggingFace model class name in a YAML comment) was flagged as a "Mistral AI API Key". 🤖 Generated with [Claude Code](https://claude.com/claude-code) --------- Signed-off-by: Ye Yu <yeyu@nvidia.com> Co-authored-by: Claude Opus 4.6 <noreply@anthropic.com> |
||
|
yeyu-nvidia
|
651fd223e6 |
feat: EAGLE3 LoRA co-training improvements (#1607)
Layer-selective LoRA injection for EAGLE3 co-training, optimizer-stable warmup (LoRA always in the optimizer; warmup gated by a flag), and an export+merge+lm_eval evaluation script. Review feedback addressed: - trust_remote_code is caller-controlled (TRUST_REMOTE_CODE / --trust_remote_code), default False - eagle_base_lora_start_layer raises ValueError instead of silently injecting zero adapters - eval_lora.sh validates HF_MODEL_CKPT / EAGLE_CKPT up front - added unit tests for start-layer injection and validation (8/8 passing, incl. on-cluster GPU run) Signed-off-by: Ye Yu <yeyu@nvidia.com> |
||
|
h-guo18
|
902d36921a |
[Feat]: Streaming Hidden-states Dataset (#1509)
### What does this PR do? Type of change: new feature **Design doc:** https://gist.github.com/h-guo18/241c94968b0591324c361d97cf995dd0 Jira ticket: https://jirasw.nvidia.com/browse/OMNIML-4341 Sandbox CI: https://gitlab-master.nvidia.com/omniml/integration/nmm-sandbox/-/jobs/327911555#L2228 Streaming hidden-states dataset: per-sample activations pulled from a live `vllm serve` over HTTP, replacing on-disk activation dumps. Two axes for future extensions: - **Backend** (`_fetch`): vLLM now; TRT-LLM / SGLang next. - **Algorithm** (`_format`): Eagle now; distillation / probing next. - **Sandbox CI**: https://gitlab-master.nvidia.com/omniml/integration/nmm-sandbox/-/merge_requests/169 Shared plumbing — async producer, token-level truncation to `training_seq_len`, loss-mask alignment, DDP via Accelerate's dispatcher (rank 0 fetches, broadcasts), circuit breaker, resume — lives in `StreamingDataset`. First instance: **`EagleVllmStreamingDataset`**. API: `data.mode ∈ {online, offline, streaming}`; legacy configs auto-promote. ### Usage ```yaml data: mode: streaming data_path: input_conversations/train.jsonl streaming_server_url: http://localhost:8000 streaming_model_name: meta-llama/Llama-3.1-8B-Instruct training: training_seq_len: 4096 # also caps the prompt sent to vllm ``` Requires `vllm serve` with `ExampleHiddenStatesConnector` and `dataloader_num_workers=0`. End-to-end Slurm pipeline: `tools/launcher/examples/Qwen/Qwen3-8B/hf_streaming_eagle3.yaml`. ### Testing - **Unit**: full-corpus invariant, rank-0-only iter, resume, circuit breaker, mocked-httpx integration. - **E2E**: `launch_train.sh` against a stdlib `HTTPServer` mimicking the connector. - **Smoke** (Qwen3-8B / 8×H100 / 4096 ultrachat samples, single epoch): train_loss 32 → 18, MT-Bench AR 1.003 → 1.20. ### TODO before un-drafting - [ ] Observability counters (filtered, fetch failures, queue depth, latency). - [ ] Changelog entry. - [x] Add test in sandbox. **Non-goals (v1):** multi-epoch streaming, cross-rank dynamic load balancing. ### Before your PR is "*Ready for review*" - Backward compatible: ✅ (legacy configs auto-promote) - New PIP dep: N/A - New tests: ✅ - Changelog: ❌ (TODO above) - Claude approval: ❌ <!-- This is an auto-generated comment: release notes by coderabbit.ai --> ## Summary by CodeRabbit * **New Features** * Streaming training mode with server-backed hidden-state fetching, deterministic seed control, resume support, and streaming-specific dataset options (server, model, prefetch, shared storage). * **Behavior / Bug Fixes** * Stronger mode validation; offline behavior derived from data mode; resume handling adjusted to avoid double-skip during streaming runs. * **Tests** * End-to-end CI streaming test and expanded unit tests covering streaming, resume, DDP, determinism, and failure cases. * **Infrastructure** * Launcher script and pipeline config for end-to-end streaming training. <!-- review_stack_entry_start --> [](https://app.coderabbit.ai/change-stack/NVIDIA/Model-Optimizer/pull/1509?utm_source=github_walkthrough&utm_medium=github&utm_campaign=change_stack) <!-- review_stack_entry_end --> <!-- end of auto-generated comment: release notes by coderabbit.ai --> --------- Signed-off-by: h-guo18 <67671475+h-guo18@users.noreply.github.com> |
||
|
h-guo18
|
40a4dd326d |
[Feat]: Eagle Dry Run Mode (#1566)
### What does this PR do? Type of change: new feature Adds `--dry_run` to `examples/speculative_decoding/main.py`: load → `mtsp.convert` → save, then exit (no `trainer.train()`). With `FakeBaseModel`, the convert→save→export chain runs in seconds and produces an exportable EAGLE3 / Medusa / DFlash checkpoint with correct structure but untrained draft-head weights — useful for end-to-end plumbing smoke tests on downstream stacks (vLLM, TRT-LLM, SGLang) without paying for a real training run. Where it sits among existing EAGLE3 modes: ``` EAGLE3 modes ├── online base model runs forward in-loop ├── offline reads pre-dumped hidden states from disk ├── streaming streams hidden states from a live server in-loop └── dry-run ★ skip training entirely; convert + save + export ← NEW (this PR) ``` Companion `FakeBaseModel` fixes so small base checkpoints work: - Synthesize the weight_map from a single `model.safetensors` when no sharded index is present (Llama-3.2-1B, Qwen3-0.6B, …). - Honor `tie_word_embeddings`: reuse `embed_tokens` when `lm_head` is absent from safetensors. A new launcher YAML (`tools/launcher/examples/Qwen/Qwen3-8B/hf_eagle3_dryrun.yaml`) wires this together as a one-task pipeline. ### Usage ```bash # Direct python main.py --dry_run \ --config modelopt_recipes/general/speculative_decoding/eagle3.yaml \ model.model_name_or_path=meta-llama/Llama-3.1-8B-Instruct \ model.use_fake_base_for_offline=true \ data.offline_data_path=/tmp/dryrun-placeholder \ training.output_dir=ckpts/dryrun python scripts/export_hf_checkpoint.py --model_path ckpts/dryrun --export_path export/dryrun # Launcher uv run launch.py --yaml examples/Qwen/Qwen3-8B/hf_eagle3_dryrun.yaml --yes ``` ### Testing - `tests/unit/torch/speculative/plugins/test_fakebase.py`: 3 new cases — single-file fallback, tied-embeddings fallback, and the negative case (missing `lm_head` without tying). - `tests/examples/speculative_decoding/test_eagle.py::test_eagle3_dry_run`: full `launch_train.sh --dry_run → export_hf_checkpoint.py` chain on `tiny_llama`; asserts exported state_dict has all `LLAMA_EAGLE_SINGLE_LAYER` required keys. - Manually verified end-to-end on Llama-3.1-8B-Instruct (sharded), Llama-3.2-1B-Instruct (single-file + tied), and Qwen3-0.6B (single-file). ### Before your PR is "*Ready for review*" - Is this change backward compatible?: ✅ — `--dry_run` is opt-in; `FakeBaseModel` changes are additive fallbacks. - If you copied code from any other sources or added a new PIP dependency, did you follow guidance in `CONTRIBUTING.md`: N/A - Did you write any new necessary tests?: ✅ - Did you update [Changelog](https://github.com/NVIDIA/Model-Optimizer/blob/main/CHANGELOG.rst)?: N/A — examples-only addition. - Did you get Claude approval on this PR?: ❌ ### Additional Information N/A <!-- This is an auto-generated comment: release notes by coderabbit.ai --> ## Summary by CodeRabbit * **New Features** * Added a `--dry_run` CLI flag to perform a fast early-exit execution that saves model artifacts without training. * Added support for single-file model checkpoint formats in the loader. * **Bug Fixes** * Improved checkpoint-loading error messages and handling. * Enhanced tied-embeddings fallback when head weights are absent. * **Tests** * Added integration and unit tests covering dry-run behavior and single-file/tied-embedding loading. * **Documentation** * Added a launcher example for dry-run smoke testing. <!-- review_stack_entry_start --> [](https://app.coderabbit.ai/change-stack/NVIDIA/Model-Optimizer/pull/1566?utm_source=github_walkthrough&utm_medium=github&utm_campaign=change_stack) <!-- review_stack_entry_end --> <!-- end of auto-generated comment: release notes by coderabbit.ai --> --------- Signed-off-by: h-guo18 <67671475+h-guo18@users.noreply.github.com> |
||
|
Shengliang Xu
|
9d0d97829a |
chore(lint): modernize typing (PEP 604/585) and enable UP032 (#1537)
### What does this PR do? Type of change: chore / refactor (no behavior change) Two small lint-cleanup commits: **1. `chore(typing): modernize Union/Optional/List to PEP 604 / 585 syntax`** (8 files) - Replace `X = Union[A, B] # noqa: UP007` with `X: TypeAlias = A | B` for the six module-level type aliases (`ModelLike`, `Criterion`, `NodeTarget`, `CalibrationDataType`, `Hparam.Importance` / `ActiveSlice`). The `TypeAlias` annotation is required so mypy continues to treat them as aliases under PEP 604. - Modernize forward-ref unions in `modelopt/onnx/quantization/autotune/` to full-string forward refs (e.g. `"RegionPattern | None"`). - Update docstring type tags in `examples/puzzletron/evaluation/hf_deployable_anymodel.py`. **2. `chore(lint): remove UP032 ignore and convert .format() to f-strings`** (10 files) - Drop `UP032` from `extend-ignore` in `pyproject.toml`. - Auto-convert 19 `"...".format(...)` calls to f-strings across export plugins, examples, tests, and tools. One conversion in `modelopt/torch/utils/plugins/megatron_generate.py` was wrapped manually to stay under the 100-char limit. **Intentionally left as-is:** - `tools/launcher/slurm_config.py` keeps its `# ruff: noqa: UP045` — nemo_run's CLI parser can't introspect PEP 604 optional annotations. - `modelopt/torch/puzzletron/*` is **not** touched. The subtree disables ruff's `UP` family entirely (per-file-ignore `"UP"`) while migration is in progress, and converting `Optional[X]` to `X | None` there would silently break runtime introspection in `block_config._get_dataclass_type` that uses `get_origin(tp) is typing.Union` (PEP 604 unions return `types.UnionType` from `get_origin`, not `typing.Union`). Best revisited when puzzletron's lint carve-out is narrowed. - `UP038` (`isinstance(x, (int, float))` → `isinstance(x, int | float)`) — ruff has officially deprecated this rule; PEP 604 in isinstance is slightly slower and misleads readers about PEP 695 / `Optional`. Ignore kept. ### Usage No user-facing API changes. ### Testing - Pre-commit hooks (ruff check, ruff format, mypy, bandit, license) pass on both commits. - Ruff status against `main`: 37 unrelated pre-existing findings (W291/W293/E501/RUF005/PLR1704); zero new findings introduced by this PR. ### Before your PR is "*Ready for review*" - Is this change backward compatible?: ✅ — Runtime behavior of the six type aliases changes from a `typing.Union` instance to `types.UnionType`. Downstream code introspecting via `get_origin(...) is typing.Union` on these aliases would break, but no in-repo caller does this on them. (The introspection in `modelopt/torch/puzzletron/block_config.py` operates on user-supplied dataclass field types, none of which are these aliases.) - If you copied code from any other sources or added a new PIP dependency, did you follow guidance in `CONTRIBUTING.md`: N/A - Did you write any new necessary tests?: N/A (no behavior change) - Did you update [Changelog](https://github.com/NVIDIA/Model-Optimizer/blob/main/CHANGELOG.rst)?: ❌ — internal style refactor; happy to add a Misc note if reviewers want one. - Did you get Claude approval on this PR?: ❌ — not yet. <!-- This is an auto-generated comment: release notes by coderabbit.ai --> ## Summary by CodeRabbit * **Style** * Modernized type annotations across the codebase to use Python 3.10+ union syntax and TypeAlias where appropriate. * Standardized string formatting to f-strings, improving clarity of logs, errors, and validation messages. * **Chores** * Updated linting configuration to reflect modern typing/style rules. <!-- review_stack_entry_start --> [](https://app.coderabbit.ai/change-stack/NVIDIA/Model-Optimizer/pull/1537?utm_source=github_walkthrough&utm_medium=github&utm_campaign=change_stack) <!-- review_stack_entry_end --> <!-- end of auto-generated comment: release notes by coderabbit.ai --> --------- Signed-off-by: Shengliang Xu <shengliangx@nvidia.com> |
||
|
h-guo18
|
7038dec918 |
[1/2Refactor] speculative decoding: use mto config subsystem (#1328)
### What does this PR do?

Type of change: new feature

Port the speculative-decoding example to ModelOpt's recipe/config
subsystem: `model` / `data` / `training` / `<algo>` now load from a
single YAML with Pydantic validation and OmegaConf dotlist overrides.
Adds built-in `eagle3` / `dflash` recipes, drops the redundant
`training.mode` field (inferred from recipe class), and shrinks
`main.py` by ~145 lines (−208 / +63).

JIRA: OMNIML-3859

### Usage

```bash
python main.py --config general/speculative_decoding/eagle3 \
    model.model_name_or_path=meta-llama/Llama-3.2-1B \
    data.data_path=train.jsonl \
    training.output_dir=ckpts/test
```

### Testing

- `pytest tests/unit/recipe/test_loader.py` — new coverage for Eagle /
DFlash YAML loading, dotlist overrides, and field-level validation.
- Smoke-trained both built-in `eagle3` and `dflash` recipes end-to-end.

### Before your PR is "*Ready for review*"

Make sure you read and follow [Contributor
guidelines](https://github.com/NVIDIA/Model-Optimizer/blob/main/CONTRIBUTING.md)
and your commits are signed (`git commit -s -S`).

Make sure you read and follow the [Security Best
Practices](https://github.com/NVIDIA/Model-Optimizer/blob/main/SECURITY.md#security-coding-practices-for-contributors)
(e.g. avoiding hardcoded `trust_remote_code=True`, `torch.load(...,
weights_only=False)`, `pickle`, etc.).

- Is this change backward compatible?: ❌ — `main.py` CLI switched to
`--config <recipe>` (+ dotlist overrides); the old argparse flags are
removed.
- If you copied code from any other sources or added a new PIP
dependency, did you follow guidance in `CONTRIBUTING.md`: N/A — no new
deps (`pydantic`, `omegaconf` already in core).
- Did you write any new necessary tests?: ✅ —
`tests/unit/recipe/test_loader.py`.
- Did you update
[Changelog](https://github.com/NVIDIA/Model-Optimizer/blob/main/CHANGELOG.rst)?:
❌ — to be added.

### Additional Information

Follow-up to the `modelopt.recipe` subsystem introduced for PTQ; this PR
extends the same declarative-YAML pattern to speculative decoding
(Eagle3 / DFlash / Medusa).


<!-- This is an auto-generated comment: release notes by coderabbit.ai
-->
## Summary by CodeRabbit

* **New Features**
* Added typed speculative-decoding recipe support for EAGLE, DFlash, and
Medusa; CLI dotlist overrides supported for single-file recipes.
* Trainer/config schema extended with speculative-training fields and
draft-vocab cache loading for Eagle.

* **Bug Fixes**
* Offline training no longer mutates model configs; loader enforces
required algorithm sections and prints recipe/config only on the primary
process.
* Reduced noisy per-rank logging by restricting status output to the
primary process.

* **Tests**
* Expanded tests for recipe loading, dotlist overrides, validation
strictness, and error cases.

* **Documentation**
  * Recipe YAMLs updated with metadata and usage notes.
<!-- end of auto-generated comment: release notes by coderabbit.ai -->

---------

Signed-off-by: h-guo18 <67671475+h-guo18@users.noreply.github.com>
|
||
|
yeyu-nvidiaandClaude Sonnet 4.6
|
383ab4e224 |
fix: include medusa in data_module assignment in main.py (#1370)
## Problem
When `training.mode == "medusa"` is used in `main.py`, the `data_module`
variable is never assigned because line 344 only covered `eagle3` and
`dflash` modes. This causes an `UnboundLocalError` when the trainer is
constructed with `**data_module`.

Fixes OMNIML-4147

## Fix
Add `"medusa"` to the `training_args.mode in ("eagle3", "dflash")`
condition so `data_module` is correctly populated for medusa training.

<!-- This is an auto-generated comment: release notes by coderabbit.ai
-->

## Summary by CodeRabbit

* **Bug Fixes**
* Fixed speculative decoding example to properly handle "medusa" mode
alongside existing "eagle3" and "dflash" modes.

<!-- end of auto-generated comment: release notes by coderabbit.ai -->

Signed-off-by: Ye Yu <yeyu@nvidia.com>
Co-authored-by: Claude Sonnet 4.6 <noreply@anthropic.com>
|
||
|
h-guo18
|
1ec931c2c7 |
[2/3][Feat]: Offline DFlash training (#1343)
### What does this PR do? Type of change: new feature Part 2 of a 3-PR series splitting #1271: - **[1/3] #1296**: File reorg + deprecate `ParallelDraft` - **[2/3] this PR**: Offline DFlash training (depends on #1296) - **[3/3] #1297**: Extract `HFSpecDecMixin` Changes: - Add `dflash_offline` flag to `DFlashConfig` for training from pre-computed hidden states; deletes base model layers to save memory. - Add Pydantic validators on `DFlashConfig`: - `_derive_dflash_offline` — auto-derive `dflash_offline` from `data_args.offline_data_path` in validation context. Not user-configurable: any user-supplied value is overridden by the derived value. - `_resolve_mask_token_id` — auto-detect `dflash_mask_token_id` from `tokenizer.mask_token_id`. - `_check_mask_token_id` — fail fast if unset after resolution. - `HFDFlashModel.modify()`: select `num_orig_hidden_layers` when offline; pick `_base_model_lm_head` device when no base layers present; drop base-model `layers` module. - `HFDFlashModel.forward()`: add offline branch — consumes precomputed `base_model_outputs` via `DFlashBaseModelOutput.from_offline_dict`, and when `dflash_self_logit_distillation` is enabled with `base_model_logits` absent, recomputes logits from `base_model_hidden_states` via `_base_model_lm_head`. Raises a clear error from the non-training / `pseudo_speculative_generate` paths when `dflash_offline=True`, since base-model layers have been deleted. - `DFlashBaseModelOutput` dataclass in `modeling_dflash.py` (with `from_offline_dict` classmethod) to unify online/offline output shapes. `aux_hidden_states` is required in `from_offline_dict` so missing keys fail fast at the entry point rather than deeper in the forward. - `examples/speculative_decoding/main.py`: replace inline `mask_token_id` auto-detect with `DFlashConfig.model_validate(dflash_cfg, context={"tokenizer": tokenizer, "data_args": data_args})`. ### Silent bug fix — `add_generation_template` → `add_generation_prompt` The pre-refactor `compute_hidden_states_hf.py` passed `add_generation_template=False` to `tokenizer.apply_chat_template`. This kwarg does not exist on HF `apply_chat_template` and was being silently ignored, so the intended "don't append a generation prompt" behavior was never actually applied. The new `tokenize_with_loss_mask` helper in `examples/speculative_decoding/collect_hidden_states/common.py` uses the correct `add_generation_prompt=False`. **This is a real behavior change** for anyone re-dumping hidden states: trailing generation prompts that were previously appended to the tokenized sequences will no longer be included. ### Testing - New tests: - `tests/unit/torch/speculative/plugins/test_hf_dflash_offline.py` — CPU unit tests for convert path (online keeps base layers, offline deletes them; `num_orig_hidden_layers` drives `target_layer_ids` in offline mode) and `DFlashConfig._derive_dflash_offline` validator. - `TestDFlashOfflineForwardGPU` in `tests/gpu/torch/speculative/plugins/test_hf_dflash.py` — GPU forward smoke with precomputed `base_model_outputs`, plus the `dflash_self_logit_distillation` logit-recompute path. - training test: <img width="454" height="317" alt="image" src="https://github.com/user-attachments/assets/79b92790-4d15-4313-bb9b-f35665b012e6" /> <img width="456" height="310" alt="image" src="https://github.com/user-attachments/assets/4558559f-9c35-49ed-b36e-82fbc99eab23" /> ### Before your PR is "*Ready for review*" Make sure you read and follow [Contributor guidelines](https://github.com/NVIDIA/Model-Optimizer/blob/main/CONTRIBUTING.md) and your commits are signed (`git commit -s -S`). Make sure you read and follow the [Security Best Practices](https://github.com/NVIDIA/Model-Optimizer/blob/main/SECURITY.md#security-coding-practices-for-contributors) (e.g. avoiding hardcoded `trust_remote_code=True`, `torch.load(..., weights_only=False)`, `pickle`, etc.). - Is this change backward compatible?: ✅ — additive `dflash_offline` flag defaulting to `False`; validators fall through when context not provided. - If you copied code from any other sources or added a new PIP dependency, did you follow guidance in `CONTRIBUTING.md`: N/A - Did you write any new necessary tests?: ✅ — see Testing section above. - Did you update [Changelog](https://github.com/NVIDIA/Model-Optimizer/blob/main/CHANGELOG.rst)?: ✅ ### TODO (follow-up) - [x] Update `examples/speculative_decoding/collect_hidden_states/compute_hidden_states_*.py` to support DFlash offline data. Current scripts are Eagle-specific — they hardcode the `[2, N/2, N-3]` aux-layer selection and emit `{input_ids, hidden_states, aux_hidden_states}`. DFlash offline needs: - Aux layer indices driven by `build_target_layer_ids(num_orig_hidden_layers, num_draft_layers)` (or a configurable list), not the Eagle triplet. - `base_model_hidden_states` key (last-layer hidden) so `DFlashBaseModelOutput.from_offline_dict` + the `dflash_self_logit_distillation` recompute path can consume it. - Optional `base_model_logits` dump so offline training can skip the self-distillation logit recomputation when logits are available. ### Additional Information Base branch is #1296 (file reorg). Retarget to `main` once #1296 merges. <!-- This is an auto-generated comment: release notes by coderabbit.ai --> ## Summary by CodeRabbit * **New Features** * Offline DFlash speculative-decoding training from precomputed base-model hidden states * Answer-only-loss training with persisted loss masks and optional chat-template support * Flexible auxiliary-layer selection via CLI and an exposed default aux-layer helper * Auto-derived offline flag in config and automatic memory optimization during offline conversion * **Documentation** * Updated guides for offline pipeline, aux-layer selection, and loss-masking options * **Tests** * New unit, GPU, and regression tests covering offline conversion, training, and config derivation <!-- end of auto-generated comment: release notes by coderabbit.ai --> --------- Signed-off-by: h-guo18 <67671475+h-guo18@users.noreply.github.com> |
||
|
h-guo18
|
7c80d85751 |
[1/3][Refactor]: File reorg; deprecate ParallelDraft (#1296)
### What does this PR do? Type of change: refactoring Part 1 of a 3-PR series splitting #1271: - **[1/3] this PR**: File reorg + deprecate `ParallelDraft` - **[2/3] #1295**: Offline DFlash training - **[3/3] #1297**: Extract `HFSpecDecMixin` Changes: - **File reorg**: `transformers.py` → `hf_eagle.py`; extract `HFMedusaModel` → `hf_medusa.py`; extract `EagleModule` / `EagleBaseModelOutput` → `modeling_eagle.py`; extract `DFlashModule` / `DFlashAttention` / `DFlashDecoderLayer` / `build_target_layer_ids` / `apply_rotary_pos_emb` → `modeling_dflash.py`. - **Deprecate `ParallelDraft`**: remove `parallel_draft_step`, `parallel_draft_heads_num_layers`, and the `ParallelDraft` module from HF Eagle; remove the `EagleMedusaExporter` branch from `HFEagleModel.get_exporter()` (the `EagleMedusaExporter` class itself still lives in `hf_spec_export.py` for Megatron parity). - **Rename**: `_draft_model_config` → `eagle_config` in export plugin. - Update imports in `examples/speculative_decoding/` and `modelopt/torch/speculative/utils.py` to follow the module rename. ### Testing Validated with existing Eagle and DFlash training scripts (re-run after `9ae5302729 revert behavior change`). ### Before your PR is "*Ready for review*" Make sure you read and follow [Contributor guidelines](https://github.com/NVIDIA/Model-Optimizer/blob/main/CONTRIBUTING.md) and your commits are signed (`git commit -s -S`). Make sure you read and follow the [Security Best Practices](https://github.com/NVIDIA/Model-Optimizer/blob/main/SECURITY.md#security-coding-practices-for-contributors) (e.g. avoiding hardcoded `trust_remote_code=True`, `torch.load(..., weights_only=False)`, `pickle`, etc.). - Is this change backward compatible?: ❌ — renames `modelopt.torch.speculative.plugins.transformers` → `.hf_eagle`; removes `parallel_draft_step` / `parallel_draft_heads_num_layers` from Eagle config; renames `_draft_model_config` → `eagle_config` in export plugin. - If you copied code from any other sources or added a new PIP dependency, did you follow guidance in `CONTRIBUTING.md`: N/A - Did you write any new necessary tests?: N/A — pure refactor; existing tests updated for the rename. `test_hf_spec_rope_export.py` assertions were also corrected to reflect the actual production path (the old assertions were masked by `MagicMock` not invoking the `_draft_model_config` `@property`). - Did you update [Changelog](https://github.com/NVIDIA/Model-Optimizer/blob/main/CHANGELOG.rst)?: ❌ ### Additional Information Breaking changes: - `modelopt.torch.speculative.plugins.transformers` → `.hf_eagle` - `parallel_draft_step` / `parallel_draft_heads_num_layers` removed from Eagle config - `_draft_model_config` → `eagle_config` in export plugin <!-- This is an auto-generated comment: release notes by coderabbit.ai --> ## Summary by CodeRabbit * **Refactoring** * Reorganized speculative-decoding plugins into focused modules, converting the legacy "transformers" entry into a deprecated shim that re-exports the new plugin surface. * Consolidated DFlash implementation into a shared modeling component and introduced a dedicated EAGLE decoder module. * **New Features** * Added a Medusa speculative-decoding plugin with configurable heads and combined-loss training behavior. * **Chores** * Updated pre-commit license-hook exclusion and feature-flag wiring. * **Tests** * Updated export tests to expect rope-scaling fallback semantics. <!-- end of auto-generated comment: release notes by coderabbit.ai --> --------- Signed-off-by: h-guo18 <67671475+h-guo18@users.noreply.github.com> |
||
|
yeyu-nvidiaandClaude Opus 4.6
|
2fef374ded |
fix: auto-compute dp_replicate_size from world_size (#1302)
## Summary - When `dp_shard_size < world_size` (e.g., `dp_shard_size=4` on 8 GPUs across 2 nodes), `ParallelismConfig` raises `total_size (4) does not match num_processes (8)` because `dp_replicate_size` defaults to 1 - Auto-compute `dp_replicate_size = world_size // (dp_shard_size * cp_size)` so intra-node FSDP2 sharding + inter-node data-parallel replication works without manual config - This enables `dp_shard_size` to be set to per-node GPU count (better NVLink utilization) while automatically creating replicas across nodes ## Test plan - [ ] Verify single-node training (dp_shard_size == world_size, dp_replicate_size == 1) unchanged - [ ] Verify multi-node with dp_shard_size < world_size creates correct replica groups - [ ] Verify existing EAGLE3/DFlash configs still work 🤖 Generated with [Claude Code](https://claude.com/claude-code) <!-- This is an auto-generated comment: release notes by coderabbit.ai --> ## Summary by CodeRabbit * **Refactor** * Enhanced parallelism configuration initialization in the speculative decoding example to better handle distributed training scenarios. <!-- end of auto-generated comment: release notes by coderabbit.ai --> Signed-off-by: Ye Yu <yeyu@nvidia.com> Co-authored-by: Claude Opus 4.6 <noreply@anthropic.com> |
||
|
Chenhan D. YuandClaude Opus 4.6
|
355c6b7883 |
fix: PTQ 1GPU, export PP divisibility, hidden states conversations key (#1293)
## Summary - **megatron_lm_ptq.yaml**: Qwen3-8B PTQ to single GPU for L40 clusters (TP=1, all tasks) - **quantize.sh**: Auto-find largest PP dividing model's `num_hidden_layers` for export step. Qwen3-8B has 36 layers which isn't divisible by 8, causing `AssertionError` on 8-GPU nodes - **compute_hidden_states_trtllm.py**: Use `messages` with `conversations` fallback, matching the HF version. Fixes `KeyError: 'conversations'` when data uses OpenAI `messages` format ## Test plan - [x] Qwen3-8B PTQ runs on single L40 GPU - [x] Export PP auto-selects valid divisor (36 layers → PP=6 on 8 GPUs, PP=4 on 4 GPUs, PP=1 on 1 GPU) - [x] EAGLE3 offline pipeline reads data with `messages` field 🤖 Generated with [Claude Code](https://claude.com/claude-code) <!-- This is an auto-generated comment: release notes by coderabbit.ai --> ## Summary by CodeRabbit * **New Features** * Dataset input handling now supports multiple field formats for enhanced compatibility. * **Bug Fixes** * Optimized GPU resource allocation during model quantization with improved pipeline parallelism computation. * Updated quantization configuration for more efficient resource utilization. <!-- end of auto-generated comment: release notes by coderabbit.ai --> Signed-off-by: Chenhan Yu <chenhany@nvidia.com> Co-authored-by: Claude Opus 4.6 (1M context) <noreply@anthropic.com> |
||
|
yeyu-nvidiaandClaude Opus 4.6
|
07ae8e7128 |
Add LoRA co-training support for HF EAGLE speculative decoding (#1060)
### What does this PR do?

Type of change: New feature + bug fixes

Adds **LoRA co-training** support for HF EAGLE speculative decoding.
When `eagle_base_lora=True`, HF PEFT LoRA adapters are injected into the
base model and co-trained alongside the EAGLE draft module in a single
online training pass. A preservation loss (KL divergence between the
original frozen base model output and the LoRA-adapted output) prevents
base model drift. LoRA adapter weights are exported in standard peft
format alongside EAGLE draft artifacts.

### Key features

- **LoRA injection**: `peft.inject_adapter_in_model` applied in-place
(no wrapper), keeping the existing `HFEagleModel` structure intact.
- **Preservation loss**: Cross-entropy `H(ref, lora)` — equivalent
gradient to `KL(ref || lora)` since `H(ref)` is constant w.r.t. LoRA
params.
- **Warmup schedule**: `eagle_base_lora_warmup_steps` freezes LoRA for N
steps while the EAGLE head stabilizes, then enables co-training via a
`LoRAWarmupCallback`.
- **Logits detach regularization**: `eagle_base_lora_logits_detach_prob`
stochastically detaches base logits from the EAGLE loss path, preventing
LoRA from degenerating to maximize EAGLE accuracy at the cost of base
model quality.
- **Export**: Standard peft format (`adapter_model.safetensors` +
`adapter_config.json`) alongside EAGLE draft model.
- **Merge script**: `scripts/merge_lora.py` merges LoRA weights into the
base model and restores the original `config.json` (avoids transformers
5.x rewriting `rope_theta` → `rope_parameters` which breaks
vLLM/TRT-LLM).
- **Multinode fix**: `dp_shard_size` now uses `WORLD_SIZE` instead of
local GPU count.

### Config options

```python
mtsp.convert(model, mode=[("eagle", {
    "eagle_base_lora": True,                          # enable LoRA co-training
    "eagle_base_lora_rank": 64,                       # LoRA rank
    "eagle_base_lora_alpha": 16.0,                    # LoRA scaling
    "eagle_base_lora_target_modules": ["q_proj", "k_proj", "v_proj", "o_proj"],
    "eagle_base_lora_preservation_loss_weight": 0.1,  # preservation loss weight
    "eagle_base_lora_warmup_steps": 0,                # freeze LoRA for N steps
    "eagle_base_lora_logits_detach_prob": 0.5,        # detach prob (0=never, 1=always)
})])
```

### Experimental results (Qwen3-8B, checkpoint-60000)

Base model quality preserved across detach_prob sweep (lm_eval: IFEval,
ARC-C, Winogrande — results pending final collection).

**Acceptance rate** (mt_bench, draft_length=3, output_length=4096,
temperature=0):

| detach_prob | vLLM AR | TRT-LLM AR |
|---|---|---|
| baseline (no LoRA) | 2.14 | 2.15 |
| 0.5 | 1.45 | 1.44 |
| 0.8 | **3.06** | **3.01** |
| 0.85 | 2.90 | 2.90 |
| 0.9 | 2.76 | 2.77 |
| 0.95 | 2.51 | 2.58 |
| 0.99 | 2.37 | 2.37 |
| 0.999 | 2.30 | 2.27 |
| 0.9999 | 2.31 | 2.26 |

Best AR at `detach_prob=0.8`: ~40% improvement over baseline.

### Testing

`tests/unit/torch/speculative/plugins/test_hf_speculative_lora.py` (5
tests):
- `test_lora_layers_injected` — LoRA layers present after conversion
- `test_trainable_params` — only `lora_*` and `eagle_module` params are
trainable
- `test_forward_returns_loss` — forward returns non-zero scalar loss
- `test_eagle_offline_incompatible` — `eagle_base_lora=True` +
`eagle_offline=True` raises `ValueError`
- `test_export_lora_artifacts` — export produces standard peft adapter
files

### Bug fixes (included in this PR)

1. **`launch_train.sh` case pattern ordering**: glob
`--eagle_base_lora*` was before specific patterns
(`--eagle_base_lora_rank*`, etc.), silently swallowing LoRA args.
2. **LoRA optimizer exclusion during warmup**: warmup freezing excluded
LoRA from the optimizer entirely; fixed with `add_param_group` in the
callback.
3. **`merge_lora.py` config.json**: `save_pretrained()` with
transformers >=5.x rewrites `rope_theta` → `rope_parameters`, breaking
vLLM positional embeddings. Fixed by copying the original base model
config.
4. **Multinode `dp_shard_size`**: used local GPU count instead of
`WORLD_SIZE`.

### Checklist

- [x] Backward compatible (all new config fields have defaults)
- [x] Uses `peft` via lazy imports (no hard dependency)
- [x] Unit tests added
- [x] Online HF training only (`eagle_offline=True` blocked)

---------

Signed-off-by: Ye Yu <yeyu@nvidia.com>
Co-authored-by: Claude Opus 4.6 <noreply@anthropic.com>
|
||
|
Chenhan D. YuandClaude Opus 4.6
|
3131195241 |
add: DFlash block diffusion speculative decoding (#1211)
DFlash (Block Diffusion for Flash Speculative Decoding) predicts an entire block of tokens in a single forward pass using masked parallel prediction with KV injection from the target model's hidden states. Key features: - Feature fusion (multi-layer hidden states -> FC + RMSNorm) - KV injection (fused features as K/V in every draft layer with QK-norm) - Random anchor sampling with bidirectional intra-block attention - Logit distillation with exponential loss decay (gamma weighting) - Multi-node DDP training with checkpoint resume - Export to z-lab compatible HF format - Online validation (context-dependent ground truth) Training recipe: modelopt_recipes/general/speculative_decoding/dflash.yaml Results: examples/speculative_decoding/doc/dflash_results.md ### ModelOpt Eval (online validation, osl=512) | Dataset | z-lab | ModelOpt (306K) | Diff | |---------|-------|-----------------|------| | gsm8k | 4.10 | **5.19** | **+1.09** | | MT-Bench | 3.58 | **4.36** | **+0.78** | ### z-lab Official Eval (dflash.benchmark, osl=512) | Dataset | z-lab | ModelOpt (306K) | Diff | |---------|-------|-----------------|------| | gsm8k | **5.00** | 4.08 | -0.92 | | MT-Bench | **3.28** | 2.99 | -0.29 | > z-lab model trained with block_size=16. ModelOpt trained with block_size=8. ## Evaluation Method Impact (gsm8k) | Eval Method | z-lab checkpoint | ModelOpt (306K) | |-------------|-----------------|-----------------| | Fixed GT (ModelOpt eval) | 2.95 | 4.23 | | Online GT (ModelOpt eval) | 4.10 | **5.19** | | z-lab official eval | **5.00** | 4.08 | ### What does this PR do? Type of change: ? <!-- Use one of the following: Bug fix, new feature, new example, new tests, documentation. --> <!-- Details about the change. --> ### Usage ```python # Add a code snippet demonstrating how to use this ``` ### Testing <!-- Mention how have you tested your change if applicable. --> ### Before your PR is "*Ready for review*" Make sure you read and follow [Contributor guidelines](https://github.com/NVIDIA/Model-Optimizer/blob/main/CONTRIBUTING.md) and your commits are signed (`git commit -s -S`). Make sure you read and follow the [Security Best Practices](https://github.com/NVIDIA/Model-Optimizer/blob/main/SECURITY.md#security-coding-practices-for-contributors) (e.g. avoiding hardcoded `trust_remote_code=True`, `torch.load(..., weights_only=False)`, `pickle`, etc.). - Is this change backward compatible?: ✅ / ❌ / N/A <!--- If ❌, explain why. --> - If you copied code from any other sources or added a new PIP dependency, did you follow guidance in `CONTRIBUTING.md`: ✅ / ❌ / N/A <!--- Mandatory --> - Did you write any new necessary tests?: ✅ / ❌ / N/A <!--- Mandatory for new features or examples. --> - Did you update [Changelog](https://github.com/NVIDIA/Model-Optimizer/blob/main/CHANGELOG.rst)?: ✅ / ❌ / N/A <!--- Only for new features, API changes, critical bug fixes or backward incompatible changes. --> ### Additional Information <!-- E.g. related issue. --> <!-- This is an auto-generated comment: release notes by coderabbit.ai --> ## Summary by CodeRabbit * **New Features** * Added DFlash speculative decoding mode with parallel block prediction support. * Included training launchers and MT-Bench evaluation scripts for DFlash models. * Added online acceptance rate validation for improved inference verification. * **Documentation** * DFlash quick start guide with configuration parameters and training examples. * Performance results and benchmarks for DFlash-trained models. <!-- end of auto-generated comment: release notes by coderabbit.ai --> --------- Signed-off-by: Chenhan Yu <chenhany@nvidia.com> Co-authored-by: Claude Opus 4.6 (1M context) <noreply@anthropic.com> |
||
|
h-guo18
|
6403389eb0 |
Feat: Configurable Eagle ROPE scaling during export (#1238)
### What does this PR do? JIRA ticket: https://jirasw.nvidia.com/browse/OMNIML-3469 Type of change: New feature Decouple EAGLE training rope configuration from export rope configuration, enabling separate YaRN rope scaling injection at export time for long-context inference. #### Changes **Configurable export rope scaling (`EagleConfig`)** - Add `eagle_export_rope_scaling` field to `EagleConfig` with default YaRN config (`factor=32.0`, `original_max_position_embeddings=2048`) - Set to `{}` to disable rope scaling injection at export **Simplified training defaults (`default_config.py`)** - Change default training rope from `llama3` (theta=500k) to `default` (theta=10k) — models now train with simple positional embeddings; rope scaling is applied only at export - Add `rope_theta` inside `rope_scaling` dict for transformers 5.x cross-version compatibility **Move config validation/rewriting into `EagleConfig` (`config.py`)** - `_derive_eagle_offline`: derives `eagle_offline` from `data_args.offline_data_path` via validation context, removing manual assignment in `main.py` - `_check_rope_scaling_consistency`: rejects configs where `eagle_export_rope_scaling` is set but training `rope_type` is not `"default"` - `_warn_rope_vs_training_seq_len`: warns when `original_max_position_embeddings` differs from `training_seq_len` **Export rope injection (`hf_spec_export.py`)** - Inject `eagle_export_rope_scaling` into the exported HF config when training rope_type is `"default"` - Fall back `rope_theta` from `rope_scaling` dict for transformers 5.x compatibility **Fix Megatron RotaryEmbedding crash (`megatron_eagle.py`)** - `dict_to_config()` set `rope_scaling=True` whenever the `rope_scaling` key existed, even without a `"factor"` — causing `RotaryEmbedding` to divide by `None` - Now only enables `rope_scaling` when the dict actually contains a `"factor"` key ### Usage Configure in YAML config (or use defaults from `eagle3.yaml`): ```yaml eagle: eagle_export_rope_scaling: rope_type: yarn factor: 32.0 original_max_position_embeddings: 2048 ``` Set to empty dict to disable export rope injection: ```yaml eagle: eagle_export_rope_scaling: {} ``` ### Testing - New unit tests: `tests/unit/torch/speculative/test_eagle_config.py` — rope consistency validator, seq_len warning, context-derived `eagle_offline` - New unit tests: `tests/unit/torch/export/test_hf_spec_rope_export.py` — export rope injection, fallback, and empty-config cases ### Before your PR is "*Ready for review*" Make sure you read and follow [Contributor guidelines](https://github.com/NVIDIA/Model-Optimizer/blob/main/CONTRIBUTING.md) and your commits are signed (`git commit -s -S`). Make sure you read and follow the [Security Best Practices](https://github.com/NVIDIA/Model-Optimizer/blob/main/SECURITY.md#security-coding-practices-for-contributors) (e.g. avoiding hardcoded `trust_remote_code=True`, `torch.load(..., weights_only=False)`, `pickle`, etc.). - Is this change backward compatible?: ✅ (new field has sensible default; existing configs work unchanged) - If you copied code from any other sources or added a new PIP dependency, did you follow guidance in `CONTRIBUTING.md`: N/A - Did you write any new necessary tests?: ✅ - Did you update [Changelog](https://github.com/NVIDIA/Model-Optimizer/blob/main/CHANGELOG.rst)?: ❌ (should be added if merging as a feature) <!-- This is an auto-generated comment: release notes by coderabbit.ai --> ## Summary by CodeRabbit * **New Features** * Add export-time rope-scaling configuration for EAGLE models. * **Improvements** * Stronger validation and context-aware reconciliation between training and export configs. * Export now injects rope-scaling and rope-theta when appropriate. * Default rope-scaling values updated for EAGLE variants. * Model instances now expose export rope-scaling for downstream use. * **Tests** * Added unit tests covering rope-scaling export behavior and configuration validators. <!-- end of auto-generated comment: release notes by coderabbit.ai --> --------- Signed-off-by: h-guo18 <67671475+h-guo18@users.noreply.github.com> |
||
|
yeyu-nvidiaandClaude Sonnet 4.6
|
9050188034 |
Fix test_collect_hidden_states: use synthetic short conversations (#1234)
## Summary - `test_collect_hidden_states` was using real daring-anteater conversations (typically 1000+ tokens) but the tiny test model has `max_position_embeddings=32`. Both sampled conversations exceeded the default `--max-seq-len 3072` filter, producing zero `.pt` files and failing the assertion. - Added a `tiny_conversations_path` fixture with synthetic short single-turn conversations that tokenize within `max_position_embeddings=32`. - Changed `test_collect_hidden_states` to use this fixture with `--max-seq-len 32`. - Added a `None` guard for `tokenizer.chat_template.replace(...)` to avoid `AttributeError` when the tokenizer has no chat template. ## Test plan - [ ] `pytest tests/examples/speculative_decoding/test_eagle_offline_ptq.py::test_collect_hidden_states` passes - [ ] CI `speculative_decoding` job passes 🤖 Generated with [Claude Code](https://claude.com/claude-code) <!-- This is an auto-generated comment: release notes by coderabbit.ai --> ## Summary by CodeRabbit * **Bug Fixes** * Resolved compatibility issues when tokenizers do not have a chat template configuration by adding proper error handling. * Standardized tokenization input extraction logic across different transformer library versions for consistent behavior. * **Tests** * Enhanced test infrastructure with new conversation data fixtures and improved sequence length validation for speculative decoding examples. <!-- end of auto-generated comment: release notes by coderabbit.ai --> --------- Signed-off-by: Ye Yu <yeyu@nvidia.com> Co-authored-by: Claude Sonnet 4.6 <noreply@anthropic.com> |
||
|
yeyu-nvidiaandClaude Sonnet 4.6
|
c901814ff9 |
Fix compute_hidden_states_hf.py: handle BatchEncoding from apply_chat_template (#1225)
## Summary

- `apply_chat_template(..., return_tensors="pt")` returns a
`BatchEncoding` in transformers 4.46+, which no longer subclasses `dict`
- The old guard `isinstance(tokenized, dict)` evaluates to `False` for
`BatchEncoding`, so `input_ids` was set to the whole `BatchEncoding`
object
- Calling `.shape[1]` on a `BatchEncoding` triggers
`__getattr__("shape")` → `AttributeError`
- Fix: check `isinstance(tokenized, torch.Tensor)` instead, which
correctly handles both old transformers (plain tensor) and new
transformers (BatchEncoding)

This is causing `test_collect_hidden_states` to fail in the speculative
decoding CI for all open PRs (#1207, #1210, #1221).

## Test plan

- [ ] `torch-pr (speculative_decoding, 26.01)` CI passes
- [ ] Verify fix handles both `torch.Tensor` return (old transformers)
and `BatchEncoding` return (new transformers 4.46+)

🤖 Generated with [Claude Code](https://claude.com/claude-code)

Signed-off-by: Ye Yu <yeyu@nvidia.com>
Co-authored-by: Claude Sonnet 4.6 <noreply@anthropic.com>
|
||
|
Keval Morabia
|
04cd596d79 |
Add experimental support for transformers>=5.0 + min torch 2.8 (#975)
### What does this PR do? - Add experimental support for transformers >=5.0 and remove deprecated usages: https://github.com/huggingface/transformers/blob/main/MIGRATION_GUIDE_V5.md - ⚠️ For accelerate examples that used `--warmup-ratio: float` (deprecated in 5.x), we now change it to `--warmup-steps: float | int` which works as ratio if float but only for 5.x. For 4.x, it will error out if float and prompt user to change back to `--warmup-ratio` or pass an int absolute step count. - ⚠️ Unified Hugging Face checkpoint export for quantized checkpoints may not work for some models with transformers>=5.0 yet as it requires a lot of fixes (e.g. change in how MoE experts are organized) - ~Add Workaround for TRT-LLM's import of deprecated transformers functions so trt-llm based gpu unit tests work fine. Still deployment for models needs proper fixes directly in TRT-LLM hence llm/vlm ptq example tests still run with transformers 4.57~ - Everything except PTQ and Export (mainly MoE) should work fine with transformers>=5.0 - Bump min torch to 2.8 and enable 2.11 cicd testing - NOTE: Upcoming Nemo:26.04 container comes with transformers 5.3 ### Testing <!-- Mention how have you tested your change if applicable. --> - [x] CI/CD tests passing - [x] Manually tested unit tests, gpu tests with transformers 4.56 and 5.4 - [x] Manually tested example tests (except trt-llm container tests) with transformers 4.56 and 5.4 - [x] 2-gpu nightly CICD tests manually triggered and passing: [gpu tests](https://github.com/NVIDIA/Model-Optimizer/actions/runs/23867257540), [example tests](https://github.com/NVIDIA/Model-Optimizer/actions/runs/23867260643) ### Before your PR is "*Ready for review*" Make sure you read and follow [Contributor guidelines](https://github.com/NVIDIA/Model-Optimizer/blob/main/CONTRIBUTING.md) and your commits are signed (`git commit -s -S`). Make sure you read and follow the [Security Best Practices](https://github.com/NVIDIA/Model-Optimizer/blob/main/SECURITY.md#security-coding-practices-for-contributors) (e.g. avoiding hardcoded `trust_remote_code=True`, using `torch.load(..., weights_only=True)`, avoiding `pickle`, etc.). - Is this change backward compatible?: ✅ <!--- If ❌, explain why. --> - If you copied code from any other source, did you follow IP policy in [CONTRIBUTING.md](https://github.com/NVIDIA/Model-Optimizer/blob/main/CONTRIBUTING.md#-copying-code-from-other-sources)?: N/A <!--- Mandatory --> - Did you write any new necessary tests?: ✅ <!--- Mandatory for new features or examples. --> - Did you update [Changelog](https://github.com/NVIDIA/Model-Optimizer/blob/main/CHANGELOG.rst)?: ✅ <!--- Only for new features, API changes, critical bug fixes or backward incompatible changes. --> <!-- This is an auto-generated comment: release notes by coderabbit.ai --> ## Summary by CodeRabbit * **New Features** * Make remote-code usage opt-in via a configurable --trust_remote_code flag across examples and tools. * **Bug Fixes** * Improve checkpoint/resume detection and related training guidance to avoid erroneous errors. * **Refactor** * Consolidate dtype/config naming, switch warmup settings from ratio → steps, and unify tokenizer invocation patterns. * **Documentation** * Simplify changelog title and add misc notes for release 0.44. * **Chores** * Remove scheduled PR-branch cleanup workflow and relax/remove several transformers version pins. * **Tests** * Adjust test gates, skips, and structures to align with updated deps and behaviors. <!-- end of auto-generated comment: release notes by coderabbit.ai --> --------- Signed-off-by: Keval Morabia <28916987+kevalmorabia97@users.noreply.github.com> |
||
|
yeyu-nvidiaandClaude Sonnet 4.6
|
cccfded8a9 |
Add support for offline speculative decoding model PTQ (#883)
## What does this PR do? **Type of change:** new feature **Overview:** This PR enables loading in a ModelOpt pretrained offline speculative decoding model (e.g., EAGLE3) and performs PTQ on it and export. ## Usage Follow the speculative_decoding examples to train an offline speculative decoding model first. Then follow the command below to quantize and export it: ```bash python hf_ptq.py --pyt_ckpt_path <dir_of_offline_specdec_model> --specdec_offline_dataset <dir_of_dataset> ``` ## Testing <!-- Mention how have you tested your change if applicable. --> ## Before your PR is "*Ready for review*" <!-- If you haven't finished some of the above items you can still open `Draft` PR. --> - **Make sure you read and follow [Contributor guidelines](https://github.com/NVIDIA/Model-Optimizer/blob/main/CONTRIBUTING.md)** and your commits are signed. - **Is this change backward compatible?**: Yes/No <!--- If No, explain why. --> - **Did you write any new necessary tests?**: Yes/No - **Did you add or update any necessary documentation?**: Yes/No - **Did you update [Changelog](https://github.com/NVIDIA/Model-Optimizer/blob/main/CHANGELOG.rst)?**: Yes/No <!--- Only for new features, API changes, critical bug fixes or bw breaking changes. --> ## Additional Information <!-- E.g. related issue. --> <!-- This is an auto-generated comment: release notes by coderabbit.ai --> ## Summary by CodeRabbit * **New Features** * Offline speculative decoding workflow: support loading a local dataset for calibration, generation, and export; new CLI option to specify the offline dataset. * **Improvements** * Export and quantization paths now accept and propagate offline speculative-decoding inputs. * Offline data loading honors a sample-size limit and enforces safe batch sizing for calibration. * **Bug Fixes** * Better handling of model/config mismatches and varied batch types in offline flows. <!-- end of auto-generated comment: release notes by coderabbit.ai --> --------- Signed-off-by: Ye Yu <yeyu@nvidia.com> Co-authored-by: Claude Sonnet 4.6 <noreply@anthropic.com> |
||
|
Keval Morabia
|
ba4f42df1c |
Minor fix for example tests
Signed-off-by: Keval Morabia <28916987+kevalmorabia97@users.noreply.github.com> |
||
|
Keval Morabia
|
ebc534d765 |
Update code-copying guidelines in CONTRIBUTING.md
Signed-off-by: Keval Morabia <28916987+kevalmorabia97@users.noreply.github.com> |
||
|
Chenhan D. Yu
|
0246041b01 |
feat(speculative): add vLLM data synthesis pipeline and Nemotron dataset preparation scripts (#1176)
### What does this PR do? Type of change: New feature, new example, bug fix Adds a vLLM-based synthetic data generation pipeline for speculative decoding draft model training, along with dataset preparation scripts for NVIDIA's Nemotron Post-Training dataset collections. **Data synthesis pipeline** (`tools/launcher/common/vllm/query.sh` + `common/query.py`): - Launch a vLLM server and run multi-turn inference to synthesize training data from input conversation skeletons - Fork-safe OpenAI client: reinitializes HTTP connection pool after `datasets.map()` forks worker processes, preventing 400 errors from corrupted connections - Clear Docker `ENTRYPOINT` so vLLM containers (which default to `vllm serve`) work correctly under NeMo Run's executor - `--max-tokens` argument to bound generation length - Local file loading support (`--data /path/to/file.jsonl`) - Re-raise connection errors so `datasets.map()` halts the shard instead of silently producing empty rows - Map `developer` role to `system` (OpenAI format compatibility) **Multi-turn reasoning trace handling** (`common/query.py`): - Strip `<think>...</think>` blocks from intermediate assistant turns before re-feeding to the model; preserve the full trace only on the final turn **Nemotron dataset preparation** (`examples/dataset/`): - `make_nemotron_ptv2_dataset.py` — prepares [nvidia/Nemotron-Post-Training-Dataset-v2](https://huggingface.co/datasets/nvidia/Nemotron-Post-Training-Dataset-v2) (~3.3M rows generate, ~1.9M rows train) - `make_nemotron_ptv3_dataset.py` — prepares the [Nemotron PTv3 collection](https://huggingface.co/collections/nvidia/nemotron-post-training-v3) of 16 datasets (~3.4M rows generate, ~3.9M rows train) - Both support `generate` mode (strips assistant turns for synthesis input) and `train` mode (normalizes to clean OpenAI format for SFT) - `conversation_utils.py` — shared utilities: `strip_assistant_turns`, `normalize_messages`, `make_augment_fn`, `AugmentationSpec` - `augmentations.yaml` — 12 language-redirect variants + style/format hints, cycled across dataset rows - Scripts live in `examples/dataset/` (not under `speculative_decoding/`) to signal reusability beyond speculative decoding **Bug fixes**: - `strip_assistant_turns()`: return `{"messages": []}` when no user turns remain (system-only rows were previously passed through instead of being filtered) - `concatenate_datasets()`: guard against empty parts list - SSH tunnel user precedence: explicit `user` arg now correctly overrides `slurm_config.user` ### Usage ```bash # Prepare PTv3 input conversations for synthesis (~3.4M rows): python examples/dataset/make_nemotron_ptv3_dataset.py --output-dir /tmp/ptv3_gen # Launch vLLM server + synthesize responses: bash tools/launcher/common/vllm/query.sh \ --model /path/to/model \ --tensor-parallel-size 4 \ -- \ --data /tmp/ptv3_gen/default.jsonl \ --save /tmp/ptv3_responses \ --num-shards 10 --num-proc 4 --max-tokens 4096 # Prepare PTv2 for direct SFT training (~1.9M rows): python examples/dataset/make_nemotron_ptv2_dataset.py --mode train --output-dir /tmp/ptv2_train ``` ### Testing Tested end-to-end on an NVIDIA GB10 node (119 GiB GPU memory) with `vllm/vllm-openai:qwen3_5-cu130` container and `Qwen/Qwen3.5-4B`: - vLLM server starts correctly with cleared Docker entrypoint - `datasets.map(num_proc=4)` runs without connection errors (fork-safe client) - Multi-turn synthesis produces correct assistant responses with thinking traces handled ### Before your PR is "*Ready for review*" Make sure you read and follow [Contributor guidelines](https://github.com/NVIDIA/Model-Optimizer/blob/main/CONTRIBUTING.md) and your commits are signed (`git commit -s -S`). Make sure you read and follow the [Security Best Practices](https://github.com/NVIDIA/Model-Optimizer/blob/main/SECURITY.md#security-coding-practices-for-contributors) (e.g. avoiding hardcoded `trust_remote_code=True`, `torch.load(..., weights_only=False)`, `pickle`, etc.). - Is this change backward compatible?: ✅ - If you copied code from any other sources or added a new PIP dependency, did you follow guidance in `CONTRIBUTING.md`: N/A - Did you write any new necessary tests?: N/A (data synthesis scripts; tested manually) - Did you update [Changelog](https://github.com/NVIDIA/Model-Optimizer/blob/main/CHANGELOG.rst)?: N/A <!-- This is an auto-generated comment: release notes by coderabbit.ai --> ## Summary by CodeRabbit * **New Features** * Added dataset generation and augmentation capabilities for Nemotron post-training datasets (v2 and v3) * Enhanced query functionality with thinking-block filtering and improved client management for robust parallel processing * Added support for local dataset file paths alongside HuggingFace Hub datasets * **Bug Fixes** * Fixed SLURM executor user resolution and Docker container entrypoint configuration * Improved error handling for connection failures during dataset synthesis * **Documentation** * Updated dataset preparation guide with new generation modes and augmentation configuration details <!-- end of auto-generated comment: release notes by coderabbit.ai --> Signed-off-by: Chenhan D. Yu <5185878+ChenhanYu@users.noreply.github.com> Signed-off-by: Chenhan Yu <chenhany@nvidia.com> |
||
|
h-guo18
|
82d96a635f |
[Speculative Decoding] Refactor EAGLE3 training to YAML-based config and recipe system (#1134)
## What does this PR do?

Refactors EAGLE3 training to use a single base YAML config with
OmegaConf dotlist overrides.

**Type of change:** Refactor

## Changes

- Single base config
`modelopt_recipes/speculative_decoding/_base_eagle3.yaml` for all EAGLE3
training; removed per-model child YAMLs.
- `launch_train.sh` accepts `--config <yaml>` plus dotlist overrides
(e.g. `model.model_name_or_path=xxx`).
- Removed `__base__` YAML inheritance logic from `main.py`.
- `dp_shard_size` default changed from `0` sentinel to `None` for
clarity.
- Removed `eagle_config.json` and `fsdp_config.json`; architecture
config is now nested under `eagle.eagle_architecture_config` in YAML.
- `train_eagle3_and_export.sh` now uses base YAML + dotlist instead of
generating a temporary YAML.
- Updated README and tests accordingly.

## Usage

```bash
# Online training
./launch_train.sh \
    --config ../../modelopt_recipes/speculative_decoding/_base_eagle3.yaml \
    model.model_name_or_path=meta-llama/Llama-3.2-1B \
    data.data_path=input_conversations/train.jsonl \
    training.output_dir=ckpts/llama-3.2-1b-online

# Offline training
./launch_train.sh \
    --config ../../modelopt_recipes/speculative_decoding/_base_eagle3.yaml \
    model.model_name_or_path=meta-llama/Llama-3.2-1B \
    data.offline_data_path=$HIDDEN_STATES_DIR \
    training.output_dir=ckpts/llama-3.2-1b-offline
```

---------

Signed-off-by: h-guo18 <67671475+h-guo18@users.noreply.github.com>
|
||
|
Keval MorabiaandRinZ27
|
5dc17dfd15 |
[Security] Enable torch.load(weights_only=True) for secure checkpoint loading + trust_remote_code fix (#1181)
### What does this PR do? - Add secure checkpoint loading support using `torch.serialization.add_safe_globals([cls])`. This also removes 1 existing pickle usage. - Remove hard-coded `trust_remote_code=True` - Replaces https://github.com/NVIDIA/Model-Optimizer/pull/1056 by @RinZ27 ### Testing <!-- Mention how have you tested your change if applicable. --> CICD tests ran ### Before your PR is "*Ready for review*" Make sure you read and follow [Contributor guidelines](https://github.com/NVIDIA/Model-Optimizer/blob/main/CONTRIBUTING.md) and your commits are signed (`git commit -s -S`). Make sure you read and follow the [Security Best Practices](https://github.com/NVIDIA/Model-Optimizer/blob/main/SECURITY.md#security-coding-practices-for-contributors) (e.g. avoiding hardcoded `trust_remote_code=True`, `torch.load(..., weights_only=False)`, `pickle`, etc.). - Is this change backward compatible?: ✅ <!--- If ❌, explain why. --> - If you copied code from any other sources or added a new PIP dependency, did you follow guidance in `CONTRIBUTING.md`: ✅ <!--- Mandatory --> - Did you write any new necessary tests?: ✅ <!--- Mandatory for new features or examples. --> - Did you update [Changelog](https://github.com/NVIDIA/Model-Optimizer/blob/main/CHANGELOG.rst)?: ✅ <!--- Only for new features, API changes, critical bug fixes or backward incompatible changes. --> ### Additional Information NVBug: 5999336 <!-- This is an auto-generated comment: release notes by coderabbit.ai --> ## Summary by CodeRabbit * **New Features** * Added safe checkpoint save/load helpers and a --trust_remote_code CLI flag in examples to control remote-code loading. * **Bug Fixes** * Checkpoint loading now defaults to safer, weights-only semantics to reduce arbitrary-code exposure. * **Documentation** * CHANGELOG updated with security guidance and opt-in procedure for unsafe checkpoint loading. * **Tests** * New unit tests validating the safe-load behavior. <!-- end of auto-generated comment: release notes by coderabbit.ai --> --------- Signed-off-by: RinZ27 <222222878+RinZ27@users.noreply.github.com> Signed-off-by: Keval Morabia <28916987+kevalmorabia97@users.noreply.github.com> Co-authored-by: RinZ27 <222222878+RinZ27@users.noreply.github.com> |
||
|
Keval Morabiaandh-guo18
|
80d2f02a2d |
Fix spec dec example tests (#1183)
### What does this PR do? Type of change: Test fix <!-- Use one of the following: Bug fix, new feature, new example, new tests, documentation. --> - Fix `tests/examples/speculative_decoding` - previously silently skipped - Avoid pulling nemotron-post-training-dataset-v2 in tests to reduce chances of HF loading timeout in CICD - Make slow and redundant tests manual to speed up CICD ### Testing <!-- Mention how have you tested your change if applicable. --> - Tests passing ### Before your PR is "*Ready for review*" Make sure you read and follow [Contributor guidelines](https://github.com/NVIDIA/Model-Optimizer/blob/main/CONTRIBUTING.md) and your commits are signed (`git commit -s -S`). Make sure you read and follow the [Security Best Practices](https://github.com/NVIDIA/Model-Optimizer/blob/main/SECURITY.md#security-coding-practices-for-contributors) (e.g. avoiding hardcoded `trust_remote_code=True`, `torch.load(..., weights_only=False)`, `pickle`, etc.). - Is this change backward compatible?: ✅ <!--- If ❌, explain why. --> - If you copied code from any other sources or added a new PIP dependency, did you follow guidance in `CONTRIBUTING.md`: N/A <!--- Mandatory --> - Did you write any new necessary tests?: ✅ <!--- Mandatory for new features or examples. --> - Did you update [Changelog](https://github.com/NVIDIA/Model-Optimizer/blob/main/CHANGELOG.rst)?: N/A <!--- Only for new features, API changes, critical bug fixes or backward incompatible changes. --> <!-- This is an auto-generated comment: release notes by coderabbit.ai --> ## Summary by CodeRabbit * **Chores** * Removed git‑LFS install step from CI and deleted an automated branch‑cleanup workflow * Trimmed example environment dependencies and relaxed transformers compatibility; added an optional tokenization dependency * **Tests** * Switched tests to generate datasets dynamically and improved fixture handling * Standardized PTQ test parameters (explicit calibration dataset) and refined GPU/test selection * **Bug Fixes** * Improved device-awareness and numeric handling in speculative decoding attention paths <!-- end of auto-generated comment: release notes by coderabbit.ai --> --------- Signed-off-by: Keval Morabia <28916987+kevalmorabia97@users.noreply.github.com> Co-authored-by: h-guo18 <67671475+h-guo18@users.noreply.github.com> |
||
|
h-guo18
|
7f5fd65003 |
[Feat]FakeBaseModel for offline eagle; Kimi-K2.5 fixes; (#1052)
### What does this PR do? Adds `FakeBaseModel` for offline EAGLE training and several Kimi-K2.5 compatibility fixes. - **New**: `FakeBaseModel` — lightweight model that loads only `lm_head` and `embed_tokens` from a local checkpoint, avoiding full model weight loading during offline training. Configured via `FakeBaseArguments` and integrated into `load_vlm_or_llm`. - **Fix**: `_find_base_model_parts` — support Kimi-K2.5 VLM layout (`language_model.model` path) - **Fix**: offline mode lm_head access and CompressedTensors ignore path - **Fix**: Kimi-K2.5 decoder `past_key_value`/`past_key_values` argument mismatch - **Fix**: `rglob` for `.pt` discovery in nested offline data dirs; single-node GPU count respects `CUDA_VISIBLE_DEVICES` Type of change: Bug fix, new feature ### Testing Tested offline EAGLE training for Kimi-K2.5 end-to-end. ### Before your PR is "*Ready for review*" Make sure you read and follow [Contributor guidelines](https://github.com/NVIDIA/Model-Optimizer/blob/main/CONTRIBUTING.md) and your commits are signed (`git commit -s -S`). Make sure you read and follow the [Security Best Practices](https://github.com/NVIDIA/Model-Optimizer/blob/main/SECURITY.md#security-coding-practices-for-contributors) (e.g. avoiding hardcoded `trust_remote_code=True`, `torch.load(..., weights_only=False)`, `pickle`, etc.). - Is this change backward compatible?: ✅ - If you copied code from any other sources or added a new PIP dependency, did you follow guidance in `CONTRIBUTING.md`: N/A - Did you write any new necessary tests?: ❌ - Did you update [Changelog](https://github.com/NVIDIA/Model-Optimizer/blob/main/CHANGELOG.rst)?: ❌ ### Additional Information <!-- E.g. related issue. --> <!-- This is an auto-generated comment: release notes by coderabbit.ai --> ## Summary by CodeRabbit * **New Features** * Lightweight fake-base model support for offline speculative-decoding training * **Improvements** * Added CLI flags: --use_fake_base_for_offline, --trust_remote_code, and --fsdp * Expanded offline .pt discovery to include nested subdirectories * Better GPU detection with explicit single-node logging; FSDP enabled only when requested * Model loading and launch tooling now honor offline and trust-remote-code flags * **Bug Fixes** * Improved compatibility with legacy transformer / Kimi-K2 call signatures * **Tests** * Added tests covering fake-base loading and offline training workflows <!-- end of auto-generated comment: release notes by coderabbit.ai --> --------- Signed-off-by: h-guo18 <67671475+h-guo18@users.noreply.github.com> |

